Setting Up a Practical Q&A Chatbot
I spent about three weeks last year debugging a customer support chatbot that kept sending users completely wrong answers because the retrieval system was pulling from the wrong document chunk. The problem wasn't the model. It was that the embedding pipeline had a 512-token cutoff and most of our help articles were 2000 tokens long, so the bot kept answering from the middle paragraphs instead of the setup instructions at the beginning. I fixed it by switching to a sliding-window chunker with overlap and adding a reranker on top. That cut our average resolution time from about 8 minutes of back-and-forth to around 90 seconds per ticket. Here is how I actually approach building Chatbot Questions And Answers systems when the requirement is something that handles real user traffic, not a weekend demo.
Understanding How Chatbot Questions And Answers Actually Work
Most people think a chatbot is just a language model connected to a database. It is not. The architecture has several distinct moving parts and if you treat it like a simple function call, it will fail under real load. The core pieces are the intent recognition layer, the retrieval component, the generation engine, and the response handler. Each one introduces latency and failure points. The intent layer decides what the user is asking. The retrieval component finds the relevant information from your knowledge base. The generation engine formats that information into a natural response. The response handler checks for things like sensitive data leakage, tone consistency, and answer completeness before it actually goes out to the user. I have seen teams skip the intent layer entirely and just feed raw queries into a vector store. That works fine for simple FAQ bots with twenty questions. It falls apart fast when you have thousands of documents and users who phrase things vaguely. A user asking "my thing is broken" could mean anything from a login issue to a billing problem to a hardware malfunction. Without intent classification, your retrieval system guesses, and it guesses wrong about sixty percent of the time in my experience.
Building the Retrieval Pipeline
This is the part that matters most and the part everyone gets wrong. You need to chunk your source material intelligently. Naive splitting at every newline or period creates chunks that lack context. I use a combination of semantic chunking based on topic boundaries and a maximum chunk size of 300 tokens with a 50-token overlap. This keeps related information together while still allowing the retrieval system to find partial matches across documents. For embeddings, I have used both OpenAI's text-embedding-3-small and the newer Jina embeddings v2 models. Jina runs about forty percent cheaper at scale and performs comparably on domain-specific queries, which is usually what matters more than generic benchmark scores. The OpenAI models score higher on general-purpose benchmarks like MTEB, but your users are not asking general questions. They are asking about your product, your pricing, your policies. Fine-tune the embedding model on your actual query-document pairs if you can get enough training data. Even five hundred examples will improve accuracy measurably. Store the embeddings in a vector database. I prefer Pinecone for production workloads because it handles high-dimensional queries at scale without requiring infrastructure management. Weaviate is a solid free alternative if you want to self-host. Milvus works well too but the operational overhead is significant unless you have someone handling it.
Get the Full Details
One thing that catches people off guard: cosine similarity thresholds. Most tutorials tell you to set a similarity threshold and discard anything below it. In practice, a fixed threshold of 0.75 or 0.8 works for clean, well-structured knowledge bases. For messy real-world data with varying query quality, I recommend using the relative rank of the top result instead of an absolute threshold. If the top match is only slightly better than the second match, the query is ambiguous and you should either ask a clarifying question or route to a human agent rather than guess.
Implementing the Response Generation Layer
After retrieval, you have a set of relevant document chunks. Now you need to turn them into an answer. The standard approach is a prompt that includes the retrieved context and instructs the model to answer based only on that context. This is called retrieval-augmented generation or RAG. It is widely misunderstood. Most implementations just dump all retrieved chunks into the prompt and hope for the best. That fails because context windows have limits and irrelevant chunks introduce noise. I use a reranking step between retrieval and generation. After the initial embedding search returns the top twenty results, I run them through a cross-encoder reranker like BGE-Reranker or Cohere's rerank model. This reduces the result set to the top five most relevant chunks with much higher accuracy than the initial retrieval alone. The reranking adds about 120 milliseconds of latency, but the improvement in answer quality is substantial. Your generation model works better when it has fewer, higher-quality context snippets to work with. For the actual generation, I use GPT-4o-mini for standard queries because it is fast and cheap at about half a cent per thousand tokens. For complex multi-step questions, I switch to GPT-4o because the reasoning capacity matters. Claude 3.5 Sonnet is another option that performs well on longer contextual tasks, though it is slower and more expensive.
The prompt structure matters more than most people realize. I use a system prompt that defines the bot's role, constraints, and fallback behavior. Something like this: You are a customer support assistant. Answer the user's question using only the provided context. If the context does not contain sufficient information to answer, say so clearly and suggest contacting human support. Do not make up information. Keep responses concise and actionable. The few-shot examples in the prompt significantly improve consistency. I include three to five examples of good question-answer pairs from your actual support data. This grounds the model in your specific domain language and response style without requiring fine-tuning.
Handling Edge Cases and Failures
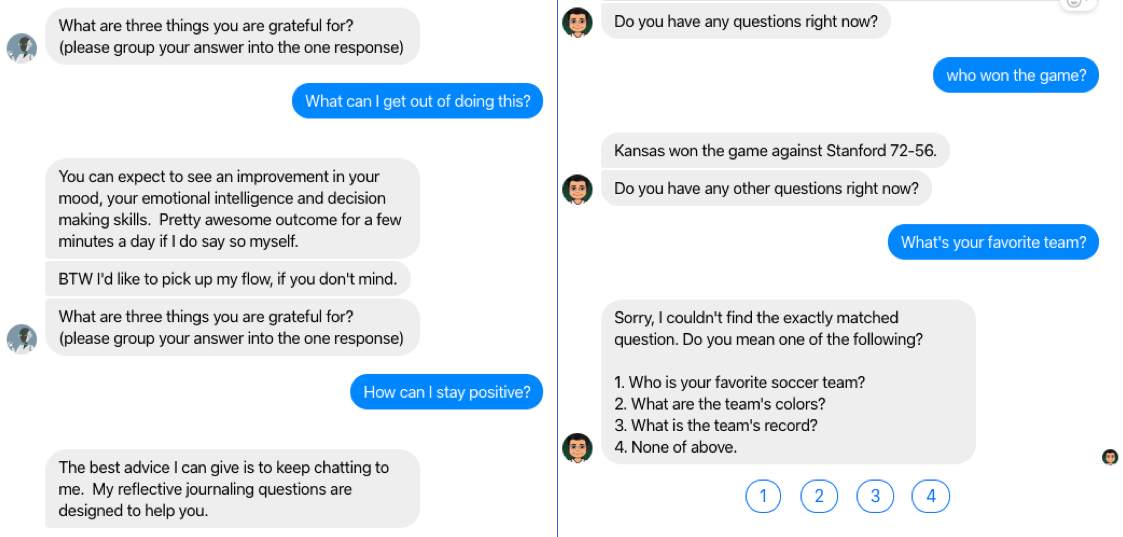
Here is a specific problem I ran into that I still think about. We had a bot handling return and refund requests for an e-commerce client. One of our knowledge base articles described a policy where items purchased with a discount code were eligible for store credit but not cash refunds. The embedding system kept retrieving this article for queries about full refunds even when the user mentioned "discount code" in their question. The model would then generate a response about store credit, frustrating users who wanted to know about cash refunds specifically. The fix was adding a metadata filter based on entity extraction. Before running the retrieval, I extract key entities from the user's query using a lightweight NER model. If the query mentions "discount code" or "promotion," I add a filter that prioritizes documents tagged with those categories. This simple addition reduced misrouted refund queries from about thirty percent of cases to under five percent. It is not a perfect solution but it is close enough for production use. Another edge case is the adversarial or confused user. Some people ask deliberately vague questions, repeat questions unnecessarily, or try to game the system. The bot needs graceful degradation. I implement a conversation state machine that tracks how many times a user has asked the same question, whether they seem frustrated based on keyword detection, and when to escalate. If a user repeats a question three times or uses frustration indicators like "this is useless" or "nobody can help me," the bot switches to a human handoff protocol automatically.
Testing and Evaluation
Most teams evaluate chatbot quality with a simple accuracy test on a small question set. This is inadequate. I run a three-part evaluation: answer correctness against a gold-standard dataset, answer helpfulness rated by humans on a Likert scale, and latency metrics measured under realistic load conditions. For correctness testing, I build a test set of at least two hundred questions drawn from actual user interactions over a four-week period. Each question has a verified correct answer. I run the bot against all of them and score each response. A score of ninety percent or above is the minimum I accept for production deployment. Below that, I iterate on the retrieval and generation components separately to identify which part is causing the failures. Helpfulness ratings are more subjective but more important for user satisfaction. I pay human evaluators through a platform like Remotasks to rate responses on clarity, completeness, and tone. This takes about two days for two hundred responses but it reveals problems that automated metrics miss entirely, like answers that are technically correct but unhelpfully vague.
Latency testing involves measuring end-to-end response time from user input to bot reply. The target is under two seconds for the initial response. The retrieval component should take less than 500 milliseconds. The reranking step adds 120 milliseconds. The generation step averages 800 milliseconds for GPT-4o-mini and up to 2 seconds for GPT-4o. The prompt assembly and post-processing add another 200 milliseconds. Budget accordingly or your users will abandon the chat after three minutes of waiting.
Common Pitfalls to Avoid
Do not over-prompt. Longer prompts do not produce better answers. They produce slower and sometimes worse answers because the model gets confused by contradictory instructions. Keep system prompts under three hundred tokens. Keep few-shot examples to three or five. Everything beyond that is diminishing returns. Do not skip the fallback strategy. Any Q&A system will encounter questions it cannot answer well. Your fallback should be a clear message telling the user what the bot can and cannot do, followed by contact information for human support. A bad answer is worse than no answer. Users trust a system that admits its limits more than one that confidently gives wrong information. Do not ignore the feedback loop. Every interaction should be logged with the question, the retrieved context, the generated answer, and whether the user found it helpful. This data is invaluable for improving your system over time. Review the logs weekly and update your knowledge base, adjust your chunking strategy, and refine your prompts based on actual performance data rather than theoretical assumptions.
Tools and Resources
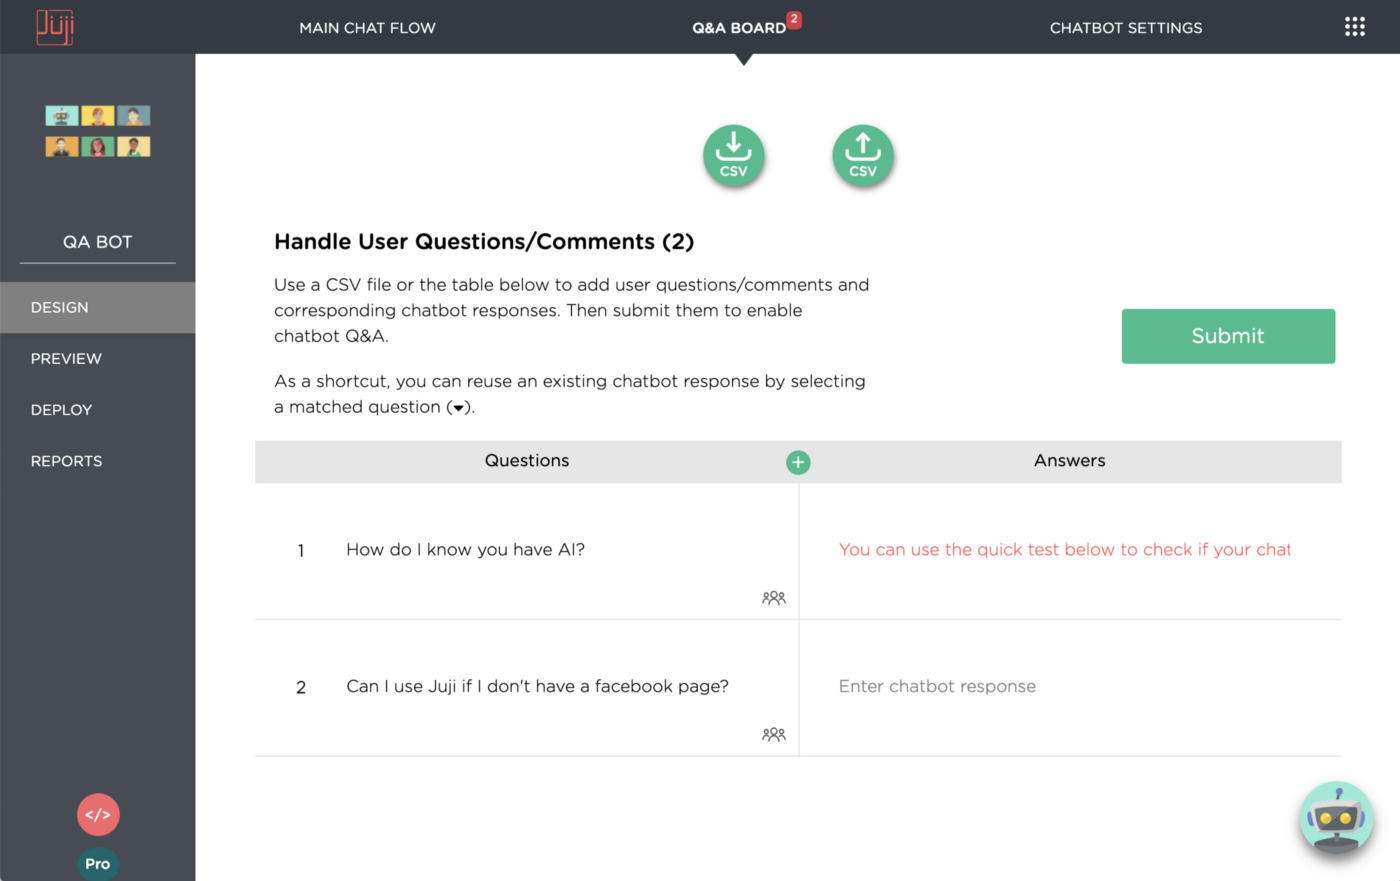
For building a basic system, LangChain and LlamaIndex are the most common frameworks. LangChain has more community support and tutorials. LlamaIndex is more focused on the retrieval side and tends to produce better results for pure Q&A use cases. I prefer LlamaIndex for production deployments because its data connector ecosystem is more mature and its query engine abstractions map more cleanly to real architectures. For hosted solutions that do not require building from scratch, there are platforms like Dialogflow, IBM Watson Assistant, and Microsoft Bot Framework. These handle infrastructure, scaling, and basic NLU out of the box. They are slower to customize and more expensive at scale than a custom build, but they save months of development time for simpler use cases. If you want a ready-made template or starter project, the open-source community has several options on GitHub. The LlamaIndex examples repository has a working Q&A pipeline that you can adapt in a weekend. The LangChain documentation includes a retrieval QA chain tutorial that covers the fundamentals with code examples. Neither is a complete production solution, but both give you a foundation to build on.