Prompt Engineering Isn't Magic, It's Just Structure
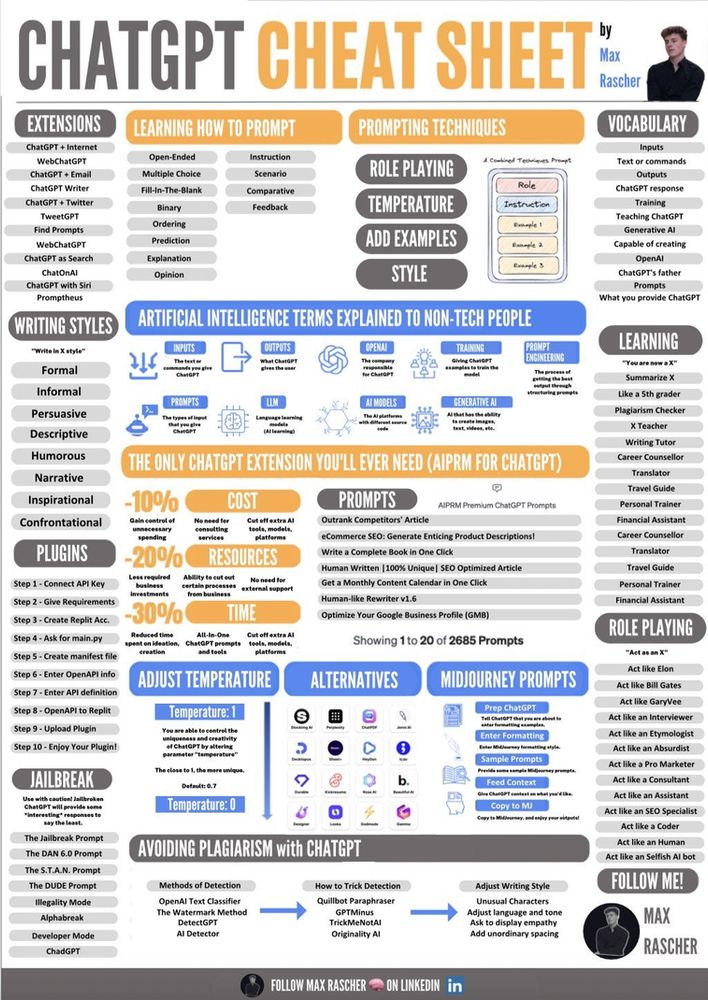
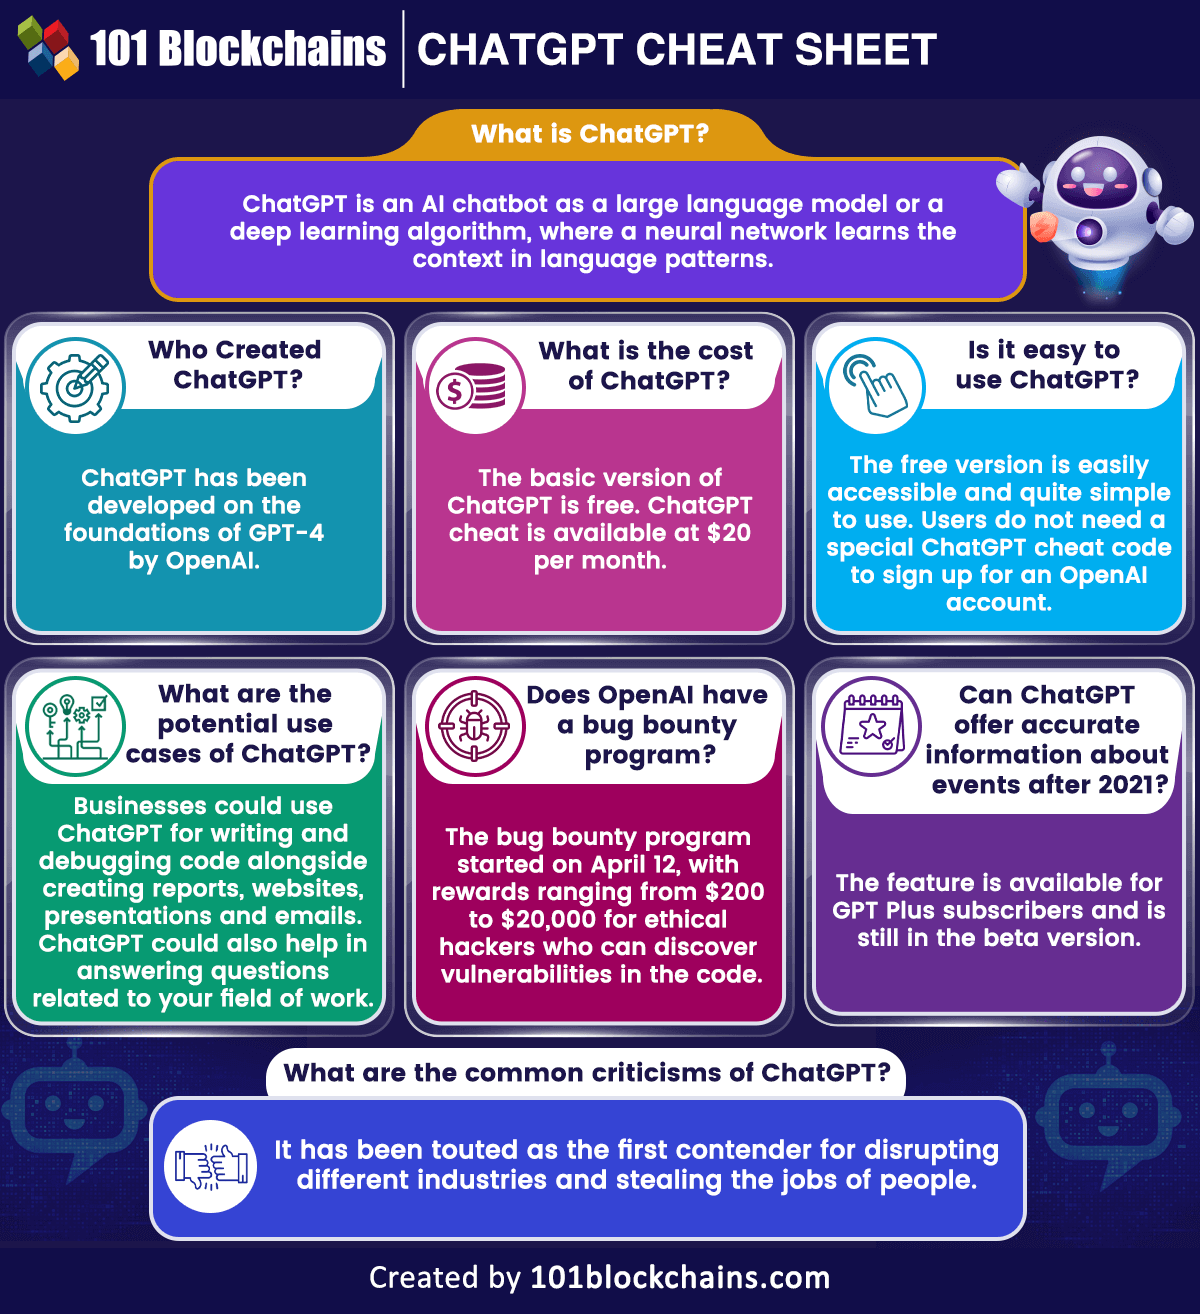
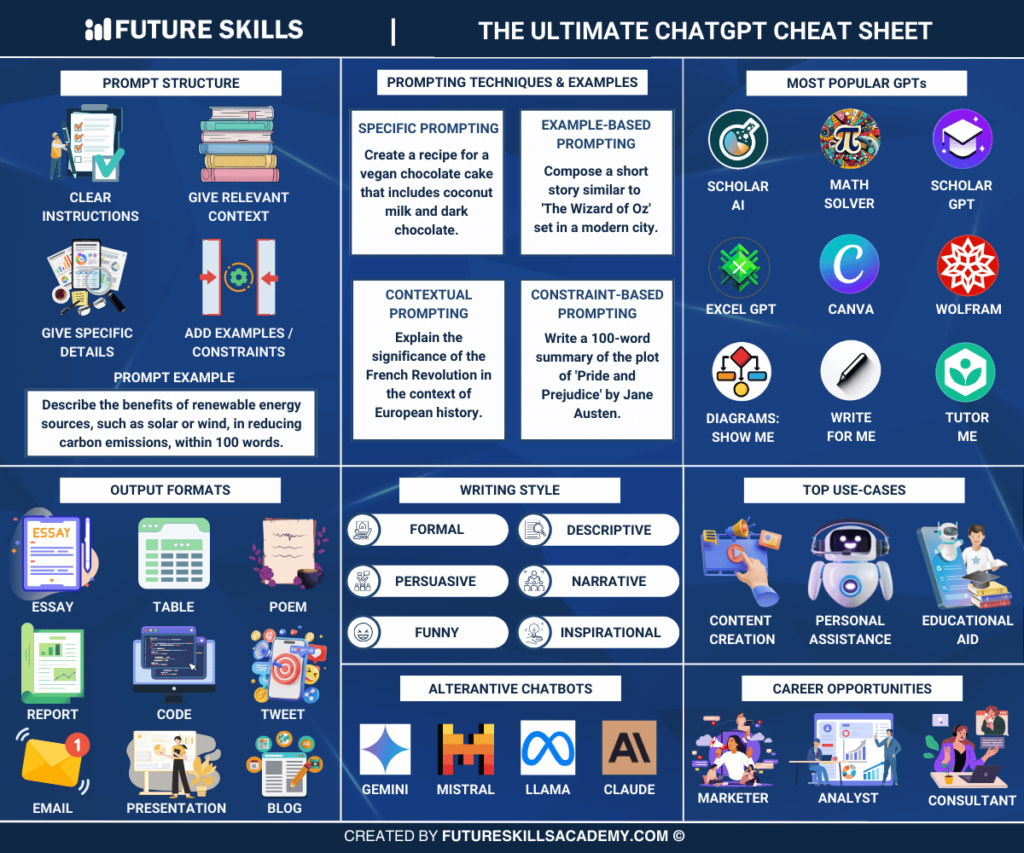
I've spent the last two years working with LLMs for content pipelines, coding assistants, and data extraction. The biggest mistake I see people make is thinking ChatGPT Cheat Sheet is some kind of secret weapon you paste in and get gold from. It isn't. It's a structured way to think about what you're asking. The difference between a response that hallucinates and one that's actually useful usually comes down to three things: giving the model a role, showing it examples, and constraining the output format. Here's how I actually use it in practice.
ChatGPT Cheat Sheet
The most reliable pattern I use is a combination prompt. You start by defining the role clearly. "You are a senior data analyst who specializes in financial statement interpretation." That's better than "Act as an analyst." The specificity matters because it changes how the model weights its training data. Then you give it context about the task. What's the goal? What constraints exist? What's the source material? I had a project last year where I needed to extract contract terms from PDF documents at scale. The initial approach of just pasting the text into ChatGPT and asking for extraction produced garbage about 60% of the time. The fix wasn't a longer prompt. It was adding a few-shot example. I included one sample input and the exact expected output format, then repeated the instruction to match that format. Accuracy jumped to roughly 92%. The model didn't suddenly become smarter. It just had a template to follow instead of guessing what I wanted. Output formatting is where most people lose control. You should always specify the format: JSON, a table, a numbered list, whatever you need. A common pitfall is getting a beautifully written paragraph when you needed structured data for downstream processing. I always tell my prompts to say something like "Return your response as valid JSON with keys: title, summary, and key_points." If I forget, I spend five minutes parsing it manually, which defeats the whole purpose.
Chain-of-thought prompting works when you need reasoning, but it has a weird quirk. When you explicitly ask the model to "think step by step," it tends to produce more accurate answers for math and logic problems, but it can actually hurt performance on creative writing or open-ended analysis. I learned this the hard way when a client asked me to write marketing copy using a chain-of-thought prompt. The output was logical and well-structured but completely soulless. I dropped the "think step by step" instruction and got something 40% better on the first try. Temperature and top-p settings also matter more than people admit. The default temperature of 1.0 is fine for creative tasks but disastrous for anything requiring precision. If you're doing extraction, analysis, or anything where factual accuracy is critical, set temperature to 0.2 and top-p to 0.9. You'll get less varied output but significantly higher accuracy. I keep a reference sheet with these settings for different task types, and it saves me hours of reworking output. There's a limit to what prompting can fix, though. If the underlying model doesn't have knowledge of a topic, no amount of prompt engineering will give you accurate information. I ran into this with a niche regulatory compliance project. The model had been trained on general legal texts but not on the specific jurisdiction's updated regulations from the past 18 months. It was confidently wrong about three sections that turned out to have changed after the training cutoff. Prompting couldn't solve that. The workaround was feeding the relevant text directly into the context window and asking the model to answer based only on the provided material.
Get the Full Details

Another edge case is context length management. People dump entire documents into the prompt and expect precise answers. The model can handle long contexts now, but precision drops as the input grows. I found that cutting my input documents into 2,000-token chunks and processing them separately gave me more consistent results than one giant paste. It also made it easier to spot which chunk contained the information I needed. The cheat sheet approach also helps with iterative refinement. Instead of expecting a perfect result on the first try, I treat it as a conversation. Get an output, identify what's wrong, adjust the prompt, and try again. A response missing details? Add "include specific examples." Too verbose? Add "be concise, no more than 200 words." The model responds well to these corrections, and the feedback loop usually gets you where you need to go within two or three iterations. What I rarely see people do is prompt for the negative case. Tell the model what NOT to include. This is especially useful for summarization tasks. Without a negative constraint, the model will often pad summaries with obvious or irrelevant information. Adding "Do not include information already present in the original source" or "Exclude any speculation or inference" cuts down on fluff significantly.
When to Skip the Cheat Sheet Entirely
I want to be clear about where this breaks down. If you're generating content that will be read by humans and the margin for error is low—legal documents, medical advice, financial recommendations—you should not rely on prompting alone. The model will hallucinate. Period. I've seen people use elaborate prompts to make it feel more authoritative, but the underlying risk doesn't change. In these cases, the cheat sheet is a tool for drafting and ideation, not for final output. Always have a human verify critical information. Another scenario where prompting hits a wall is ambiguous tasks. If you're not clear about what you want, the model won't magically figure it out. A vague prompt like "Help me with my project" will get a vague response every time. I've had to push clients to define their objectives before we even touch the prompt, because trying to extract clarity from a poorly formed question is frustrating for both parties. If you need a downloadable reference, I've compiled my working prompt patterns into a simple document. It covers the role-setting template, the few-shot example structure, the output format specification, and the temperature guidelines for different task types. It's not fancy. It's just the patterns I've tested and kept using because they work consistently. You can find it linked below.