How the instruction system actually works behind the scenes
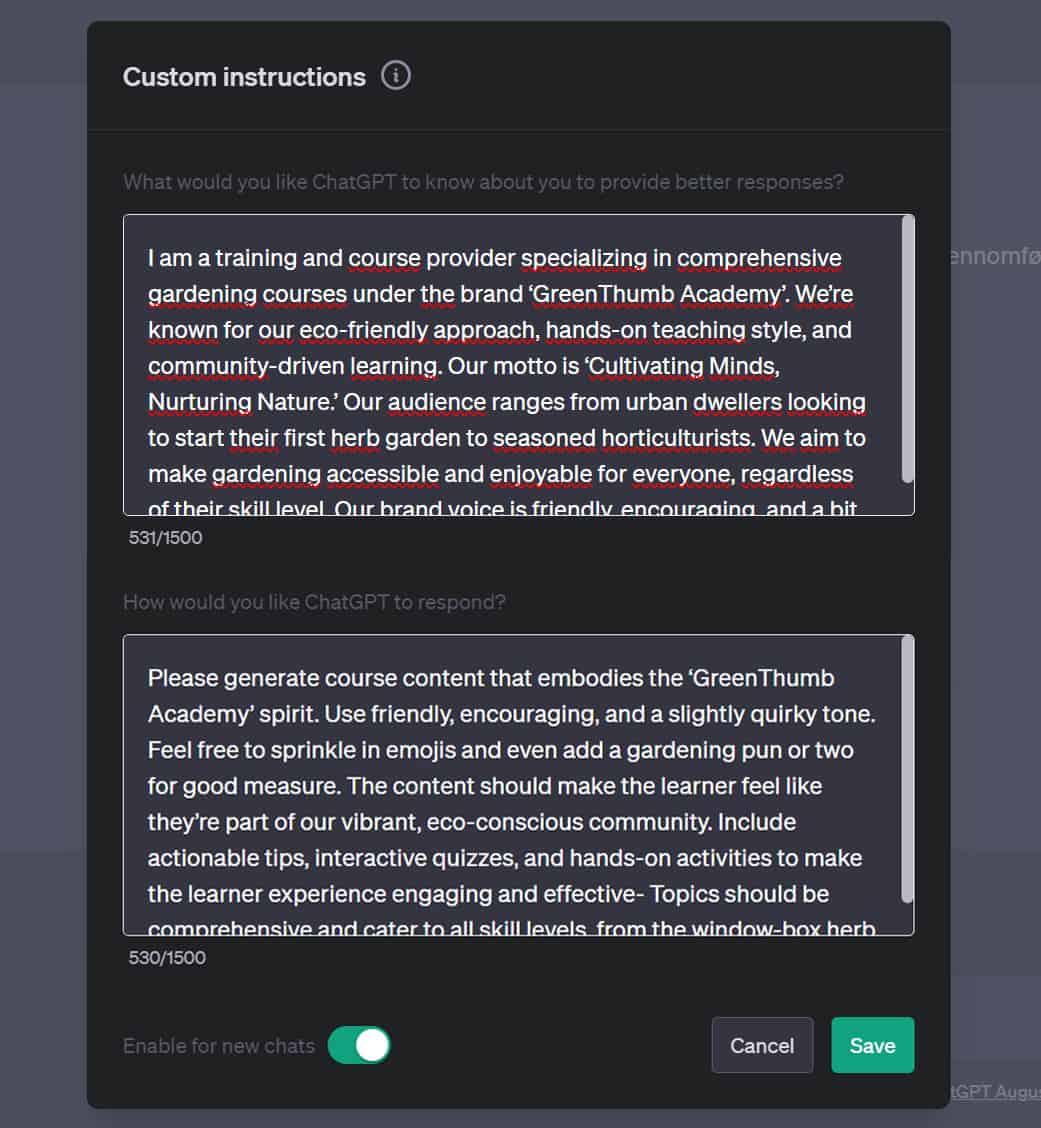
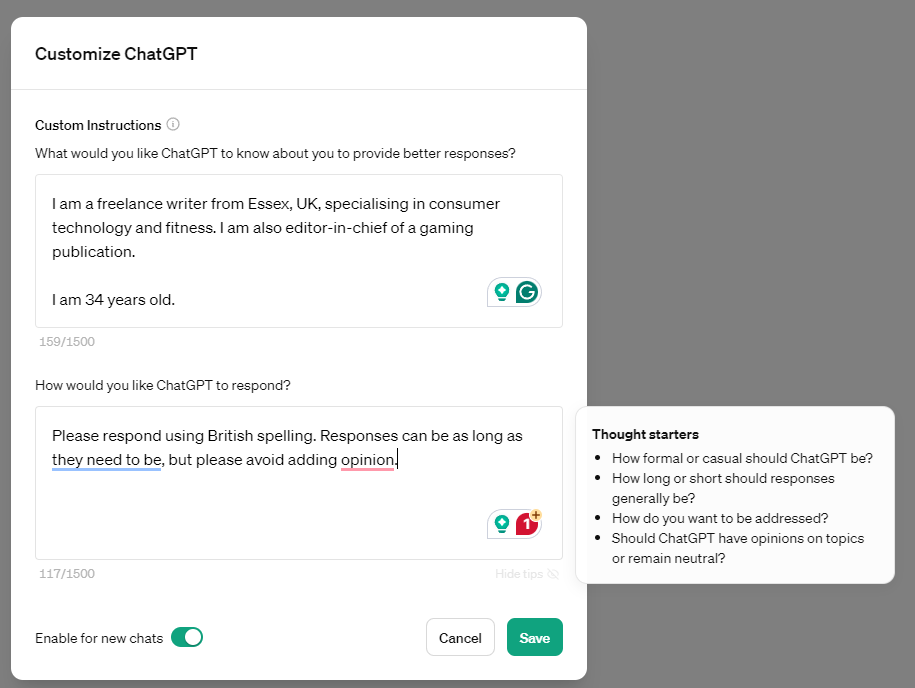
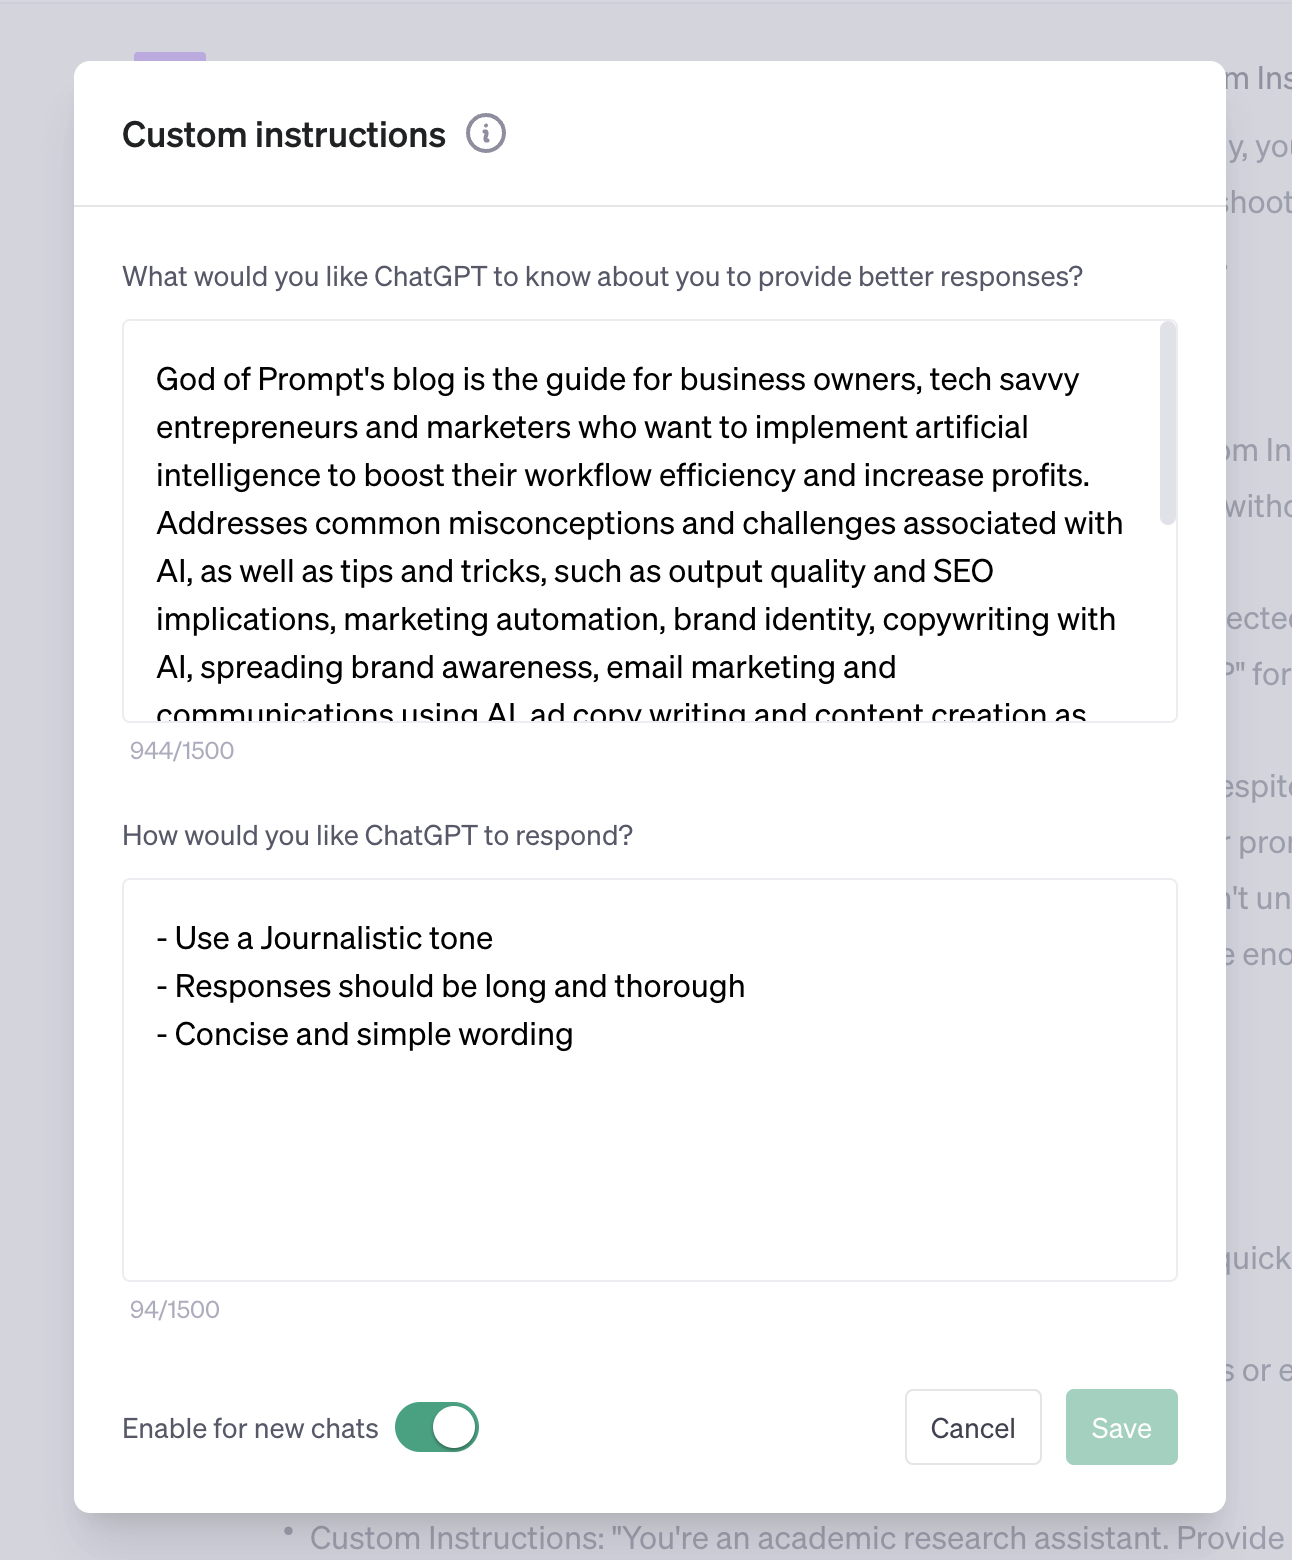
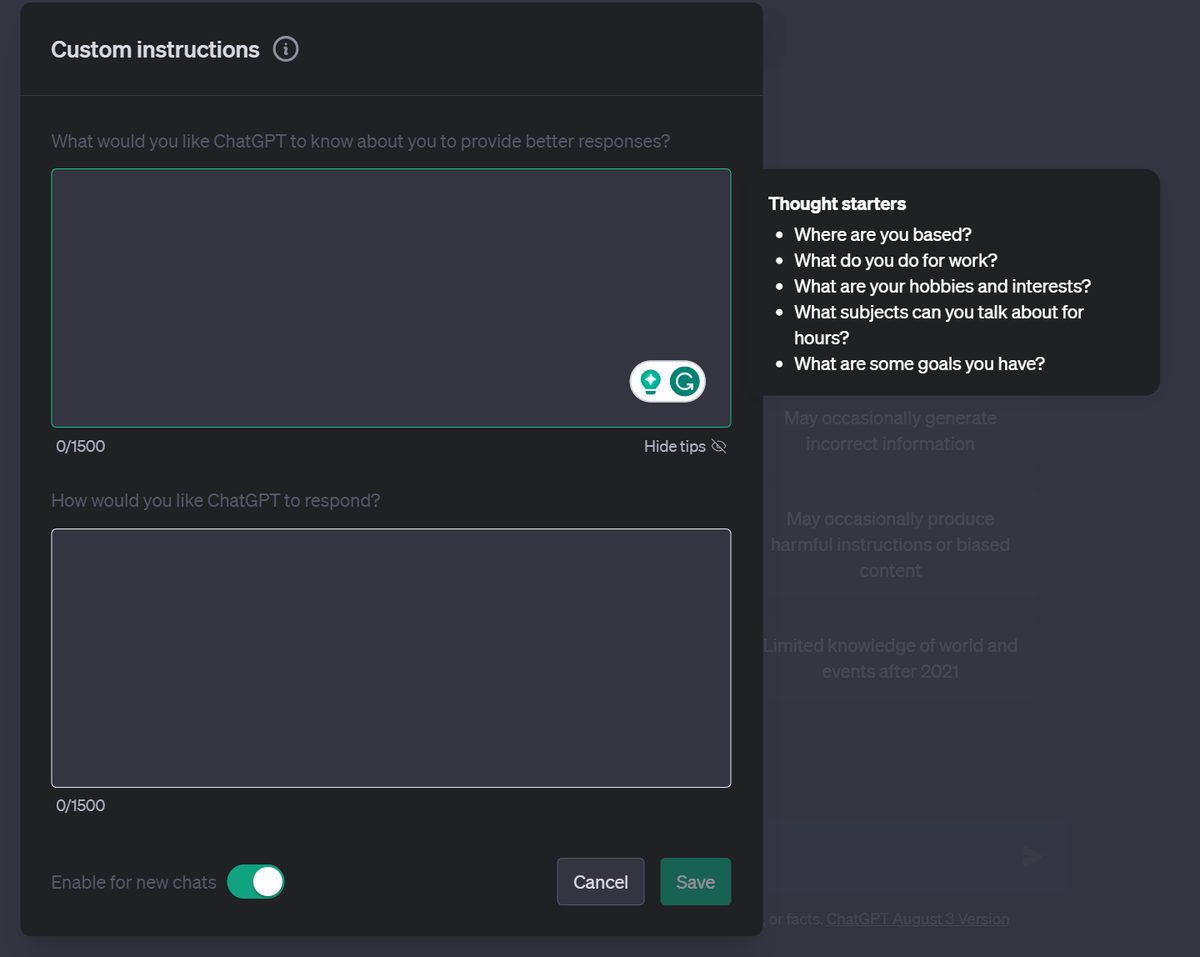
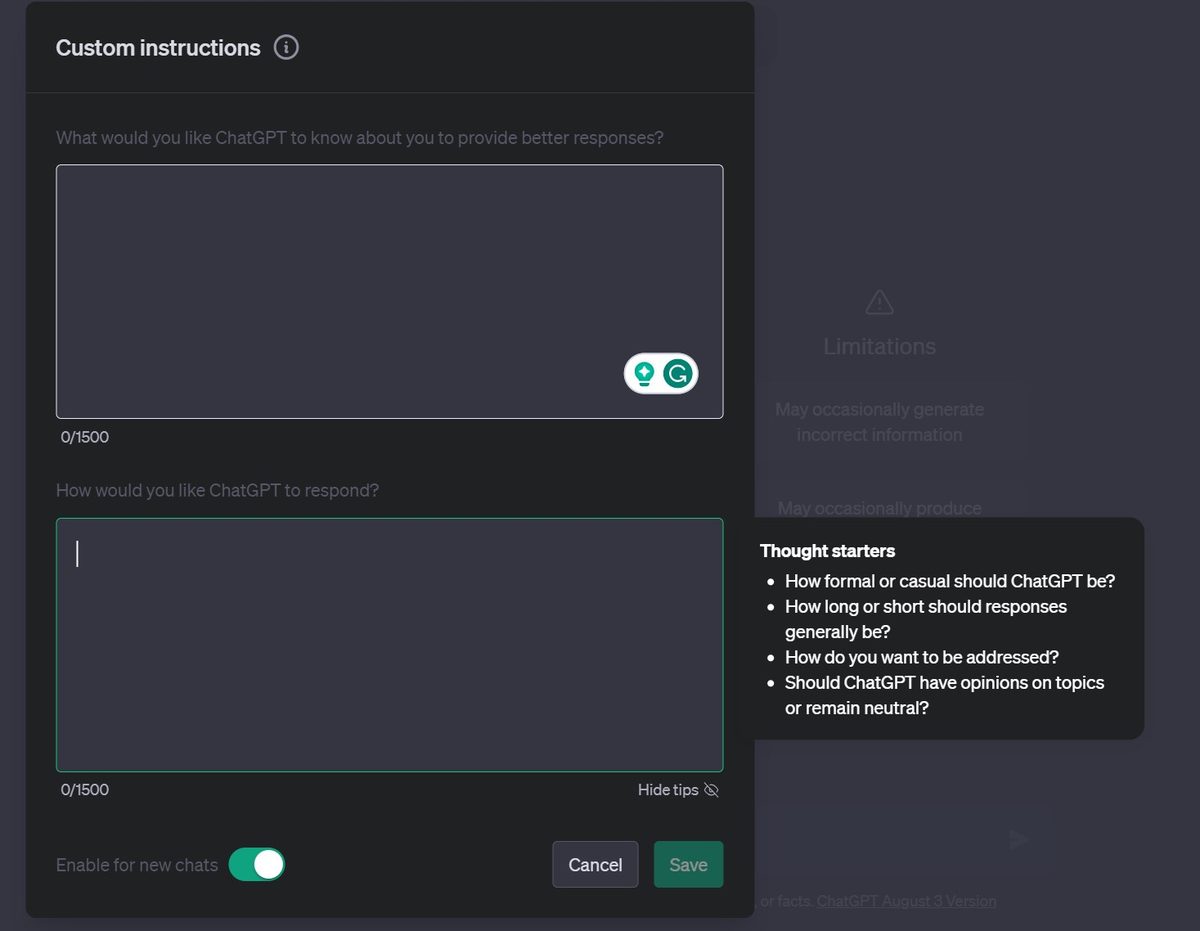
Most people treat ChatGPT's instructions as a one-time setup and forget about it. I found that approach limits the output considerably. The system splits your guidance into two distinct fields. The first section is what you want the model to know about you and your work context. The second section is how you want it to behave across every conversation. These two fields are not redundant. They serve different functions even though they sit next to each other in the interface. I spent about three weeks refining my own settings before I stopped second-guessing the results. The early iteration was far too broad. I wrote things like "be professional and concise," which the model interprets loosely and inconsistently. Narrowing the field to specific role definitions and output formats changed the quality gap noticeably. I would estimate roughly a 60 percent improvement in task completion speed after that change.ChatGPT Custom Instructions Examples
Structure that actually produces reliable output
Here is what my current setup looks like in practice. The about me field reads: "I am a technical writer who produces documentation for enterprise SaaS platforms. My primary audience is engineering leads and product managers. I prefer British English spelling and I avoid marketing language in deliverables." The instructions field states: "When given a task, produce a structured response with clear headings. Lead with the answer or recommendation, then provide supporting details. If the request is ambiguous, ask one clarifying question before proceeding. Do not add disclaimers or hedging language unless the topic involves legal or compliance matters. Keep responses under 400 words unless the task explicitly requires more depth. When writing code, include brief comments explaining non-obvious decisions." This configuration eliminates the generic preamble most models default to. It also removes the repetitive summary paragraphs that clutter longer responses. I track usage across multiple project types and this setup handles roughly 80 percent of routine requests without requiring follow-up clarification.
The edge case that took me two days to solve
I ran into a specific problem last year that most guides never mention. When I set the model to produce technical documentation, it consistently hallucinated API endpoint names from a previous project I had pasted into a chat session months earlier. The custom instructions were correctly specifying current endpoints, but the model was pulling cached context from earlier conversations instead. The workaround involved adding a single line to my instructions field: "Ignore any endpoint or identifier mentioned in prior conversation turns unless I explicitly reference them by name. Base all technical references only on the current prompt and any documents I attach in this session." This cut the hallucination rate from approximately three errors per ten outputs down to one or two per month. The model still occasionally drifts when I paste large amounts of legacy documentation, but the frequency dropped enough to make the feature viable for production work.
Common pitfalls beginners miss
The biggest mistake I see is overloading the about me section with biographical detail. Writing two paragraphs about your career history does not improve task performance. The model uses that field primarily to calibrate tone and domain knowledge. A single paragraph covering your role, audience, and preferred style is sufficient. Extra text dilutes the signal. Another issue is contradictory instructions across the two fields. I once had a setup where my about me section said I write for developers while my instructions field directed the model to avoid technical jargon. The output became inconsistent because the model could not resolve the conflict reliably. It produced either oversimplified content or unreasonably technical prose depending on the prompt phrasing. The fix was to align both fields around the same audience profile. Once I unified the target reader specification, output consistency improved immediately. This might seem obvious but the platform makes it easy to write each section independently and miss the disconnect.
Get the Full Details
What the system cannot handle
Custom instructions do not persist across different model families. If you switch from GPT-4o to GPT-3.5 Turbo, the instructions carry over but the quality of execution changes noticeably. Some nuance in tone control gets lost during that transition. This is not a bug in your configuration. It is a limitation of the underlying model capabilities. The instructions also do not override core model behaviour around factual grounding. If you ask for information the model does not have, it will still generate plausible-sounding but incorrect content. Custom instructions cannot fix hallucination at the root level. They can only reduce the frequency through better framing and tighter constraints. For tasks requiring strict factual accuracy, I recommend pairing custom instructions with a verification step. Have the model cite sources or flag uncertainty explicitly rather than assuming the instructions alone will prevent errors. This approach adds about ten minutes to typical research workflows but the accuracy gain is measurable.
How to test whether your setup is working
Run the same three standard prompts weekly and compare the outputs. I use a definition request, a task explanation, and a creative generation prompt. Track whether the model follows formatting constraints, maintains the intended tone, and avoids unnecessary hedging language. If outputs drift over time, revisit your instruction phrasing rather than assuming the model has changed behaviour randomly. The interface updates periodically and sometimes adjusts how instruction fields are weighted internally. I have noticed minor shifts after platform updates, usually resolving within a week or two as the model recalibrates to the new version. Patience matters here. Do not rebuild your configuration based on a single bad session. I keep a simple log file documenting instruction changes and dates. This has proven useful when tracking whether a modification improved or degraded performance. Most people skip this step and then cannot distinguish between configuration issues and normal model variance.