Using ChatGPT for Data Analysis Is Mostly About Prompting and Knowing When to Stop
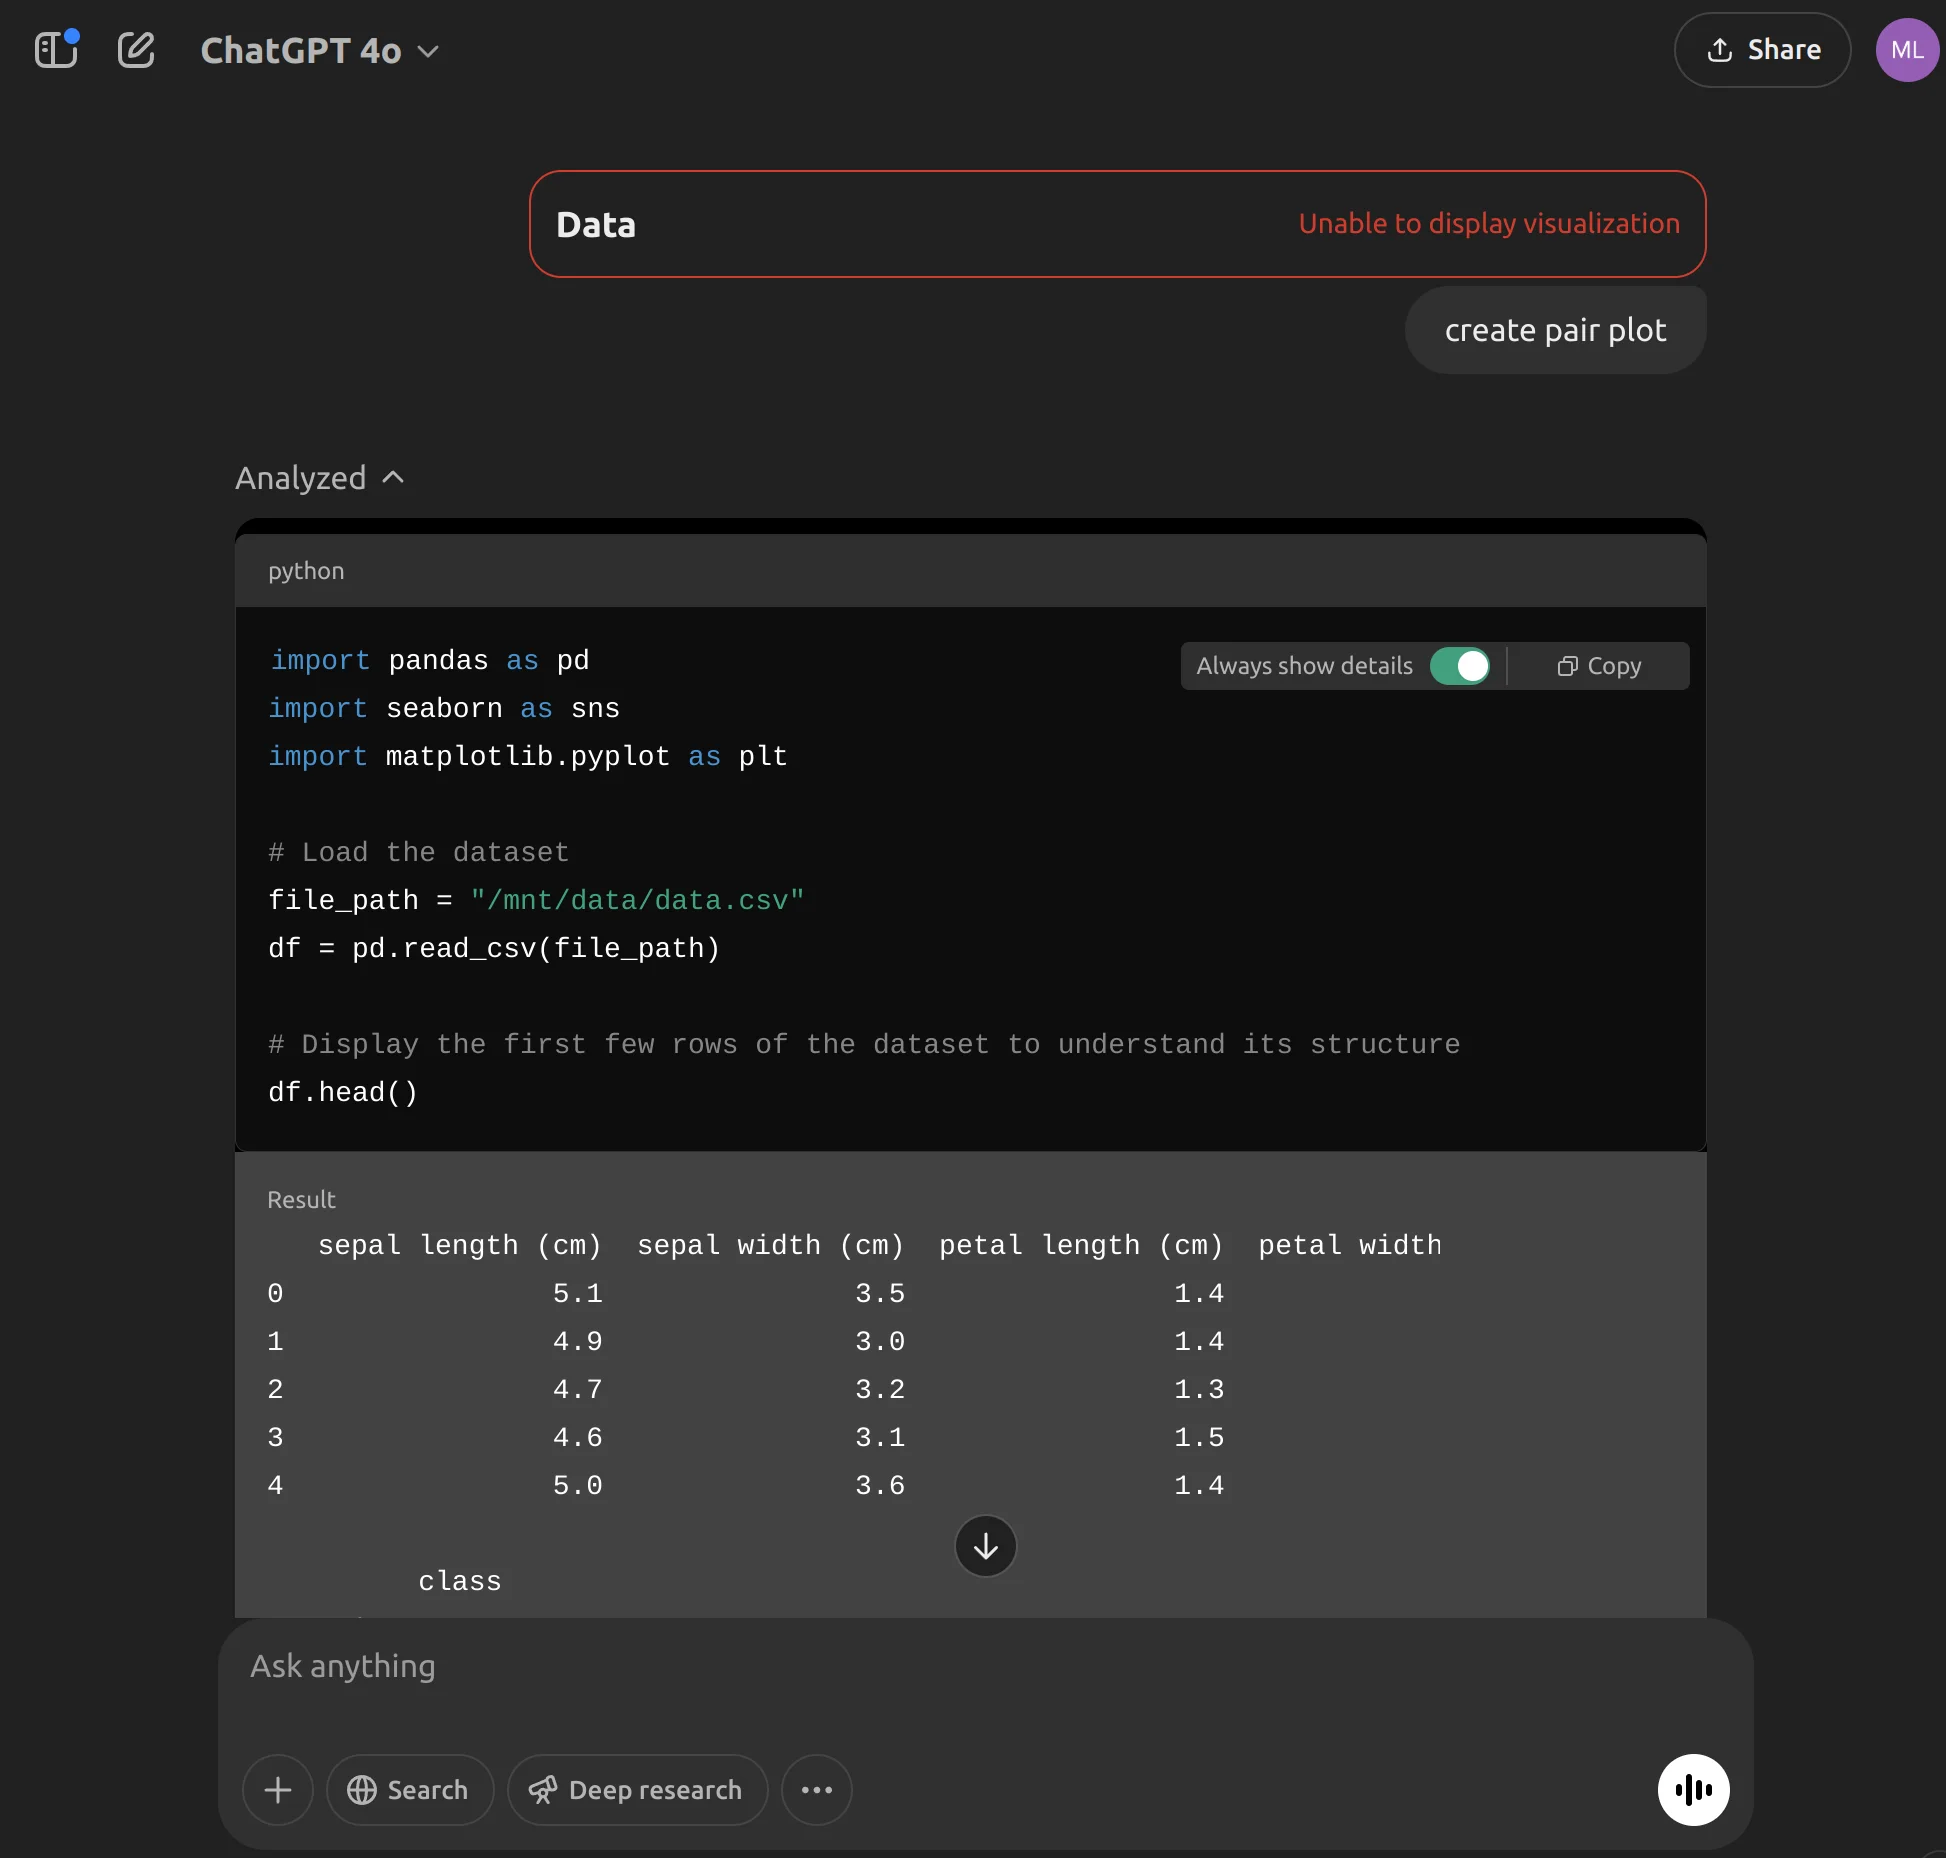
I've spent enough time doing this that I can tell you upfront: ChatGPT For Data Analysis works best when you treat it like a junior analyst who knows SQL and Python but has never seen your actual data before it stares at it. That framing matters more than anything else I'll say here. The process is simpler than people make it. You upload a file, you describe what you want, and you iterate. I typically use the data analysis mode in ChatGPT Plus, which runs code in a sandboxed environment. You give it a CSV, Excel file, or JSON, and it writes and executes Python code to explore, clean, and visualize the data. Here's what I actually do. I paste the file or describe its location, then I write a prompt like "Clean this dataset and remove rows where the timestamp is null, then group by product category and calculate month-over-month revenue variance." The model generates Python code using pandas and matplotlib, executes it, and returns results with explanations. You can ask follow-up questions and it references the same execution environment.
The key thing nobody tells beginners is that the context window handles roughly 128,000 tokens, which means even moderately large datasets of around 50,000 rows with 20 columns fit comfortably. Beyond that, you start hitting memory limits and the code execution begins to stall or produce truncated outputs. At that point you're better off chunking the data or pre-processing it yourself before uploading. I remember working with a client last year who had transactional data spanning three years, roughly 2.1 million rows across four related tables. They wanted me to pull this into ChatGPT and build a dashboard. The initial attempt crashed the code interpreter after about forty seconds of execution. The workaround was straightforward: I merged the tables locally in pandas, aggregated them down to a monthly summary level first, and then uploaded the much smaller derived dataset. ChatGPT handled the visualization and exploratory analysis from there in about three minutes. Trying to push the raw data through was a waste of twenty minutes of token usage and patience.
What Actually Works and What Doesn't
ChatGPT's data analysis capabilities rest on several assumptions that are worth understanding before you rely on them. First, it uses Python's pandas library by default for data manipulation. This is fine for tabular data. It becomes problematic fast when you need spatial queries, graph traversals, or time-series operations that require specialized libraries like networkx, geopandas, or statsmodels. The sandbox environment has a restricted set of packages installed. If you reference something not available, the code execution fails and you get an error message that's sometimes vague about which dependency is missing. I learned this the hard way when trying to run a basic SARIMAX forecast and discovering the model couldn't import statsmodels. Switching to a simpler moving-average approach saved me from debugging a dependency issue that would have gone nowhere. Second, the quality of output depends heavily on how specifically you frame the question. Vague prompts like "analyze this data" produce generic summaries that are usually obvious. Prompts like "identify outliers in the revenue column using the IQR method, flag any months where the z-score exceeds three standard deviations, and create a scatter plot of marketing spend versus conversion rate with trend lines" produce usable code on the first try most of the time. The difference between a useful result and a useless one is often ten additional words in your prompt.
Get the Full Details
Third, and this is the part most people miss, ChatGPT can hallucinate column names and data types if your dataset has unusual headers or inconsistent naming. I've seen it generate code referencing a column called "Customer_ID" when the actual column was named "customer-id" with a hyphen. It made its best guess based on context and proceeded to write code that failed at runtime. The fix is always to ask it to print the column names and data types first before doing any heavy lifting. This single step catches the majority of downstream errors. Another thing that trips people up is the assumption that ChatGPT remembers previous conversation turns perfectly. It does, but not with perfect fidelity. In longer sessions, I've noticed that earlier instructions get partially dropped or conflated with new ones. If you're building a multi-step analysis over twenty or thirty messages, document your steps externally. Keep a separate notebook of what you've asked and what the outputs were. Relying purely on conversational memory for auditability is a mistake I made early on and it cost me a significant amount of time going back to verify results.
When to Use It and When to Step Away
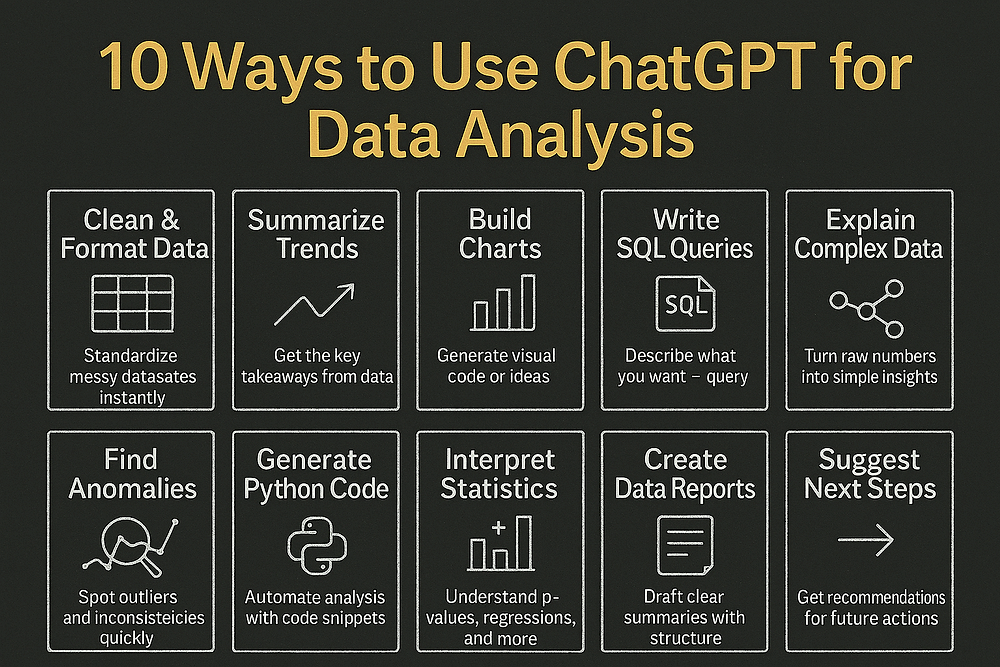
ChatGPT For Data Analysis is genuinely useful for exploratory data analysis, quick visualizations, cleaning tasks, and generating boilerplate code for common operations. It cuts routine data wrangling time from maybe two hours down to fifteen or twenty minutes for straightforward datasets. For exploratory work where you're testing hypotheses or checking distributions, it's fast enough to be genuinely productive. It is not useful for production-grade analysis, reproducible research pipelines, or anything where you need version control on your transformations. The outputs are stateless between sessions unless you save them. There is no git history. There is no automated testing. If you're doing something that needs to be audited or repeated exactly, you're better off writing the Python script yourself and using ChatGPT only to help you debug specific sections. Statistical rigor is another area where the tool underperforms relative to expectations. The code it generates for statistical tests is usually syntactically correct, but it sometimes applies the wrong test for the data structure. For example, it suggested running a t-test on paired data once when the samples were actually independent. The p-value was technically valid for the code it wrote, but the code didn't match the experimental design. Always verify the statistical assumptions, especially when the analysis is going to inform decisions that affect revenue or strategy.
For complex data engineering tasks involving multiple sources, joins across databases, or ETL pipelines, traditional tools like dbt, Airflow, or even a well-written SQL script will do the job faster and more reliably. ChatGPT can help you write the code, but it cannot execute it against your actual infrastructure. You'll still need to run it yourself and validate the results. The time saved is marginal compared to the time you spend fixing incorrect assumptions in the generated code.

Practical Workflow I Use Regularly
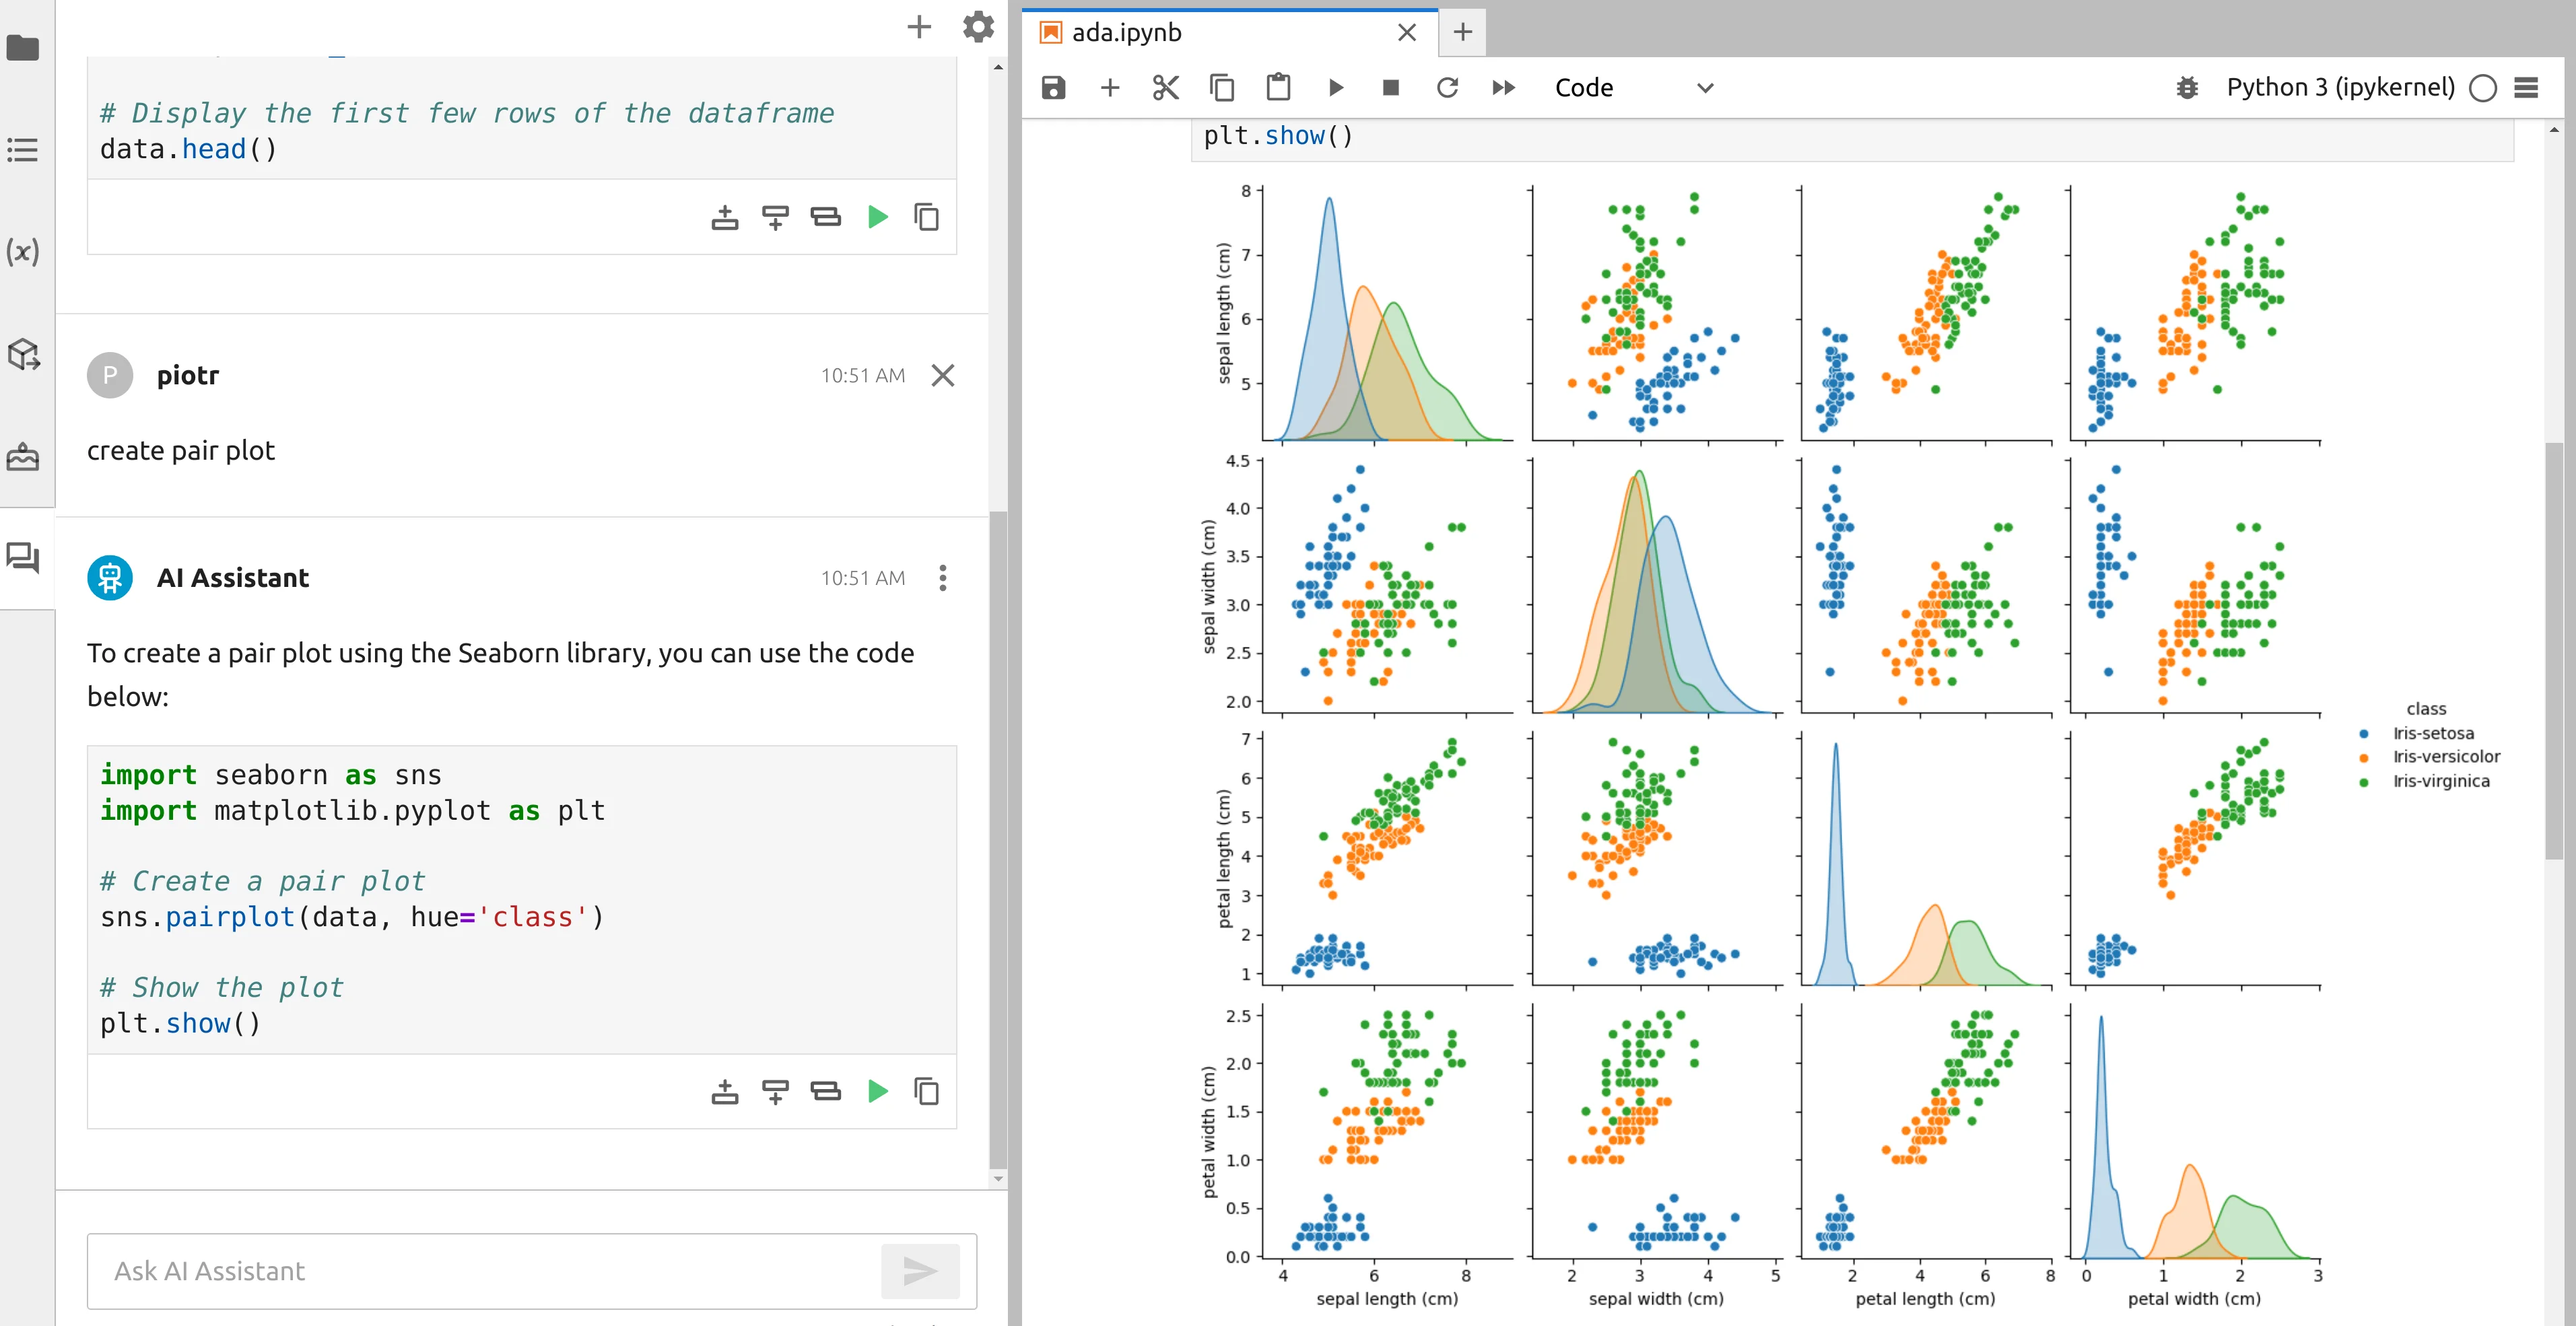
I start by uploading the dataset and asking ChatGPT to describe what it sees. Column names, row counts, data types, and missing value summaries. This baseline tells me whether the data is in decent shape or if I need to do preprocessing before the analysis even starts. From there, I move into targeted questions. I don't ask it to analyze everything at once. I break the analysis into discrete steps and verify each one before proceeding. Distribution checks, outlier detection, correlation matrices, segmentation. Each step gets its own prompt and its own verified output. This prevents the kind of compounding errors that happen when you rely on a single long chain of reasoning. When I need visualizations, I ask for specific chart types with labels, legends, and titles. Default matplotlib outputs from ChatGPT are functional but usually ugly. A quick request for "clean style with proper axis labels and a legend positioned outside the plot area" improves the readability substantially without much extra effort.
I export the final code after verification. Even if I'm not going to reuse it immediately, having the code means I can version it, share it, and run it on updated data later without rebuilding the analysis from scratch. ChatGPT itself does not store your code between sessions. Once the conversation closes, it's gone unless you saved it. The biggest practical limitation I encounter is that ChatGPT's code interpreter doesn't have persistent storage. You can't save intermediate datasets or checkpoints within the session. If the execution environment resets, you lose any computed variables that weren't explicitly saved to disk. I work around this by requesting that it write intermediate results to CSV files and download them. This is a minor inconvenience that adds about two to three minutes per step but protects you from losing hours of work if the session times out.
Bottom Line
ChatGPT is a competent assistant for data analysis tasks, not a replacement for someone who understands what the code is actually doing. It speeds up routine work significantly and lowers the barrier to entry for basic exploratory analysis. It also introduces risks around hallucinated column references, incorrect statistical choices, and missing context in long conversations. The tool is most valuable when you stay close to each step, verify outputs against your domain knowledge, and treat it as a collaborator rather than an autonomous system. If you do that, you'll get solid results quickly. If you hand it a dataset and walk away, you'll get something that looks right until you check the details, and by then you've already wasted time you could have spent verifying it in the first place.