What You Actually Need When Doing Data Science Work
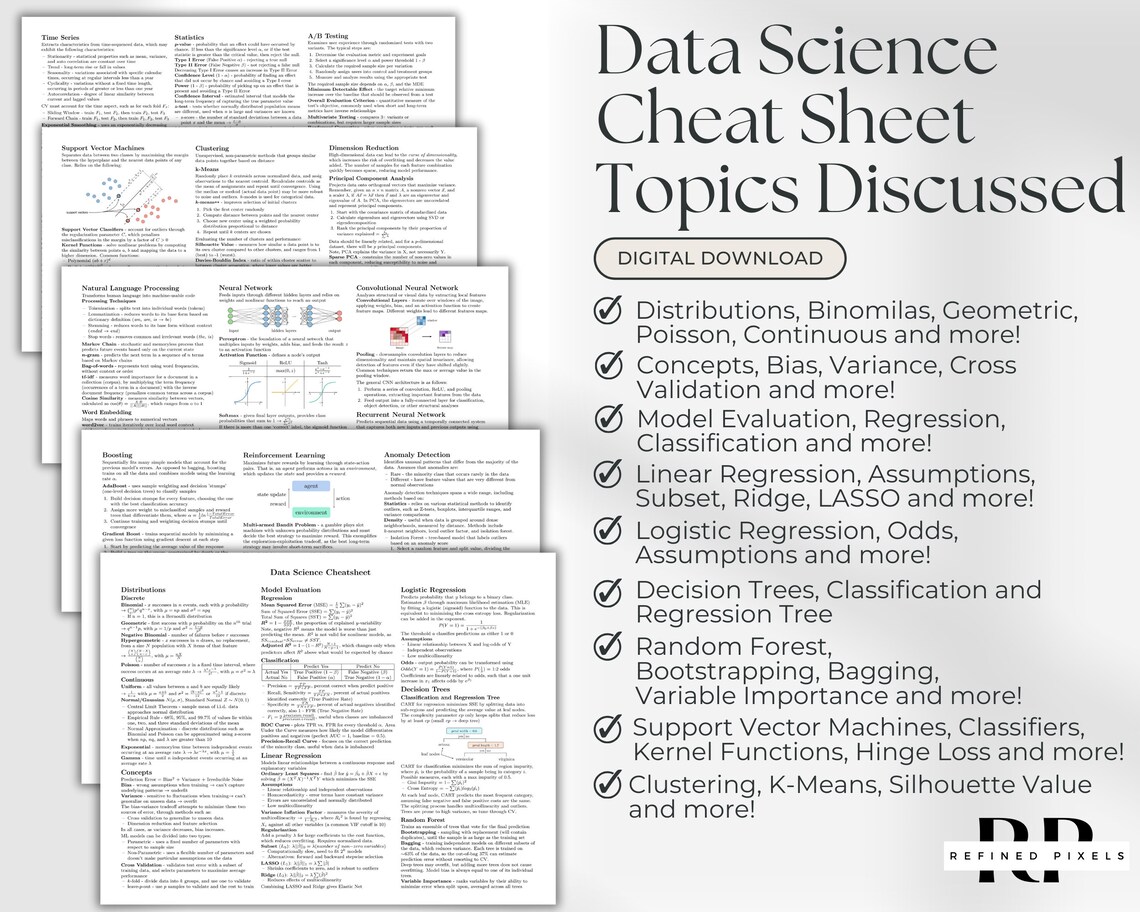
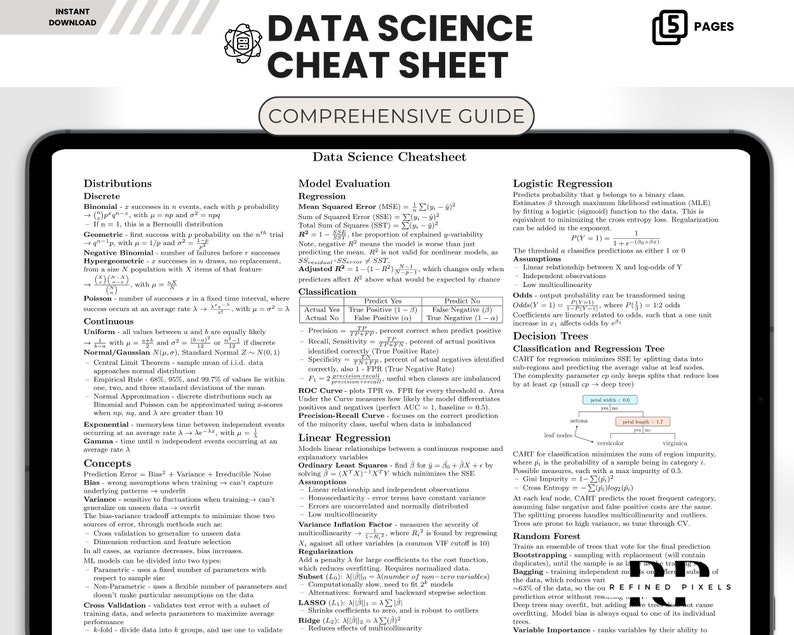
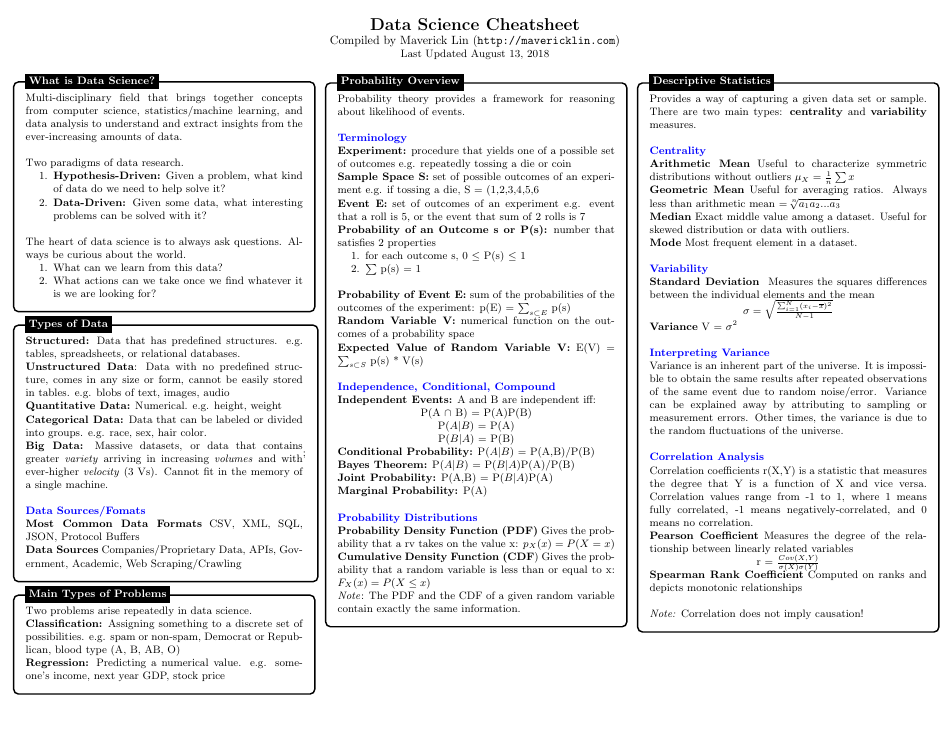
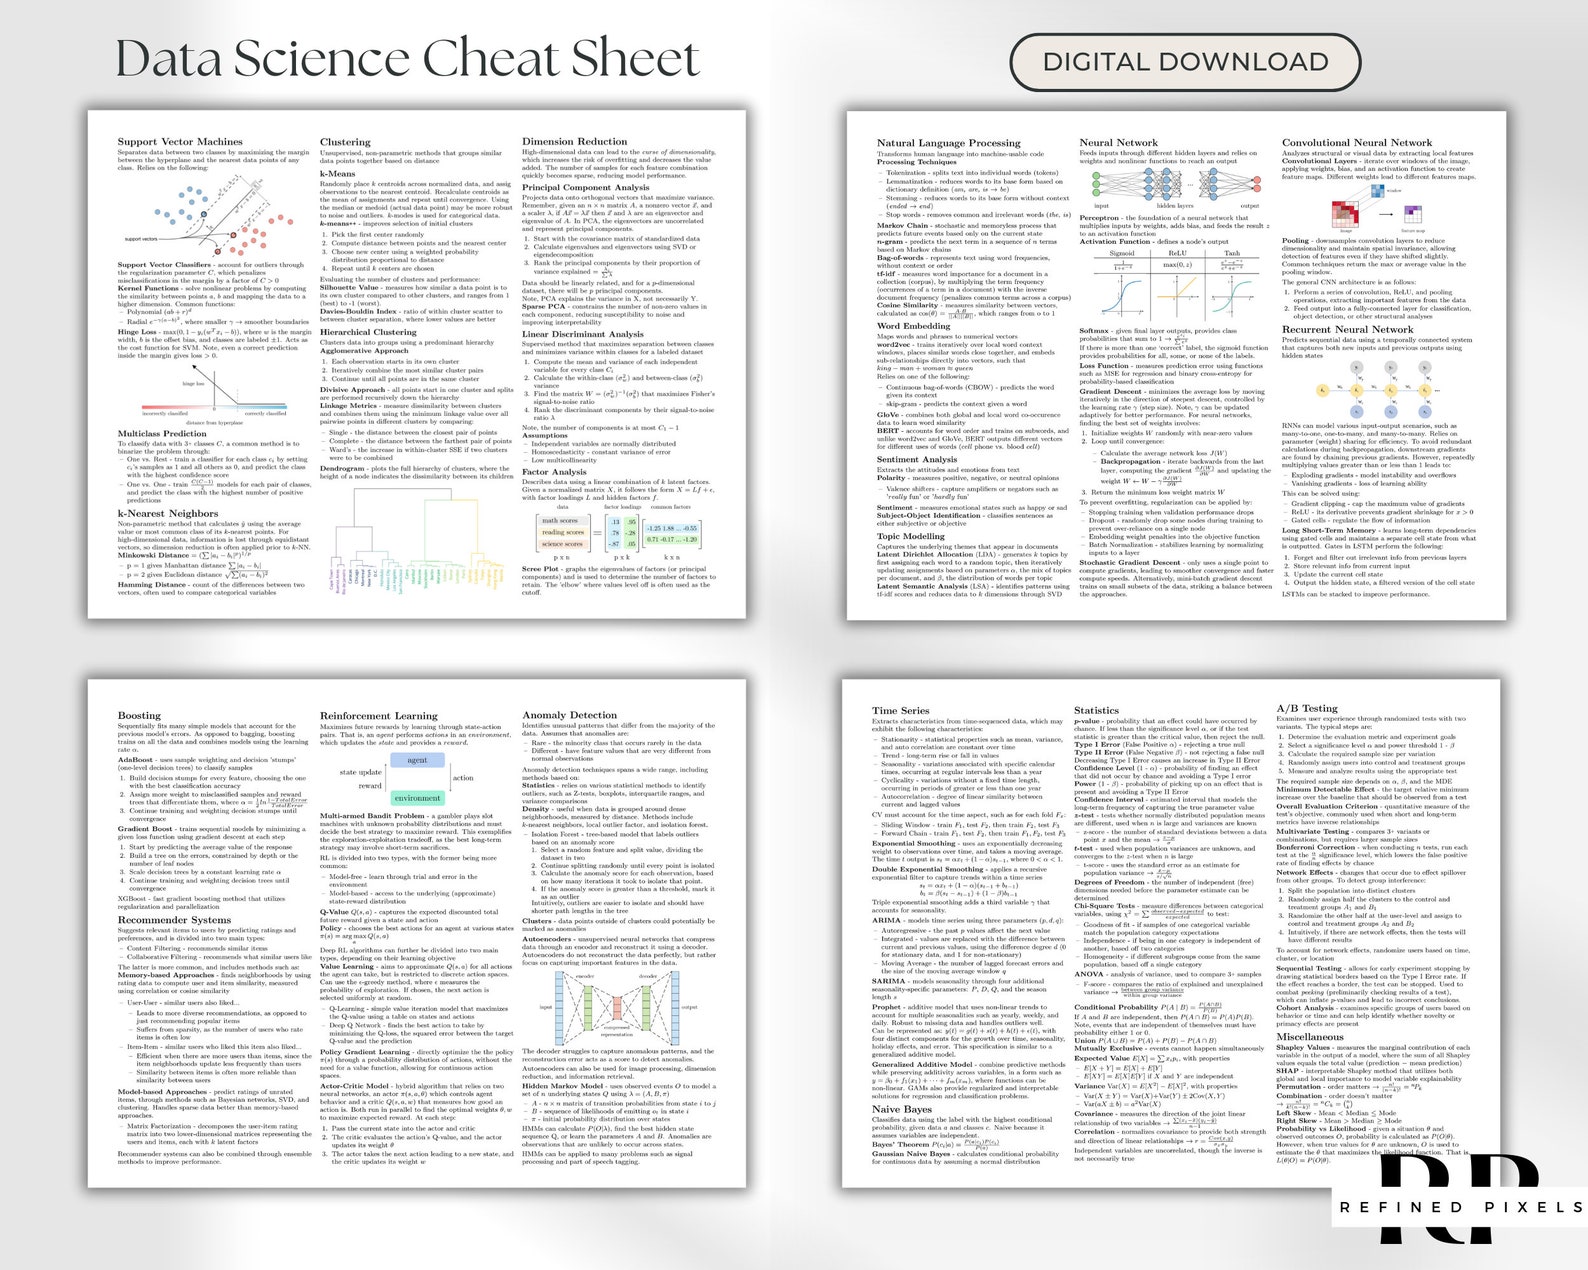
The Cheat Sheet For Data Science Weekly is a compact reference resource that aggregates common commands, functions, and workflows across Python, SQL, statistics, and machine learning libraries. It gets updated on a weekly cadence, which means the material stays relatively current without requiring you to hunt through documentation every time you hit a syntax wall. I picked it up about two years ago when I was spending roughly forty minutes per session just looking up how to reset index labels after a pandas merge, or remembering the exact argument order for scikit-learn's cross_val_score. The cheat sheet cut that lookup time down to maybe three minutes on average. That adds up across a project timeline.
Cheat Sheet For Data Science Weekly Structure and Coverage
Each issue runs about twelve to eighteen pages and breaks into sections covering Python data manipulation (pandas and numpy), visualization (matplotlib and seaborn), SQL query patterns, statistical testing fundamentals, and a rotating feature that goes deeper into one specific topic. The ML section covers scikit-learn API patterns, common model evaluation metrics, and pipeline construction basics. The visual section is practical, not theoretical. It shows you the exact code you need to produce a boxplot with outliers labeled, or a correlation heatmap with significance shading. The layout is deliberately dense. Someone who has never used a technical reference document will find it overwhelming at first. That is by design. The resource assumes you are working and need answers fast. It is not a textbook. It is a lookup tool. I keep a local copy open in one browser tab while I work in a Jupyter notebook in another. The habit of switching back and forth is mildly disruptive until you build muscle memory for where things live on the page. After about three weeks of regular use, that friction drops significantly.
How to Actually Use It Without Wasting Time
Most people download these resources and never open them again. That defeats the entire purpose. The effective approach is to treat it as a living workspace document. I flag entries with a highlighter tool in PDF mode when I encounter a command I use regularly but can never remember off the top of my head. Things like sklearn's train_test_split random_state behavior, or the difference between .loc and .iloc indexing under edge conditions. One specific problem I ran into involved missing data imputation across multiple dataframe partitions. The standard advice in the cheat sheet covers simple median fill, but it does not address the case where you have spatially clustered nulls in a time-series dataset. I hit that edge case on a forecasting project last fall. My workaround was to combine the cheat sheet baseline imputation with a forward-fill pass on grouped datetime partitions, then validate the result against a holdout window. The cheat sheet gave me the foundation. The gap was something you figure out through experience. Another thing most people miss about this resource. The statistical testing section lists p-value thresholds as if they are universal constants. They are not. In practice, the choice between 0.05 and 0.01 depends heavily on your sample size, the cost of a false positive in your specific domain, and whether you are doing single testing or multiple comparisons. The cheat sheet mentions Bonferroni correction in passing. It does not go deep because that is not what a cheat sheet does. You need to understand the limitation yourself.
Get the Full Details
Common Pitfalls When Relying on Reference Documents Like This
The biggest risk is treating the material as authoritative truth rather than a starting point. Pandas releases new versions roughly quarterly, and some syntax changes break code that looked correct six months ago. I encountered this when upgrading from pandas 1.5 to 2.0. A method I had relied on for groupby aggregation with named output columns changed its behavior. The weekly issue at that time had already flagged the breaking change, but people who were not actively reading each issue were caught off guard. Another issue is overconfidence in the ML section. The coverage of model evaluation is solid for beginner to intermediate work, but it glosses over class imbalance handling in the main text. If you are working on fraud detection or any dataset where the positive class is under two percent of your data, the accuracy metric shown in the reference material will mislead you. You need to look at precision-recall curves and AUC-PR instead. The cheat sheet references these terms but does not provide the implementation patterns. You have to go to the source documentation for that. A third limitation is the SQL section. It covers standard ANSI patterns and some common dialect-specific shortcuts, but it does not address query optimization for large-scale warehouse environments. If you are running queries against a production data lake with millions of rows, the syntax advice is correct but performance advice is absent. That requires a different kind of reference material altogether.
Download and Access Details
The weekly issues are available through the Data Science Weekly website. You subscribe with an email address and receive a PDF attachment each week. There is no paid tier for the core content. Some special editions and extended tutorials sit behind a premium subscription, but the main cheat sheet material remains free. I have been receiving it for over a year now without encountering any paywall on the standard weekly issues. You can also find archived issues on the site if you want to catch up on past topics. The archive is searchable by keyword, which is useful when you need to look back at a specific concept covered in an earlier issue. Navigation on the archive page is functional but not particularly polished. It works.
Whether It Is Worth Your Time
If you are doing data science work on a regular basis and find yourself constantly searching for syntax reminders or API parameter orders, this resource is reasonably efficient. It will not replace documentation or formal training. It will not make you a better analyst by itself. But it does reduce the contextual switching cost that happens when you leave your IDE to search for a command. That cost is real and it accumulates. If you are completely new to data science, the density will be challenging. You may benefit more from a structured course first and then using the cheat sheet as a companion resource once you have baseline familiarity. If you are an experienced practitioner, the value depends on whether your work involves enough variety across Python, SQL, and statistics to warrant a consolidated reference. A specialist who only does deep learning with PyTorch will find limited utility in most weekly issues. The resource is what it claims to be. It is a cheat sheet. Use it accordingly.