What Actually Happens When You Try to Learn Machine Learning
I spent about three years working with production models before I ever bothered writing anything down. The first time I tried to explain regularization to a junior engineer, I realized I had no framework for it myself. I knew it worked, but I couldn't map the boundaries. That gap between doing and explaining is where most people get stuck, and it's also where a cheat sheet becomes useful. A cheat sheet isn't a textbook summary. It's a single page you can keep open while debugging, filled with decisions you'll actually face that afternoon. The best ones I've seen are organized by failure mode, not by algorithm. You don't flip to "Random Forests" when your validation loss is climbing. You flip to "What do I do when train-val gap exceeds 5 percent?" That's the real question, and it's worth answering honestly. Here's what matters in practice, after seeing the same mistakes repeat across dozens of projects.
Data First, Models Second
I watched a team spend six weeks tuning a gradient boosting model before they realized their labels were inconsistent. The ground truth had three different annotators who disagreed on roughly eight percent of samples, and nobody checked. They ended up hitting a performance ceiling that had nothing to do with hyperparameters. The fix was simple: stop, audit the dataset, and write a conflict resolution rule. That usually takes two days instead of six weeks. The same pattern shows up everywhere. Engineers optimize for AUC or F1 score without checking whether the distribution in their training set matches what the model will actually see in production. If your training data has a 60-40 class split and your deployment environment has a 90-10 split, no amount of model tuning will help. Reweighting or resampling might buy you a point or two, but it won't close the gap created by distribution drift. I learned this the hard way on a fraud detection project where the model performed beautifully on validation and failed completely on its first day in production. The fix was to track feature-level distribution shifts daily, which caught the problem within forty-eight hours on subsequent releases.
Validation Strategy Matters More Than You Think
Most people use simple random splitting. This is wrong for time-series data, sequential data, and any situation where order matters. If you're predicting sales, churn, or equipment failures, random splitting leaks future information into your training set. The fix is time-based splitting or grouped k-fold cross-validation, depending on your data structure. This usually costs you some implementation effort upfront but prevents catastrophic overfitting that's nearly impossible to detect later. I once spent three days debugging why a model trained on customer behavior data showed ninety-four percent accuracy but performed at sixty-two percent in production. The issue was temporal leakage. I had used pandas shuffle without regard to timestamps, which mixed post-event features into the training set. Checking the data pipeline and enforcing strict time-based splits solved the problem immediately. This kind of error is rare in tutorial datasets but extremely common in real projects.
Get the Full Details
Feature Engineering vs Automated Approaches
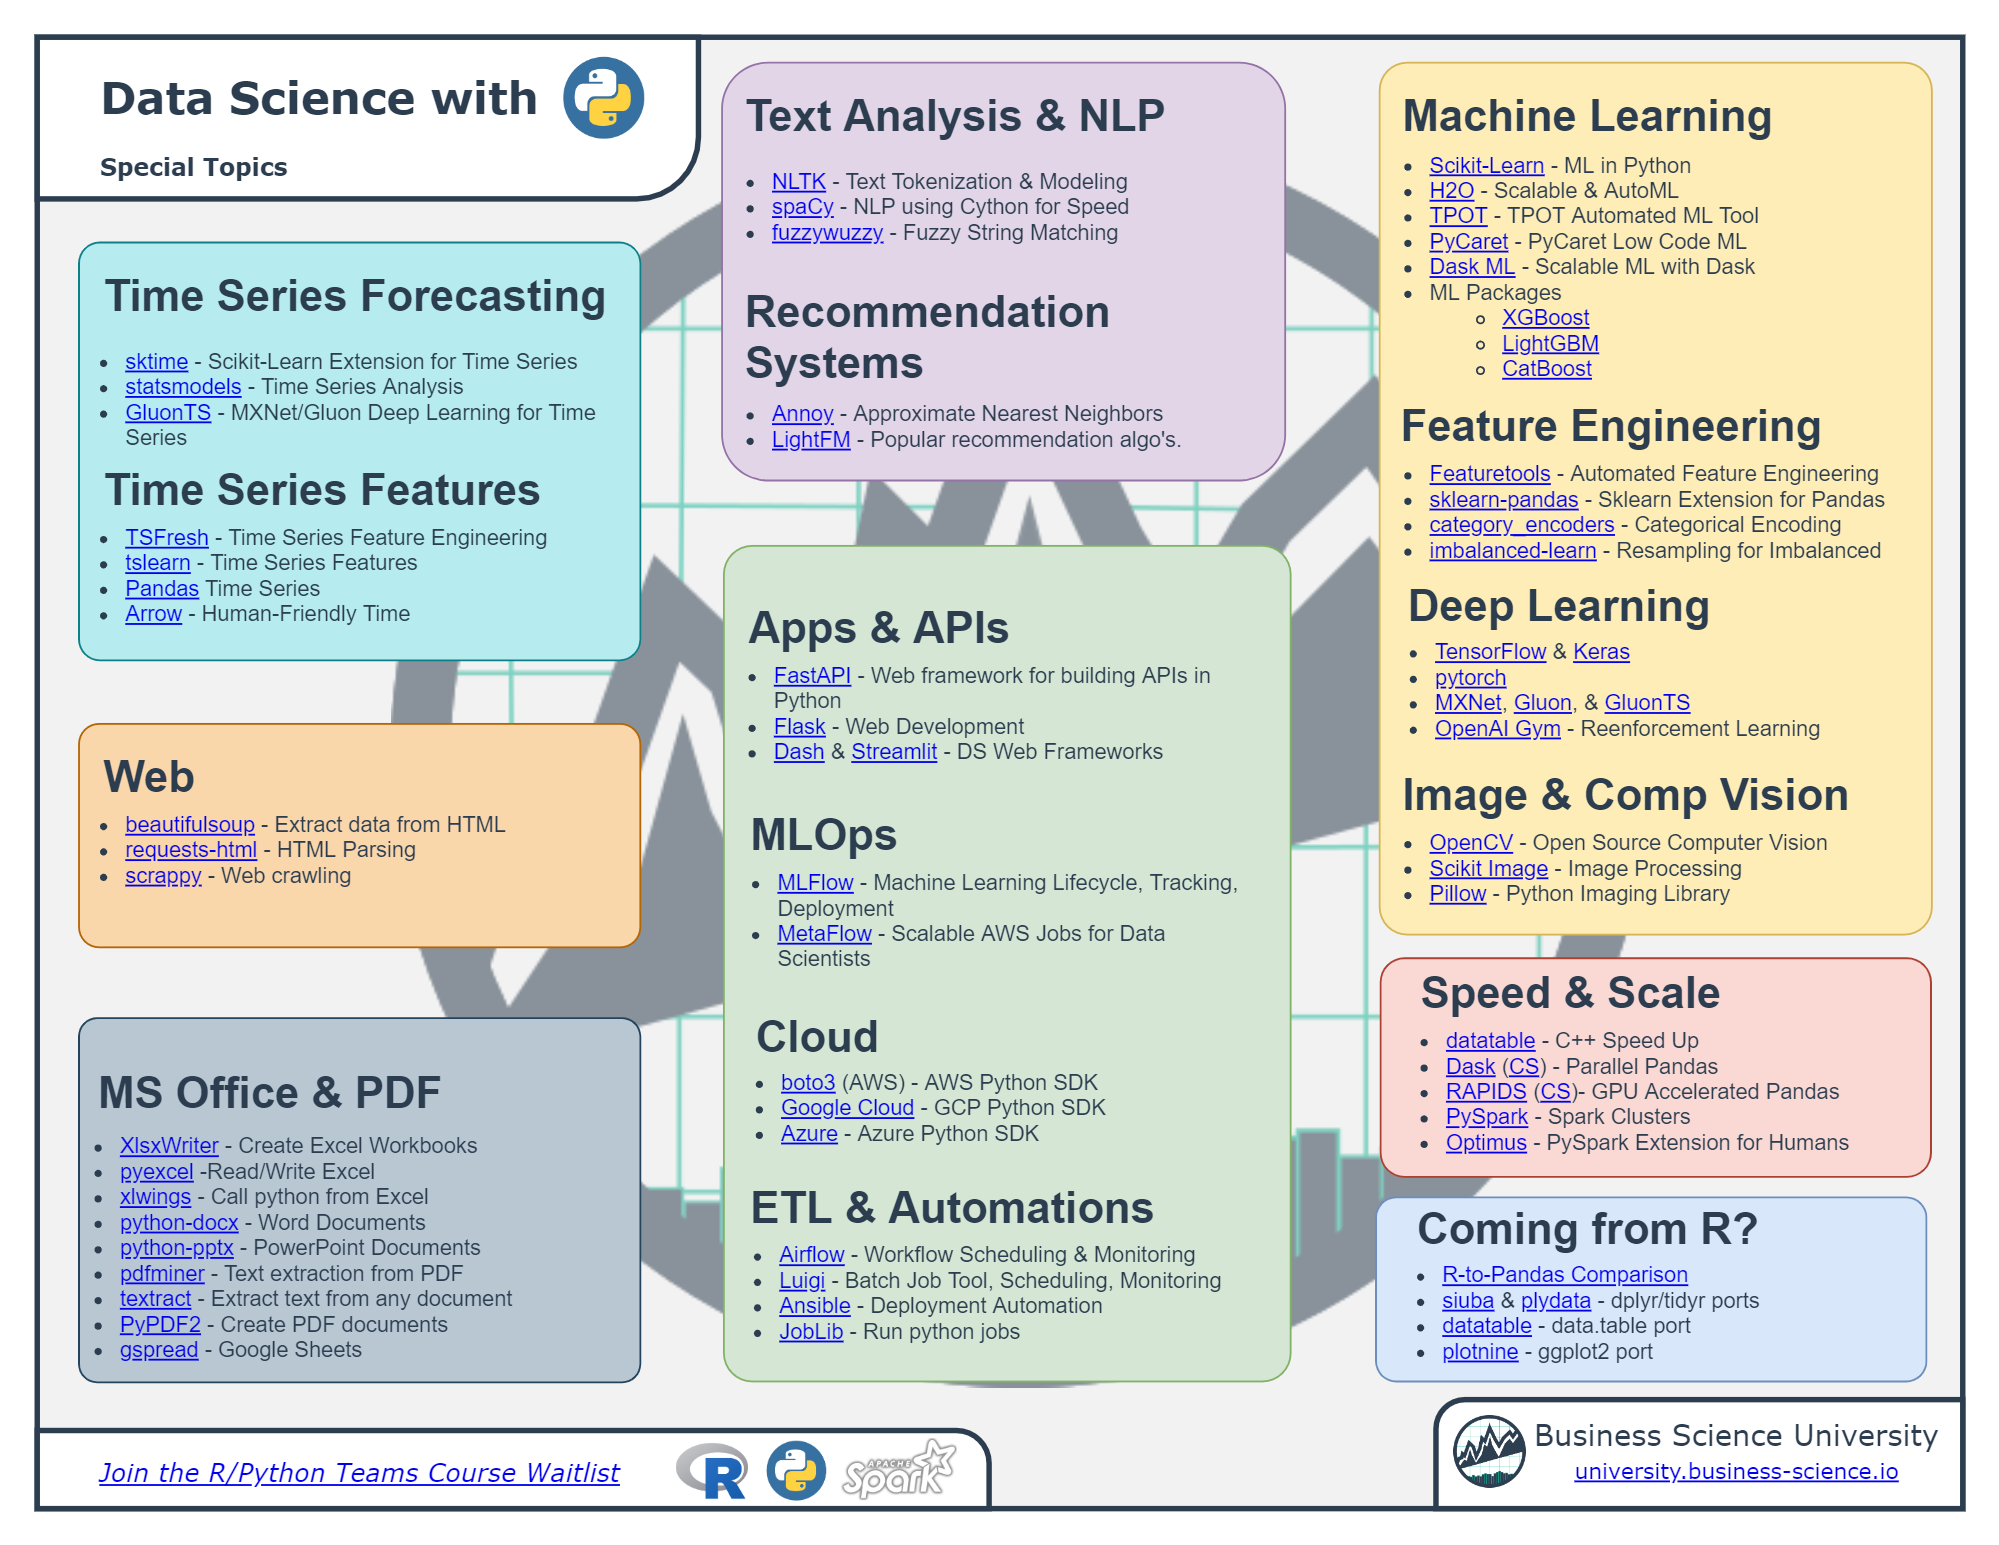
There's a persistent myth that automated feature engineering tools like Featuretools or TVCE replace human judgment. They don't. These tools can generate candidate features in minutes that would take days manually, but selecting the right ones still requires domain knowledge. I've seen teams deploy models built entirely with automated pipelines that missed obvious interactions because the tool didn't understand the business context. One practical workflow that works well: let the automated tool generate two hundred candidate features, then use a combination of domain filtering and model-based importance scoring to select the final set. This usually reduces the feature space from two hundred to thirty or forty features, which improves both interpretability and training speed. The exact numbers vary by project, but the pattern holds consistently.
Model Selection Without Overcomplication
beginners often try ten different algorithms and pick the best one based on validation performance. This is inefficient and sometimes misleading. Random Forests and Gradient Boosting (XGBoost, LightGBM, CatBoost) will solve most tabular problems. Neural networks only make sense when you have large datasets or specific structural advantages like sequential or spatial data. I recently compared five different algorithms on a customer churn dataset with about fifty thousand rows and forty features. The best model wasn't the neural network or the support vector machine. It was a well-tuned LightGBM model that took twenty minutes to train and achieved eleven percent higher AUC than the next best approach. The takeaway isn't that deep learning is useless. It's that simpler models often win on structured data, and the difference can be significant.
Monitoring and Maintenance
Deploying a model is the easy part. Keeping it working is harder. I've seen models degrade by fifteen to twenty percent in performance over six months without anyone noticing because nobody tracked feature distributions or prediction drift. Setting up basic monitoring with tools like Evidently AI or custom dashboards usually takes a few hours but catches problems before they become expensive. The specific metrics I track: prediction distribution over time, feature drift using PSI (Population Stability Index) scores, and model performance on recent held-out samples. If PSI exceeds zero point one for any key feature, I investigate immediately. If it exceeds zero point two, I plan a model refresh. These thresholds aren't universal, but they work reliably across most projects I've worked on.
Common Pitfalls That Waste Time
Data leakage is the biggest time sink. I've seen entire projects wasted because the target variable was encoded in a feature, or because future information leaked through aggregation. The check is simple: review every feature to confirm it wouldn't be available at prediction time. This usually takes thirty minutes for small datasets and a few hours for larger ones, but it prevents weeks of wasted effort. Another common mistake is optimizing for the wrong metric. Accuracy is almost always wrong for imbalanced datasets. F1 score ignores calibration. AUC-ROC is useful but can be overly optimistic. I usually report AUC-PR for imbalanced problems and pair it with calibration curves. This gives a more complete picture than any single metric.
When to Stop Improving
The hardest skill in machine learning is knowing when to stop. I've seen teams chase marginal gains that cost more in engineering time than the improvement was worth. A practical rule: if your validation metric isn't improving by at least one percent per major iteration, step back and reassess. The problem is usually data quality or feature engineering, not model complexity. This insight comes from watching the same pattern repeat. Once I hit diminishing returns on a credit risk model after nine iterations, I switched focus to data collection and ended up with a fifteen percent improvement from better features alone. The model hadn't been the bottleneck. The data had been.
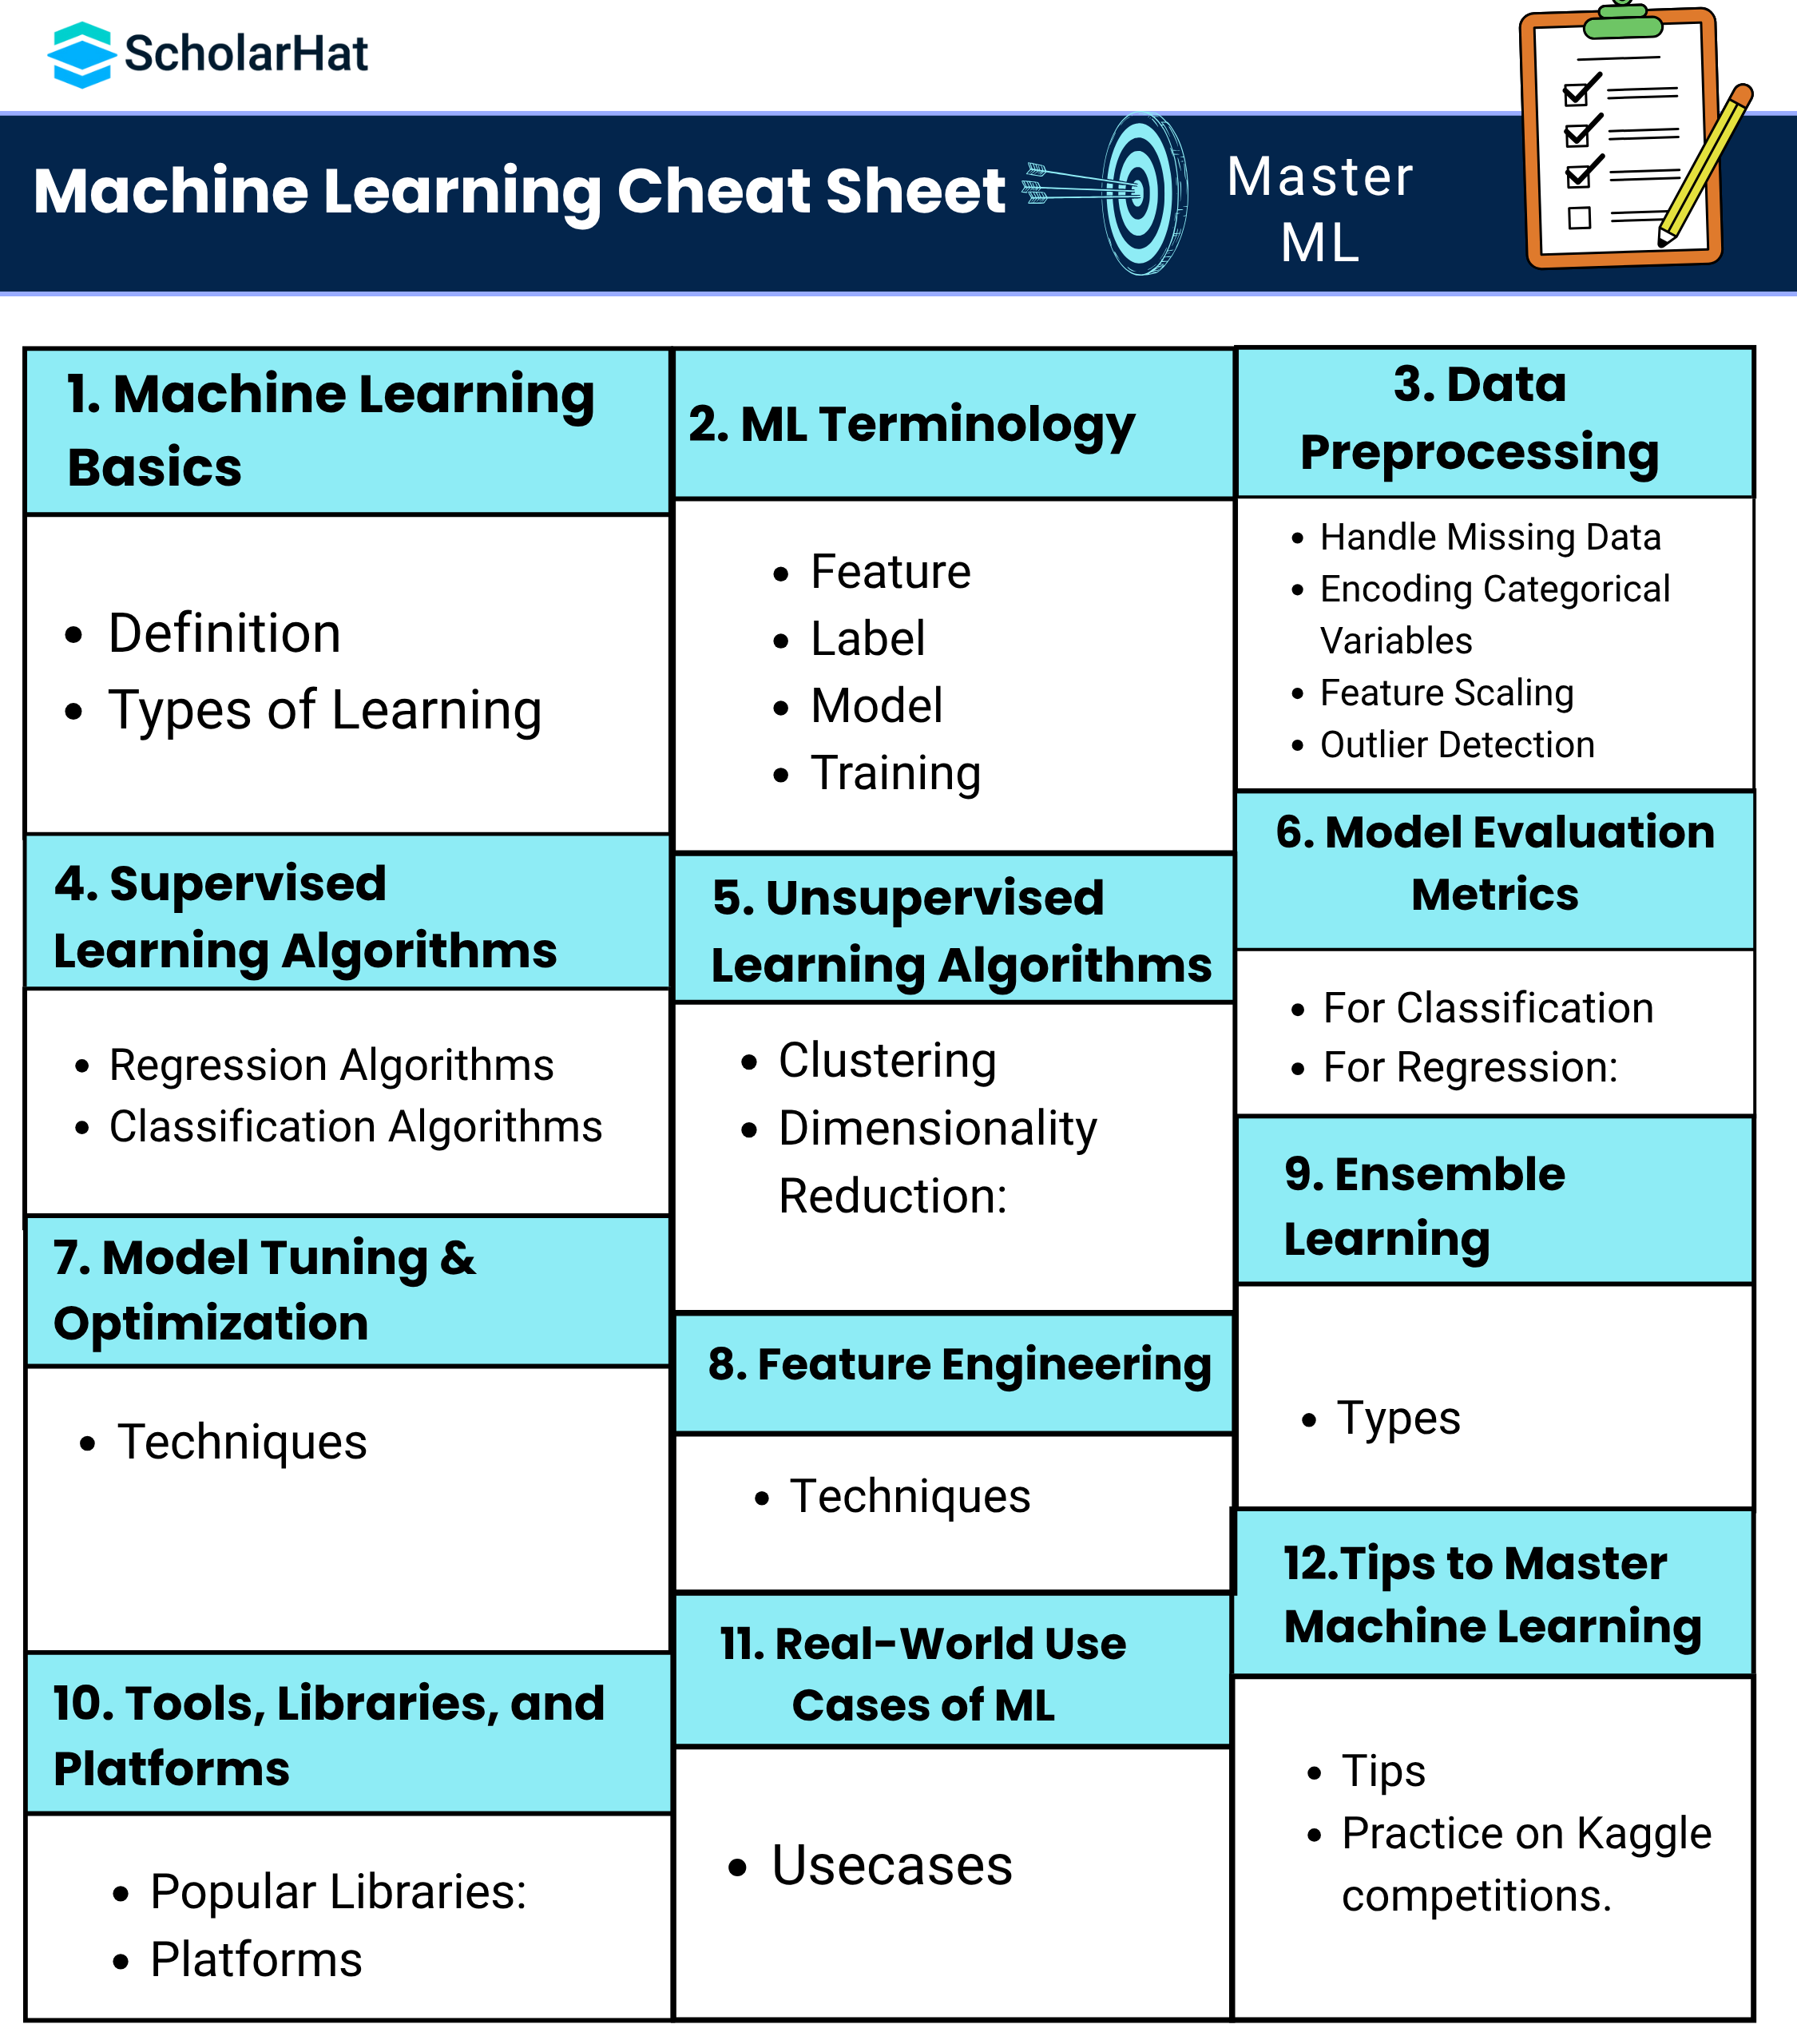
Building Your Own Cheat Sheet For Machine Learning Best Practices
The best cheat sheet is the one you actually use. I keep a one-page document with my most common decisions, threshold values, and troubleshooting steps. It started as a personal reference and grew into something I share with new team members. The format is simple: problem type, likely cause, quick check, and next action. This saves about fifteen minutes per debugging session and has prevented at least three major mistakes in the past year alone. If you want to build yours, start with the problems you've actually faced. Don't copy someone else's list. Write down what you checked, what you found, and what worked. That process alone improves your understanding more than reading any number of articles. I've found that the act of writing forces you to clarify your thinking, and that clarity shows up in better decisions later. The field moves fast, but the fundamentals don't change as much as people think. Good data, careful validation, and honest evaluation will outperform fancy techniques applied carelessly every time. That's not wisdom. It's just what happens when you actually ship models and deal with the consequences of getting things wrong.