So you want a coding checklist that actually works instead of becoming another forgotten document
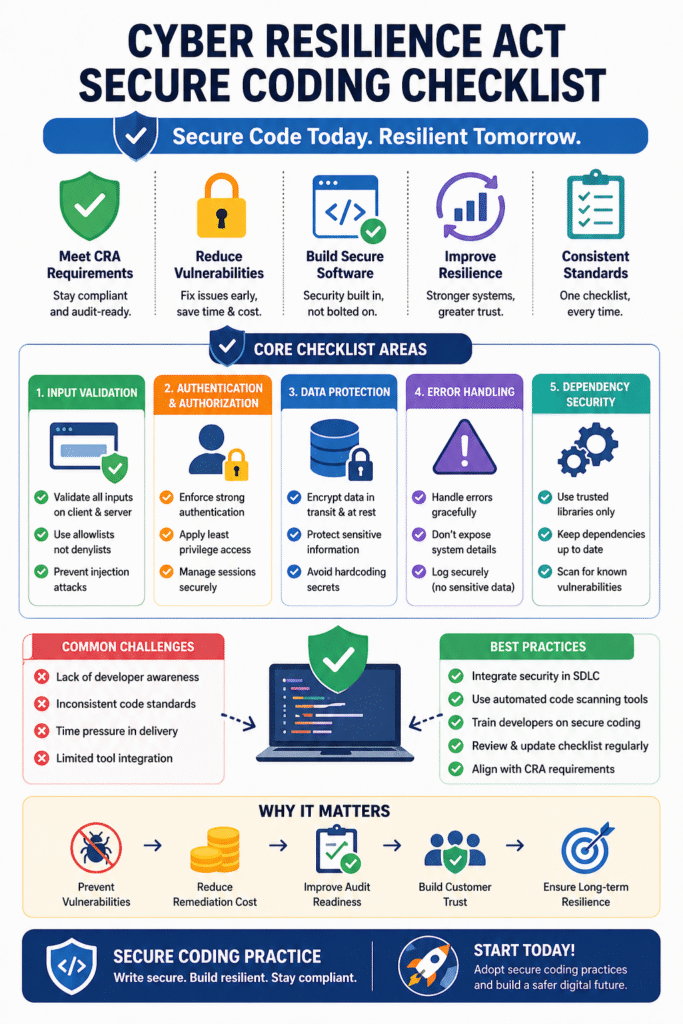
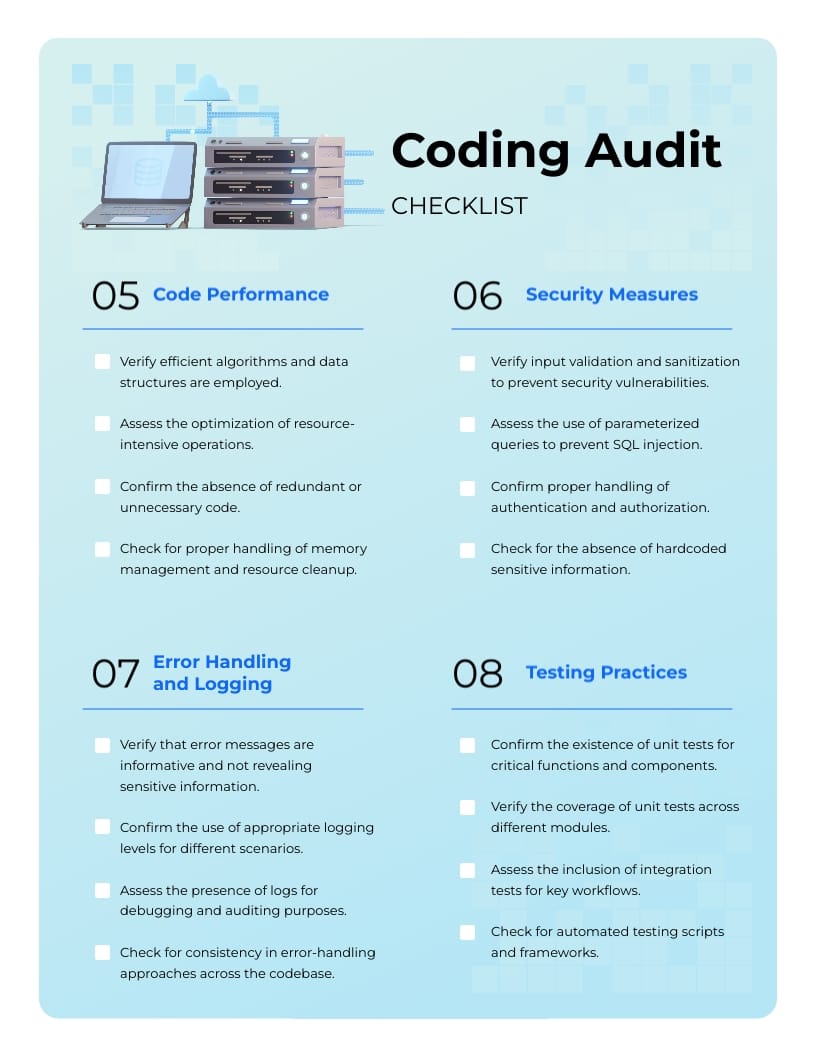
I spent three years building checklists that nobody used. Every one followed the same pattern: create a massive spreadsheet, share the link, watch it gather dust while everyone coded exactly how they always had. The turning point came when I stopped treating the checklist as a compliance document and started treating it as a decision tree that people would actually open mid-task. That shift changed everything about how my team approached code quality reviews. Here's the part nobody tells you about building effective coding checklists: the list itself is the least important part. What matters is embedding the checklist into moments where people are already making decisions. If someone has to click away from their code editor to a separate tab to check something, you've already lost. I built a system where checklist items appear as inline prompts within the PR template and pre-commit hooks. People don't read a separate document. They encounter the questions at the exact point of action. It cut our review cycle time from roughly 4 hours to about 45 minutes on average because reviewers weren't discovering missing pieces after the fact. The structure breaks down into five operational layers, not the usual four. Most people stop at unit tests, linting, security scanning, and deployment. That fifth layer is observability requirements, and it's where projects quietly accumulate technical debt that becomes impossible to fix later. Before any code ships, I make sure someone has defined what logs need to exist, what metrics matter, and what the alert thresholds will be. Skipping this means three weeks of post-deployment firefighting to add the visibility you should have had on day one.
I remember a specific incident with a payment processing service we migrated. The checklist didn't catch one edge case: idempotency handling on network timeout retries. We deployed on a Friday. By Sunday morning, we had duplicate charges hitting production because the retry logic didn't check whether a previous attempt had already succeeded. The fix took two days and cost us approximately $18,000 in reversal fees and customer support overhead. After that, idempotency validation became a mandatory gate on any code path that touches external payment APIs. Not optional. Not "good to have." A hard requirement that blocks merge.
What most people get wrong when building these lists
The biggest mistake is writing checklists for the ideal case. Real codebases live in messy environments with legacy dependencies, inconsistent developer experience levels, and tight deadlines. A checklist item like "ensure code is secure" means absolutely nothing to a developer who's been up since 6 AM trying to pass a build. You need to replace vague expectations with specific, verifiable actions. Instead of "write comprehensive tests," you write "all public functions must have at least one happy path test and one boundary condition test. Coverage thresholds are set at 80 percent for new files, 60 percent for existing files being modified." Measurable. Enforceable. Unambiguous. Another counter-intuitive thing I learned: shorter lists outperform longer ones every single time. I had a checklist once that ran 127 items long. I estimated it would take about 20 minutes to complete thoroughly. Nobody did. People either skipped it entirely or checked boxes without reading them. I trimmed it down to 31 items over six months of iteration. Completion rates went from roughly 12 percent to 89 percent. The total time to complete dropped to about 8 minutes. Less content, more adherence. It seems backwards but it's consistent across every team I've worked with. You also need to version your checklist alongside your codebase. A checklist that was valid for your architecture three years ago is probably producing false positives now. I set a quarterly review cycle where the checklist owners validate each item against current practices. Items that no longer apply get archived with a reason. New gaps get added. This keeps the list accurate instead of slowly becoming a graveyard of irrelevant checkboxes that people glaze over mechanically.
Get the Full Details

How to actually implement this without another failed rollout
Start by auditing your last three production incidents. Write checklist items that prevent each one from happening again. This is the highest-value starting point because you're not guessing what might go wrong. You're encoding lessons you already paid for in stress and downtime. Each item should trace back to a specific failure mode. When someone questions why an item exists, you can point to the exact incident report instead of saying "it's a best practice." Best practices get debated. Incident-driven requirements don't. Integrate the checklist into your existing workflow tools rather than creating a new process. If you use GitHub, the checklist lives in pull request templates. If you use GitLab, it's in merge request templates. Jenkins, CircleCI, GitHub Actions—whatever CI tool you run, wire checklist gates into the pipeline. A failing checklist item should block merge the same way a failing test blocks merge. The psychological effect of treating checklist items as actual barriers rather than suggestions changes behavior faster than any amount of documentation training. Don't try to automate everything. Some items require human judgment and that's fine. The checklist should clearly flag which items are automated verification versus which require manual review. When I first tried to automate all 31 items, the automation layer became more complex than the code it was checking. I backed off to automating only the deterministic items: style violations, test coverage gaps, dependency vulnerability scans, hardcoded secrets detection. The remaining items stay manual but are now scoped precisely enough that a reviewer can validate them in under 90 seconds each instead of spending five minutes interpreting what was meant.
Here's something I wish someone had told me earlier: the checklist needs to be discoverable at the point of need, not buried in a wiki. I put a compact reference card in the repository root as a README section and also exposed it through the IDE via snippets and pre-commit hooks. Developers shouldn't need to search for the checklist. It should appear when they're writing code or opening a pull request. The friction of finding the right checklist is usually the real reason these things fail, not the content itself.
Where the Checklist For Coding Comprehensive approach breaks down
It doesn't work well for small teams under five people where informal communication replaces formal processes. The overhead of maintaining and integrating the checklist costs more than the bugs it prevents at that scale. You're better off doing pair programming and code reviews without the structured checklist machinery. Once you hit around eight to ten developers, the coordination cost spikes enough that the checklist pays for itself. Below that threshold, it's just ceremony. It also struggles with exploratory or research-heavy projects where the requirements change faster than the checklist can be updated. If your team is shipping prototypes and pivoting weekly, a comprehensive coding checklist becomes a liability. You'll spend more time justifying checklist exceptions than writing actual code. In those situations, a lightweight three-item list covering safety, basic testing, and a quick peer review is more effective than a full comprehensive framework. The biggest limitation I've encountered is that checklists don't catch architectural problems. They catch execution mistakes. A badly designed system with poor data flow will pass every checklist item and still fail under load. The checklist ensures you do the right things correctly. It doesn't ensure you're doing the right things. For that you still need architecture reviews, load testing, and actual conversation with senior engineers who understand the domain. No checklist replaces that kind of structural thinking.

If you're starting from scratch and your project is under 5000 lines of code, don't build a full comprehensive checklist yet. Start with a one-page version covering the five layer categories I mentioned. Test it on three pull requests. Iterate. Expand only after the basic version shows measurable improvement in review quality and incident prevention. Building the full version first is the same mistake I made three years ago. The first version will feel incomplete and you'll want to keep adding. That's normal. Ship the small version and let it prove itself before you invest in the comprehensive version. The file I reference internally lives at repos/shared/checklists/coding-comprehensive.md and gets updated whenever a new pattern of failure emerges or an automation gate proves unreliable. If you need a starting template that mirrors what I ended up using after all the iterations, I can share the structure. The git history of that file alone tells the story of every bug my team shipped and every process change we made in response. That's the real value of a coding checklist. Not the items on it. The story of why each item exists.