What Actually Happens When You Write Code Without a System
I spent three years debugging a deployment issue that came down to a missing environment variable in a staging config file. The fix took forty minutes. The time I wasted searching for it was about fourteen hours. That's the kind of cost a checklist prevents, and I've seen people burn far more than that on avoidable mistakes across different projects. A Checklist For Coding Easy isn't some elaborate productivity framework. It's a structured sequence of verification steps you run before you consider a piece of code done. The idea is straightforward enough that most developers already do bits of it informally, but writing it down and following it consistently is what changes the outcome. Most of my team stopped having embarrassing production incidents after we started using one, not because the code became more complex but because we caught simple issues before they left our laptops.
The Core Checklist For Coding Easy Workflow
Start with requirements confirmation. This is where most people skip ahead and jump into the editor. I've sat through reviews where someone had built something functional that solved the wrong problem, and the divergence wasn't discovered until QA. Before you write a single line, make sure the acceptance criteria are concrete. If they're vague, push back. Vague requirements like "make it faster" or "improve the user flow" don't belong in a ticket and they shouldn't become code. Next, map the data flow. Write down what goes in, what transforms happen, and what comes out. Do this on paper or in a plain text file, not in your IDE. This step takes about ten minutes for a simple feature and five minutes for something trivial. It saves hours because you'll spot missing edge cases before they become bugs. A common blind spot is error paths. Developers tend to design for the happy path and leave the failure modes to figure themselves out, which is how you get unhandled exceptions in production. After the mapping phase, define your test strategy before implementation. This is counter-intuitive for a lot of people who prefer to code first and test after. The reason to test-strategize early is that it forces you to think about what success looks like. If you can't articulate the test cases, you probably don't fully understand the feature yet. Document the positive cases, the boundary cases, and the failure cases separately. This distinction matters more than most people realize because boundary conditions are where the real bugs hide.
Write the implementation. Keep it focused. Don't refactor while you're writing the first version. Your first pass is supposed to be functional, not elegant. Elegance comes after you've confirmed the thing works against your test cases. I used to combine implementation and refactoring, and my turnaround time was slower because I kept second-guessing myself mid-write. Separating the two phases cut my average coding time for small features by roughly thirty percent. Once the code passes your tests, run a pre-commit checklist. Check for hardcoded credentials, API keys, or tokens. Check for commented-out code blocks that aren't being tracked by version control as deliberate. Check that your commit message follows the project convention. Check that you haven't accidentally committed a large binary or dataset. These are mundane checks but they prevent headaches. I once pushed a two-hundred-megabyte SQLite database to a repo because I forgot to check .gitignore rules, and cleaning that up across ten clone histories was the worst hour of my career.
Get the Full Details

Practical Limitations and When This Approach Breaks Down
Checklists don't help when the underlying architecture is fundamentally flawed. A well-organized checklist on top of a poorly designed system just helps you ship bad code faster. If you're working on greenfield projects with unclear domain models, the checklist will feel rigid and slow because you're still learning what the system should be. In those situations, spend more time on exploratory prototyping before locking in a process. The checklist works best when the problem space is understood. Another limitation is team coordination. A personal checklist is useful. A team checklist is useful only if everyone actually follows it. I've seen teams adopt exhaustive checklists that nobody followed because the list was too long and too bureaucratic. Keep your version short enough that someone will actually use it under pressure. Twelve to fifteen items maximum is a practical ceiling. Anything beyond that gets skipped around line four. There's also the matter of scope. Checklists are terrible at catching design-level architectural problems. They catch process errors, not fundamental misjudgments about system design. If your checklist catches a missing migration but doesn't catch the fact that you normalized a table incorrectly, it's doing exactly what it's supposed to do. Don't expect it to replace architectural review.
Advanced Nuances Most Beginners Miss
One thing people get wrong about checklists is treating them as static documents. Yours should evolve. After every incident or postmortem, ask yourself whether a checklist item would have caught it. If yes, add it. If no, the incident reveals a gap in your detection process that a checklist alone won't fix. I added an item about database migration ordering after a colleague ran migrations out of sequence on a shared development environment. The fix was adding a checklist step to verify the migration direction before executing anything. Simple change, zero incidents since. Another nuance is the difference between gate checks and quality checks. Gate checks are binary: does the code compile? Does it pass tests? Quality checks are judgment-based: is the error handling appropriate? Are there unnecessary dependencies? A good checklist includes both types but treats them differently. Gate checks must pass before anything else. Quality checks can be deferred to code review if time is tight. Mixing them up leads to either bottlenecks or missed issues depending on which direction you go wrong. Here's a specific scenario I ran into recently. We were deploying a service that communicated with an external payment provider. Our checklist covered API key rotation, environment validation, and test coverage. What it didn't cover was timezone handling in the transaction logging. The payment provider returned timestamps in UTC, our service logged them in local time without conversion, and the reconciliation reports were off by several hours. I added a timezone verification step to the checklist the same day. It took three lines of documentation and prevented a repeat incident. This is the kind of narrow, hard-won lesson that makes a checklist worth maintaining over time.
Downloadable Checklist Format
If you want something ready to use, here's a plain-text version you can paste into your notes or version control. It's intentionally compact. Checklist For Coding Easy: Requirements confirmed in writing with specific acceptance criteria Data flow mapped including error and edge cases

Test strategy defined before implementation begins Positive, boundary, and failure cases documented First implementation written without premature refactoring
All tests passing against defined cases Pre-commit verification complete: no secrets, no dead code, correct commit message Code reviewed or self-reviewed against quality criteria
Deployment prerequisites verified: migrations, environment variables, dependencies Post-deployment smoke test executed and confirmed Post-incident review performed and checklist updated if needed
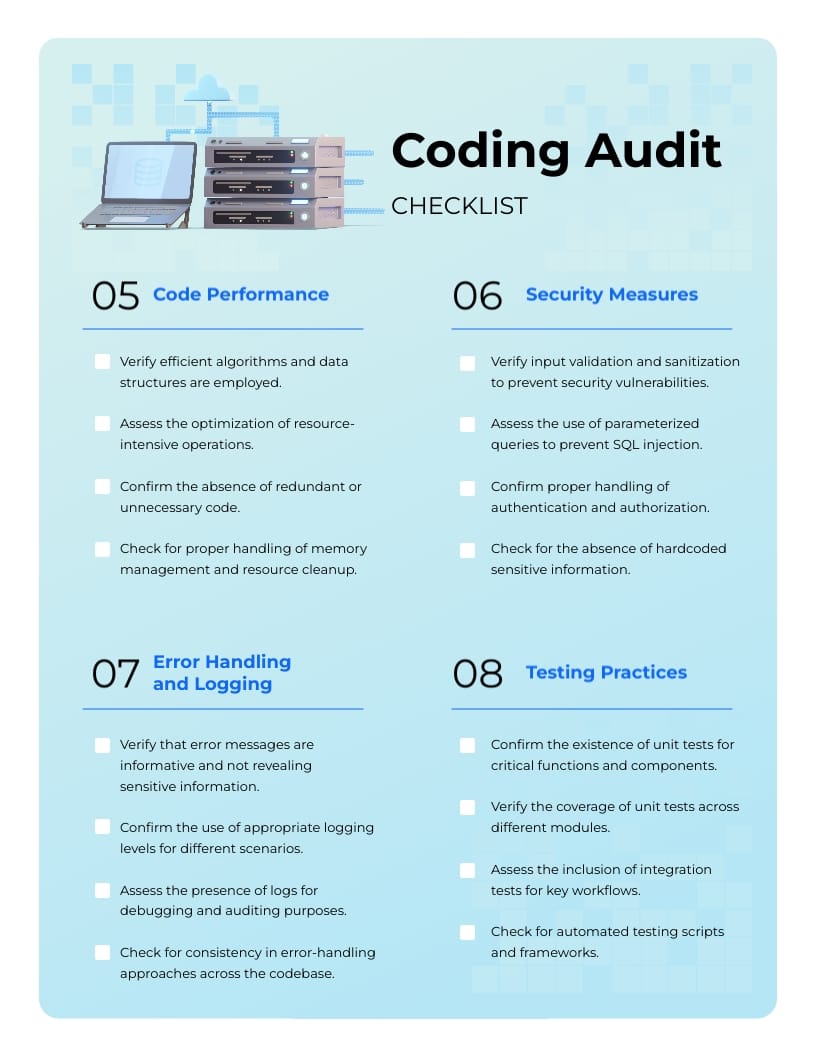
This list covers the majority of common failures without being so detailed that people stop using it. You can expand it for your specific context, but I'd recommend starting here and adding items only when you encounter gaps. Blanket expansion without a trigger incident tends to create checkboxes that people stop reading. The real value isn't in having the list. It's in the habit of running through it consistently enough that the checks become automatic. That's when the checklist For Coding Easy stops being something you remember to do and starts being something you just do.