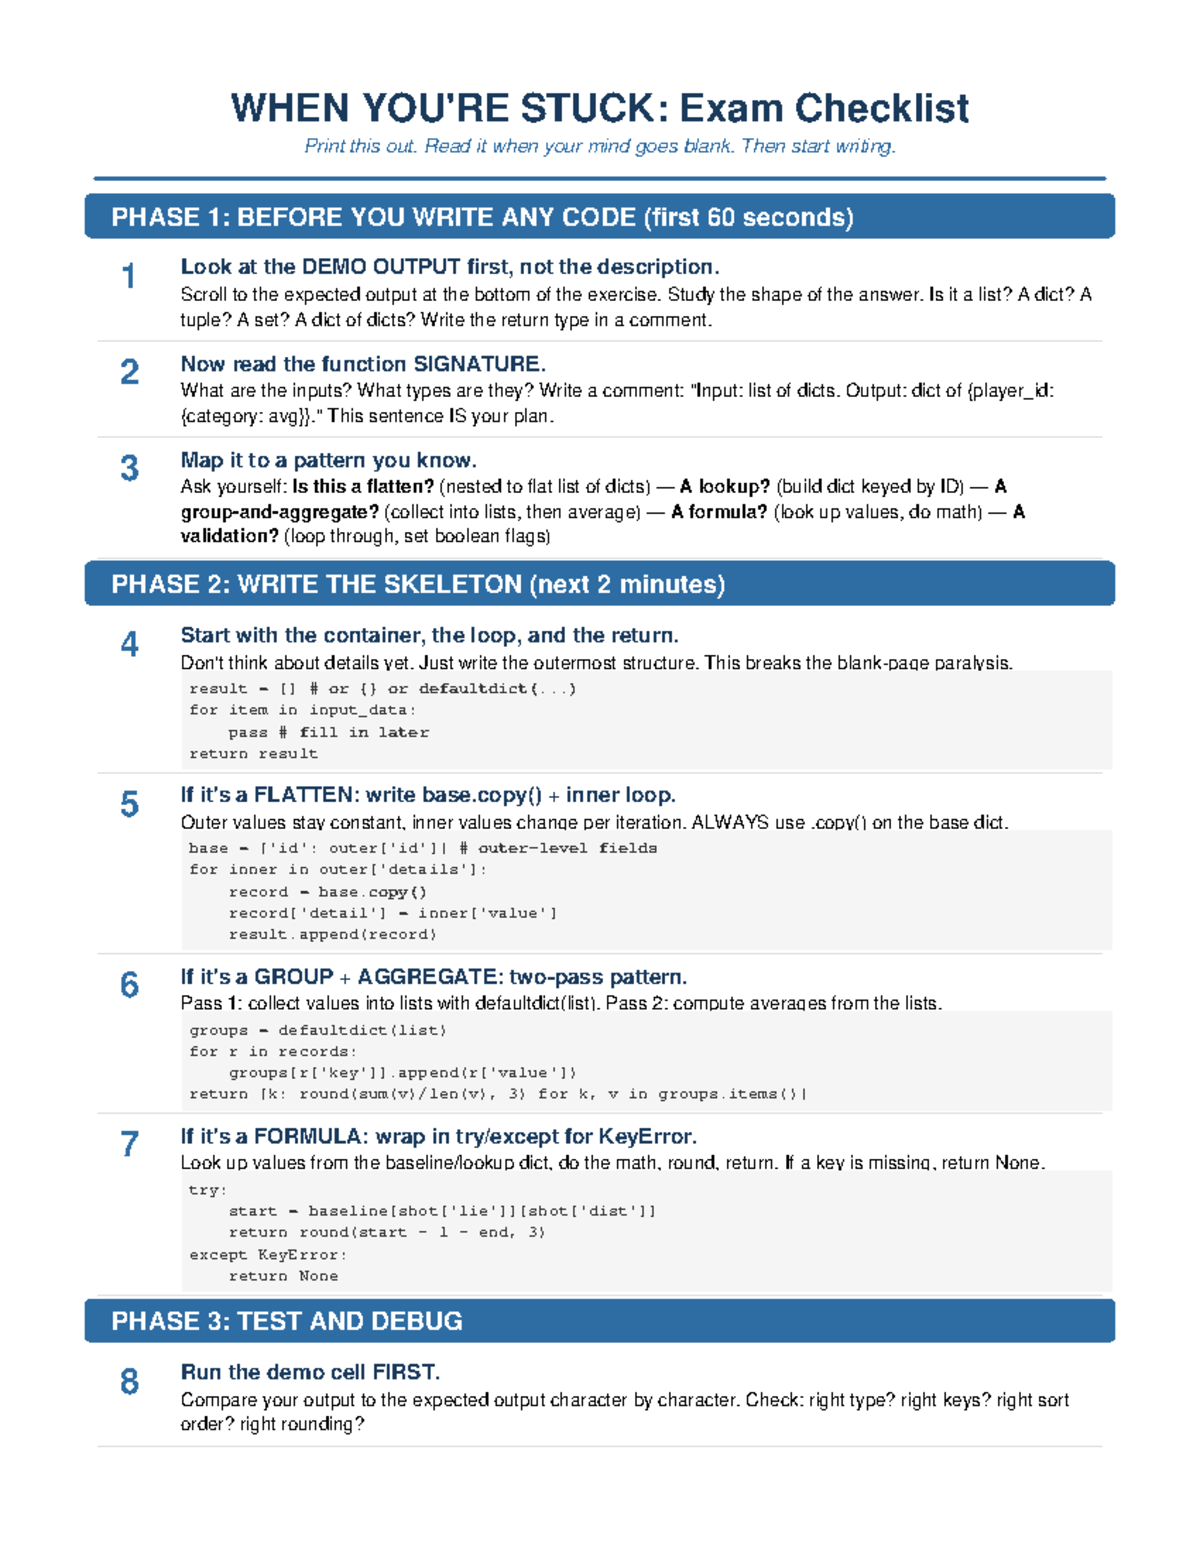
Why You Need a Yearly Coding Checklist
Most teams don't have one. They write code for twelve months, ship whatever ships, and then wonder why their architecture looks like a crime scene by Q4. A yearly checklist for coding isn't about productivity hacks or motivational slogans. It's a structured review of your codebase, practices, tools, and team habits that catches problems before they compound into full-blown technical debt.I spent three years working at a startup where we shipped fast and never looked back. By the time we raised Series B, our build times had climbed to forty-seven minutes, we had seventeen different JavaScript runtime versions in our monorepo, and nobody could remember why half the database indexes existed. We lost six weeks just cleaning up the mess we had created. That experience taught me that skipping the yearly review is the most expensive decision a team can make. Code quality and standards. This means reviewing your linter rules, formatting standards, and static analysis thresholds. Are they still appropriate? Have they been weakened over time to accommodate rushed deadlines? Check your configuration files. If you find overrides or disabled rules from last year that were never re-evaluated, that is a red flag. Dependency audit. Run a full dependency scan. Check for packages with known vulnerabilities, abandoned projects, or severe version drift. I once found a project running a logging library from 2018 that had zero maintenance and conflicted with our production observability pipeline. Upgrading it caused a two-hour outage because nobody had documented which error messages it produced. The workaround was to wrap the old library in an adapter before upgrading, which took a day but prevented the outage. Document every dependency change you make during this process.
Architecture health. Look at your directory structure, module boundaries, and coupling. Are services still separated appropriately? Is there accidental coupling hiding in shared utilities? Track whether new features are getting routed through appropriate abstraction layers or if they are being pasted directly into consumer code. Testing coverage and strategy. Coverage percentage alone is useless. What matters is whether your test strategy still matches your risk profile. Are critical paths still tested? Have integration tests become too brittle and are being quietly skipped? Check your CI pipeline for skipped or conditional test runs. If you see tests being conditionally skipped due to flakiness, that is a problem you need to document and fix, not hide. Performance and infrastructure. Review your deployment pipelines, infrastructure-as-code, and runtime costs. Are you still using the same cloud instances you provisioned two years ago? Have build artifacts accumulated and not been cleaned? I worked on a project where our CI storage costs had quietly grown to fourteen thousand dollars per month because old Docker images and test artifacts were never pruned. Setting up an automated cleanup policy reduced that to under five hundred dollars monthly.
Team knowledge and documentation. This is the area most people ignore. Check your README files, architecture decision records, onboarding guides, and API documentation. Are they current? If a new developer joined today, how long would it take them to ship their first pull request? I have seen this number range from three days to three weeks depending on documentation quality. The gap exists entirely because of unchecked assumptions about what should be documented.
Get the Full Details
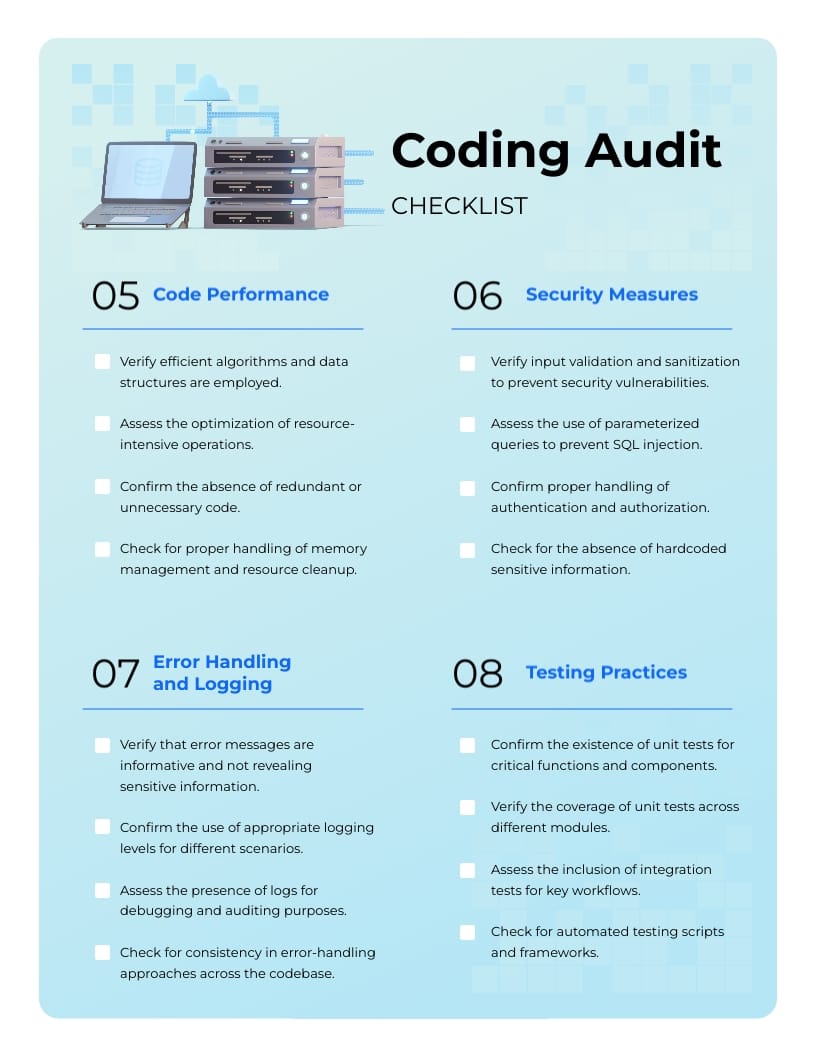
How to Execute the Yearly Review Without Wasting Time
The biggest mistake teams make is treating this as a single event. It should be distributed across a two-week sprint with clear ownership for each section. Assign one person per area. Set a hard deadline. Report findings in a shared document that becomes part of your next quarterly planning session.Start with the dependency audit. It is the fastest area to assess and often reveals the most immediate risks. Use automated tools like `npm audit`, `dependabot`, or `safety` for Python. But do not stop at the tool output. Manually review the top twenty packages by usage frequency. Automated scanners miss context-specific risks. Move to code quality next. Run your linter and static analyzer in strict mode. Do not accept warnings. If the noise is too high, disable specific rules temporarily but log them for review. A strict run typically takes between four and eight hours depending on your codebase size. Budget accordingly. The architecture review requires the most senior involvement. Pull three people who have worked on the system for at least a year. Walk through the module map together. Ask each person to identify one area they would redesign if starting fresh. These patterns reveal the actual structural problems that documentation never shows.
For testing, run your full suite in a clean environment. Note any skipped tests, any tests that take longer than ten seconds, and any that share state in dangerous ways. Then sample twenty random test files and read them line by line. You will spot gaps that summary reports never capture.
Common Pitfalls That Derail the Process
Teams treat the checklist as a checkbox exercise. They fill out the template and file it. Nothing changes. The review only has value if the findings feed directly into your next sprint's backlog. Assign story points to every actionable item. Without that, you are just writing a report nobody reads.Another failure mode is reviewing too much at once. If you try to audit every microservice in a large platform, you will burn out your team and produce nothing useful. Pick your most critical service first. Do a deep review there, then spread the process to other services in subsequent quarters. A focused review of one service in two weeks produces more actionable results than a surface-level scan of fifteen. The third pitfall is ignoring cultural issues. If your team has been rushing deployments without code review for six months, no checklist will fix that. The problem is management pressure, not process. Document this honestly. Flag it in your report. A checklist cannot compensate for a broken timeline.
What the Checklist Catches That Daily Work Misses
Daily development focuses on shipping features. The yearly review forces you to look at the accumulated cost of those shipping decisions. Technical debt compounds silently. A slightly inefficient query here, a duplicated utility function there, a middleware layer added without understanding its full impact. None of these are urgent individually. Together they create systemic fragility.My most useful finding came from discovering that three separate teams in our organization had independently written nearly identical authentication middleware. Each version had subtle differences. Each had a different security review history. Consolidating them into a single shared library reduced our security audit surface by roughly forty percent and cut future auth-related bugs significantly. That kind of pattern only becomes visible when you step back and look at the whole system. The yearly review also surfaces tooling decisions made under pressure. You will find configurations that exist because someone was tired and copied a stack overflow answer three years ago. You will find environment variables with default values that should have been removed. You will find dead code that is still being imported. This is not exciting work. It is necessary work.
Practical Output You Should Have After Completing It
By the end of the review cycle, you should have a living document with categorized findings, priority rankings, assigned owners, and estimated effort. Every item should answer three questions: what is wrong, what is the impact, and what is the fix. Vague findings like "code quality is declining" are not useful. Specific findings like "the payment service has six unresolved TODOs related to idempotency checks, estimated two days to remediate" are.Track your findings across years. A good team will show improvement in the same categories year after year. If the same issues reappear, you have a process problem, not a knowledge problem. Repeat failures mean the fix was never actually applied or was applied incorrectly. Investigate why before moving forward. I recommend storing the final document in your team's knowledge base with a fixed naming convention. Something like yearly-code-review-2025.md makes it trivial to locate and compare against previous years. Use this comparison during planning meetings to justify time allocated for technical debt reduction. There is no perfect version of this checklist. Your industry, team size, and tech stack will change what matters most. A mobile team will weight testing and build pipeline reviews differently than a data engineering team. Adapt the framework to your context rather than forcing your context into a generic template. The structure provides direction. Your experience determines the priorities.


