What Actually Goes Into a Data Science Checklist
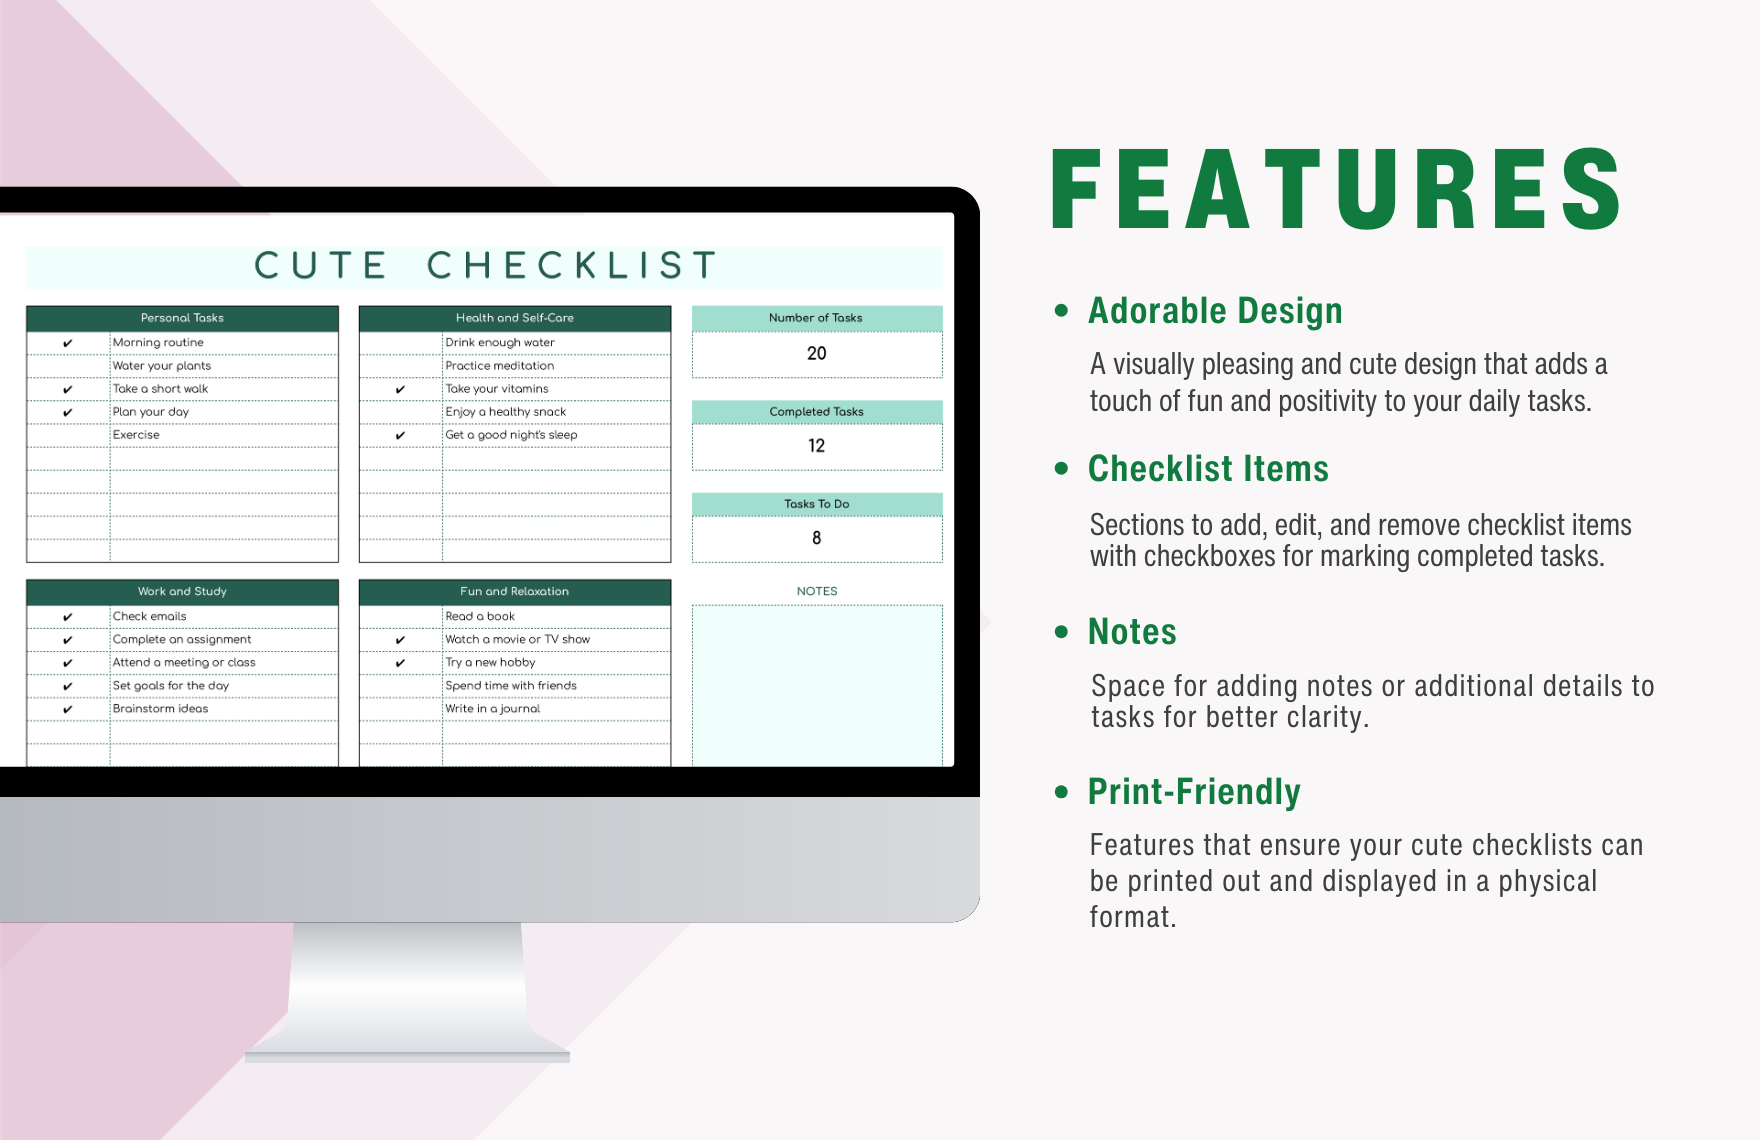
You pick up a tool called the Checklist For Data Science Cute and the name makes it sound like something aimed at beginners or people who want a friendly tone, but the content inside is usually pretty dense. It covers the standard pipeline stages. Data ingestion, cleaning, feature engineering, model selection, validation, deployment. The cute branding just means the layout is less intimidating than a formal SOP document. That's basically all it is, nothing magical. I've seen a handful of these floating around GitHub repos and personal blogs over the years. Most of them follow the same structure: data collection steps, validation gates, preprocessing routines, and a deployment section that's often just two bullet points because nobody writes deployment checklists seriously until it bites them. The ones worth your time are the ones where the preprocessing section actually calls out specific failure modes instead of just saying "handle missing values." Here's what a functional version looks like when you strip away the nice formatting:
Data audit. Check for duplicate rows, verify schema matches what the source says it should match, timestamp ordering. Not every dataset needs a timestamp check but if you're doing time series work and skip it, your train/test split will leak. I learned that the hard way on a regression project where the training set had future data from a batch job that ran late. Model performance looked great. Real-world performance was useless. Missing value handling. Count NaNs per column, decide imputation strategy or drop threshold, document the decision. The decision part is what most checklists skip. You need a reason for why you imputed with median instead of dropping, not just that you did it. Feature engineering. Type conversions, encoding method choice, scaling normalization decision, interaction terms. If you're using tree-based models, scaling doesn't matter and adding it to your checklist just creates noise. Linear models and neural nets are different story. Include the scaling step there.
Model validation. Cross-validation strategy, metric selection, baseline comparison. Most people pick random k-fold without thinking about whether the data has group structure. If your samples are clustered by customer ID or device ID, you need grouped cross-validation or your metrics are inflated. I've seen this repeatedly and it's almost always an oversight in the checklist phase because nobody thought to add a "check for leakage vectors" line. Documentation. Version everything. Data version, feature set version, model artifacts, seed values. The seed values part is separate from the model version because changing the training data doesn't change the model file but it does change the results if you reload with a different seed. One thing these checklists rarely cover well is the monitoring piece after deployment. Drift detection thresholds, retraining triggers, fallback behavior. If you're shipping a model into production and the checklist ends at model evaluation, you're setting yourself up for a weekend page call.
Get the Full Details

Common Mistakes People Make With These Checklists
Treating it as a one-time pass. It isn't. You revisit the data audit section when the source changes. You revisit the validation section when the business metric changes. A checklist is a living document, not a form you fill out once and archive. Skip the edge cases because they feel rare. Last year I was working with a dataset where the target variable had a 0.3% class balance. Standard stratified k-fold kept producing folds with zero positive samples in the minority class. The fix was switching to stratified group k-fold with the group being the temporal day bucket. The original checklist had no mention of this scenario because class imbalance at that level isn't something most templates account for. Confusing completeness with quality. A checklist with fifty items that are all "yes" because you rubber-stamped them is worse than a checklist with eight items you actually thought about. The useful checklists are the short ones where each item forced a decision.
If you want a concrete resource, search GitHub for "data science checklist" and sort by stars. The Cute-named versions tend to have nicer Markdown formatting but the content density is usually lower than the bare-bones repos. Neither type replaces actually thinking through your pipeline, but both are better than nothing if you're starting from scratch.