The Things Nobody Mentions Until Your Model Breaks in Production
Most data science projects don't fail because the algorithm is wrong. They fail because someone skipped the obvious operational stuff. I spent three days last month debugging a model that was producing garbage predictions. The code was fine. The training loss was fine. The problem was that a downstream team quietly changed the format of a date field from YYYY-MM-DD to epoch timestamps, and no one had a check for that in the pipeline. That is exactly why you need a Checklist For Data Science Modern. Not a theoretical one from a blog post, but a living document that covers the gaps between "it works on my laptop" and "it works in production." Below is the one I actually use. It is incomplete by design. You will add to it as your organization grows and your failures accumulate.
Data Layer Checks
Start with the source. Every pipeline needs a data contract that is enforced, not hoped for. A data contract is a set of conditions—schema, null rates, value ranges—that must hold before data enters your feature store or training job. If it breaks, the pipeline halts with a clear error, not a silent degradation. I built a checkout prediction model once where the upstream team added a new optional column mid-quarter. It wasn't in the schema. The model didn't crash because the ingestion script just ignored it. But when we tried to explain feature importance, SHAP was pulling numbers from that invisible column and nobody knew why. We spent a week chasing ghosts. After that, every pipeline I touched required schema validation at ingestion using Great Expectations or a similar library, with the pipeline refusing to proceed if the contract failed. Your data layer checklist should include:
- Source contracts documented and versioned
- Schema validation on every read and write
- Null and outlier rate alerts per feature, not just per dataset
- Data lineage tracking from source to model input
- Backfill tests that verify old data still produces the same features
For lineage, use DVC or OpenLineage. The overhead is real but small—maybe 15 minutes per pipeline setup—and it saves hours when you need to answer "which model version used which snapshot of the data?" During an audit, that question is never polite. It demands an answer immediately. If you cannot recreate a model from a git SHA, a data version, and a config file in under 30 minutes on clean infrastructure, you do not have reproducibility. You have luck. MLflow or Weights & Biases works for this. The tool is secondary to the discipline of logging everything: hyperparameters, data version hash, random seeds, environment specs. Here is a nuance beginners miss. People track the right hyperparameters and forget the data augmentation seed. Or they log the model architecture but not the exact library versions. A single version bump in NumPy or scikit-learn can shift metrics by a fraction that looks insignificant until you are comparing results across teams six months apart. Pin your dependencies. Log them. Version your environment with Docker or Conda lock files.
Get the Full Details
Model Development and Validation
Your validation strategy is where most checklists stop being useful. Accuracy is a terrible metric for anything beyond balanced classification. If your fraud detection dataset has a 0.3% positive rate, an accuracy of 99.7% means your model predicts "no fraud" for every single row. Use PR-AUC, not ROC-AUC, for imbalanced problems. Report both precision and recall at your operational threshold. I worked on a churn model where the business insisted on 95% recall. The team hit it by pushing the threshold so low that precision dropped to 12%. We were calling 8 out of every 100 "churners" who were actually staying. The marketing team wasted a quarter's budget on retention campaigns that annoyed customers who would not have left anyway. The model was technically meeting its metric. The business outcome was terrible. After that, we required a cost matrix or business impact estimate attached to every validation report, not just statistical metrics. Your model checklist:
- Holdout set created before any modeling begins, not after
- Metric selection justified by business cost, not convenience
- Cross-validation with time-based splits for sequential data
- Feature drift detection against the training distribution
- Model cards documenting intended use and known failure modes
- Baseline comparison against a simple heuristic (always predict the majority class, always predict last week's value)
Production Readiness
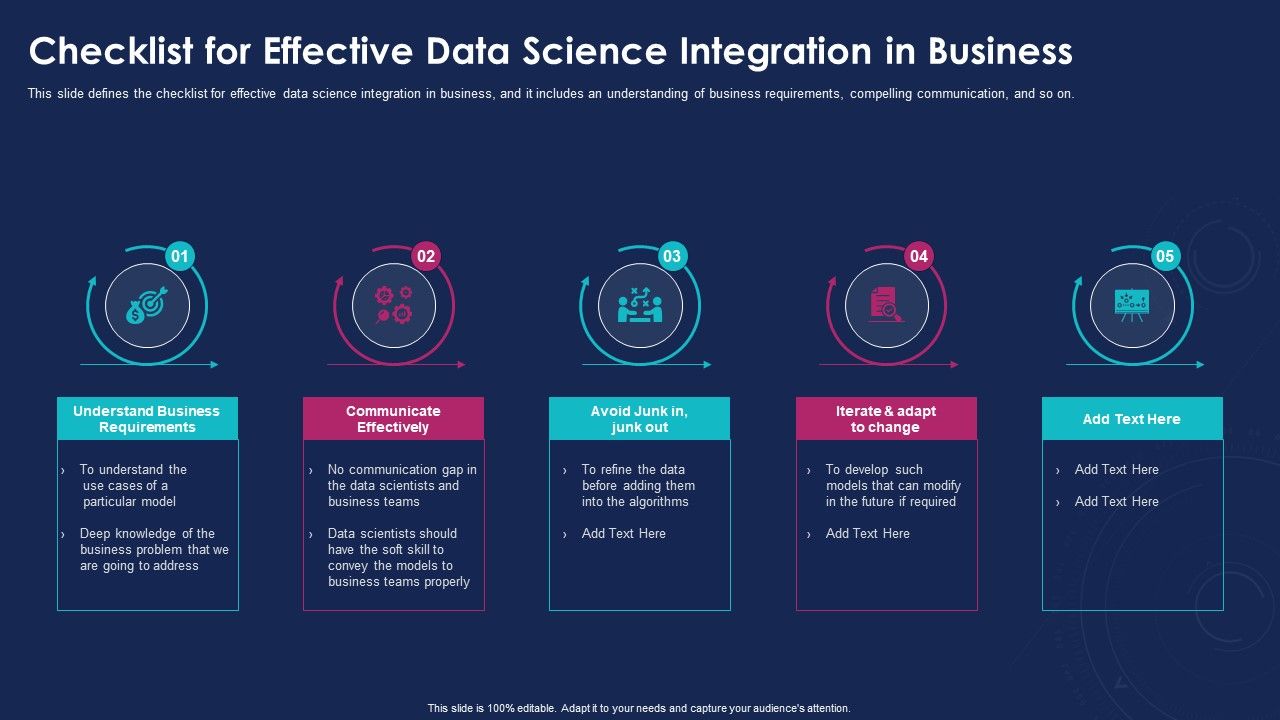
A model in production is not a file. It is a service with monitoring, logging, alerting, and a rollback plan. You need a Checklist For Data Science Modern that extends past training into deployment. The most common failure mode I see is inference drift. Your model was trained on features computed at batch time. In production, you serve predictions in real time using a different computation path. The numbers do not match. This is called train-serving skew and it kills more models than bad algorithms. Fix it by using a feature store like Feast or Tecton that guarantees the same computation in training and inference. If you cannot afford a feature store, write the exact same preprocessing code path and test it with synthetic data before going live. Your production checklist:
- Inference latency within SLO (typically under 200ms for online, under 5 minutes for batch)
- Logging of every prediction with input features and model version
- Monitoring for input drift using PSI or KL divergence, checked daily
- Monitoring for prediction drift, not just feature drift
- Error rate alerts on the serving endpoint
- Rollback procedure tested, not just documented
- GPU or CPU resource utilization tracked against capacity
- Data retention policy for prediction logs (GDPR, CCPA compliance)
One specific thing I learned the hard way: logging prediction inputs is not optional. When a stakeholder asks "why did the model reject this application?" and you have no logged inputs, you cannot answer. You either rebuild from scattered backups or you admit you don't know. Log everything. Compress it. Store it. It costs pennies per day and buys you credibility. Models decay. Not always slowly. Sometimes a single upstream change breaks a model overnight. A supplier switched their API response format. A regulatory update changed what variables you are allowed to use. A third-party data provider deprecated an endpoint. Your checklist needs to include a periodic review cadence, even if nothing is broken. Set a quarterly review for every production model. Check: Is the performance within the original acceptance band? Are there new features that should have been included? Has the business requirement shifted? Is the model still the best option or has a simpler approach become viable? I have seen models that were originally sophisticated gradient boosting setups replaced by logistic regression after the business logic simplified and the data quality improved enough that the extra complexity was noise.

This is also where you handle model retirement. Not every model deserves a forever home. Define a sunset process: archive the artifacts, update the model registry to deprecated, redirect traffic, decommission the serving infrastructure, and document the reason. An orphaned model running in production is technical debt with a latency cost.
What This Checklist Does Not Cover
It does not cover the choice of algorithm. That is a domain decision, not a process decision. It does not cover team structure, though having a dedicated ML engineer or MLOps person on the team matters more than any checklist. It does not cover selecting tools—I mentioned specific ones because I use them, but the principle matters, not the product. What it also does not guarantee is that you will catch every failure. The date field bug I described slipped through two layers of validation. No checklist is bulletproof. The value is in making the obvious failures obvious and the subtle failures detectable earlier than they would be otherwise. Keep this document somewhere your team actually reads it. Not a shared drive buried under seven folders. A pinned resource, referenced in code reviews, updated whenever someone hits a problem that should have been caught. The checklist is a living thing. If you stop updating it, it becomes exactly what most people think a Checklist For Data Science Modern is: another piece of documentation nobody follows.