What Checklist For Data Science Weekly Actually Covers
It's a curated publication that runs weekly, breaking down new papers, tools, and methodology shifts in the data science space. Most weeks you'll see three to five pieces: a paper summary, a tool tutorial, and a practical how-to. The editors tend to focus on what's actually usable rather than hype cycles, which keeps it from drifting into the usual noise. I've been reading it for a while now, and the reason is simple—it filters out enough of the junk that it saves me time instead of costing it. The "checklist" part of the name comes from the way they structure their workflow advice. They don't just say "use this model" or "try this framework." They give you an actual step-by-step validation sequence to run before you ship anything. That's the thing most people miss when they skim it quickly. Here's how the weekly cycle normally works in practice. You get an email on Tuesday mornings with the round-up. Most issues are between 800 and 1500 words of actual content. They use structured sections: feature pick, paper of the week, tool review, and community spotlight. The feature pick is usually the heaviest piece—a deep dive into one method or technique with code snippets and benchmark results. The paper of the week tends to cover arXiv work that hasn't hit mainstream tools yet, which is useful if you're trying to stay ahead of your team.
I should mention the one recurring issue that bugs me. Their paper summaries are solid, but they occasionally gloss over the limitations section of a paper. I caught this twice this year with a couple of NLP papers where the stated benchmark results fell apart under distribution shift, and the summary didn't flag that at all. The workaround was to just pull the original paper and skip straight to the ablation study or the appendix. Takes about ten minutes and saves you from implementing something that won't hold up. For people who want to actually use what they publish, here's the practical approach I'd suggest. Don't just read the feature pick passively. Open your own notebook, replicate the core experiment they describe, and vary one parameter. If you're using Python, a minimal setup with pip install of their listed dependencies usually takes under five minutes on a standard laptop. Then run their baseline code, note the result, and test an edge case—missing values, small sample size, or imbalanced classes depending on the topic. This tells you faster whether the method is robust enough for your actual data than any summary ever will. There's also a counter-intuitive thing about their tool reviews that most beginners ignore. They tend to favor tools with active GitHub repos and frequent commits over tools with flashier APIs but slower update cycles. I learned this the hard way last year when a tool they reviewed positively became unmaintained three months later, and following their dependency list led me to a dead end during a production deployment. Now I always cross-reference the repo's last commit date before adopting anything from their recommendations.
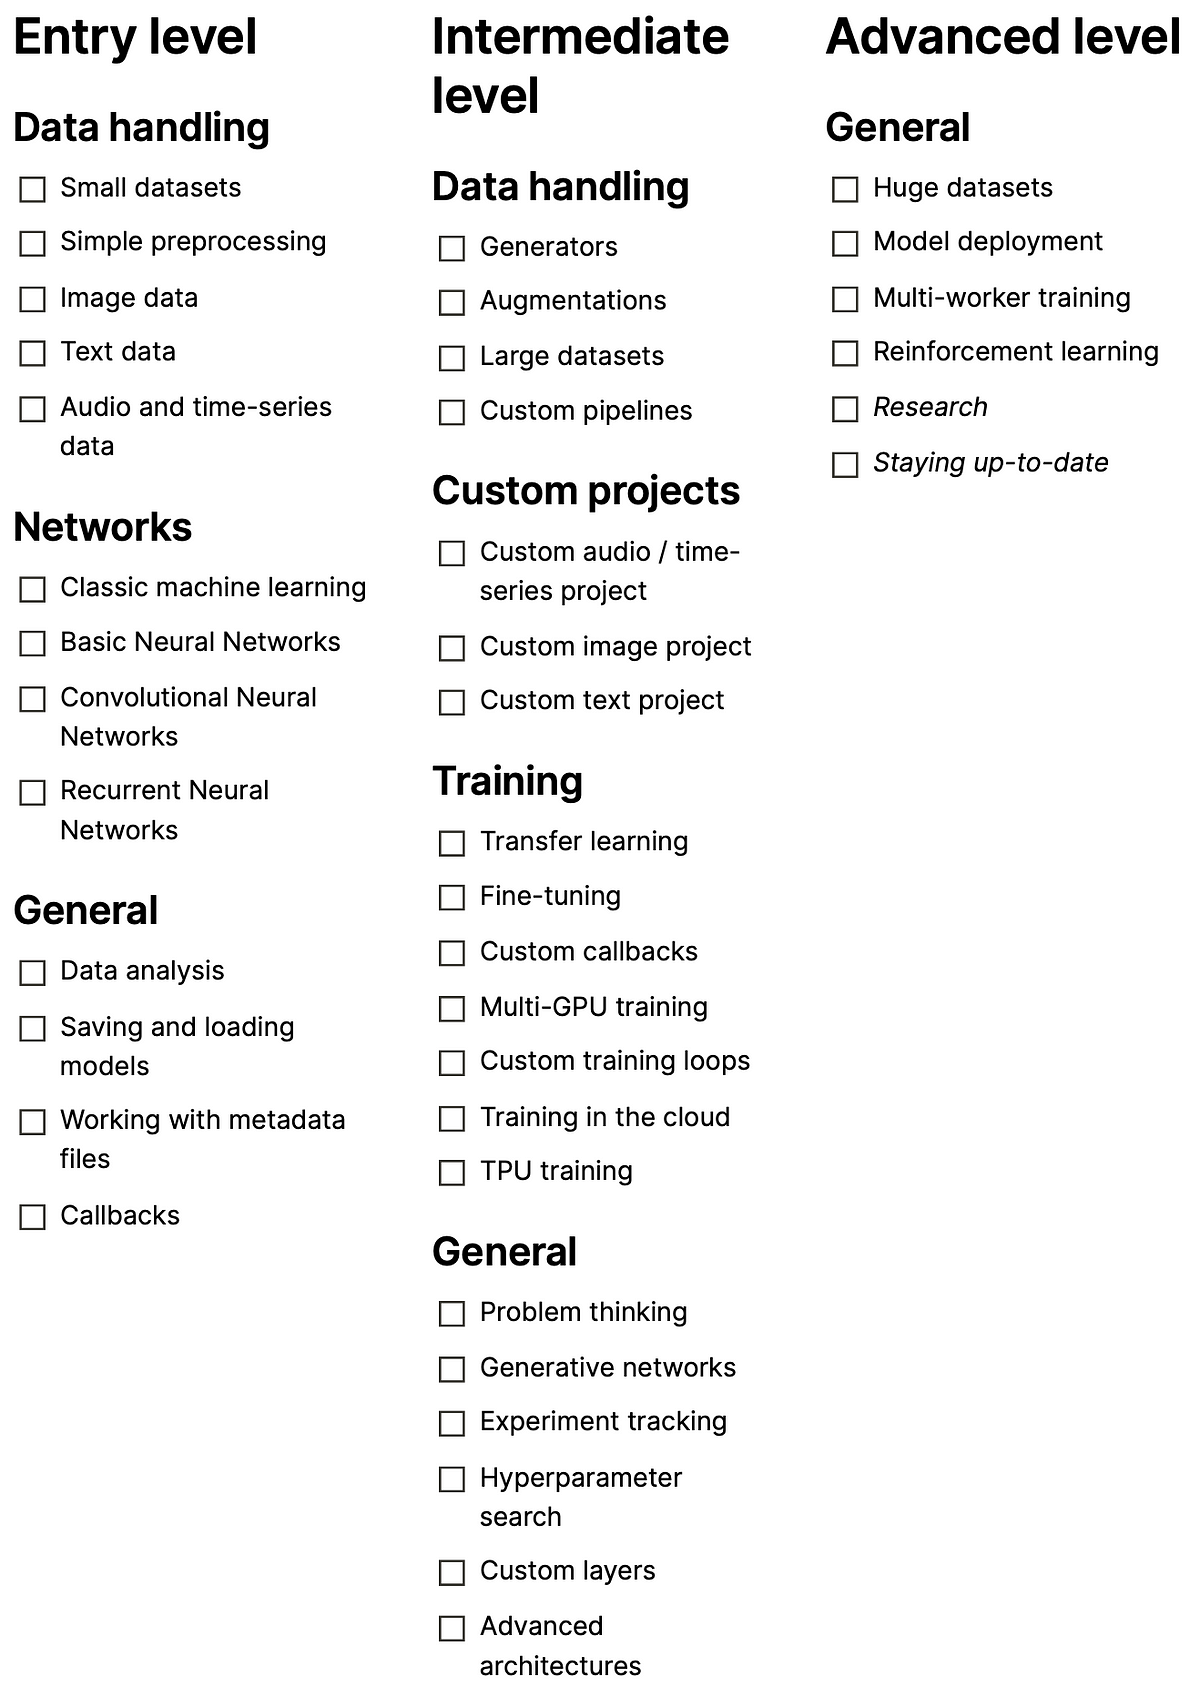
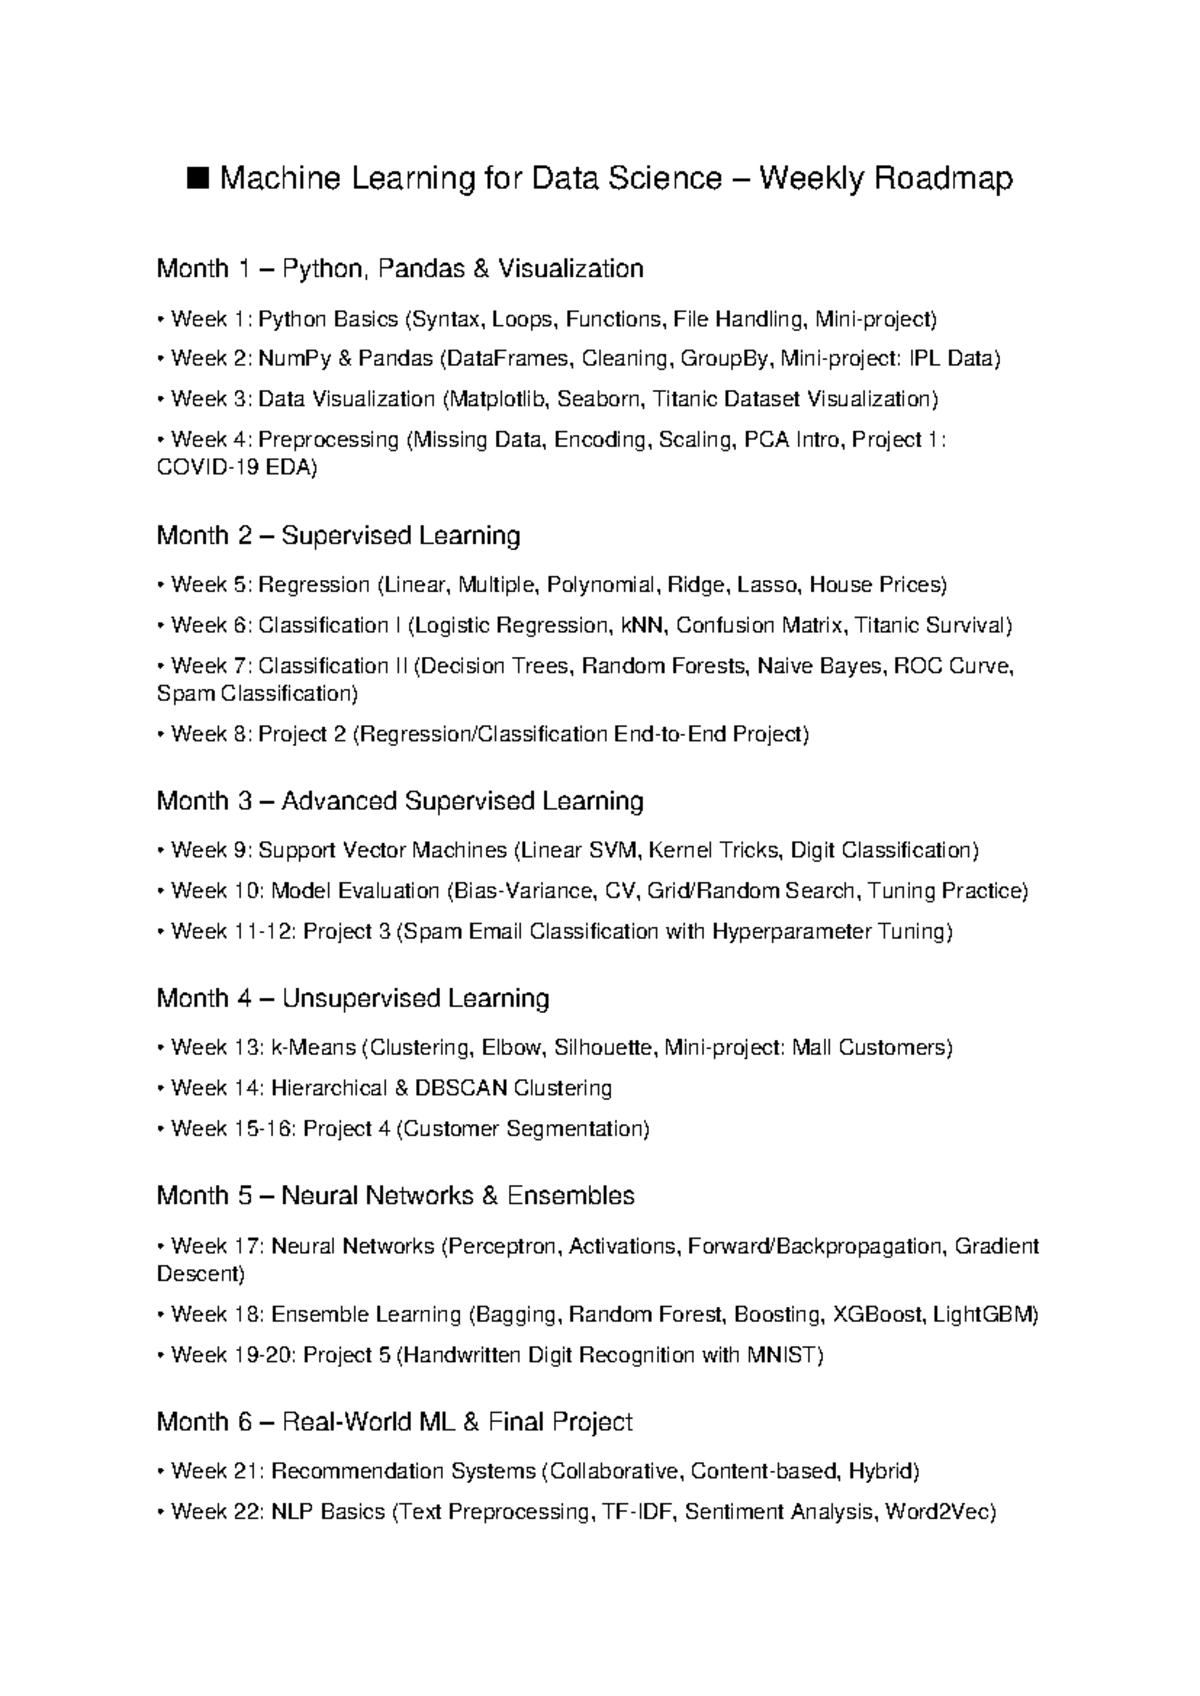
Another thing worth noting: their content assumes a baseline of programming literacy. If you've never written a loop or touched pandas, the weekly issues will move too fast. I'd recommend spending a month on the basics first—data cleaning, basic visualizations, and simple model training—before diving into the advanced sections. It's not gatekeeping, it's just that the editorial team writes for people who are already in the workflow, not people trying to figure out what Jupyter is. If you want the download or subscription link, it's hosted at checkfordatascienceweekly.com. The free tier covers the weekly digest and the paper summaries. The paid tier adds the code repositories, extended benchmarks, and the monthly template library, which is useful if you need quick scaffold code for common tasks like A/B test analysis or time series forecasting pipelines. The template library alone is worth the subscription if you're doing this full-time. I've pulled from there at least once a month for standard report structures and model evaluation scripts. Writing those from scratch each time eats into actual analysis time, and having a tested starting point cuts that preparation down significantly.
Get the Full Details

When It Doesn't Work
Let me be clear about the limitations. The publication doesn't cover MLOps infrastructure deeply—Kubernetes deployments, model monitoring setups, or data pipeline orchestration. If that's what you need, you'll still have to look elsewhere. They also skew toward Python-heavy content, which isn't a dealbreaker but means R users or Scala-focused data engineers might find themselves skipping half the issues. The benchmark results in their tool reviews are also run on controlled hardware. I found this out when I tried to match their performance numbers on older enterprise GPUs and got roughly half the throughput they reported. Not their fault, just something to keep in mind when planning capacity. If you're looking for a beginner-friendly introduction to machine learning, there are better resources. Their material assumes you already know what cross-validation is and why train-test splits matter. For people earlier in their journey, starting with foundational courses before picking up the weekly digest will make the whole experience less frustrating and more immediately useful.