Most people treat ML project management like a guessing game until it fails
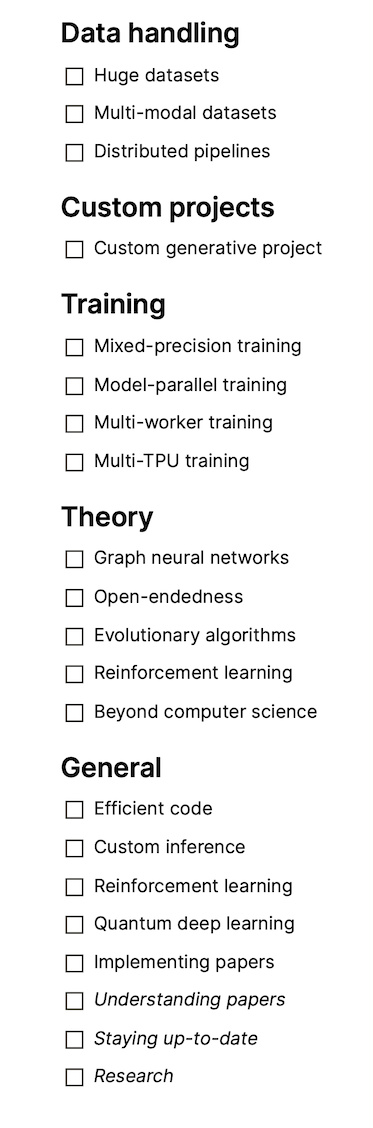
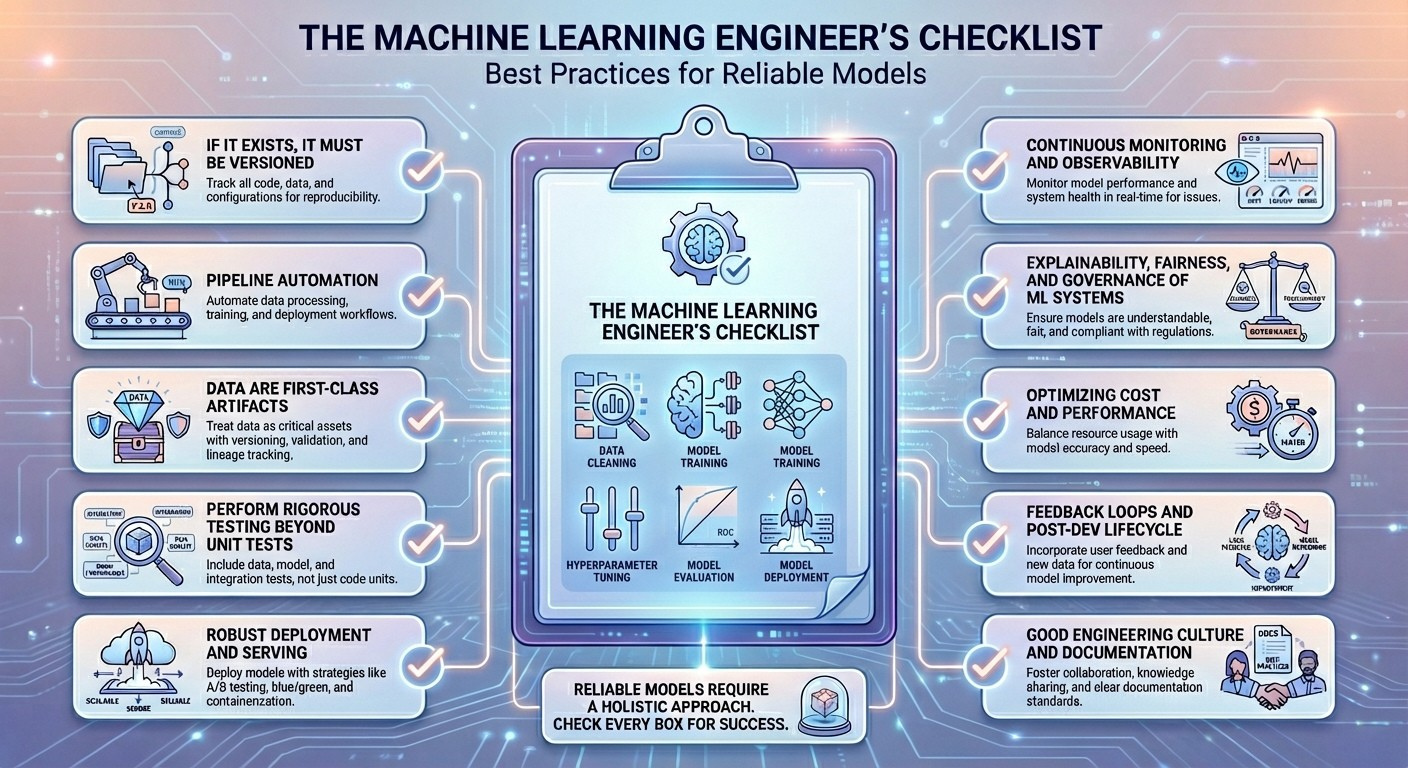
I used to skip documentation entirely, figuring I'd remember what mattered. That lasted until a model trained for three days on a GPU cluster only to fail at inference because the preprocessing pipeline didn't match what the training script expected. The feature scaling was inverted between notebook and serving. I spent a full week tracking down a discrepancy that any halfway decent checklist would have caught in ten minutes. That's why I ended up building and refining a Checklist For Machine Learning Ultimate over the course of several years. It started as a personal reference and slowly became something I force my entire team to use on every project, regardless of size. The checklist itself is a living document, not a static set of instructions. It covers everything from data collection protocols to model deployment validation, but the real value comes from the specific workflow it enforces.
Why a Checklist For Machine Learning Ultimate Actually Matters
Machine learning projects have a different failure profile than traditional software development. A web app either works or it doesn't. An ML model can be technically correct but produce garbage outputs because the training data distribution shifted, because you accidentally introduced data leakage in preprocessing, or because the evaluation metric doesn't actually correlate with what the business cares about. These failures are subtle and expensive to detect after the fact. The checklist forces you to address each failure mode explicitly before you move to the next phase. It's not about bureaucracy. It's about making the implicit errors visible. When I review a project at the data preparation stage, I look at the checklist first. I check whether the team has documented the exact schema, the data provenance, and whether they've run a statistical sanity check against the raw output. Three hours of work on paper saves three days of debugging later.
How the Checklist Works in Practice
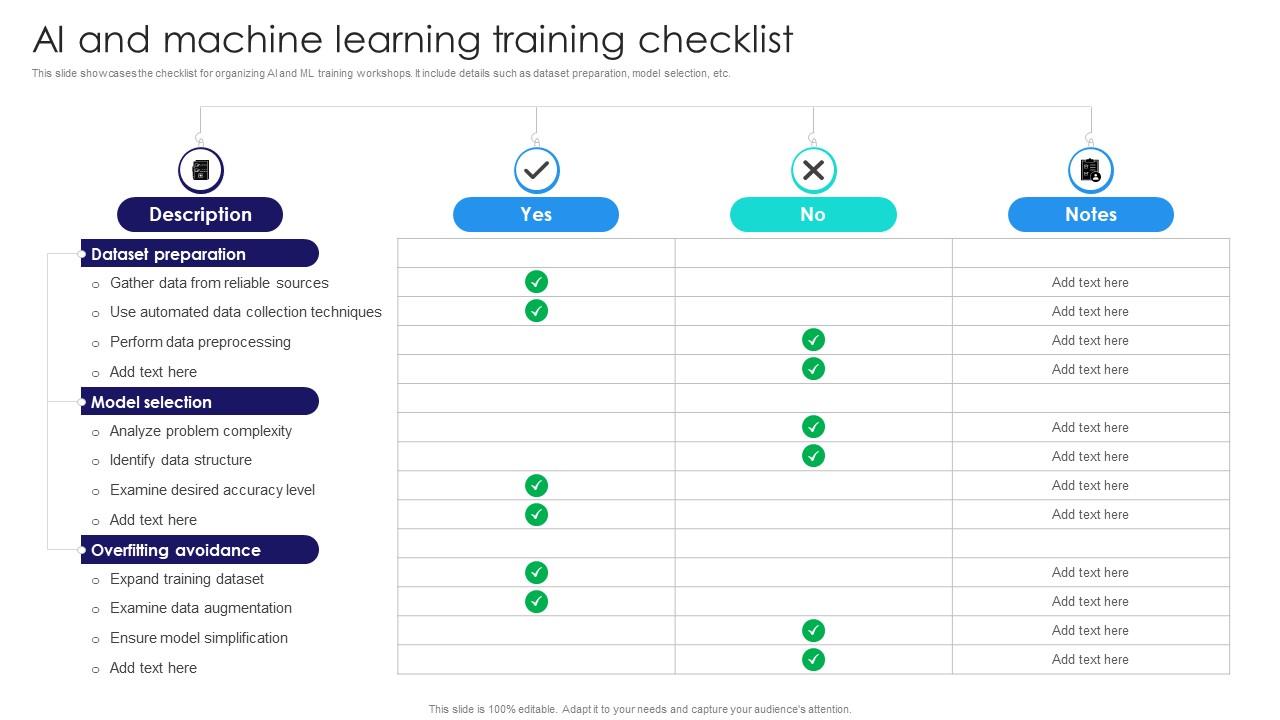
The workflow follows a sequential but iterative structure. You don't complete every section before moving forward, but you cannot skip sections and return to them later without a documented justification. Here is how each major phase breaks down. This is where most projects quietly start failing. You need source URLs, extraction scripts, timestamps, and a record of every transformation applied between raw ingestion and the versioned dataset. I had a project once where the training data came from an API that changed its response format without notice. The model looked great in validation because we'd cached a snapshot, but production predictions degraded immediately. The checklist requires you to verify the data source stability and document versioning for every input feed. If you can't timestamp exactly when each row was created and what it looked like at ingestion, the checklist stops you there. You also need to document missing value patterns, not just count them. Random missingness is fine. Missingness that correlates with your target variable is a leakage risk. I caught this in a churn prediction project where customer support ticket data was missing for loyal customers but present for those about to leave. The model learned to predict churn from the presence of support tickets rather than actual churn signals. The checklist has a dedicated step for analyzing missing value correlation with the target.
Get the Full Details

Exploratory Data Analysis and Validation
Standard EDA involves visualizing distributions and correlations. The checklist demands more. You need to split your exploratory analysis by segment. If your data comes from multiple geographic regions or user cohorts, analyze each segment separately. Aggregated statistics often hide distribution mismatches that destroy model performance. Run adversarial validation at this stage. Train a binary classifier to distinguish between your training set and your holdout or production data. If the classifier achieves AUROC above 0.7, your train and test distributions are too different and your model will not generalize. This took me maybe twenty minutes to set up but prevented a catastrophic launch failure on a recommendation system project. The dataset I was working with had a seasonal bias that wasn't apparent in aggregate statistics.
Feature Engineering and Selection
Every feature needs a documented purpose, a source, and a transformation formula. I enforce this because I've seen too many models where someone creates a derivative feature, forgets what it represents, and then the feature name becomes meaningless by the end of the project. You need version control on your feature engineering pipeline separate from your model training code. They serve different revision cycles. The checklist includes a time-based leakage check. When you create features, ensure none of them contain information that would not be available at prediction time. This is almost always an issue with aggregated features. If you're computing customer lifetime value as a feature and your training data includes transactions after the prediction point, you've introduced look-ahead bias. The fix is straightforward: compute the feature using only data available before the prediction timestamp. But you have to check for it explicitly.
Model Training and Validation
The checklist requires you to define your validation strategy before you write any training code. K-fold cross-validation on its own is insufficient for most real-world scenarios. You need time-based splits if your data is temporal. You need group-based splits if your observations are correlated within groups, such as multiple transactions from the same user. I've lost count of the number of models that showed excellent cross-validation scores and failed immediately in production because the split strategy didn't account for data dependency structure. There is a counter-intuitive point about hyperparameter tuning that most people miss. Grid search over a large space with a fixed validation set often produces overfitted hyperparameters. Instead, use nested cross-validation or repeated k-fold with different random seeds for each repetition. The difference in results can be significant, and the additional compute cost is usually negligible compared to the cost of deploying an overfitted model.
Evaluation and Business Alignment
Your evaluation metric must align with the business objective, and the checklist forces you to state that alignment explicitly. If you're optimizing for accuracy on an imbalanced dataset where the positive class is 2 percent of the data, accuracy is a meaningless metric. Use precision-recall AUC or F-beta score weighted toward the cost-sensitive outcome. But more importantly, translate the metric into business terms. What does a one-point increase in AUC actually mean for revenue or cost savings? I worked on a fraud detection project where the business stakeholder insisted on 99 percent recall. The model achieved it but generated so many false positives that the investigation team could not handle the volume. We recalibrated the operating point to 95 percent recall with higher precision and the overall business outcome improved because investigators could act on the alerts. The checklist includes a validation step where you simulate the operational impact of different decision thresholds rather than optimizing purely for metric values.
Model Deployment and Monitoring
Deployment checklists often get skipped because the model works on the validation set. But production environments introduce variability that training pipelines do not account for. Your inference infrastructure needs to handle missing inputs gracefully, reject requests from out-of-distribution sources, and log predictions for downstream monitoring. I had a model serving in production that started degrading because the input data had a slow distribution shift. The model had no monitoring because we never defined the monitoring metrics during the checklist phase. The checklist requires you to define drift detection thresholds, alerting mechanisms, and rollback procedures before deployment. Not after. When I deployed a model for a financial services client, we set up daily feature distribution checks and automatic alerts when any feature drifted beyond three standard deviations from the training baseline. The alert fired on day four. The feature drift was caused by a change in how the upstream data provider formatted a date field. We rolled back to the previous model version and fixed the preprocessing within two hours instead of discovering the issue weeks later through customer complaints.
Common Pitfalls Even Experienced Practitioners Miss
The first pitfall is checklist complacency. Having a checklist does not mean checking every item. I've seen teams mark everything as complete without actually performing the verification. The workaround is to require evidence for each item, not just a checkbox. Screenshots, output logs, or metric values should accompany the completion of critical steps. The second pitfall is treating the checklist as one-size-fits-all. A recommendation system project has different risk vectors than a medical diagnosis model. The Checklist For Machine Learning Ultimate should be adapted per project type. The core structure remains the same, but certain items carry more weight depending on the domain. In healthcare, data lineage and auditability matter more than in a marketing experiment. In high-frequency trading, latency and infrastructure stability dominate the risk profile. The third pitfall is not updating the checklist. Every project teaches you something new about where failures occur. I add items to the checklist after every project retrospective. Recent additions include checks for GPU driver version consistency across training and inference environments, and a requirement to validate that feature stores return the same values in batch and online serving modes.

Where the Checklist Fails
A checklist cannot compensate for fundamentally poor data quality. If your source data is corrupt or your labeling process is unreliable, the checklist will only help you document how bad the data is more efficiently. You still need to invest in data quality upfront. The checklist also slows down rapid prototyping. If you are experimenting with a new architecture on a clean public dataset, the full checklist overhead can feel excessive. I allow my team to use a trimmed version for exploration and reserve the complete checklist for anything approaching production. But the trimmed version still contains the critical items: data validation, time-based leakage checks, and explicit evaluation metric selection. Finally, checklists do not replace domain expertise. Understanding why a feature matters or whether a model's prediction makes sense in context requires knowledge that no procedural document can encode. The checklist catches procedural errors. It does not catch conceptual ones.