The Practical Guide To ML Model Vintage Tracking
Machine learning models degrade. Not because your code is wrong, but because the world changes around it. Data drifts, distributions shift, and your model quietly becomes less useful while nobody notices. That is why keeping a reliable checklist for machine learning vintage management matters more than most teams realize. Most data science teams train a model, ship it, and move on. The model runs in production until something obvious breaks. By then, you have lost weeks or months of degraded performance. A vintage tracking checklist is simply a structured set of checkpoints that force you to record, compare, and monitor model performance across time periods — usually calendar months or quarters. Think of it as giving your models a chronological identity card. I built the first real version of this for a fraud detection system at a payments company. We were losing money on edge cases and could not prove whether the model was the problem or the data was the problem. The vintage checklist gave us the proof we needed.
What You Actually Need To Track
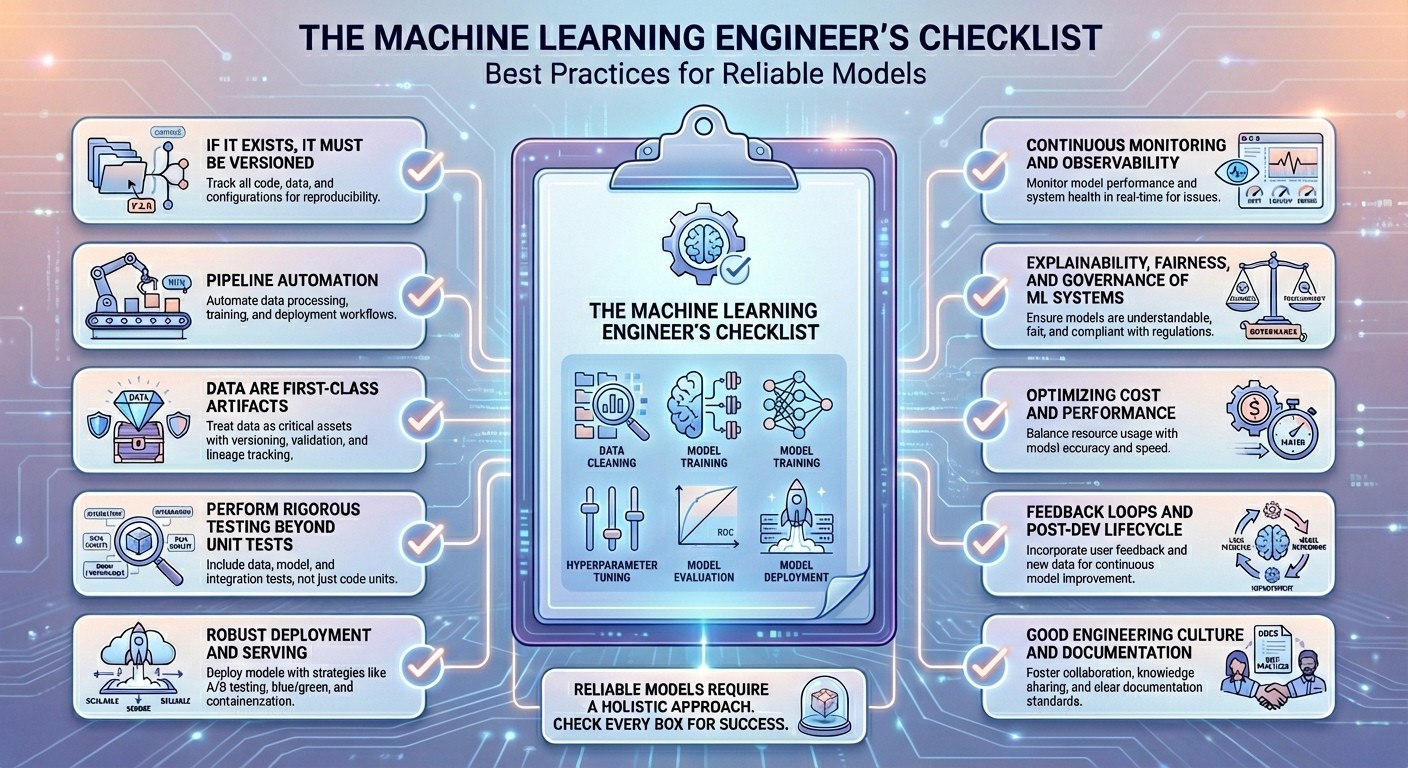
Here is the core structure I use and recommend. It is not complicated, but skipping any of these fields will blind you later. Every entry must include: model name, version tag, training data window start and end dates, features used, hyperparameters, algorithm type, and the person who approved deployment. This sounds basic. I cannot tell you how many times I have opened a production incident report and found zero traceability because someone deployed a model without recording the feature list. Record these metrics for each vintage period, not just an overall aggregate:
- Precision, recall, F1 score (or your domain equivalent) broken down by month/quarter
- AUC-ROC or AUC-PR if applicable
- Calibration error if your model outputs probabilities
- Volume metrics: how many predictions per vintage period Aggregating across time is the single most common mistake. A model that looks fine overall might have been steadily declining for six months before a sudden drop. Vintage-level breakdown catches that. Overall averages hide it.
Get the Full Details
Drift Indicators
Include population stability index (PSI) or feature-level KS statistics for each vintage. These tell you whether the input distribution has shifted relative to your training baseline. If PSI exceeds 0.1 across multiple features in a row, your model is operating on different data than it was trained on. If it exceeds 0.2, something is seriously wrong and you should be preparing a retrain or rollback decision. Define ahead of time what triggers a response. Common thresholds I use: F1 drops 5 percent from the previous vintage means investigate. F1 drops 10 percent means consider retraining. Two consecutive vintages with PSI above 0.15 means automatic retrain queue. Write these down before you need them. Emergency decisions under pressure produce bad decisions. You do not need an expensive MLOps platform. Here is what actually works for most teams.
Start with a database table or a simple data frame. If you are using SQL, create a table called something like model_vintages with the fields above. If you are in Python, a pandas DataFrame with one row per model per vintage period is enough to begin. The tool does not matter. The discipline of filling it out matters. Connect this to your existing pipeline. Every time a model runs inference in production, log the prediction batch with its date range to your vintage table. Automated this part. Manual data entry gets abandoned within two weeks. I learned that the hard way. Generate a monthly report automatically. Pull the latest vintage data, compute the drift metrics, compare to thresholds, and send the results to Slack or email. If a threshold is breached, the alert should include the specific metric, the value, and a link to the raw data so someone can investigate immediately.
A Specific Problem I Ran Into
Once I had a model where the overall F1 score looked stable across eight months, but the vintage breakdown revealed a slow decline masked by a few high-performing months. The overall average was 0.84. The vintage trend showed it going from 0.89 down to 0.76 over that period. We would have missed that entirely without per-vintage recording. The workaround was to add a simple exponential moving average on top of the raw vintage scores. That smoothed out the noise but preserved the downward trend, making it obvious during our monthly review. Teams tend to overcomplicate this at the start. Here is what to avoid. Do not track every model version forever. Keep detailed vintage records for active production models. Archive older versions after six months unless there is a compliance requirement. You do not need to query a row from a model that was retired two years ago during an incident at 2 AM.

Do not treat all metrics equally. Pick two or three that matter for your specific use case. More metrics create noise, not signal. If your business cares about false negatives more than false positives, track recall and don't waste space on metrics nobody reads. Do not forget to record sample sizes. A precision score of 0.95 based on 20 predictions in a vintage period is meaningless. Always include the denominator. A precision of 0.95 based on 12,000 predictions is trustworthy. The gap between those two numbers is the difference between a good decision and a risky one.
When Vintage Tracking Is Not Enough
This checklist works well for models with steady inference volume and relatively slow-changing data environments. It breaks down in a few scenarios. If your model processes infrequent predictions — say fewer than 100 per week — the vintage periods become too small to draw reliable conclusions. You would need to extend the vintage window to longer periods or switch to a different monitoring approach. If your model is deployed in highly variable environments, such as a recommendation system exposed to seasonal campaigns, the drift signals from the campaign might overwhelm the genuine model degradation signal. In those cases, segment your vintage data by campaign or environment rather than using a single flat timeline. For real-time streaming models where data arrives continuously, batch-based vintages might not capture the right granularity. Consider switching to a rolling window approach instead, where you evaluate the last N days continuously rather than fixed calendar periods.
Getting Started Next Week
Create the table or DataFrame this week. Define your model list. Set the threshold values based on your historical performance data if you have it, or use conservative defaults from the industry. Automate the data ingestion. Generate the first report even if it is incomplete. Most teams wait until everything is perfect before starting. That is why they never start. Imperfect tracking is infinitely better than no tracking at all.