The actual workflow most teams skip
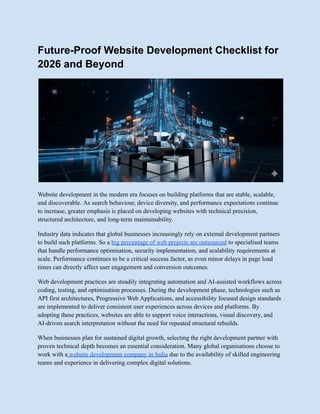
I keep seeing people ask about checklists for web development projects in 2026, and the answers are always too either/or. Either it is a 47-step document from 2019 or it is just "test everything and ship it." Neither works. A checklist is only useful if it reflects the actual failure points in your current stack. Anything else becomes noise you stop reading after week two. Here is how I approach a Checklist For Web Development 2026 that actually gets used. I organize it by phase, not by category, because people rarely fail a single item in isolation. They fail when cross-cutting concerns collide at deploy time.
Pre-build: infrastructure and scope
Before writing any component, confirm the runtime environment and its constraints. This means locking down the Node version, the package manager, and whether you are using an edge runtime, a container, or a serverless function provider. I recently worked on a project where the team assumed Vercel's edge runtime supported a Node.js-native crypto library. It does not. The build passed locally, failed in staging, and we spent three hours debugging a TypeError that traced back to an undocumented polyfill gap. The fix was swapping to the Web Crypto API and adding a runtime guard in the entry file. You catch this during the pre-build phase if you audit every dependency against the target runtime before installing. Also decide the architecture pattern upfront. Static export, SSR, SSG, ISR, hydration-only, or partial hydration. Pick one per route group. Mixing patterns in the same project without a clear boundary increases bundle size unpredictably and makes testing coverage meaningless.
Development phase: the pieces that break first
Component design needs a naming and prop contract section. Define prop types with TypeScript strict mode enabled. Disable noImplicitAny. The time saved here pays for itself in the first bug report from QA, which almost always involves a prop shape mismatch. State management requires its own checklist line. Decide whether global state lives in a store (Zustand, Jotai, Redux Toolkit), in React Server Components context, or nowhere because the data can be fetched at the route level. The common mistake is putting UI-only toggle state into the global store, then wondering why your devtools memory profile looks like a topographic map. API integration has three non-negotiable items:
Get the Full Details
- Error boundaries around every data-heavy section, not just the root.
- Typed response schemas, ideally validated at runtime with Zod or tRPC procedures.
- Caching strategy documented per endpoint: stale-while-revalidate, cache-first, or network-only. The wrong choice here causes either infinite re-fetch storms or stale content that users cannot clear without a hard refresh.
File structure should follow a feature-based layout, not a type-based one. Group by domain, not by file type. A components folder containing two hundred files tells nobody anything about where to find the billing widget. Bundle size is the first metric to set a ceiling on. I target under 150KB for the initial JS payload on mobile networks. Use bundle analysis tools like webpack-bundle-analyzer or the built-in Next.js bundle analysis to verify. Large dependencies sneak in through transitive imports. You install lodash because you need one function, and the whole library ships. Image optimization must be configured per provider. If you are using next/image or a similar component, set the proper loader, domain allowlist, and format priorities. Missing the domain allowlist causes images to fail at runtime on CDN-attached deployments, which is harder to diagnose than a broken link because the console error is vague.
Lighthouse CI should run on every merge. Set a minimum score threshold per category and fail the build if it drops. The scores change over time as browsers update, so treat them as directional, not absolute. A score of 92 today does not guarantee 92 in six months.
Testing strategy that covers the blind spots
Unit tests should cover pure logic only. Hooks, utility functions, and formatters. Do not test React rendering behavior at the unit level. Use integration tests for that. Integration tests need to cover the happy path, the error path, and the loading state path for each route. I write these with Playwright or Cypress, testing against a mocked API layer. Testing against production APIs in CI is unreliable because third-party services change responses without notice. Mock the contract, not the implementation. E2E tests should cover the critical user journeys, which are rarely more than three per product. Add more and your test suite becomes a maintenance burden that slows down releases. The sweet spot is one E2E suite per major flow.
Accessibility: the part everyone half-does
ARIA attributes are not a substitute for semantic HTML. Use the correct element first. A button that looks like a link is still a button to the browser if you mark it properly. Adding aria-label to a div that should be a button is worse than useless. It gives a false sense of completeness while the interaction model stays broken for keyboard and screen reader users. Color contrast must meet WCAG AA at minimum. Use a contrast checker during the design handoff, not after development. Fixing contrast in CSS after the component library is locked down requires overrides that conflict with dark mode theming later. Focus management matters for single-page applications. Route transitions must move focus to the new page heading or a designated landmark. Otherwise keyboard users land on invisible entry points and lose their place. I once shipped a dashboard update where the route change scrolled to the top but did not shift focus, so screen reader users encountered a header with no announcement of the new context. The fix was a single useRef and a useEffect that called focus() on the new main heading after navigation completed.
Security checklist items that get skipped
Input validation belongs on the server, not just in the client form. Client-side validation is for UX. Server-side validation is for safety. Validate every incoming request with a schema library. Reject or sanitize before it touches business logic. CORS configuration should be explicit. Wildcard origins are acceptable in development. In production, specify the exact allowed origins. A broad CORS policy combined with cookies or auth headers creates a direct path for CSRF-adjacent attacks. Dependencies need regular auditing. Run npm audit or the equivalent for your package manager on a weekly cadence. Update critical and high severity packages immediately. Low severity vulnerabilities can wait for the next scheduled update window.
Environment variables must not leak into the client bundle. Many frameworks expose any variable prefixed with NEXT_PUBLIC_ or REACT_APP_ to the browser automatically. Use this intentionally. Variables for API keys, database strings, or secrets should live exclusively on the server side.

Deployment and monitoring
Build reproducibility depends on locking dependency versions. Use a lockfile. Pin major versions in production. Do not rely on caret ranges in production builds because a minor bump can introduce breaking changes in transitive dependencies. Health checks should be defined at the application level. A simple endpoint that returns 200 when the service is ready and 503 when dependencies are down. Container orchestrators and load balancers use this to route traffic correctly. Missing this causes requests to hit an uninitialized instance. Error tracking needs to be configured before deployment, not after. Set up Sentry, Bugsnag, or an equivalent. Capture unhandled exceptions, promise rejections, and routing errors. Filter out noise by ignoring expected errors like abort signals from cancelled fetch requests.
Database migrations require a rollback plan. Every migration script must have an inverse or the system loses the ability to revert after a bad deploy. Test migrations on a staging database with production-scale data. Migrations that work on empty tables behave differently when constraints and indexes exist.
Post-launch: what to verify in the first 48 hours
Monitor Core Web Vitals from real user data, not lab metrics. Real-world performance diverges from Lighthouse scores within the first week as different device classes and network conditions interact with your bundle. Check analytics for unexpected traffic patterns. A sudden drop in conversion rate after deployment often traces back to a broken form submission handler or a missing analytics event. Review error tracking dashboards daily during the launch window. The first batch of errors usually comes from edge cases not covered by tests: unusual browser versions, slow network responses, and specific input combinations.
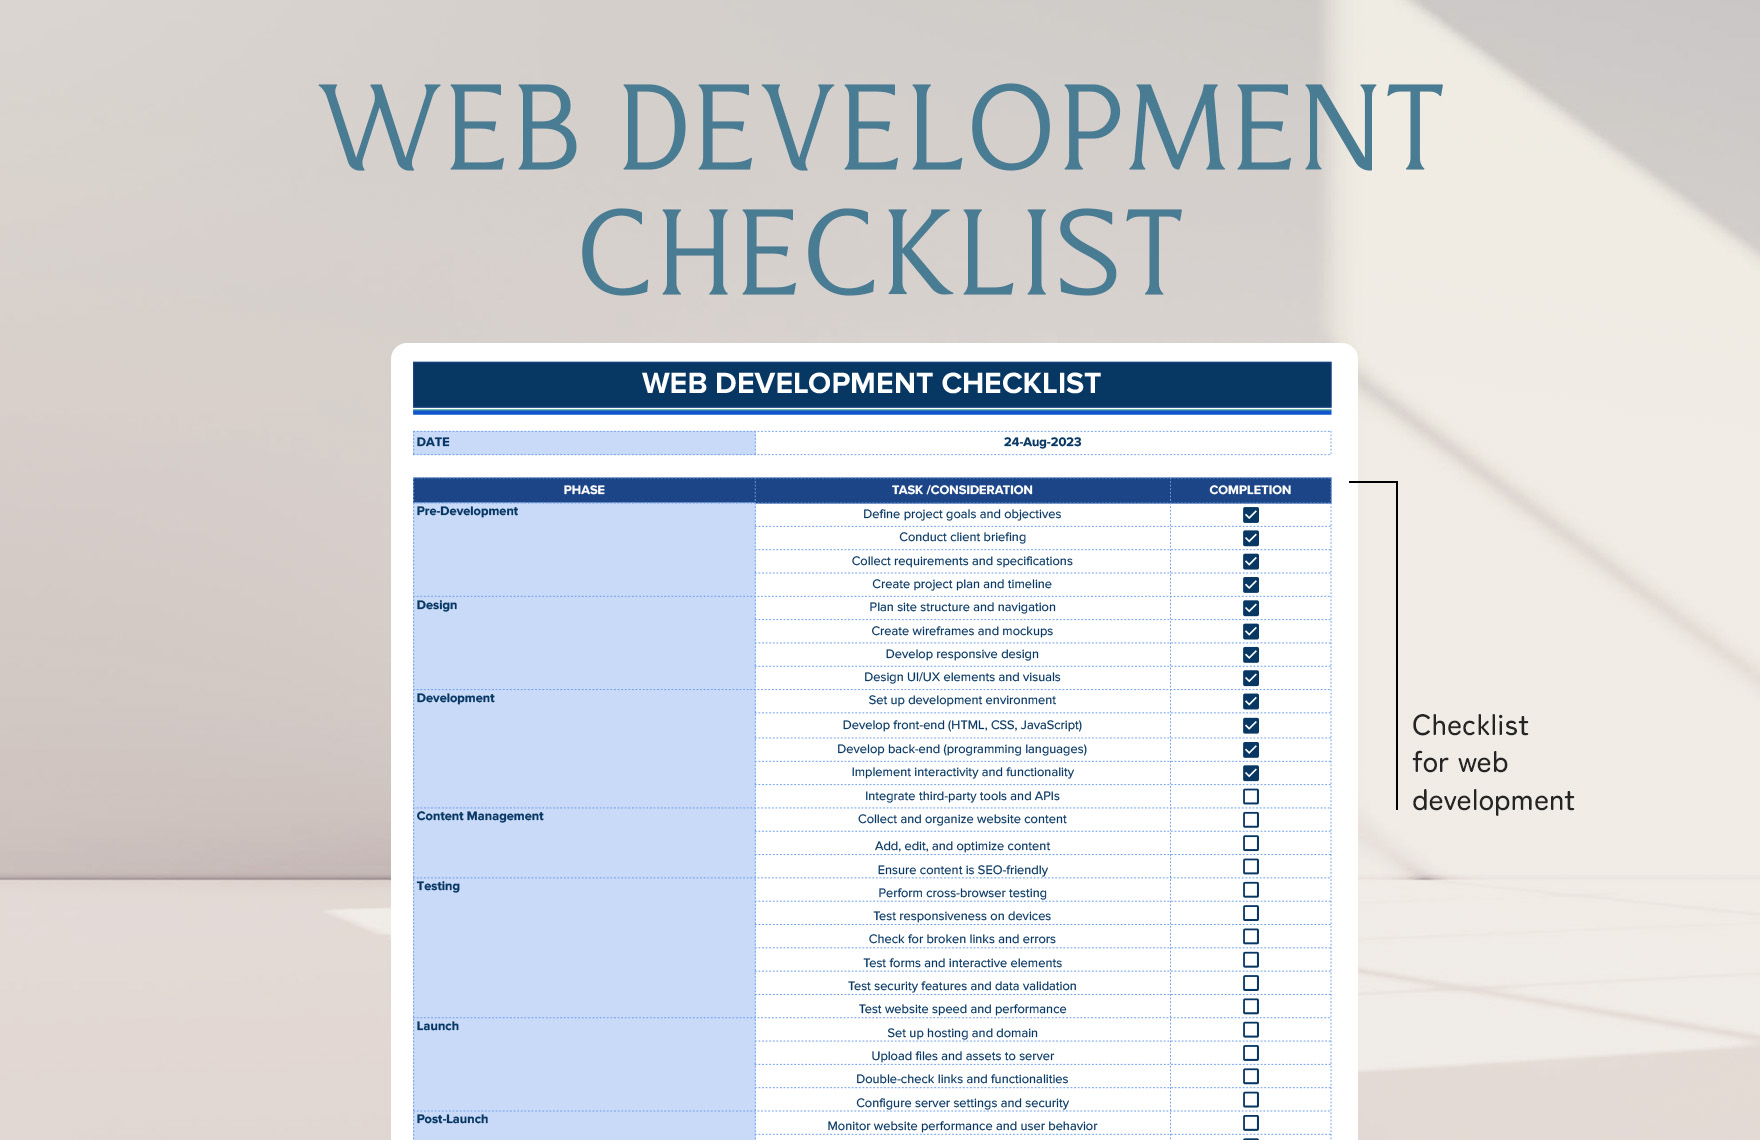
The Checklist For Web Development 2026 is not a static document. It evolves as the stack changes, as new browser APIs become available, and as the team encounters new failure modes. Keep it in the repository. Review it after every post-mortem. If an item was not relevant this sprint, mark it as obsolete rather than deleting it, so the reasoning is preserved for the next person who reads it.

