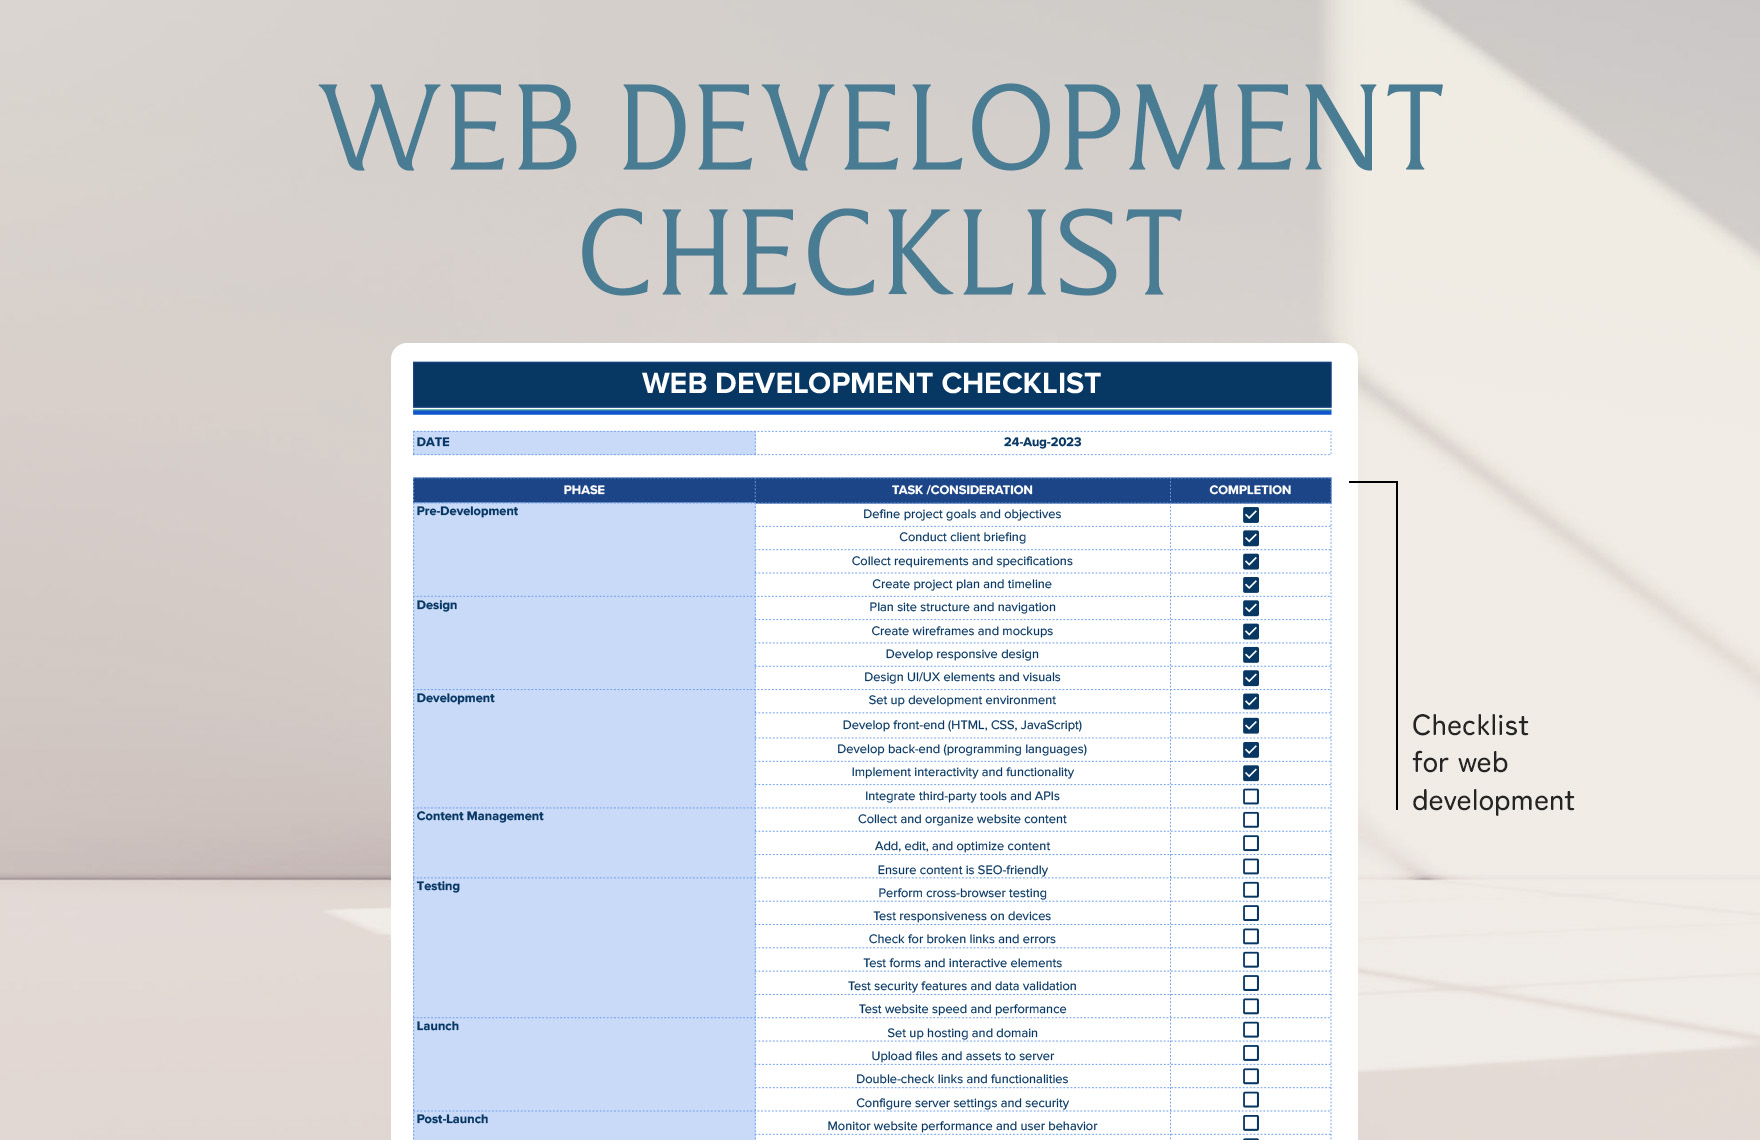
What Actually Stays On A Web Dev Checklist After Five Years Of Shipping Things
I spent the first two years of my career keeping these things in Google Docs, constantly reformatting them whenever some new tool appeared. I stopped doing that around 2019 when I realized I was spending more time maintaining the checklist than using it. What follows is basically a distilled version of what actually stuck after I stopped treating it like a sacred document and started treating it like a tool that needed to earn its place on every project. Start with the basics nobody wants to talk about because they sound obvious until a client asks why the site scores a 42 on Core Web Vitals. Semantic HTML is the first line of defense. I see teams skip this constantly, slapping divs everywhere and calling it a layout choice. It isn't. Every heading level should correspond to actual content hierarchy. Screen readers parse heading order, not CSS. The time it takes to add proper semantic markup is roughly the same as fixing it after an accessibility audit catches it, except the audit version costs money and the markup version costs nothing. Performance checks need to happen before any framework gets involved. I had a project once where a team deployed a React app that hit 3.2MB of JavaScript on first load because they hadn't split routes or audited their dependency tree. The actual feature set was a contact form and an about page. We cut that down to 89KB by removing three unnecessary libraries, implementing code splitting, and compressing images at build time instead of serving WebP variants from the asset folder. That's not a theoretical improvement. It's what actually happened over a Tuesday afternoon in 2022.
HTTPS isn't optional anymore. It's been embedded in browser behavior to the point that certain APIs simply refuse to work on insecure contexts. Geolocation, service workers, and the clipboard API all require secure origins. If you're not serving over HTTPS, you're consciously deciding to exclude functionality. That's a decision worth making intentionally rather than accidentally landing there because someone forgot to configure the SSL certificate on the staging environment. Version control practices matter more than most junior developers realize at the start of a project. I recently reviewed a codebase where the commit messages spanned from "fix stuff" to "another update" to "please work." There was no conventional commit structure, no branch naming convention, and merge conflicts that resolved into broken states because nobody understood what had changed between deployments. Setting up a simple .editorconfig file and a Husky pre-commit hook took about twenty minutes and prevented approximately twelve hours of confusion per sprint going forward. Here's something counter-intuitive that people consistently miss: more CSS doesn't mean better design. I've seen production sites where the stylesheets exceeded 400KB uncompressed, loaded on every single page including API endpoints that returned JSON. Framework-generated CSS bundles are a real problem when you're not tree-shaking properly. PostCSS with purge options configured correctly can reduce that footprint by eighty percent in most cases. The catch is that dynamic class names generated at runtime won't be purged, so you need to either avoid that pattern or maintain an explicit allowlist. That's the part most tutorials don't cover.
Accessibility testing should not rely solely on automated tools. The axe-core scans and Lighthouse accessibility audits catch maybe thirty percent of actual issues. I once shipped a form that passed every automated check and still couldn't be completed by a user navigating entirely with a keyboard. The problem was a custom dropdown component that trapped focus inside an element without proper focus management. Automated scanners can't detect whether tab order follows visual order when components are built with JavaScript. You have to manually test with a keyboard and ideally run the site through a screen reader at least once per major release. Build pipelines deserve more attention than they typically get. A properly configured CI/CD workflow catches deployment errors before they reach production. I configured a GitHub Actions pipeline for a project that ran ESLint, unit tests, type checking, a build step, and a deploy command. The total execution time was about four minutes. The first time it ran on a feature branch, it caught a TypeScript error that would have caused a silent runtime failure in production. That single catch saved an incident ticket and roughly thirty minutes of debugging that would have happened at 11 PM on a Friday. Security headers are another area where the default state is dangerous and the fix is five lines of configuration. Content-Security-Policy, Strict-Transport-Security, X-Content-Type-Options, Referrer-Policy, and Permissions-Policy should all be set explicitly. I worked on a project where the initial security audit revealed no CSP header existed, meaning any injected script could execute without restriction. Adding a strict CSP that allowed only inline scripts from approved sources eliminated the XSS vector that the penetration testing team had flagged. The header configuration itself took about ten minutes to write and validate.
Get the Full Details

Mobile responsiveness isn't just about making things fit on small screens. It's about acknowledging that touch interaction has different requirements than pointer interaction. Hit areas need to be at least 44 by 44 CSS pixels according to WCAG guidelines. I've seen buttons that were 24 pixels tall with generous visual padding that collapsed to nothing on mobile, making them unusable. The fix was measuring touch targets by their interactive boundary, not their visual appearance. CSS tap-highlight-color and touch-action properties also matter more than most developers account for. Documentation within the codebase itself is often neglected. JSDoc comments, README files that explain how to actually run the project locally, and environment variable templates are the minimum. I joined a project where the README listed ten npm scripts but didn't specify which environment variables were required for each one. The developer onboarding time was estimated at two days. It took three weeks because nobody had documented that the API key configuration differed between staging and production in ways that weren't obvious from the code alone.
Where Checklists Fall Apart
The honest part of this conversation is that no checklist replaces architectural thinking. I've watched teams complete every item on a twenty-point web development best practices checklist and still ship a product that was unmaintainable six months later. The checklist ensures individual practices are followed. It doesn't ensure those practices compose into a system that scales with the team's actual needs. A checklist can verify that you've implemented code splitting, but it can't tell you whether your chunk boundaries make sense for your routing structure. Automation fatigue is real. When every project gets the same exhaustive checklist applied without adaptation, you end up with configuration overhead that slows development without proportionally improving outcomes. I've seen projects where the CI pipeline ran seventeen separate validation steps for a static marketing site with no dynamic functionality. That pipeline took eleven minutes to execute and blocked deployments because one of the later steps had a flaky dependency. Stripping the pipeline down to eight relevant steps cut the time to four minutes and eliminated the false failure rate entirely. Some items on these lists become obsolete as the ecosystem shifts. Service worker cache strategies that made sense three years ago are being replaced by cache-first patterns driven by newer browser capabilities. The same goes for certain polyfill requirements and legacy browser support targets. Running a checklist verbatim from 2020 on a 2024 project will produce technically correct but unnecessarily conservative results. The checklist needs regular revision to reflect what the current tooling and browser landscape actually support.
There's also the question of who the checklist is for. A developer checklist, a QA checklist, and a stakeholder review checklist are fundamentally different documents that share some overlap. Combining them into one master document creates confusion about whose responsibility each item is. I maintain three separate checklists now. One for development setup and code quality, one for pre-launch QA verification, and one for client-facing readiness review. Each serves a distinct purpose and gets consulted at a different stage of the project. If you want something practical to work from, start with the items that prevent the most expensive failures. Semantic structure, HTTPS, basic security headers, and functional build automation catch the problems that cost the most to fix after deployment. Everything else can be refined as the project demands it. The goal isn't to check every box on every project. The goal is to develop judgment about which boxes actually matter for the specific thing you're building.