So You Need To Model Chemical Reactions And Chemical Reactors Without Setting Your Lab On Fire
The first thing most people mess up when they start working with Chemical Reactions And Chemical Reactors is assuming the reactor behaves like the textbook diagram. It doesn't. I learned this during a pilot plant run where we were scaling up a continuous esterification in a 500-liter CSTR. The lab-scale data from a 2-liter batch reactor predicted a 94 percent conversion at 85 degrees Celsius and a residence time of about 45 minutes. We ran the CSTR at those exact conditions and got 71 percent conversion. Four days of troubleshooting later, the issue wasn't the kinetics. It was dead zone formation near the baffle joints that effectively reduced the active reactor volume by roughly 18 percent. The reactor was still mathematically "at steady state." The chemistry just wasn't seeing the whole volume.
Starting With The Material Balance — Before You Touch Any Code
Most people jump straight into MATLAB or Python before writing down the balance equation in plain words. That's backwards. Write the balance on a whiteboard first. For a general unsteady-state reactor with inflow, outflow, generation, and consumption, it's simply accumulation equals inflow minus outflow plus generation minus consumption. If your system is liquid phase and density is essentially constant, you can drop the volume change terms. If it's gas phase with a mole change, you need to track that. I've seen multiple engineers miss the mole change term in a dehydration reaction and waste three iterations of convergence because the volumetric flow rate at the outlet was different from the inlet by nearly 30 percent.Choosing The Right Reactor Model For Your Data
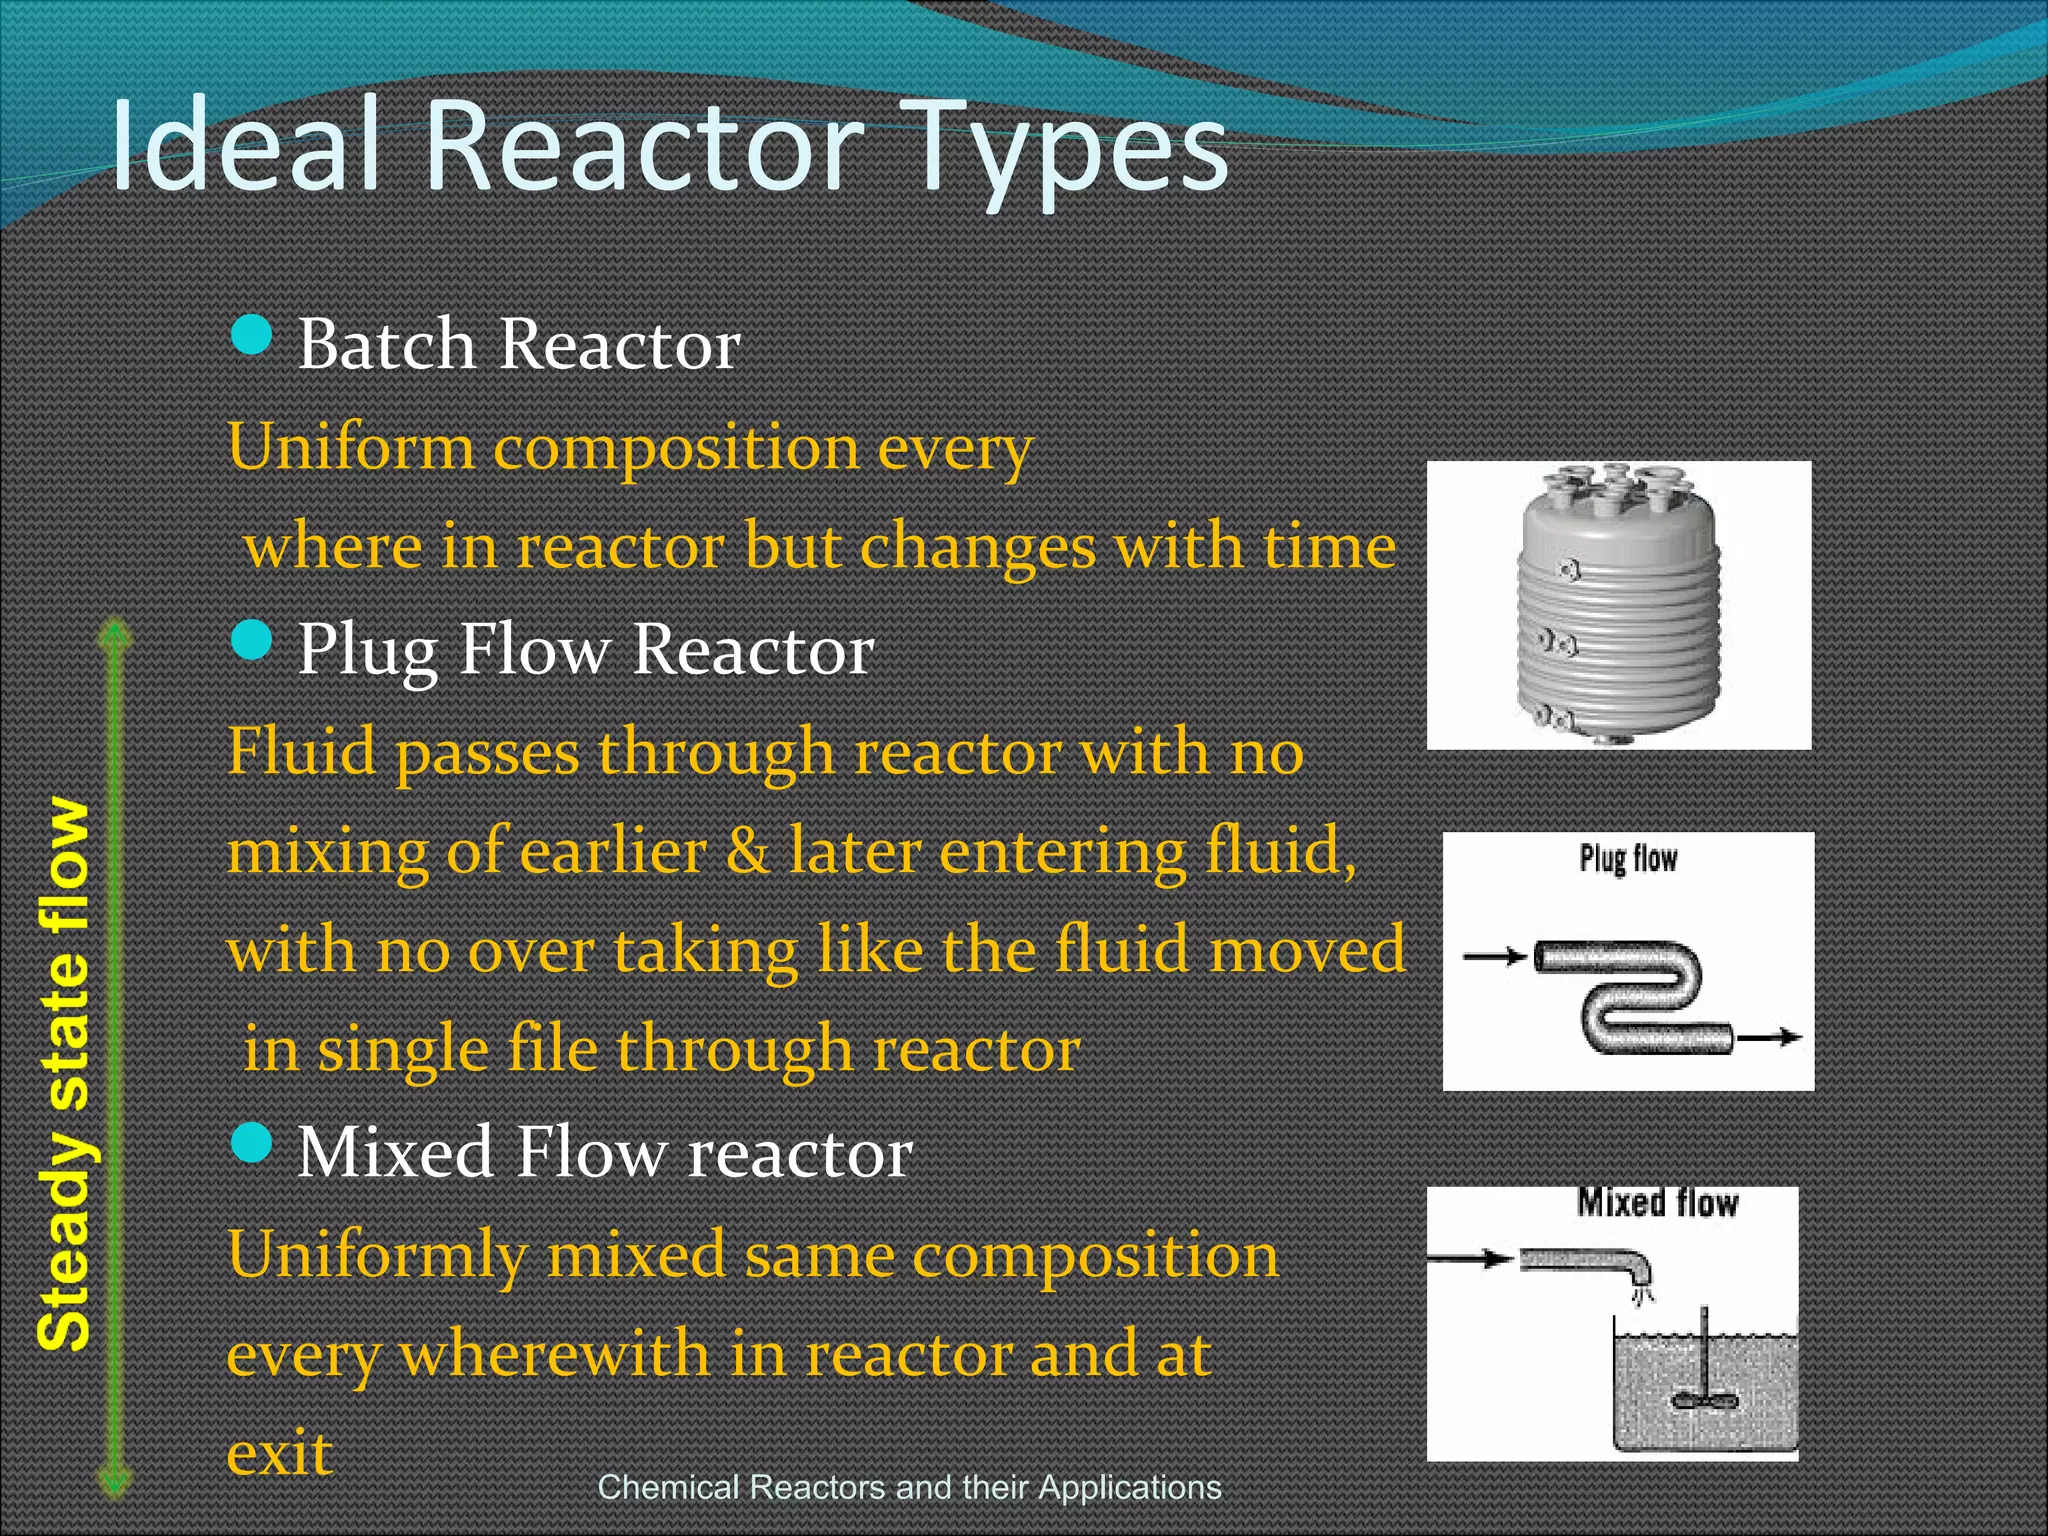
A plug flow reactor is not a real thing. It's a limiting case. What it actually means is that every fluid element spends exactly the same amount of time in the reactor and there's no radial mixing. A perfectly mixed CSTR means the outlet concentration equals the concentration everywhere inside the vessel. Real reactors fall somewhere between these two extremes. The compactness ratio — the Damkohler number relative to the Peclet number — tells you which model to use. If Da is less than 0.1 and Pe is greater than 100, PFR behavior is a decent approximation. If Da is above 10 and mixing is poor, you're likely in a regime where even a CSTR model will mislead you, and you need a dispersion model or a tanks-in-series approach. I worked on a hydrogenation project where the feed had significant back-mixing due to a poorly placed sparger. The dispersion model with an experimentally determined Peclet number of about 12 matched the conversion data within 3 percent. The PFR assumption overpredicted conversion by 14 percent, which translated to undersized downstream separation equipment. We had to re-engineer the gas distribution manifold, not just the reactor itself. The cost of that redesign was roughly four times what the initial engineering estimate for the vessel had been.Parameter Estimation Without Fitting to Noise
When you're pulling Arrhenius parameters from conversion data, don't use a simple linear regression on ln(k) versus 1/T without checking the residuals properly. I saw a dataset where someone reported an activation energy of 82 kilojoules per mole for an enzymatic hydrolysis reaction. The R-squared value was 0.97, which looked fine at first glance. When I plotted the residuals against temperature, there was a clear curved pattern. The actual mechanism switched at around 45 degrees Celsius because the enzyme started denaturing. The real activation energy for the operative range was closer to 45 kilojoules per mole. Reporting the higher value led to a reactor design that operated 12 degrees too hot in the winter months, causing continuous catalyst deactivation. Weighted nonlinear regression with proper error modeling matters more than people admit. If your conversion measurements have standard deviations that increase with conversion — which they almost always do in HPLC-based monitoring — you need to weight each data point inversely to its variance. Unweighted fitting will bias the parameters toward the high-conversion region where the absolute errors are larger but the relative precision is worse.Get the Full Details
Numerical Integration — Where Things Actually Break Down
Stiff systems are not a theoretical concern. They happen constantly in combustion chemistry, atmospheric reactions, and any system where fast and slow timescales coexist. A simple explicit Euler method with a fixed step size will either take forever with tiny steps or blow up completely. I ran a methane oxidation model using a fourth-order Runge-Kutta method with a maximum step size of 1 millisecond. The simulation ran for six hours on a decent workstation and the results were still oscillating near the steady state. Switching to CVODE with automatic stiff detection and variable step sizing dropped the computation time to about 40 seconds with tighter tolerance control. The difference isn't just convenience. It's the difference between getting an answer and never getting an answer because the solver gave up after hitting iteration limits. For steady-state CSTR problems, Newton-Raphson iteration on the nonlinear algebraic equations works well if your initial guess is close. If it's not close, the iteration diverges and you waste time. A continuation method where you gradually increase the Damkohler number from a known low-conversion solution is much more reliable. Start at Da equal to zero, where the solution is trivial, and increment by small steps until you reach your target. This traces the full bifurcation curve and reveals multiple steady states that a single Newton solve would miss entirely. Multiple steady states are not rare in exothermic CSTRs. They show up whenever the heat generation curve intersects the heat removal line at three points instead of one. The middle intersection is unstable. Operating near it without awareness can cause thermal runaway if a small disturbance pushes the system to the upper branch.Transient Operation and Startup Sequences
Startup and shutdown transients are where most safety incidents originate. A common mistake is assuming that once the reactor reaches steady state, you can jump between operating points instantaneously. In reality, thermal inertia in the reactor walls and the heat transfer fluid creates a lag that can take 20 to 40 minutes depending on the vessel size and insulation. I was reviewing a process where operators ramped the feed temperature too quickly during a cold start of an exothermic polymerization. The reactor temperature undershot the setpoint by 15 degrees initially, then surged past it by 25 degrees once the reaction kicked in, producing off-spec product for about an hour and requiring a full drain and cleanout of the reactor. The control system didn't have a ramp constraint on the feed temperature, so it responded aggressively to the error signal. Adding a rate limiter to the manipulated variable in the controller and implementing a soft start sequence where the feed is introduced at 20 percent flow for the first 30 minutes reduced the temperature overshoot to under 5 degrees in subsequent startups. This is basic process control, but it's not built into default reactor models in most textbooks.Scaling From Lab to Production
Geometric similarity doesn't guarantee similar performance. A 10-fold scale-up in volume does not produce a 10-fold scale-up in conversion. Mixing time increases with the square of the characteristic length, while reaction rate scales differently depending on the order. In a first-order reaction, the Danckwerts number — the ratio of mixing time to reaction time — determines whether you're in a micromixed or macromixed regime. If the mixing time becomes comparable to or longer than the reaction time at scale, the conversion drops significantly even though the residence time is unchanged. I ran a chlorination reaction where the lab-scale reactor had a mixing time of about 8 seconds and the production-scale vessel had a mixing time of roughly 45 seconds. The reaction half-life was about 30 seconds. The production reactor produced a different isomer distribution than the lab because the chlorination was mixing-limited rather than kinetically limited. We added an intermediate impeller and reduced the spacing, cutting the mixing time to about 20 seconds and restoring the lab-scale selectivity.Software Choices and Their Hidden Costs
Commercial simulators like Aspen Plus and COMSOL are powerful but they hide assumptions you need to understand. Aspen's reactors assume perfect mixing in RCSTR and ideal plug flow in RPlug unless you specify otherwise. COMSOL solves the full Navier-Stokes equations coupled with species transport and energy, which is accurate but computationally expensive. A 3D transient simulation of a 500-liter stirred tank with reactive species can take days on a cluster. For most design work, a 1D PFR model with experimentally validated dispersion coefficients gets you 90 percent of the accuracy at 1 percent of the computational cost. Use the expensive tool only when you need spatial detail — for example, when predicting hot spots in a packed bed catalyst or local concentration gradients in a membrane reactor. Open-source options like Cantera for detailed kinetics and Cantera's integrated reactor networks are solid for gas-phase and combustion chemistry. For liquid-phase systems with complex rheology, Pyomo with CasADi gives you good mixed-integer nonlinear programming capability at no license cost. The learning curve is steeper, but the transparency about what's happening under the hood makes debugging easier. I spent about three weeks learning the Pyomo interface for our steady-state optimization work, and that time paid off within a month when we had to modify the objective function multiple times and the commercial software kept throwing cryptic solver errors that we couldn't diagnose.
Common Pitfalls That Waste Weeks
Using steady-state data to fit transient parameters, or vice versa, is the most frequent error I encounter. Kinetic parameters estimated from batch reactor data can differ from those estimated from CSTR data if there are mass transfer limitations that become significant at higher flow rates. Always validate your kinetic model in at least two different reactor types before trusting it for design. Heat of reaction values from calorimetry can vary by 10 to 15 percent depending on the solvent and concentration. Make sure your thermal data matches your actual reaction conditions, not a diluted model system. Pressure drop calculations in packed beds using the Ergun equation assume spherical particles and a uniform bed. Real catalyst pellets are irregular and the bed can channel over time, especially after multiple thermal cycles. Measure the actual pressure drop at your operating conditions rather than relying solely on the correlation.
When Your Model Is Wrong — And How to Tell
A model that fits perfectly is usually wrong. Natural experimental systems have noise. If your residuals show no pattern and your confidence intervals are reasonable, you're probably in good shape. If the model predicts zero deviation from every data point, you've overparameterized it or you're fitting to a corrupted dataset. Cross-validation is essential. Hold out 20 percent of your experimental data, fit the model on the remaining 80 percent, and check the prediction error on the held-out set. A good model typically has a prediction error within 1.5 times the experimental standard deviation on the validation set. If it's 3 times or more, your model structure is inadequate — likely missing a reaction pathway or a transport limitation.Practical Workflow That Saves Time
Start with a dimensionless analysis. Non-dimensionalize your governing equations before solving them numerically. This reveals the key groups controlling the system behavior and helps you identify which parameters matter most. A sensitivity analysis on the dimensionless groups is faster and more insightful than varying individual dimensional parameters. After you have a working model, validate it against independent data before using it for any design decisions. A model that has only been tested against the data it was fitted to is not a model — it's a curve fit with extra steps. Then, and only then, use it for scale-up predictions, optimization, or control system design. Each of these steps — fitting, validation, scale-up prediction — should be treated as a separate phase with its own acceptance criteria. Skipping validation because you're confident in the kinetics is how plants end up with reactors that can't hit specification at production rates.


