Working Through Chi-Square Problems in Practice
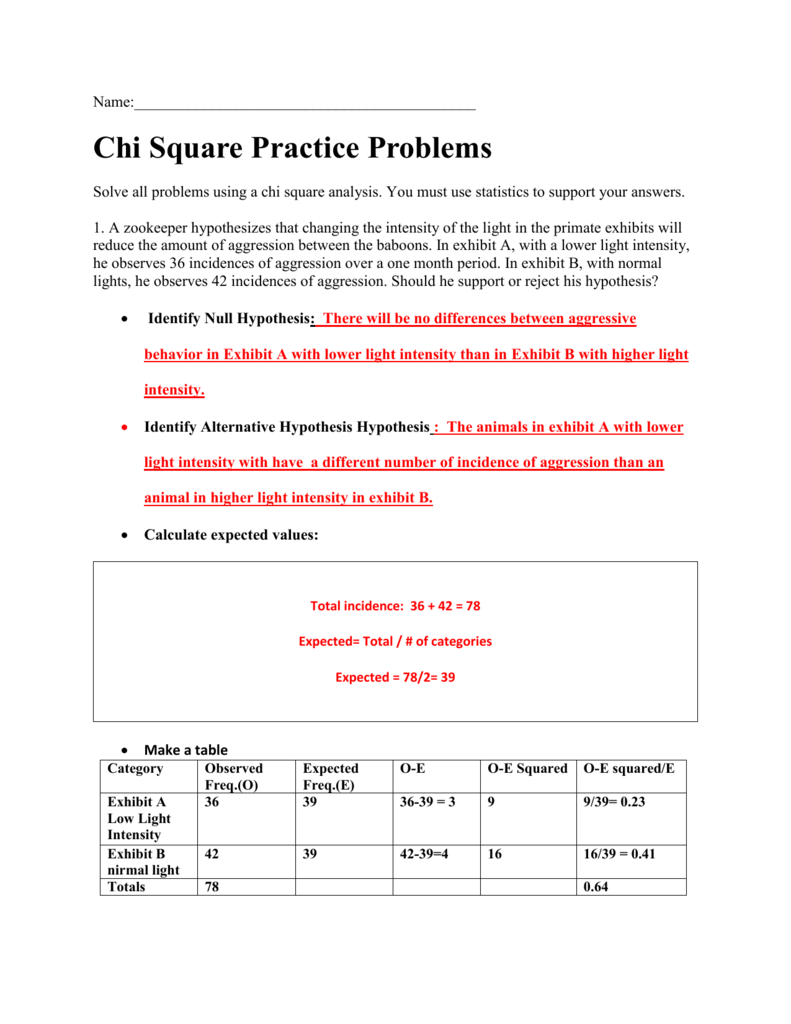
The chi-square test shows up constantly in quality control, biology, and social science work. It tests whether observed frequencies differ significantly from expected frequencies under a null hypothesis. That's the textbook version. The real world version involves messy data, small cell counts, and deciding whether you're actually testing for independence, goodness-of-fit, or homogeneity — three things that look identical until you're two hours into calculations. I work with this kind of stuff regularly. We had a situation last year where we were analyzing complaint categories across three different manufacturing shifts. The textbook Chi Square Practice Problems would make this seem straightforward. The actual dataset had five categories with two of them containing expected values under 5. That's the first thing most people miss. When expected frequencies drop below 5, the chi-square approximation breaks down and your p-values become unreliable. The workaround I ended up using was collapsing adjacent categories where it made logical sense, then running the test again. In some cases I switched to Fisher's exact test with a Monte Carlo simulation, which took about 45 seconds instead of relying on the asymptotic approximation.
Chi Square Practice Problems You'll Actually Run Into
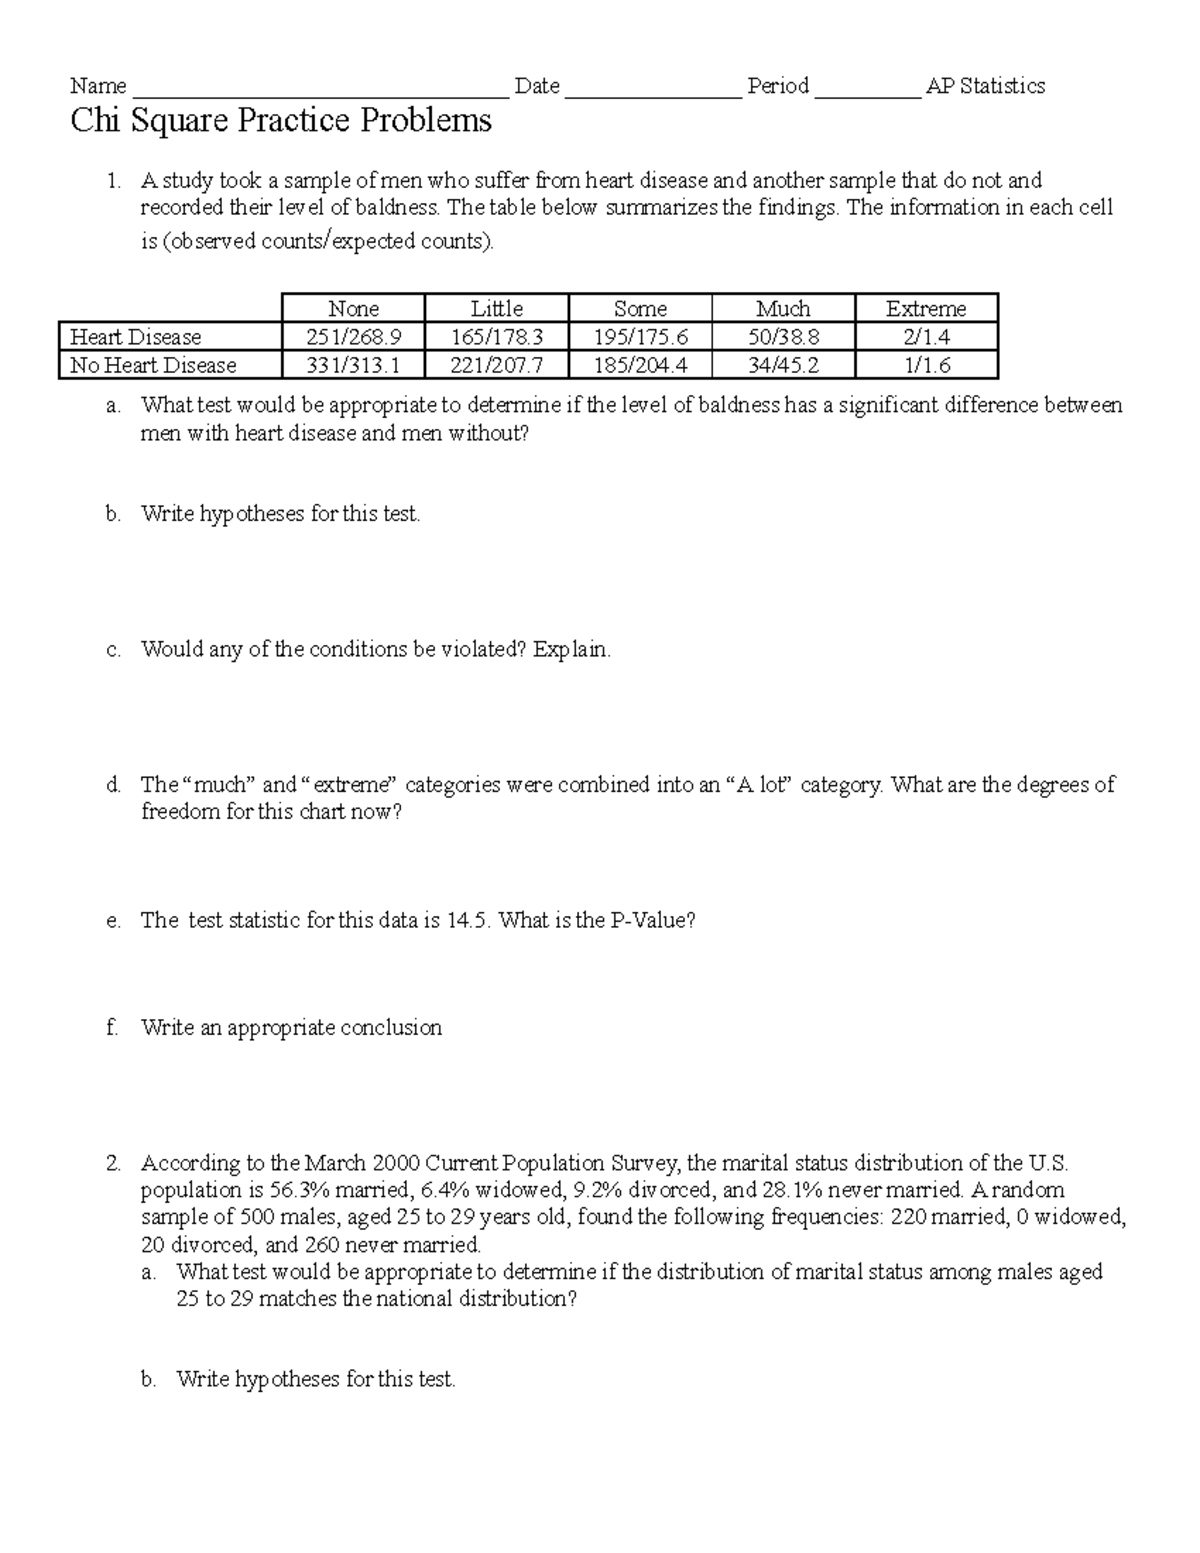
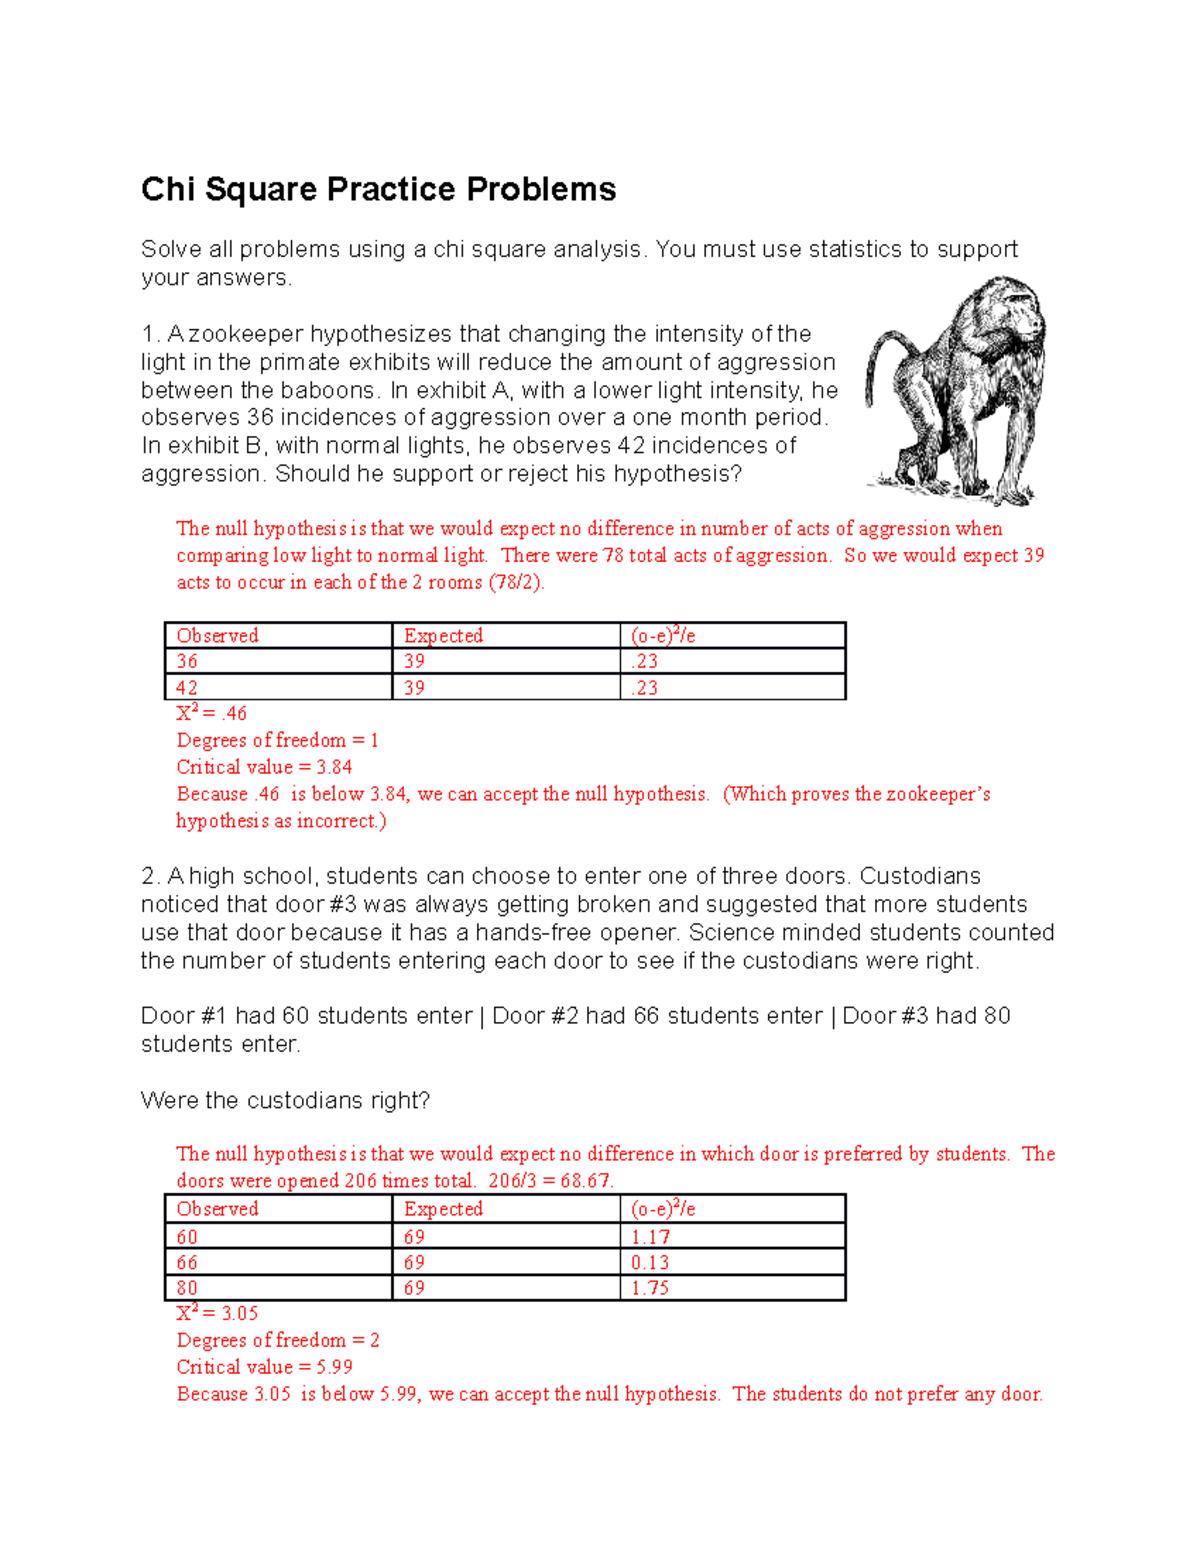
The most common type you'll see is the goodness-of-fit test. You have one categorical variable and you want to know if the distribution matches some theoretical expectation. Say you're checking whether a die is fair. You roll it 120 times and get counts for each face. The expected count per face is 20. The formula is straightforward: sum of (observed minus expected) squared, divided by expected, across all categories. You compare your calculated chi-square statistic against a critical value from the chi-square distribution with degrees of freedom equal to the number of categories minus one minus the number of parameters estimated from the data. The second type is the test of independence. You have a contingency table with two categorical variables and you want to know if they're related. Row times column divided by grand total gives you each cell's expected value. Subtract observed from expected, square it, divide by expected, sum everything up. Degrees of freedom are (rows minus one) times (columns minus one). This is the one most people mess up on because they forget that degrees of freedom depend on the table dimensions, not the total sample size. The third type, test of homogeneity, follows the same calculation as independence. The difference is purely in how you designed the study. Independence means you sampled one group and measured two variables. Homogeneity means you sampled separately from different populations and measured one variable. The math is identical. The interpretation is different. I've seen people lose points on exams and waste time in reviews because they couldn't tell which design they were dealing with after the calculation was done.
Here's something that isn't obvious: the chi-square test is sensitive to sample size in a way that trips people up. With a huge sample, even trivial differences become statistically significant. With a small sample, meaningful differences might not reach significance. A chi-square value that looks impressive might just mean you have 10,000 observations and a barely noticeable deviation from the expected distribution. Look at effect size measures like Cramer's V or phi coefficient, not just the p-value. Phi is appropriate for 2x2 tables and equals the square root of chi-square divided by the sample size. Cramer's V generalizes this to larger tables. Another thing that causes problems: the test assumes observations are independent. If you're counting the same individual multiple times or your sampling method introduces clustering, the chi-square result is invalid. I've worked with survey data where respondents were grouped by clinic and the intra-cluster correlation was ignored. The effective sample size was a fraction of what the raw count suggested, and the chi-square test gave a wildly significant result that disappeared once I accounted for the clustering structure. When you're doing these problems manually, the arithmetic gets tedious fast. A 4x5 contingency table has 20 cells. Each one requires subtraction, squaring, division, and accumulation. I used to spend about 25 minutes on a moderate-sized problem by hand. Now I use Python with scipy.stats.chi2_contingency and it takes about 10 seconds. The point isn't to avoid learning the manual method — you need to understand it to catch when software gives you nonsense — but there's no reason to waste time on calculator work once you understand the mechanics.
Get the Full Details
There are also situations where chi-square isn't appropriate and people don't always recognize that. Paired categorical data, like before-and-after measurements on the same subjects, requires McNemar's test, not chi-square. Repeated measures across more than two time points need different approaches entirely. Ordinal data where the ordering matters loses information when you treat it as nominal in a standard chi-square test. In those cases, a trend test or nonparametric alternative like the Mann-Whitney U or Kruskal-Wallis test might be more suitable. One more thing: Yates' correction for continuity. It applies to 2x2 tables and subtracts 0.5 from the absolute difference between observed and expected before squaring. It makes the test more conservative, which reduces false positives but also reduces power. Most statisticians consider it outdated for anything except small 2x2 tables. If your expected counts are reasonable, skip it. If they're small, consider Fisher's exact test instead, which doesn't rely on approximations at all. The key takeaway is that the calculation is the easy part. Understanding when to use the test, when it fails, and what the result actually means is where the work is. Run diagnostics on your expected frequencies first. Check your study design against the test assumptions. Report effect sizes alongside p-values. And don't treat a significant chi-square as proof of anything without considering practical significance.