The pipelines nobody told you about
I spent about two years manually validating data pulls, model outputs, and feature transformations before I figured out that the problem wasn't a lack of documentation — it was that I was treating ML work like it doesn't need the same checks as application code. It does. The difference is the checks are harder because your inputs are messy and your "output" isn't a binary pass/fail. Ci Cd In Data Science isn't really about deploying code quickly. That's a side effect. It's about catching the things that break quietly. A training script can run clean with zero errors while silently learning from shifted data because a column renamed itself upstream. Without automated checks, nobody notices until the dashboard looks wrong three weeks later.
What actually happens when you set this up
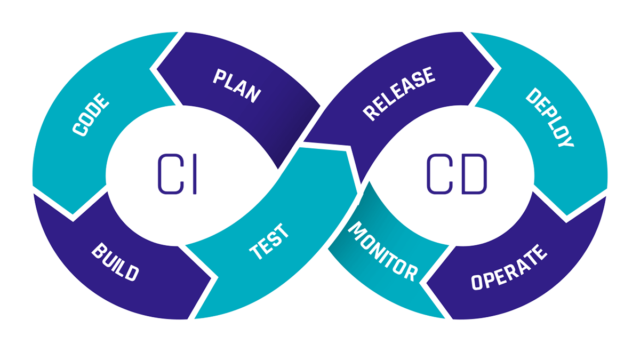
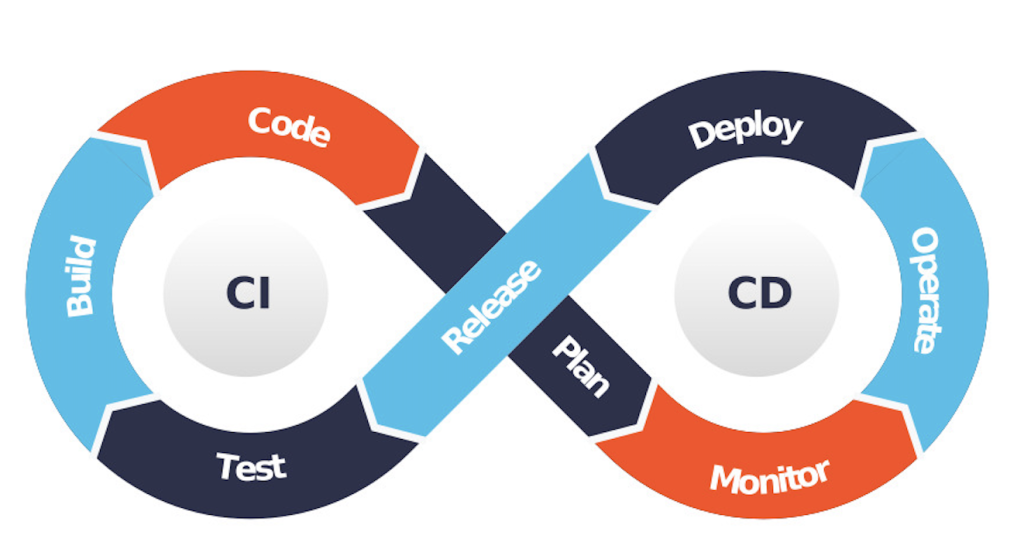
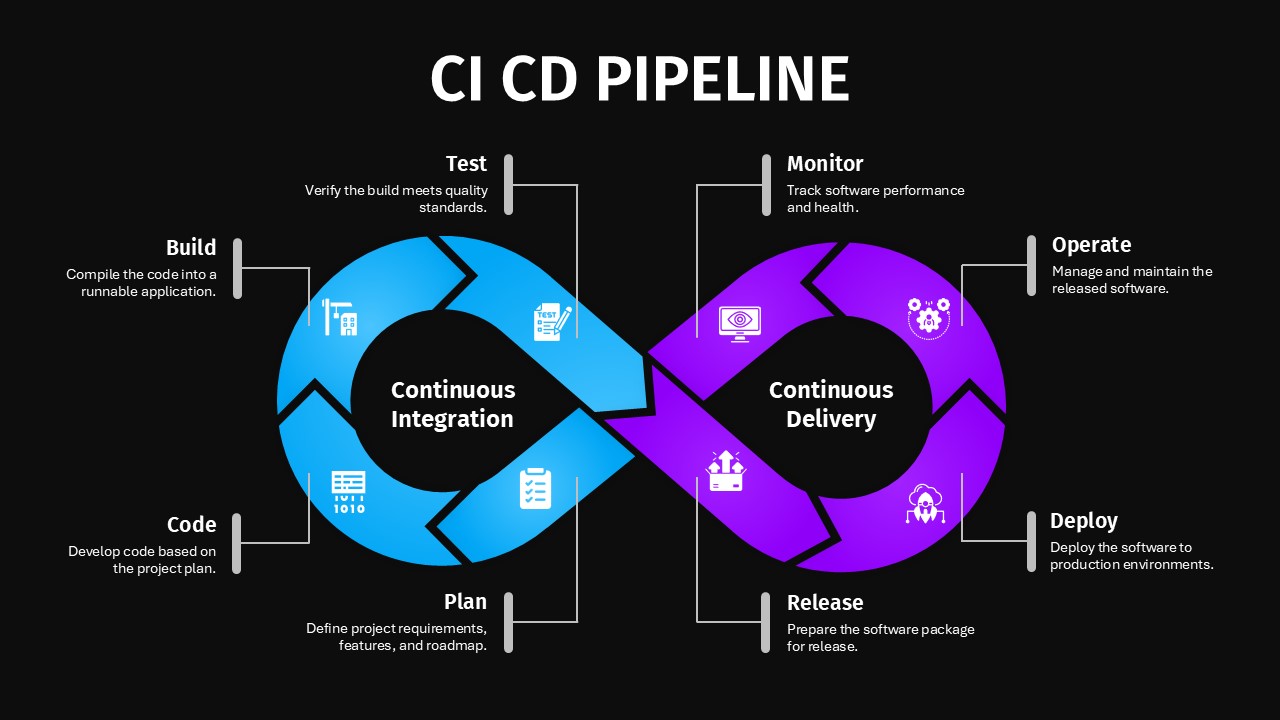
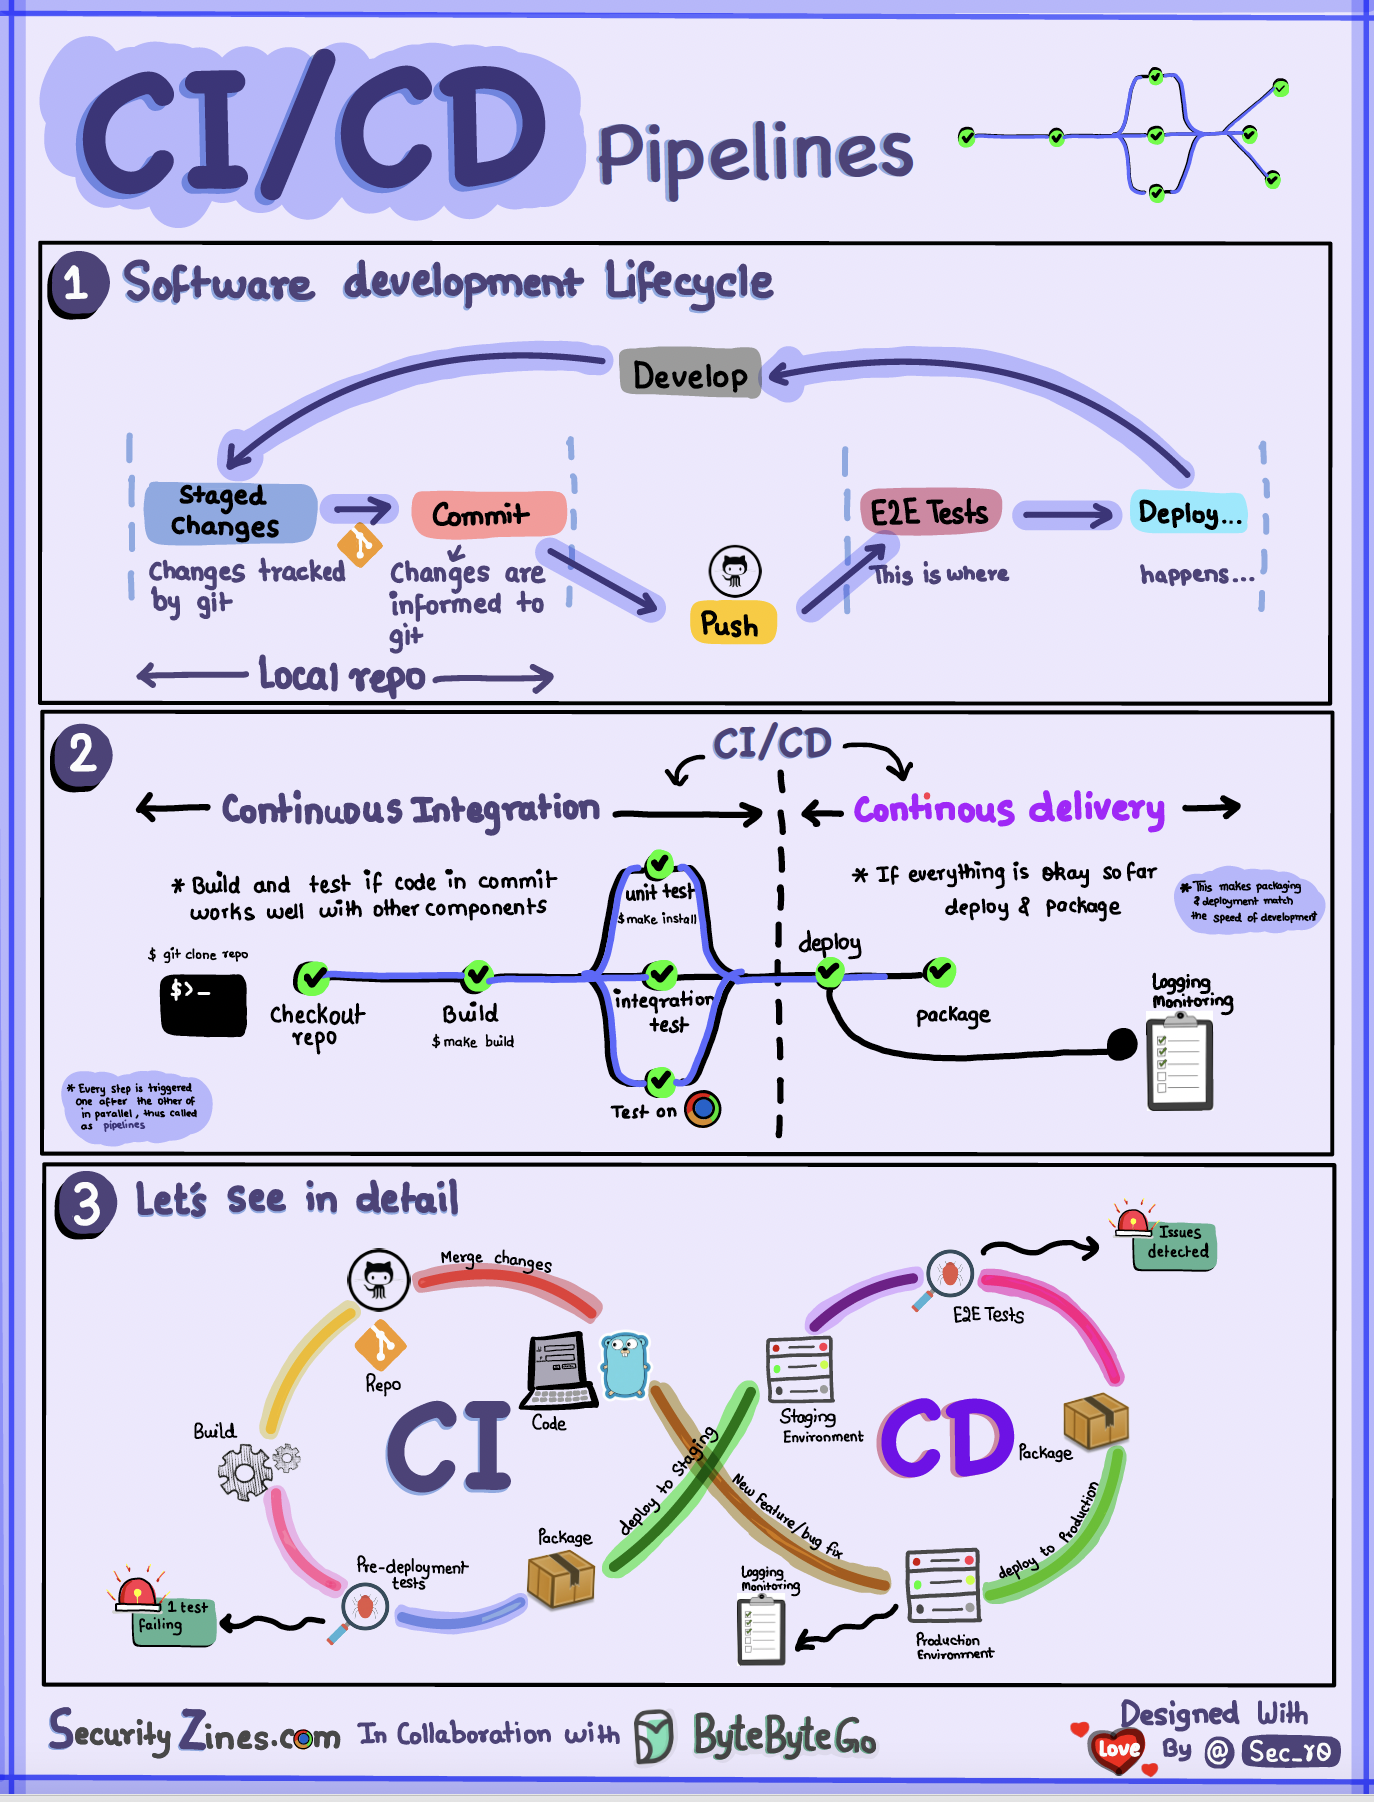
First, you define your stages. For data science specifically, the stages look different from a standard software pipeline. You have data validation, feature computation, model training, model evaluation, and deployment. Each stage has its own purpose and its own failure modes. Data validation runs before anything else. You check schema, missing value thresholds, and distribution baselines against historical snapshots. Great Expectations or Soda Core both work fine for this. If the incoming data fails the checks, the pipeline stops. This is where most people skip and move on to the next stage anyway. Don't do that. Bad data downstream creates bad models and debugging which is which is nearly impossible without early blocking gates. Feature computation is where I wasted an entire sprint on a broken assumption. The feature engineering code had a conditional branch that only triggered under certain null conditions. The test suite I wrote only covered the happy path. The pipeline passed all checks for three weeks. Then production traffic hit a segment that hit the null condition and the features came out garbage. I ended up writing a dataset diff tool that compared feature distributions between the test environment and the production input at each run. It caught the drift immediately after that. Not pretty, but it worked and now I include similar checks in every pipeline I build.
Model training runs the actual fit. This is where you want to pin dependency versions. Not the latest numpy. Not the latest pandas. Specific versions. If you skip this, two CI runs six months apart will train completely different models because an upstream dependency updated and changed behavior. We've all seen the numpy 2.0 migration. It was not fun in a production pipeline. Model evaluation is the stage people get wrong most often. Running accuracy metrics isn't enough. You need to define what passing looks like before the pipeline ever trains. Set a baseline from the previous model and require the new model to beat it on your primary metric. Also log the confusion matrix, calibration curves, and fairness metrics if you're dealing with anything that affects people. Automated drift detection between training and serving data should be part of this stage too. If the feature distribution shift is above your threshold, the model doesn't go further regardless of how good the validation score looks. Deployment for data science is different from deploying an API. Sometimes you deploy a model artifact to a registry and trigger an offline batch job. Sometimes you push to a serving endpoint. The CI step should validate that the artifact loads correctly in the target environment before marking the pipeline green. I always add a smoke test that loads the model and runs inference on a fixed sample, then compares the output hash to an expected range. Models can compile fine and still produce NaN predictions at runtime if a dependency mismatch snuck in.
Get the Full Details
Where this actually breaks down
CI/CD for data science is expensive to maintain. Your pipeline has more moving parts than an application pipeline. Data sources change. Schema drifts. Feature stores update. Model frameworks evolve. Every one of these can break a pipeline that otherwise looks healthy. You will spend more time fixing the pipeline than building the actual models in the early stages. Reproducibility is a myth unless you invest heavily in it. Even with pinned dependencies and versioned data, subtle differences in hardware, parallelism settings, or floating point ordering can produce different results. I learned this when a pipeline that produced identical results locally started producing slightly different AUC scores after moving to a GPU cluster. The difference was 0.003. It still caused the evaluation gate to fail randomly. I ended up accepting a small tolerance band instead of demanding exact reproducibility. It's not ideal but it's realistic. Small teams especially struggle with this because the maintenance burden falls on the same people who are supposed to be doing the data science work. I've seen teams set up full CI/CD pipelines and then abandon them within a month because fixing pipeline failures took longer than just rerunning things manually. That's a signal that your pipeline is over-engineered for your current needs. Start smaller. Validate data at the entry point, pin versions, and add evaluation gates. Grow it gradually.
The tooling itself is fragmented. There's no single platform that does everything well for ML. You'll end up stitching GitHub Actions or GitLab CI together with MLflow for tracking, DVC or Delta Lake for data versioning, and either Kubernetes or a managed serving platform for deployment. Each piece introduces its own failure modes and configuration surface. Spend time understanding where the integration points are fragile before you commit to a stack. If you're working with very small datasets or doing exploratory analysis, CI/CD adds zero value. It's for anything that runs repeatedly in production with real consequences when something goes wrong. Don't apply it everywhere. Pick the pipelines that matter and automate those properly instead of spreading thin coverage across everything.