Historical Climate Prediction: What It Actually Is and How to Work With It
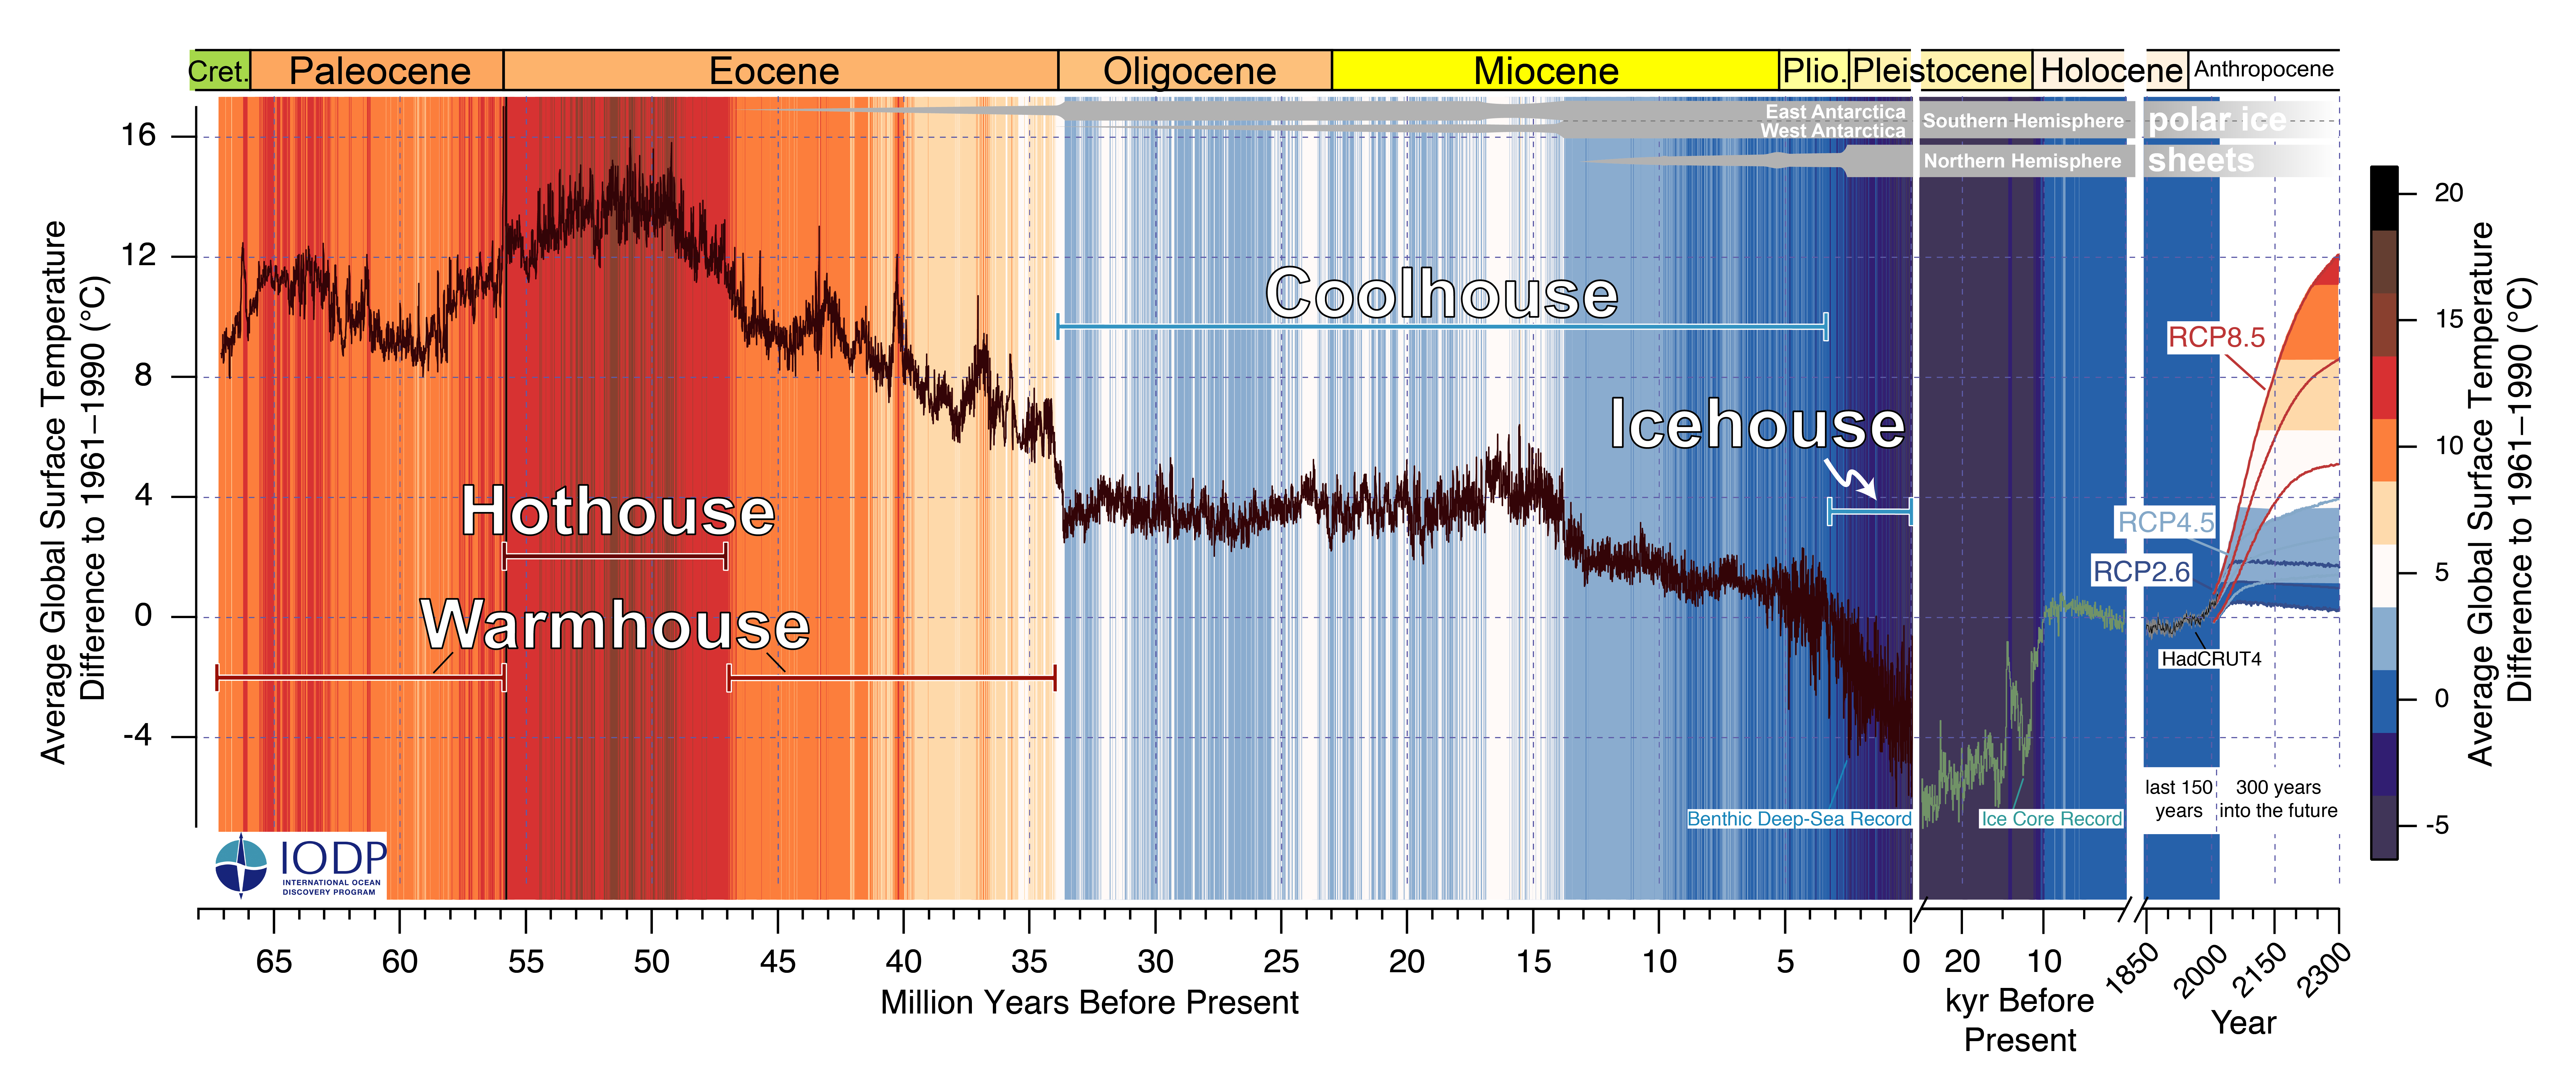
Historical climate prediction is less about forecasting weather from old records and more about reconstructing past climates using proxy data, then running those reconstructions through models to test how well we can back-predict. The core problem most people overlook is that the data itself is noisy and sparse. I've spent years wading through this stuff, and the first thing you learn is that nothing here is clean. Proxy records are the foundation. Tree rings, ice cores, sediment layers, coral growth bands, pollen counts, speleothems. Each one gives you a signal—temperature, precipitation, CO2 concentration, whatever the proxy responds to—but none of them are direct measurements. You're reading an echo. The calibration process involves matching proxy data against instrumental records where they overlap, usually going back 100 to 150 years for the most reliable datasets. That overlap period is your ground truth, and it's where most errors creep in. Models come second. Once you've built a reconstruction, you feed it into general circulation models (GCMs) or simpler energy balance models to see if the outputs match what happened. The verification step is critical. You hold out a portion of the instrumental record, run the model blind, and compare. If your model can't reproduce the 20th century warming accurately, claiming it nailed the medieval warm period is pointless.
Statistical techniques like regression analysis, principal component analysis, and Monte Carlo uncertainty propagation are standard tools. I usually start with a simple inverse calibration, solve for the climate variable, then bootstrap confidence intervals to see how much the error bars actually spread. The spread tells you whether your reconstruction is worth anything or just noise with delusions of grandeur. One practical note: Don't treat all proxies as equally reliable. A single tree ring record from a well-dated site in the Andes will outperform an aggregated dataset pulled from five poorly calibrated sources. Quality over quantity, every time.
A Real Problem I Hit and How I Worked Around It
I was working on a reconstruction for a mid-latitude region where the instrumental record was thin—barely 60 years of decent temperature data before the network thinned out significantly. The proxy sources available were mostly lake sediments, which respond to multiple overlapping signals: temperature, precipitation, organic input, even local vegetation changes. When I ran the initial calibration, the model was picking up a strong precipitation signal that I had no way to disentangle from temperature. The cross-validation scores looked fine during the overlap period because both variables happened to covary in the instrumental era, but when I pushed the model further back, it produced absurd results—temperatures swinging by nearly 4 degrees Celsius between centuries with no geological basis. The workaround was to use a multi-proxy approach with constraint. I brought in a nearby ice core record that was purely temperature-sensitive and used it as an independent anchor. I also introduced a regularization term that penalized solutions where temperature and precipitation diverged sharply from the known covariability in the instrumental period. This didn't fix everything—the uncertainty bounds were still wide—but it stopped the model from hallucinating climate swings that had no physical basis. The whole process took about three weeks that would have taken two months with a less constrained approach, but the result was defensible.
Get the Full Details
Things Beginners Get Wrong
The biggest mistake is assuming that correlation equals causation in proxy relationships. Just because a proxy record correlates with temperature during 1900 to 1950 doesn't mean that relationship held in 1300. Non-stationarity in proxy-climate relationships is a real issue and most introductory tutorials completely skip over it. The second mistake is publication bias. The literature is full of reconstructions that show dramatic past climate shifts because dramatic results get published. Reconstructions that come out flat and boring, which are actually more common and more accurate, rarely make it into prominent journals. Another nuance: spatial interpolation of proxy data is treacherous. A handful of scattered sites across a continent don't give you a reliable picture of hemispheric temperature. The famous "hockey stick" debates of the early 2000s were partly about this—methods that downweighted spatial coverage ended up producing smoother, less variable reconstructions than methods that over-interpolated between sparse points. There's no perfect answer here. You have to be honest about what your spatial resolution actually supports.
Downsides and Where This Approach Breaks Down
This work has real limitations. Proxy data resolution is coarse. Even the best tree ring records rarely go below annual resolution, and many sediment cores represent decades per centimeter. You cannot resolve individual events—volcanic eruptions, El Niño cycles, droughts—with anything close to the precision of instrumental records. You're working in averages and trends, not specifics. Models also struggle with abrupt changes. The Last Glacial Maximum is relatively straightforward to model because the boundary conditions are stable and extreme. But periods of rapid transition—like the Younger Dryas or the Paleocene-Eocene Thermal Maximum—are where most reconstructions and models diverge significantly. The physics of fast feedback loops, especially around ice sheets and methane clathrates, aren't fully captured in standard GCM setups. If your target period involves rapid climate shifts, treat the results as directional estimates at best. There's no free software package that handles all of this end-to-end. Most people chain together R packages like pdQ or climdistr for statistical calibration, then export to PMIP-compliant formats for model runs in CESM or MPI-ESM. The workflow is fragile. A single mismatch in date alignment or unit conversion between the proxy data and the model input can silently corrupt your entire reconstruction without any error message. I've lost days to this twice. Double-check your date grids. Always.
Getting Started Without Wasting Time
Start with the PAGES 2k network datasets if you need a reference. They're publicly available, well-curated, and the metadata is detailed enough that you can trace exactly how each proxy was processed. From there, pick a region and a time period where the proxy coverage is densest. Don't reach for the hard problems first. Build a reconstruction for the last 200 years in a well-sampled area, verify it against the instrumental record, and only then push further back or into data-sparse regions. The learning curve is steep but manageable if you accept that uncertainty is the product, not a bug. Every number you produce comes with a confidence interval, and the interval is usually wider than you expect. That's not a failure of your method. That's the data telling you what it actually knows.