What You Actually Need in a Cloud Native Stack
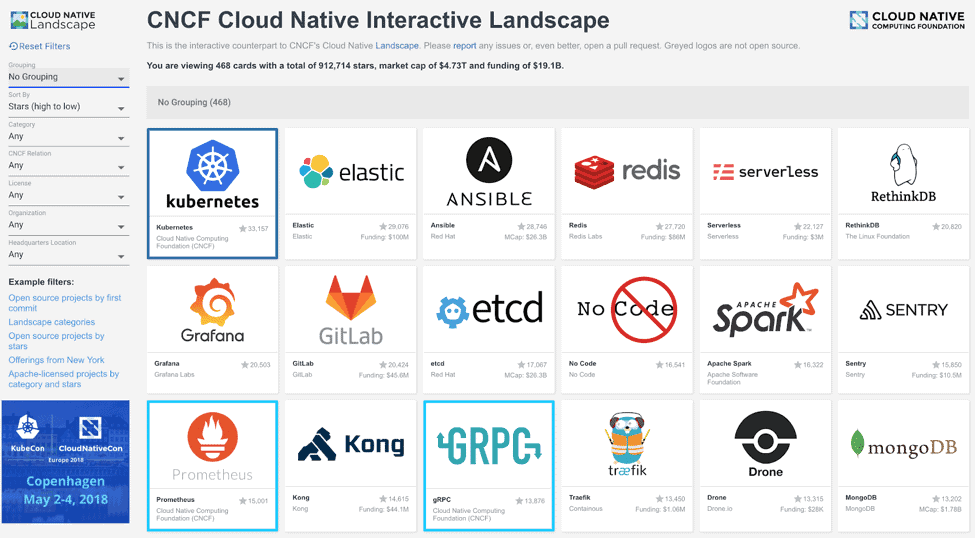
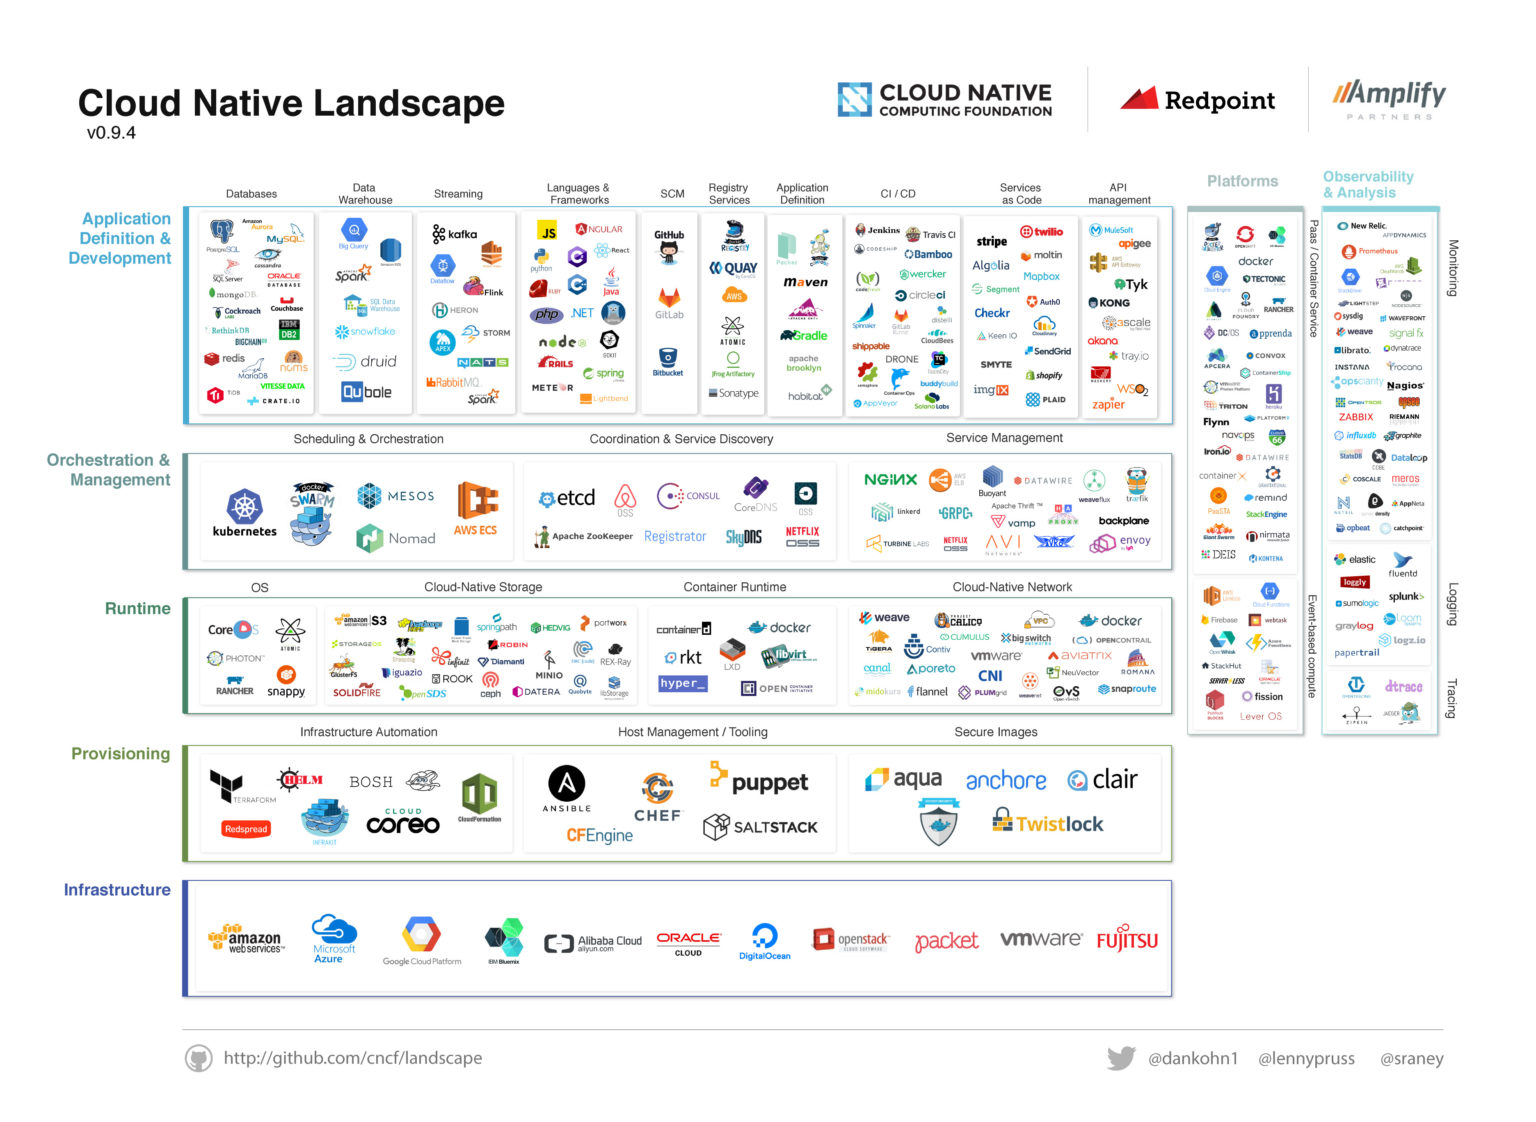
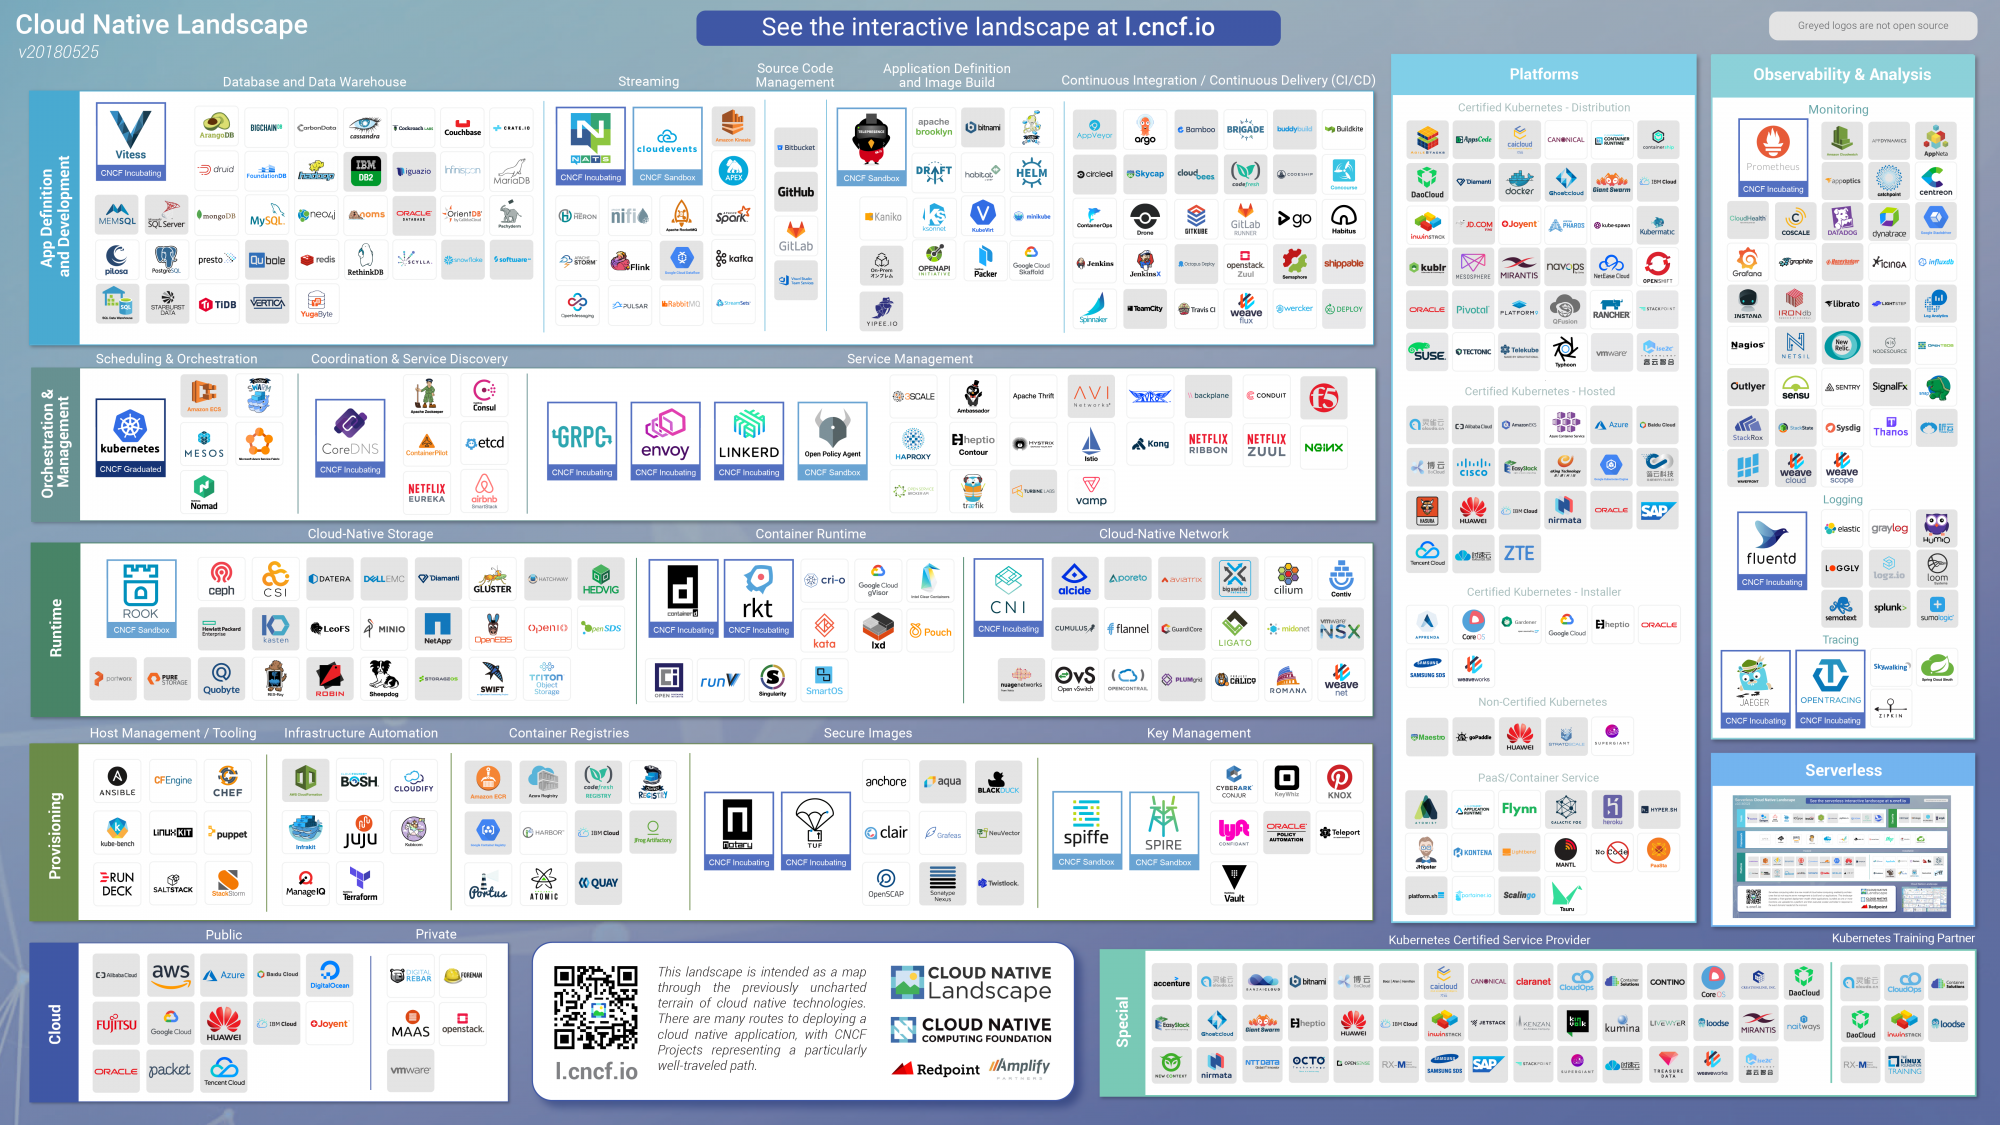
I spent about eight months trying to build out a proper inventory of cloud native technologies for a mid-size fintech migration. What I ended up with wasn't some grand unified list. It was a spreadsheet with five columns, half-empty rows, and a lot of notes about which tools we threw out and why. If you're looking for something similar, here's how I approached it. The CNCF maintains an official project landscape, but it's useless as a quick reference. It's a maze. The projects are organized by maturity tier — graduated, incubating, sandbox — and even that doesn't tell you whether a tool is actually production-ready for your workload. I stopped using their site as a decision document and started using it as a catalog of what exists. Then I built my own list based on actual deployment experience. Here's the one I landed on, broken down by layer:
Container runtime and orchestration: Kubernetes (obviously), containerd as the underlying runtime, and Docker for local development. We ran containerd directly in production and dropped Docker entirely after six months. The difference in resource overhead was measurable but small — roughly 120MB less RSS across a cluster of 40 nodes. Worth noting if you're counting. Service mesh: Istio and Linkerd. We evaluated both in 2023. Linkerd shipped in two weeks. Istio took six and still had a config that broke our prod deploy on a Tuesday. I'm not saying Linkerd is better — it is for most teams. But if you need fine-grained traffic management with complex routing rules, Istio has more moving parts that you can pull. Most teams don't need those parts. CI/CD: GitHub Actions, Argo CD, and Flagger. GitOps became non-negotiable once we hit 30+ microservices. Argo CD caught drift before we did. That alone prevented three incidents in four months where someone had manually edited a configmap in prod and nobody noticed until alerts fired.
Observability: Prometheus, Grafana, Loki, and Jaeger. The Grafana stack used to mean just the first three. Adding Jaeger for distributed tracing was the piece that made debugging latency issues actually possible instead of guesswork. Without tracing, a slow response across five services is a black box. With it, you can see exactly which hop is eating your p99. Storage: Longhorn for block storage on K8s, MinIO for object storage in environments where S3 isn't available or costs are prohibitive. We ran MinIO internally for about a year before migrating to actual S3. It saved us maybe $4,000 a month in egress fees. The tradeoff was maintaining another thing that could break. Security: Falco for runtime security, Trivy for image scanning, OPA/Gatekeeper for policy enforcement. The thing nobody tells you about OPA is that writing the policies is harder than writing the code they protect. My team spent three weeks on a single admission policy that blocked deployments without required labels. It worked eventually. The policy language (Rego) is not intuitive.
Get the Full Details

Databases and messaging: This is where the list gets messy. PostgreSQL via Bitnami Helm charts, Redis for caching, NATS for lightweight messaging, and Kafka when you actually need the throughput. We ran Kafka for about eight months and then replaced it with NATS JetStream because we had maybe 40 messages per second and were paying for a system that could handle 40,000. Overkill isn't a metaphor in cloud native — it's a line item on your bill. I ran into a specific problem with our Istio setup that I still think about. We had a canary deployment rolling out a new version of our auth service. The Istio VirtualService was configured to route 10% of traffic to the new pods. It looked correct. It was correct. The issue was that the connection pool on the existing pods wasn't draining properly because of how we'd configured the sidecar proxy's exit codes. The old pods kept accepting connections even as we scaled them down, which meant the new pods were handling 10% of requests but also getting retry storms from the old ones that hadn't fully disconnected. I spent a day tracking it down. The fix was setting terminationGracePeriodSeconds to 60 on the old deployment and adding a preStop hook that waited for the proxy to confirm no active connections before SIGTERM. Two lines of config. A whole day of head-desking. Here's something most guides don't cover: most cloud native tooling assumes you have horizontal scaling as a given. But if your application has stateful sessions or database locks that don't shard well, throwing more pods at the problem doesn't help. You'll just get more pods contending for the same resources. I've seen teams add six replicas to a service that was bottlenecked on a single PostgreSQL connection pool and wonder why latency got worse. It did, because the pool was already saturated and six more clients just made it choke harder. The answer wasn't more compute. It was connection pooling with PgBouncer and a query rewrite that eliminated a N+1 problem. The infrastructure fix was wrong. The application fix was right.
Another counter-intuitive thing: newer isn't always better in the CNCF ecosystem. The graduated projects tend to be stable because they've survived years of production abuse. The incubating ones are where the interesting stuff is, but they're also where things break in ways that aren't documented yet. We picked Cilium over Calico for our CNI after reading benchmarks that showed better performance under load. That was six months ago. Cilium has been solid. But when we upgraded from 1.12 to 1.14, there was a kernel module mismatch that took our staging cluster down for four hours. Calico wouldn't have done that. It's boring. Boring is reliable. The downsides of building your own cloud native stack from these components are real. You're responsible for upgrades. You're responsible for security patches across every layer. You're responsible for knowing when Prometheus needs more retention and what happens when it runs out of disk. The managed alternatives — EKS, GKE, AKS — exist for a reason. They handle the control plane. They still leave you managing everything else, but that's less surface area than doing it all yourself. If you're starting from zero and your goal is just to get something running, start with a managed Kubernetes offering and fill in the gaps. If you're managing your own cluster, invest in GitOps early. The cost of setting up Argo CD or Flux on day one is maybe two days of work. The cost of doing it after you've accumulated configuration drift across twenty services is a weekend you won't get back.
The CNCF landscape page at landscape.cncf.io is still the best place to browse what's available, even if it's not practical for decision-making. Use it to discover tools. Use your own experience to decide which ones to keep.