The messy reality of segmenting customers with cluster analysis
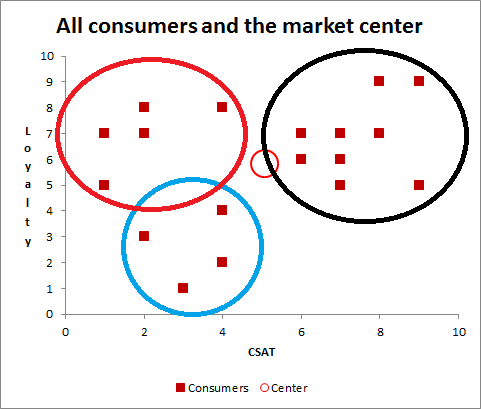
Most companies pile transaction history, demographics, and behavioral logs into a data warehouse and call it research. Then they wonder why their marketing teams are guessing. The actual work starts when you decide to group those rows into meaningful clusters, which is where Cluster Analysis For Market Segmentation becomes both the most useful and most abused technique in the business intelligence toolkit. Clustering takes your dataset and finds natural groupings without you telling it how many groups should exist. K-means is the default algorithm because it is fast and easy to interpret, but hierarchical clustering shows the dendrogram so you can see relationships at multiple resolution levels, and DBSCAN catches irregular shapes that K-means will flatten into garbage. The output is a label you assign to every record: cluster zero, cluster one, cluster two, and so on. After that, you stop letting the math do the heavy lifting and start doing the part where humans figure out what those labels mean. Start by cleaning the features that matter. Remove columns with ninety percent missing values, cap extreme outliers at the ninety-ninth percentile rather than deleting them outright, and standardize every numeric column with Z-score normalization. Without standardization, a feature measured in dollars will dominate distance calculations over a feature measured in seconds, even if the dollar feature is less predictive. If your data contains categorical variables, use one-hot encoding for low-cardinality fields and target encoding for high-cardinality fields with careful cross-validation to avoid leakage.
Scale selection changes everything. I once ran a clustering job on a retail dataset using raw purchase amounts alongside customer tenure. The algorithm produced five clusters, but cluster two was entirely made up of customers who had only ever made a single large purchase. It was not a behavior segment; it was a data artifact. I fixed it by log-transforming the purchase amount and re-running with Z-score scaling, which redistributed the influence so that tenure and recency could compete fairly with spend. The new solution split into three interpretable clusters within twenty minutes instead of requiring another round of manual feature engineering. Dimensionality reduction is not always necessary, but PCA is worth running before clustering when you have more than fifteen features. It removes noise and correlation that distort distance metrics. I typically keep components that explain at least eighty-five percent of variance and check the scree plot to confirm there is no long tail of near-zero eigenvalues, which would signal that the extra components are just fitting noise.
Picking the right number of clusters without guessing
The elbow method is the starting point, not the ending point. Plot the within-cluster sum of squares against cluster count and look for the bend. That bend is approximate, and your business constraints will usually reject whatever the plot suggests. The silhouette score adds a layer of validation by measuring how similar each point is to its own cluster compared to the nearest neighboring cluster. A mean silhouette above zero point five is acceptable, above zero point seven is solid, and anything below zero point three means your clusters are barely distinguishable and you are overfitting. BIC and AIC from hierarchical or Gaussian mixture models give you a probabilistic alternative that penalizes complexity. I run all three methods in parallel and treat convergence as a signal rather than a decree. If the elbow suggests four clusters, silhouette peaks at three, and BIC favors five, the answer is almost never one of those numbers on its own. It is the overlap region where business interpretability and statistical quality meet. In practice, that usually lands between three and six segments for consumer datasets, which is a narrow band for a reason: most segmentation problems do not have a perfect answer.
Get the Full Details
From cluster labels to actionable market segments
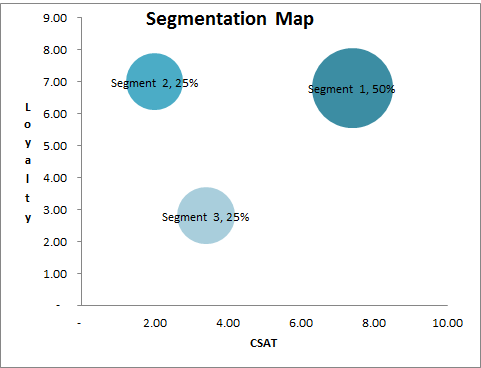
Labeling comes after clustering, not before. Describe each cluster on the original feature scale, not the standardized scale. A cluster with a mean age of three point two standard deviations above the mean means nothing until you convert it back to years. I build a quick reference table for every cluster: size, top three discriminating features, average transaction value, recency window, churn risk score, and a short descriptive name that a product manager can use in a meeting without needing a legend. Descriptive names like "high-value infrequent buyers" beat "cluster three" every time. Validation is where most people skip ahead and regret it. Hold out twenty percent of your data before training, run the clustering on the remaining eighty, and then predict cluster assignments for the holdout set using a simple nearest-centroid classifier. If the holdout distribution matches the training distribution closely, your model is stable. If it drifts, your clusters are brittle and likely sensitive to sampling variation. I also run a stability check by re-clustering with different random seeds and comparing cluster overlap with adjusted index values. Anything below zero point six suggests the solution is not reliable.
Cluster Analysis For Market Segmentation in production
Deployment is simpler than the theory makes it sound. Once you lock the centroid coordinates, feature preprocessing steps, and scaling parameters, you package them as a single pipeline. New customer records flow through the same imputation, scaling, and dimensionality reduction steps, then get assigned to the nearest centroid. Refresh the centroids quarterly or whenever cohort sizes shift enough to change the distance landscape. I refresh monthly for fast-moving e-commerce data and quarterly for slower B2B accounts, but the rule of thumb is to re-cluster when any single cluster grows or shrinks by more than fifteen percent over two consecutive periods. The tooling is standard. Python with scikit-learn handles the baseline work: KMeans, HierarchicalClustering, DBSCAN, Pipeline, and make_pipeline for reproducible preprocessing. For larger datasets, MiniBatchKMeans cuts runtime roughly in half without meaningfully changing cluster quality. R users can go with factoextra and cluster for visualization and silhouette computation. I typically write a single script that outputs a CSV with cluster assignments, a summary table, and a plot of the first two PCA components colored by cluster, then hand that to the marketing team with a one-page annotation explaining the practical implication of each segment.
Where this method breaks and what to do instead
K-means assumes spherical clusters and equal variance, which is rarely true for real customer data. If your silhouette plot shows a sharp drop after two clusters but the elbow keeps bending at higher counts, your data has elongated or overlapping groups that K-means will mis-handle. Switch to Gaussian mixture modeling with full covariance matrices. It adds computational cost but captures elliptical shapes and soft assignments where a customer genuinely belongs to multiple segments. Soft clustering is better than forcing a hard label on an ambiguous account. Another common failure mode is temporal mismatch. Customer behavior changes faster than your clustering refresh cycle. I learned this the hard way on a subscription service where the holiday season reshaped spending patterns for a quarter. A clustering model built on steady-state data labeled a segment as "low-engagement at-risk," but those were simply customers who delayed purchases during a known seasonal dip. The fix was to segment by behavioral window relative to purchase cycles rather than raw calendar dates, and to retrain the model after each major season rather than assuming annual refresh was sufficient. Causal inference is another gap. Clustering describes who behaves similarly, not why. If your goal is to test whether a price change moves a specific segment, clustering alone will not tell you. Pair it with uplift modeling or a controlled experiment after you have the segments in place. Clustering is a mapping tool, not a decision engine.
High-dimensional sparse data, such as clickstreams or event logs, does not work well with standard Euclidean distance. The curse of dimensionality makes all points equidistant from each other, which breaks K-means entirely. Use dimensionality reduction with UMAP or autoencoders before clustering, or switch to algorithms designed for sparse spaces like spectral clustering. I prefer UMAP because it preserves local structure better than PCA for behavioral data, and it runs fast enough to iterate on interactively.
A practical checklist that actually matters
Before you run anything, define what a segment should represent in business terms. Do you need actionability, measurability, stability, and sufficient size? A cluster of one hundred high-value customers might be statistically clean but useless if your ad platform cannot target it efficiently. Enforce a minimum cluster size rule, usually five percent of the total population, and merge any smaller clusters into the nearest neighbor cluster rather than discarding them as noise. Document the preprocessing pipeline explicitly. Standardization parameters, imputation strategy, outlier handling, and dimensionality reduction components must be stored alongside the centroids. A model without its preprocessing state is not reproducible, and non-reproducible segmentation is a liability, not an asset. I store everything in a versioned config file and log the pipeline hash next to each model artifact so that any stale report can be traced back to the exact data slice and parameter set that produced it. Finally, validate clusters with someone who knows the business, not just someone who knows the math. A statistician might approve a five-cluster solution with good silhouette scores, but a sales lead will spot that one cluster mixes two very different buyer types that require different messaging. Cross-check cluster profiles against known customer journeys and real account attributes. If the segments do not align with how your operations actually work, adjust the features or the algorithm rather than forcing the business to adapt to the clusters.


