Prepping for a COBOL Interview at This Point in Your Career
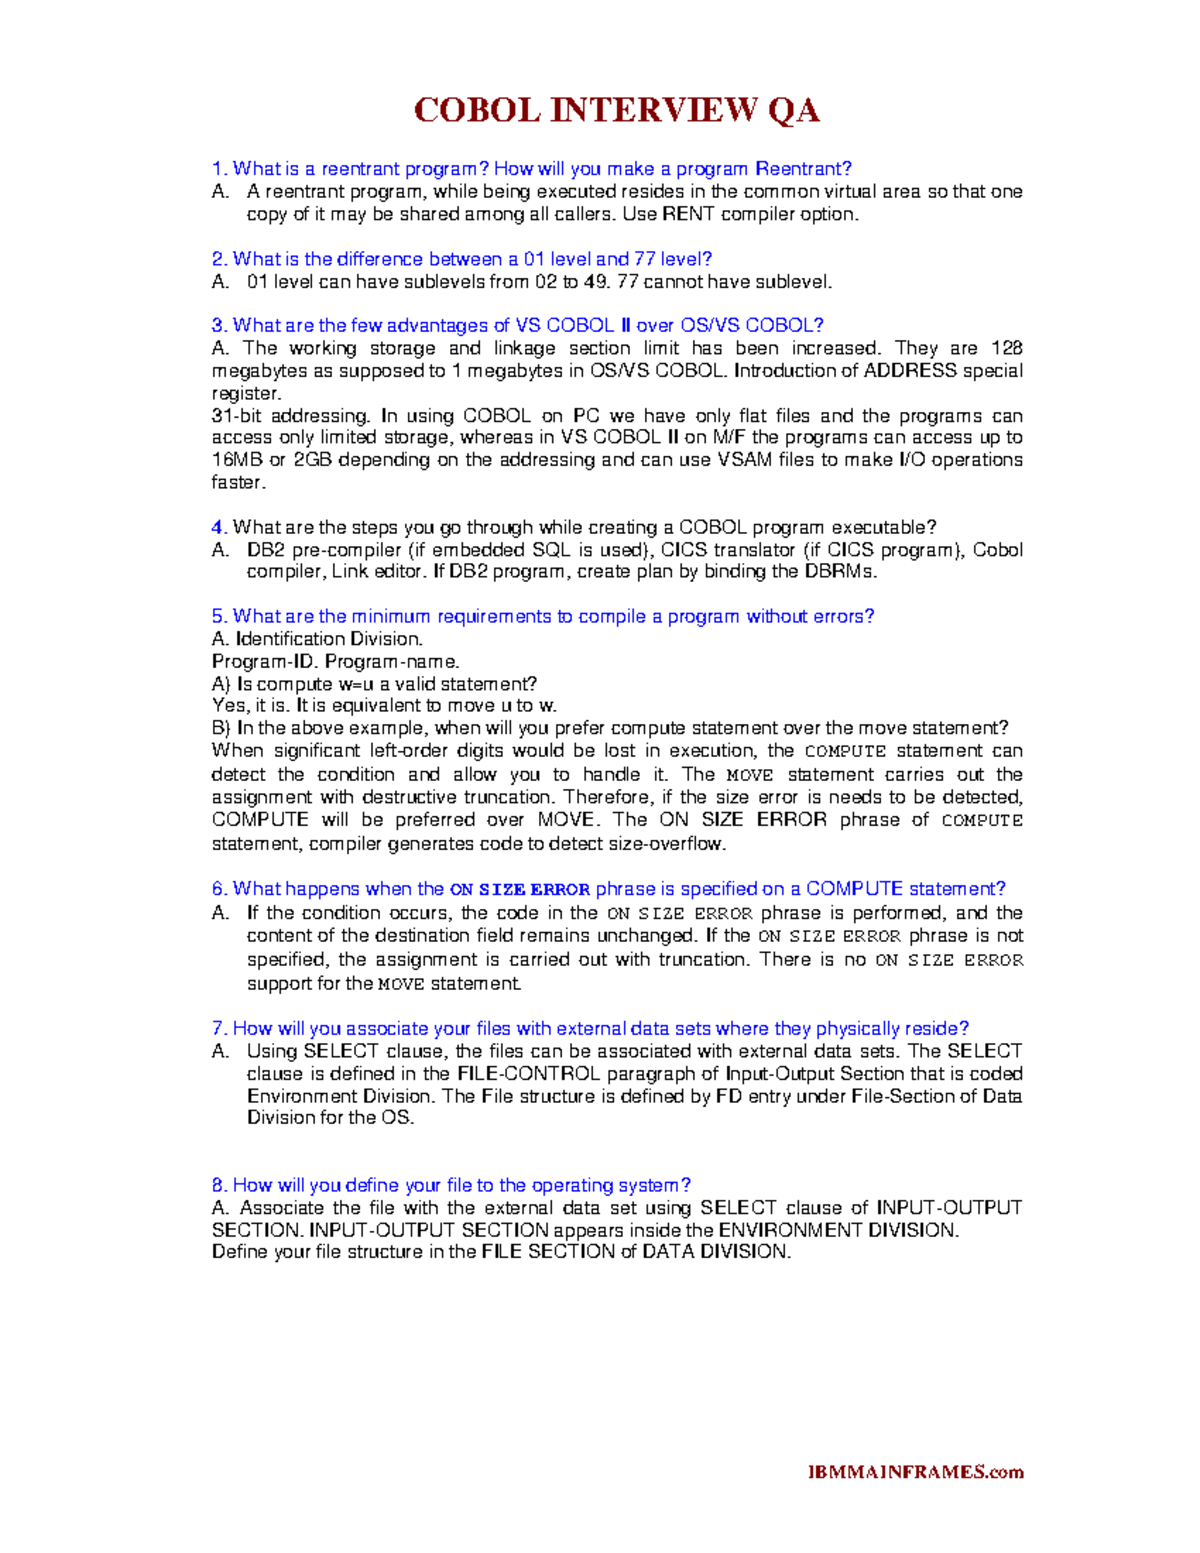
You spend enough time maintaining legacy batch systems and the interviews start coming. They're usually from banking, insurance, or government contractors who need someone who can read old code without needing a history degree. The questions aren't particularly hard if you've actually done the work, but they'll dig into areas that newer developers never encounter. I've sat on both sides of these tables, so here's what shows up repeatedly. The first category is always file handling and record processing. They want to know you understand the difference between SEQUENTIAL, RANDOM, and ISAM access modes and when each one breaks your application. Here's the thing most candidates gloss over: they'll ask about relative vs. sequential files and expect you to explain why relative files cause problems during reorganization. I once worked a production issue where a bank's nightly batch job locked a relative file for 14 hours because someone had switched the access mode from random to sequential without updating the JCL. The workaround was straightforward — restore the correct REEL parameter in the DD statement and set up a maintenance window — but the lesson stuck. You need to know how FILE STATUS works at the micro level. FILE STATUS(05) doesn't just mean "success." It's divided into categories: 00 is normal completion, 10 is end-of-file on read, 35 is a duplicate key error on WRITE, and 92 is a shared resource lock. When an interviewer asks "what does FILE STATUS 35 mean?" and you say "a duplicate," they'll press you on whether it's a fixed-length or variable-length file problem. The answer depends on the organization. That's the detail that separates people who've debugged production from people who've read a textbook. NEXT LEVEL questions move into SORT/MERGE statements and how they actually work under the hood. Most people can write a basic SORT BY field ASCENDING statement. Fewer can explain merge vs. sort, or when to use both. A MERGE requires already-sorted input files. If you feed unsorted data into a MERGE, the output is meaningless and FILE STATUS won't even flag it as an error — it'll just give you garbage. I learned this the hard way during a migration project where the source system's sorting was borderline correct. Numbers were sorted as alphanumeric instead of numeric. The SORT step passed cleanly, the merge produced results, and the downstream report came back with totals that were off by millions. Took three days to trace it back to the sort key definition. The fix was adding NUMERIC to the sort field in the SORT FIELDS parameter. Never skip that check.
Another area that comes up constantly is DATA DIVISION structure, specifically USAGE clauses. DISPLAY, COMP, COMP-3, and COMP-5. They'll ask why you'd choose COMP-3 over DISPLAY even though it takes more coding effort. The answer is storage efficiency for large-scale financial applications. COMP-3 packs two decimal digits into one byte using BCD representation. A COMP-3 field defined as PIC S9(7)V99 consumes only 5 bytes instead of 9. At scale in a mainframe environment, that matters for both I/O performance and storage costs. But here's the nuance nobody mentions: COMP-3 arithmetic is slower than COMP-2 floating point on certain mainframe architectures. If you're doing heavy mathematical operations inside a loop, COMP-2 or even COMP might outperform COMP-3 despite the larger storage footprint. I've seen COBOL programs optimized by switching a frequently-used interest calculation field from COMP-3 to COMP and cutting runtime by nearly 20 percent on a batch run that processed 40 million records. EXEC SQL and embedded SQL is another major topic. They'll test whether you understand cursor handling, especially the difference between HOLD and NO HOLD cursors and what happens to a cursor when a COMMIT occurs. A cursor declared with HOLD remains open across COMMIT statements. Without it, the cursor closes and you lose your position in the result set. This is critical for programs that process large result sets in chunks. I've seen candidates confidently explain embedded SQL theory but completely freeze when asked about the interaction between COBOL condition names and SQLCODE values. SQLCODE 100 means no more rows. SQLCODE 0 means success. Negative values indicate errors. But the real test is knowing that some SQL states don't map cleanly to COBOL condition names and you have to check SQLCODE manually in those cases. Linkage section and copybook usage comes up with surprising frequency. They'll show you a snippet where a program uses CALL with a linkage pointer and ask what happens if the called program modifies a field that the calling program considers read-only. The answer is straightforward — COBOL passes by reference by default, so any modification is visible to both programs. But they'll follow up with a question about USING vs. passing-by-value, which requires the VALUE clause in the CALL statement. It's a small detail but it reveals whether someone has actually written multi-program maintenance workflows.
There's also the debugging question that catches people off guard. They'll ask what tools you use and how you approach a production COBOL program that's producing incorrect output. The expected answer involves checking FILE STATUS, reviewing SORT output, examining data moved between sections, and validating external dependencies. But the real answer is about systematic isolation. Find the earliest point where the data is correct, then trace forward. In my experience, roughly 60 percent of production COBOL bugs originate from either misaligned copybooks or implicit truncation during MOVE operations. A MOVE of a larger alphanumeric field into a smaller one doesn't raise an error — it just silently drops characters. If you're moving a date field formatted as YYYYMMDD into a field defined as PIC X(6), you'll get YYYYMM with no warning at all. They may also ask about version differences and what changed between COBOL 85 and COBOL 2002 or later standards. Free format versus fixed format. The introduction of inline PERFORM. New string manipulation functions. These questions matter less for someone maintaining existing code and more for anyone expected to do modernization work. If you're applying to a shop doing mainframe-to-cloud migration, expect questions about what parts of legacy COBOL don't translate cleanly to modern environments. Period statements and implicit loops are the usual suspects. The hardest questions tend to be scenario-based. They'll describe a situation where a nightly batch job that used to complete in two hours is now taking eight, and ask what you'd investigate. This is where experience shows. You check CPU time versus elapsed time. You look at SORT work files and intermediate dataset sizes. You review whether the database access patterns changed. You examine whether file organization is still optimal after years of updates. One concrete example: a client had a routine that suddenly slowed down because a new index had been added to the database for a different application. The COBOL program's SELECT statement was doing an implicit dynamic SQL prepare on every execution instead of using a static plan. The optimizer chose a different access path because of the new index. We fixed it by binding a package and using static SQL with an explicit PLAN. Runtime dropped from 8 hours to 90 minutes.
Get the Full Details
Don't sleep on questions about program structure and control flow either. They might ask you to explain the relationship between paragraphs, sections, and sentences, or when it makes sense to use EXIT PARAGRAPH versus STOP RUN. STOP RUN terminates the entire program and all nested calls. EXIT PARAGRAPH just exits the current paragraph and returns control. Confusing the two in a deeply nested call structure can cause cascading issues that are difficult to trace in older debuggers. Finally, be ready to discuss what you don't know. There are edge cases in COBOL — oddities around alphabetical order conventions, the behavior of the UNSTRING statement with delimiters, or how INSPECT reformats operate on different character sets — that even seasoned developers encounter infrequently. Saying "I haven't worked with that specific feature" is better than fabricating an answer. These interviewers have been doing this for decades and they'll know immediately if you're bluffing.