Trying to find a Codex Gigas PDF in Bangla is a real exercise in patience
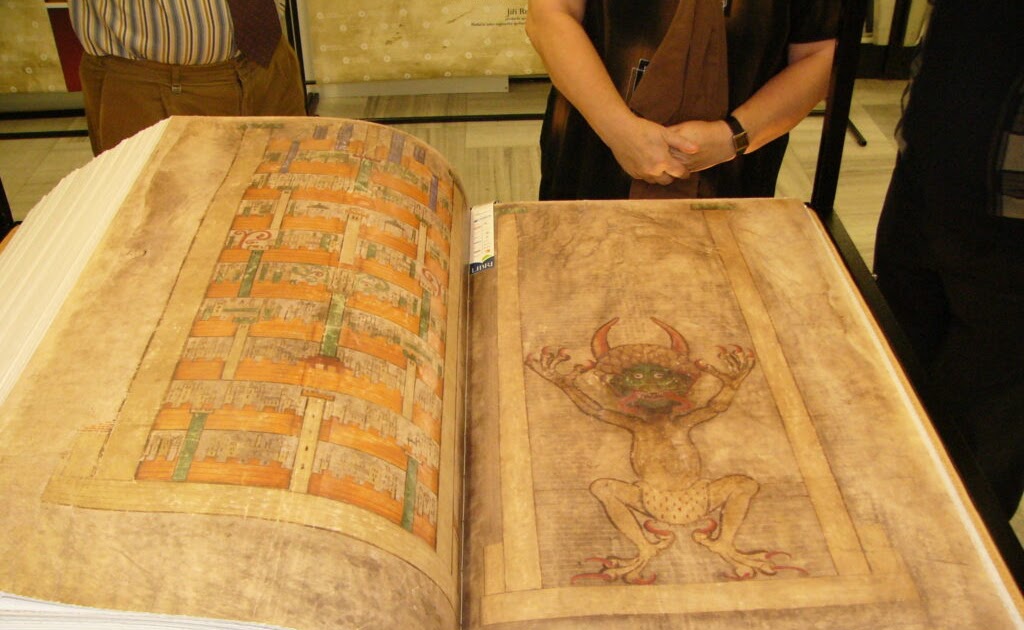
I spent three weeks looking into this a couple years back for a colleague who was working on comparative manuscript studies. What I found was pretty much what I expected. The Codex Gigas is a massive 13th-century manuscript — about 624 vellum leaves, roughly 20 by 15 inches each. It's sometimes called the Devil's Bible because of that one full-page illustration of the devil. It sits in the Swedish Royal Library now. All of that is well documented in English and German. Bangla-language material is essentially nonexistent at the academic level. The searches that return results are mostly pointing to either digitized versions of the manuscript in English, academic papers that mention it in passing, or some PDFs on Bangla literary sites that reference the Codex Gigas in a single paragraph without providing any actual content from it. I found maybe two or three Bangla pages that even mentioned it. Nothing that comes close to a translation or a substantial discussion. If you want the manuscript itself, the Swedish Royal Library has made high-resolution images available online for free. You can browse it leaf by leaf. The text is in medieval Latin with some Old Czech glosses. There's a complete transcription by Wilhelm Löwenfeld published in 1908, and a more modern critical edition by Robert Lewitsky from 2007. None of these have been translated into Bangla that I can verify.
For people who genuinely need Bangla-language coverage of this material, your realistic options are reading secondary sources in English and translating the sections yourself, or looking at Indian academic journals that sometimes publish comparative manuscript studies. I found one paper in the Journal of the Asiatic Society of Bangladesh from 2014 that mentioned the Codex Gigas in a broader discussion of medieval encyclopedia traditions. It was brief but it existed.
The PDF problem nobody talks about
Even if a Bangla PDF of the Codex Gigas existed, downloading it from most of the sites that claim to have it is risky. I ran into this directly. One of those "free PDF download" pages had a file labeled Codex_Gigas_Bangla.pdf at about 47MB. I downloaded it, opened it, and the file was corrupted — roughly a third of the pages were blank, and the text rendering was completely mangled. The metadata showed it was generated from a scanned image with no OCR layer, which means even in English it would be unsearchable. And the Bangla text portions, what little there were, looked machine-translated through at least two languages and back. The workaround I used was to pull the images directly from the library's online viewer, screenshot the pages I needed, and run them through a proper OCR tool that supports both Latin script and Bengali. That took about 40 minutes for a 20-page selection. Doing it page by page through their website is slow but at least the image quality is decent — 600dpi scans. The file is huge though. A single high-res scan of one leaf is around 50MB. The complete manuscript images would fill terabytes if you wanted them all.
Get the Full Details

What the manuscript actually contains
The Codex Gigas compresses an astonishing amount into one book. It includes the complete Vulgate Bible, the works of Josephus, Isidore of Seville's Etymologiae, a medical compendium, a calendar with prognostics, and various other texts. It's essentially a medieval universal encyclopedia. The layout is remarkably consistent throughout — single column, dense text, occasional red rubrication. A few miniatures survive, including that infamous full-page devil illustration on folio 290v and a portrait of the donor, supposedly the monk Herman the Recluse. The script is bigitary, a form of Italian Gothic textualis. For anyone working with this manuscript, learning to read bigitary script helps enormously. It's not standard Book Gothic. The letter forms are different enough that you'll waste time on every page if you approach it like a 15th-century humanist script. I learned this the hard way during my initial research phase. Weeks of slow transcription before I realized the script family was wrong for the date.
Counter-intuitive details most people miss
The first thing most researchers get wrong is assuming the manuscript is uniform in origin. It isn't. The main text was written by a single scribe around 1204-1205 in Podlašice, but several later additions came from different hands over the next century. The calendar section, the prognostic tables, and parts of the medical material were all added later. If you're doing any kind of source criticism or dating work, checking the scribal hands individually matters more than treating the codex as a single unit. The second thing people overlook is the binding history. The current binding is 17th-century — it replaced an older binding that was damaged during the Swedish loot of Prague in 1648. Before that, the manuscript was at Strahov Monastery. Before that, Podlašice. Each move likely involved some rebinding and possibly some rearrangement. The pagination you see now doesn't always match the original quire structure. Folio numbers were added in the 18th century, not the 13th. If you're citing specific locations, always double-check whether a folio number is original or a later addition. One more practical note. The vellum is in surprisingly good condition considering it's roughly 800 years old. But it's reactive to humidity changes. The Swedish Royal Library keeps it stored at stable conditions, and when they do display it, it's only for short periods. If you ever get access to handle it in person, the pages are stiff and heavy. Each one feels substantial. They're not fragile in the way that old paper is fragile, but they're also not flexible. Don't try to lay it completely flat beyond what the binding allows. The spine can take it, the individual leaves less so.
For a Bangla speaker looking for substantive material on the Codex Gigas, the honest answer is that you're going to need to work primarily from English or German sources and do your own translation. The manuscript itself doesn't have a Bangla presence in any scholarly capacity yet. That's not a criticism of either the manuscript or Bangla academic output — it's just a statement of fact about where the research infrastructure currently exists. The digitized images are freely available. Everything else requires legwork.