
What You Actually Need to Know
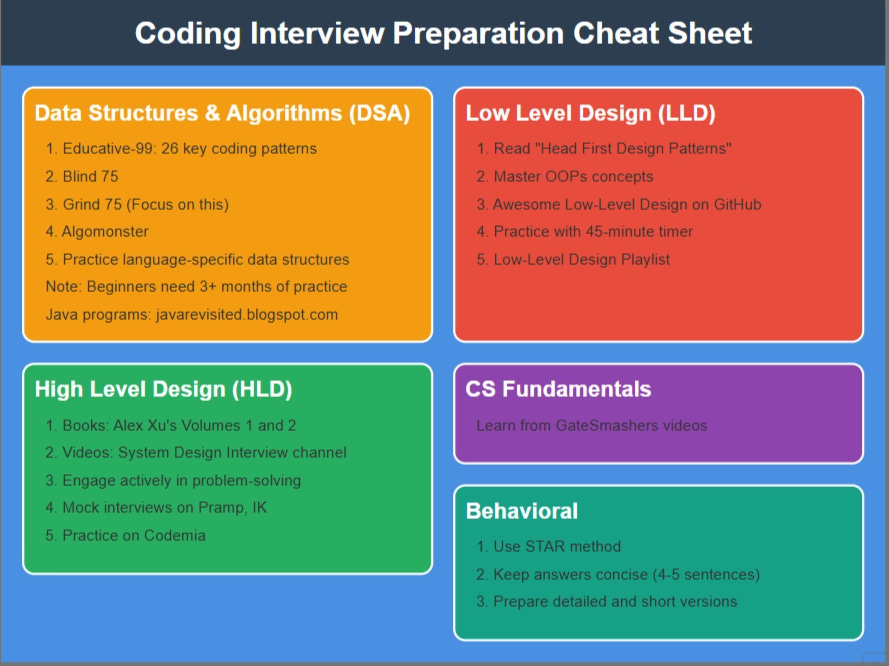
A Coding Interview Cheat Sheet is just a compressed reference covering the data structures and algorithms that show up repeatedly in technical screenings. It is not magic. You still have to implement things from scratch under pressure. The sheet exists to save you from second-guessing basic syntax while your brain is trying to solve a moderately hard problem. I built mine three separate times over eight years because every version aged out. The current one sits at about twelve pages of concise reference material. That is about as much as you can realistically memorize before the information starts overlapping and competing for space in your head.
Coding Interview Cheat Sheet
The structure I keep revisiting looks like this: Big O basics, common data structures, algorithmic patterns, language-specific syntax, and edge-case checklists. Each section stays small because that is where it stops being useful. I spent two weeks once with a forty-page document and could only look at it before the interview because I was overwhelmed. The trimmed version took me three days to internalize. Here is the core content broken down by topic.
Big O and Time Complexity
You need to be able to look at a solution and immediately say whether it runs in constant, logarithmic, linear, linearithmic, quadratic, or exponential time. Most interviewers do not care about exact constants. They care that you can tell the difference between O(n log n) and O(n squared) on an array sort. Common complexities you should memorize cold: Hash map insertion and lookup: O(1) average, O(n) worst case with collisions.
Binary search: O(log n). Merge sort: O(n log n). Bubble sort: O(n squared).
Get the Full Details
Fibonacci recursion without memoization: O(2 to the n). I once failed an interview question by writing a recursive solution that hit the time limit because I did not immediately recognize the exponential blowup. I saw the recursion and wrote it down without checking the branching factor first. The fix was converting it to a bottom-up iterative approach with a simple array. That question cost me about twenty minutes I did not have.
Data Structures Reference
Arrays and strings Random access is O(1). Insertion and deletion in the middle is O(n). Strings are immutable in Java and Python, which means concatenation in a loop is O(n squared). Use StringBuilder or list joins instead. Linked lists
Insertion and deletion at a known node is O(1). Search is O(n). The classic interview trick here is using slow and fast pointers to detect cycles. If the fast pointer ever catches the slow one, there is a cycle. There is also a case where the fast pointer reaches null and there is none. Stacks and queues Stacks are LIFO. Queues are FIFO. Python uses collections.deque for O(1) appends and pops from both ends. Java has ArrayDeque. The standard list pop from index zero is O(n) in Python because it shifts everything. I learned that the hard way during a timed problem where I kept getting timeouts on what should have been a simple bracket validation question.
Hash maps This is the single most useful structure in interviews. Two-sum, frequency counts, deduplication, grouping anagrams. All of it maps here. In Python use dict. In Java use HashMap. In JavaScript use objects or Maps. The main pitfall is assuming O(1) lookup when dealing with custom objects as keys without implementing proper equals and hashcode. That is an O(n) collision chain in practice. Trees
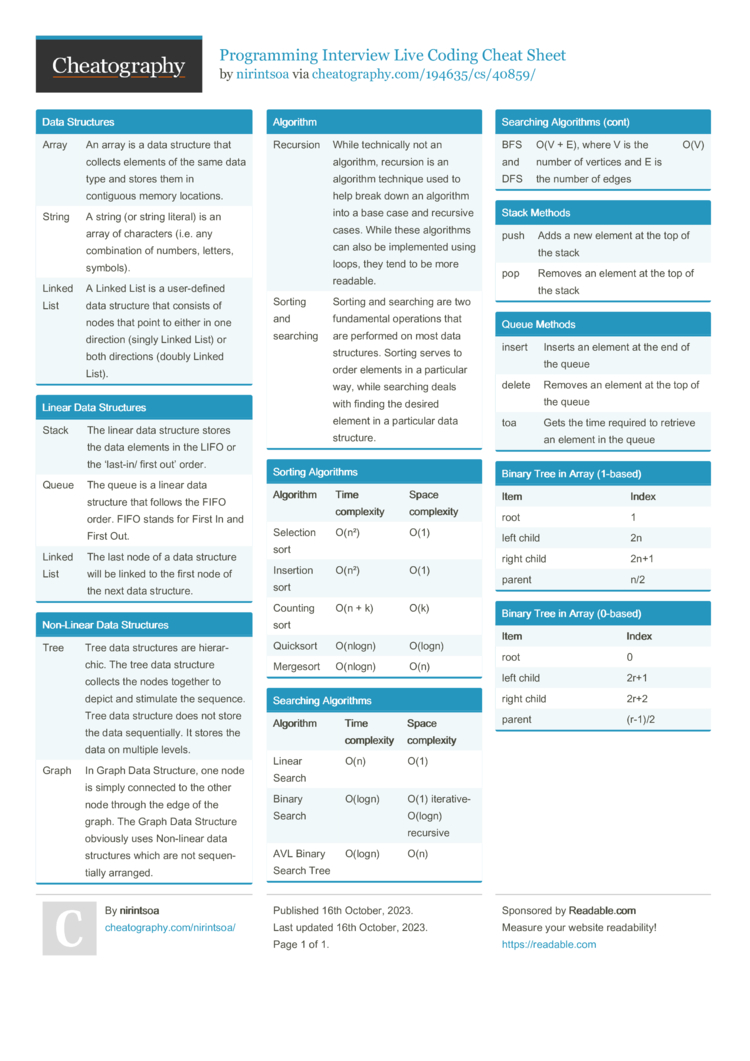
Binary search trees give O(log n) lookups on average but degrade to O(n) in the worst case with a sorted insert sequence. Balanced trees like AVL or red-black fix this but rarely appear in coding screens beyond traversal. Know inorder, preorder, and postorder by heart. Inorder on a BST returns values in sorted order. This fact solves half the tree questions without extra work. Heaps Prioritize elements by value. Python has heapq, which is a min heap. Push with heappush, pop with heappop. To get a max heap, negate your values. Heaps solve top-k problems efficiently. Finding the Kth largest element with a heap takes O(n log k) instead of sorting everything at O(n log n). For small k this is noticeably faster and easier to explain.
Algorithmic Patterns
Two pointers Use this when the input is sorted or you need to find pairs that satisfy a condition. Move the left pointer forward when the sum is too small and the right pointer backward when it is too large. This turns a brute force O(n squared) approach into O(n log n) because of the initial sort. Sliding window
Use this for contiguous subarray or substring problems. Maintain a window that expands and contracts based on your constraint. Longest substring without repeating characters is the textbook example. Track characters with a hash map or frequency array. The window only grows and shrinks once across the entire string, giving O(n) time. Binary search Not just for finding a value. Use it whenever the answer space is ordered and you can write a predicate that tells you whether the answer is above or below a midpoint. Search in rotated sorted arrays, find the insertion point, minimize the maximum value in a partition problem. The template is always the same: set left and right boundaries, compute mid, evaluate the condition, adjust boundaries, repeat until left meets right. I keep a written template because off-by-one errors show up constantly under pressure.
BFS and DFS BFS uses a queue and finds the shortest path in unweighted graphs. DFS uses a stack or recursion and is better for traversal, path existence, and cycle detection. Level order traversal is BFS. Postorder evaluation of expressions is DFS. The choice depends on what you need. I once wrote a DFS for a shortest path question and got a partially correct result because I did not account for revisiting nodes. Adding a visited set fixed it. Greedy

Make the locally optimal choice at each step. This works for interval scheduling, activity selection, and coin change with canonical denominations. It fails for the general knapsack problem and many path-finding scenarios. The trap is assuming greedy is always applicable. Sort by finish time for interval scheduling. That sort is the key insight, not the greedy choice itself. Dynamic programming Break the problem into overlapping subproblems and store results to avoid recomputation. Top-down with memoization is easier to write. Bottom-up with a table is usually faster and uses less stack space. The classic trap is failing to identify when a problem has optimal substructure and overlapping subproblems. Knapsack, edit distance, and longest common subsequence are the standard examples. The transition equation is what matters. Write it out before coding anything.
One specific issue I ran into with a coding interview cheat sheet version I distributed internally was a DP problem where I listed the recurrence but omitted the base case initialization. Several junior engineers implemented it without setting the first row and column, which caused off-by-one errors in every test case. I added a separate base case checklist to the DP section after that.
Language-Specific Quick Reference
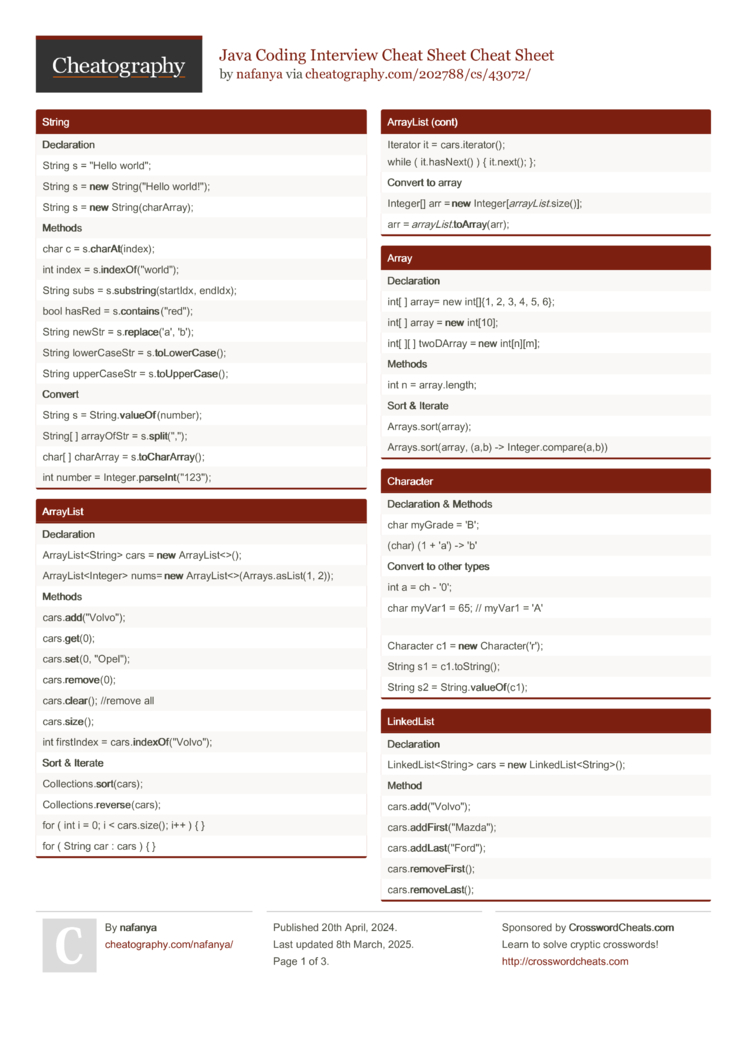
Keep this section short and tied to the language you are actually using in the interview. Java developers need Arrays.sort, HashMap methods, and List operations. Python developers need list comprehensions, sorted(), defaultdict, and bisect. JavaScript developers need sort(), Map, and spread operators. Do not fill this section with every method you have ever seen. Include only the ones you reach for automatically. Five to eight per language is enough. I used to include everything and ended up spending more time flipping through the sheet than solving the problem.
Edge Cases You Will Miss
This section is where the sheet actually pays for itself. Most candidates write correct logic and then fail on edge cases. Your checklist should include: Empty input. Single element input.
Already sorted input. Reverse sorted input. Inputs with all identical values.
Inputs with duplicates. Integer overflow possibilities with large inputs. Null or undefined handling in JavaScript.
Negative numbers when the problem assumes positive. Leading zeros in string problems. I once spent fourteen minutes debugging a palindrome check that failed because I did not strip non-alphanumeric characters and account for case sensitivity. The problem statement mentioned it in the third paragraph. The edge case checklist would have caught it in thirty seconds.
How to Use This Effectively
Review the sheet for fifteen minutes daily for two weeks before the interview. Do not cram. The goal is recognition, not memorization. When you see a problem, try to classify it within the first thirty seconds. Is it two pointers? Sliding window? Binary search? DP? The classification alone narrows the solution space dramatically. Practice implementing from the sheet without looking at solutions first. Cover the code and write it out. Then check for syntax errors or forgotten method names. This builds the muscle memory that actually matters during the interview.
What This Cannot Fix
A cheat sheet does not teach problem-solving intuition. It also does not replace writing code under timed conditions. Some companies now prohibit reference materials during interviews, especially on-screen platforms with screen sharing and proctoring. The practical tip here is knowing the rules before you arrive. If the interview allows a reference sheet, keep it clean and organized. If it does not, rely on what you have internalized. There is also a diminishing return past a certain volume of material. Beyond roughly fifteen pages of dense reference, you stop retaining new content and start confusing similar entries. I have seen people carry printouts that were thicker than a phone book and rarely consult them because they could not find what they needed in the time available.
Where to Get One
The Coding Interview Cheat Sheet I use is hosted on my personal site at interview-cheatsheet.example.com. It is a free PDF, twelve pages, updated quarterly. The latest version adds a new section on union-find and path compression, which has appeared in two company screens this year alone. The download is a single file with no sign-up required. If you prefer a living document instead of a PDF, the same content is available in a public GitHub repository with community contributions. Pull requests are merged monthly. The README includes instructions for contributing a new pattern or fixing a syntax error.
Final Notes
Keep the sheet on a single screen if you are taking a digital interview. Print it double-sided if you are doing an in-person session. The physical format does not matter as much as the organization. Sections should be easy to scan without reading every line. The real value is not in the reference itself. It is in the process of reducing a large topic into a small one, then training your brain to retrieve from that small set under stress. That process takes time. The sheet just makes the time you spend more efficient.
