Understanding the translation process
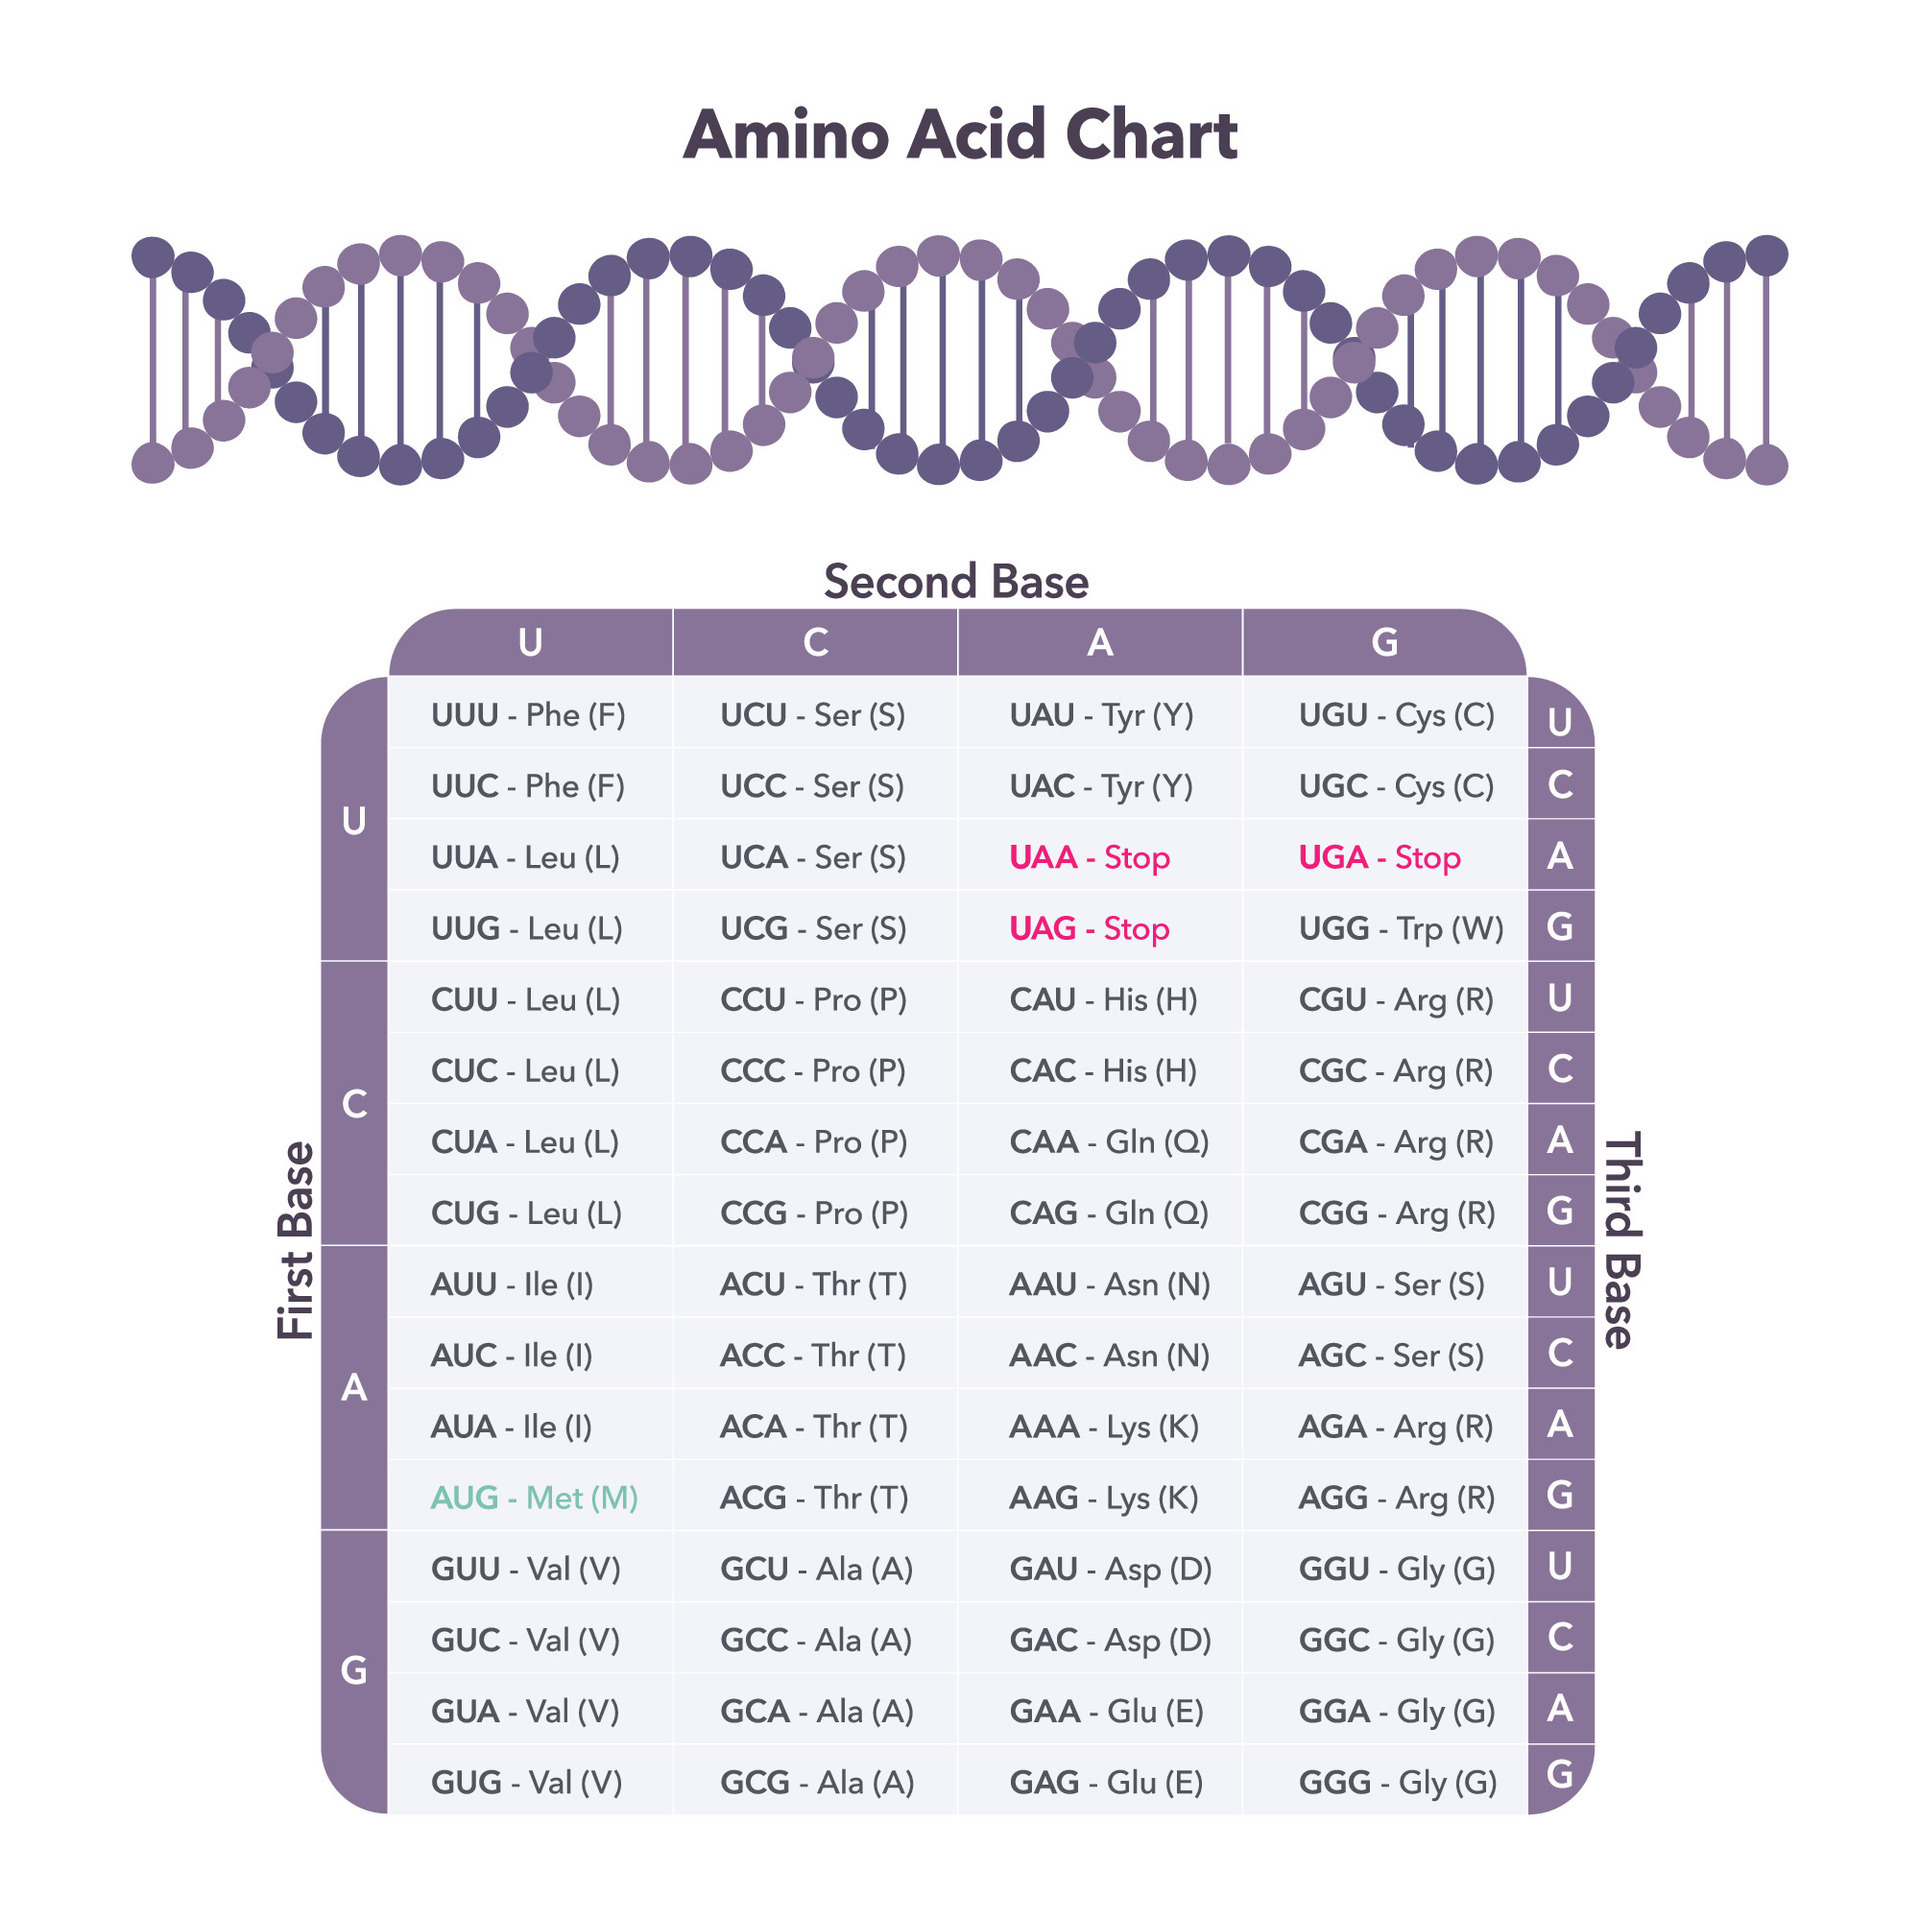
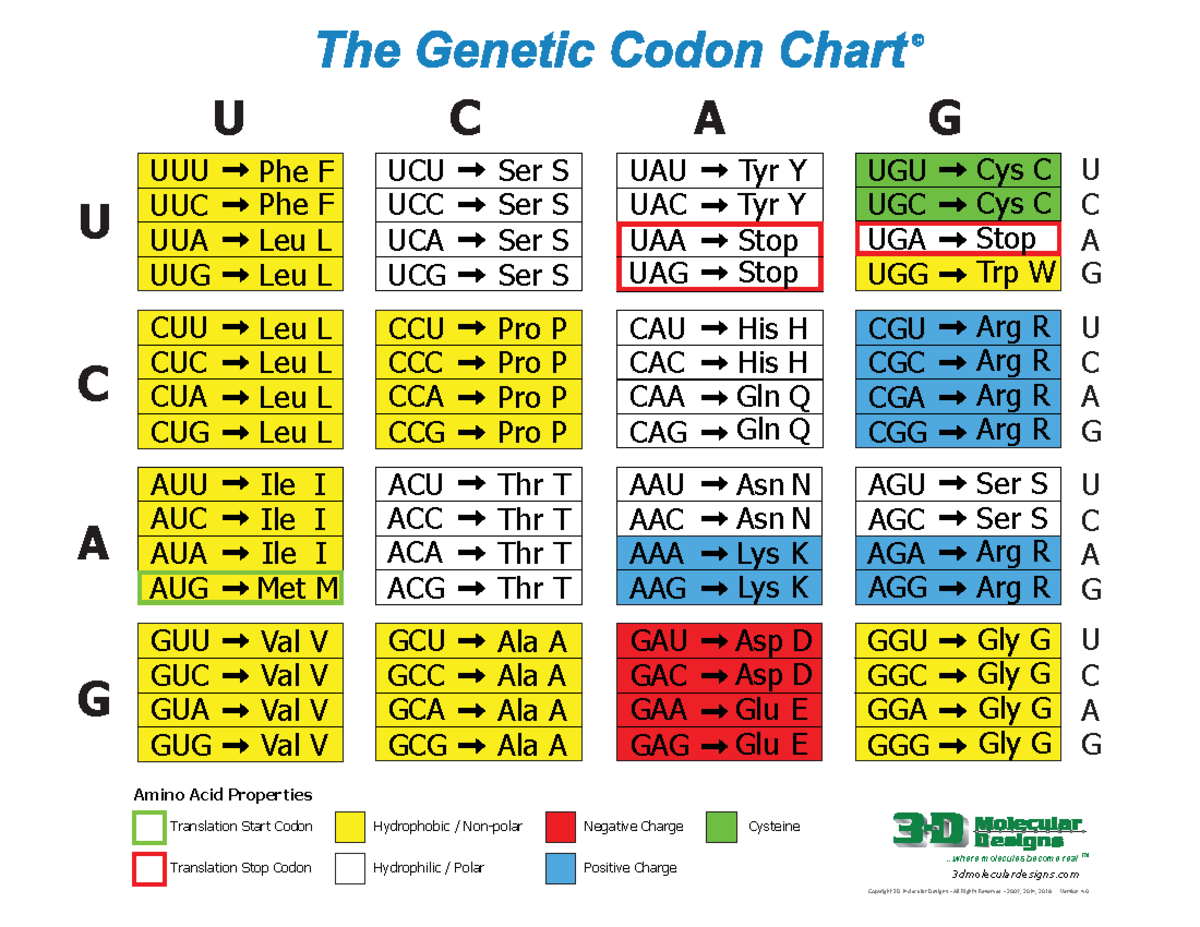
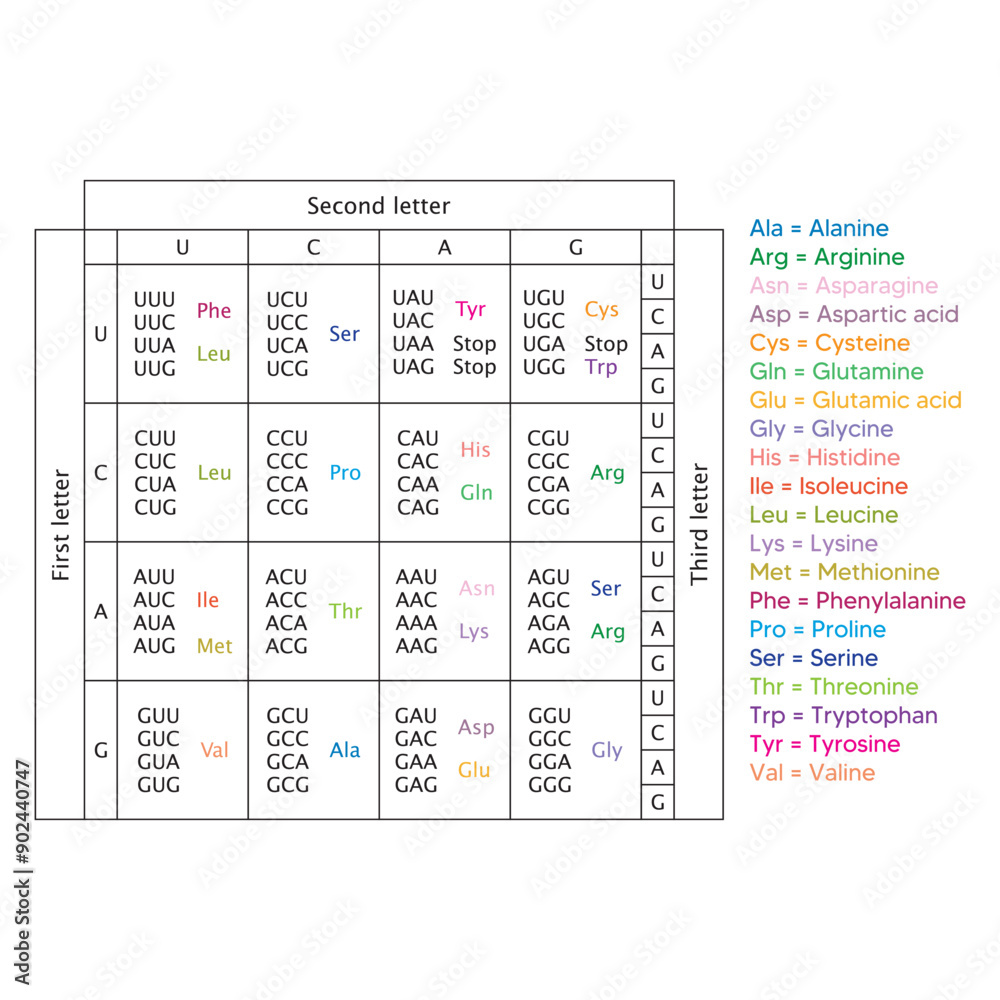
The codon table maps 64 three-nucleotide sequences to 20 amino acids plus stop signals. Every coding strand of DNA or RNA gets read in non-overlapping triplets, and each triplet corresponds to a specific residue or a termination command. It is a lookup problem, not something that requires derivation. You feed it a sequence and it tells you what protein comes out. Here is how I actually do it in practice. Write or paste your nucleotide sequence. Make sure it is oriented 5-prime to 3-prime, because reading frame depends entirely on that direction. Then chunk it into triplets starting from the first base. Do not shift the frame partway through unless you have a reason, because that is how you get completely wrong results. Map each triplet using the standard genetic code, or whatever variant applies to your organism. I will get to variants in a moment. I work mostly with Sanger-confirmed constructs and synthetic gene blocks. Once, I ran a codon-to-amino-acid translation on a plasmid I had ordered from a vendor. The sequence looked clean. The ORF came out right for about 400 bases and then suddenly shifted into a string of wrong residues. Turned out the vendor had introduced a single-nucleotide insertion in a homopolymer run, something like an extra A in an AAAAA stretch. Standard chromatogram inspection missed it because the peak looked reasonable. I caught it by printing the raw trace and looking at the fluorescence values directly. A peak height ratio of roughly 3:1 instead of the expected 2:1 for a clean single base told me exactly where the insertion sat. Fixed it with site-directed mutagenesis. Wasted about two weeks on it. After that, I never trust a homopolymer region without Sanger confirmation on both strands.
The standard table is what you will find in almost every textbook. It assigns codes like ATG to methionine, TTT and TTC to phenylalanine, and TAA, TAG, and TGA as stop codons. But the standard table is not universal. Mycoplasmal organisms read UGA as tryptophan instead of stop. Yeast mitochondria use CUN codons for threonine rather than leucine. Some ciliates repurpose stop codons into glutamine. If you are translating a sequence from an unconventional organism and you use the standard table, you will get a protein that does not exist. Always verify which genetic code table applies to your source organism before you proceed. A common pitfall that costs people a lot of time is forgetting to check the reading frame. If your sequence starts with an incomplete codon at the 5-prime end, you need to decide whether that is intentional. Leader sequences, Kozak contexts, and ribosome binding sites often sit upstream of the actual start codon. Translating from the wrong frame gives you nonsense amino acids until a stop codon appears, usually within the first 20 to 40 triplets. I count bases first. I confirm the ATG position. I then translate from that ATG in the correct frame. I never assume the first ATG is the real start without checking context and the expected protein length against the literature or the construct design. Another thing beginners miss is the difference between DNA and RNA tables. The DNA table uses T. The RNA table uses U. If you are working with mRNA sequences or running a tool that expects RNA input, feeding it DNA with thymine will confuse some parsers. The mapping itself is identical except for that one letter swap, but the format mismatch causes errors in automated pipelines more often than people realize. When I hand off sequences to collaborators, I label them explicitly as DNA or RNA and use the corresponding alphabet throughout.
Here is a straightforward example. Take the sequence ATGGCTGATCGTAG. Chunk it: ATG GCT GAT CGT AG. The first four triplets translate to methionine-alanine-aspartate-arginine. The trailing AG is incomplete, so it does not code for anything unless the next base arrives. The resulting peptide fragment is MADA. That is it. No drama, no hidden complexity. The complexity appears when sequences get long and you are dealing with multiple open reading frames, overlapping genes, or alternate splicing isoforms. For quick local work, I use a simple Python script with Biopython. The Seq object handles frame selection and stop codon reporting. It takes about ten seconds to translate a 3-kilobase sequence on my machine. If you want something without coding, online translators exist, but I do not put proprietary sequences into public tools anymore. The turnaround time is fast, but the data leaves your control. I keep everything local for anything I intend to publish or submit. The main limitation of manual or table-based translation is that it only works on complete, curated sequences. If your sequence contains ambiguous bases like N, R, Y, or gaps, the codon table cannot assign a single amino acid. You have to either mask those regions, run a degenerate translation that outputs ambiguity codes, or rewrite the sequence to resolve the unknowns first. I usually replace ambiguous positions with the most likely base based on the source organism's codon usage bias before translating. It is a judgment call, and it can be wrong, but it is better than getting a string of unknowns in your result.
Get the Full Details

Start codon selection is another area where people make mistakes. ATG is the default, but GTG and TTG can serve as start codons in bacteria and some other systems. They still code for methionine at the N-terminus after initiation, even though the internal codon would normally specify valine or leucine. If your translation tool only recognizes ATG as a start, you will miss real open reading frames. I adjust my search parameters to include alternative start codons when working with bacterial or organellar sequences. Stop codon readthrough is rare but real. Certain viral sequences and some engineered constructs contain stop codons that are suppressed by near-cognate tRNAs or recoding elements. A standard translation will show a truncated protein where the actual product is longer. If your observed protein runs larger than the predicted size on a gel, go back and check whether a stop codon might be being read through. I have seen this in expression constructs where a premature stop was bypassed by the host's translational machinery, giving a fusion protein that ran at the wrong molecular weight and confused the entire project for months. My workflow is simple and it has not changed much over the years. I get the sequence. I check the source and confirm the genetic code table. I verify the reading frame and the start codon. I translate. I sanity-check the output against the expected protein length and known domains. If anything looks wrong, I go back to the raw sequence and re-examine it. Most errors come from frame shifts, wrong tables, or unverified ambiguous bases. Fix those and the translation is usually correct within minutes.
There is no shortcut around checking your assumptions. The codon table itself is reliable. The problems almost always come from the sequence you put into it or the rules you apply to it. Pay attention to those two things and the rest is just lookup work.