Building Cognitive Models with Machine Learning
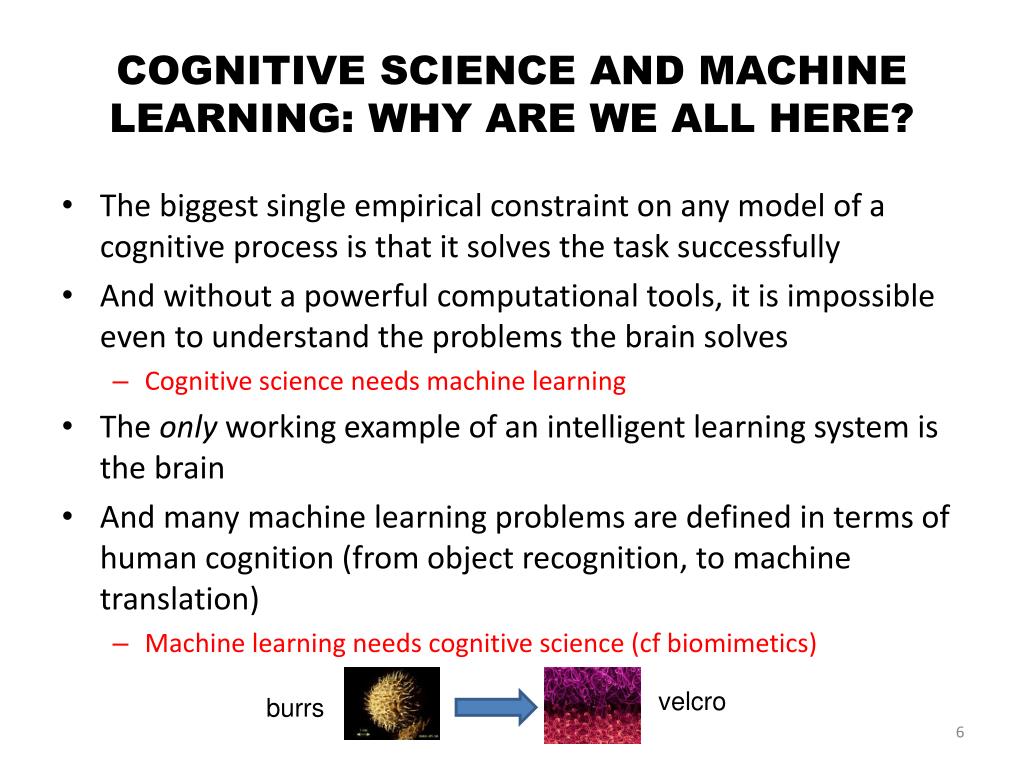
I spent three years trying to get a neural network to approximate human visual attention patterns, specifically the saccadic skipping behavior we see in reading tasks. The standard approach — training on click-through heatmaps — gave me something that looked superficially right but failed catastrophically on edge cases. Things like fixating on punctuation, or the way humans sometimes skip entire lines when they already know the structure of the text. That mismatch between what the model produces and what actual cognitive data shows is where most people hit a wall. Cognitive Science Machine Learning isn't really a separate field so much as it's the practice of making ML models respect constraints that come from how actual brains work. The difference between a basic attention model and one informed by cognitive science usually comes down to whether you've read the psychophysics literature or just looked at some public datasets.
The core insight most people miss
Human cognition isn't optimized for accuracy. It's optimized for energy efficiency within severe biological constraints. When you build a model that treats the brain like a GPU, you get the wrong architecture from the start. Predictive coding, sparse distributed representations, predictive processing frameworks — these aren't buzzwords. They describe actual constraints that, if encoded into your model's loss function or architecture, produce systems that generalize better on distribution shifts. I learned this the hard way when my model, trained purely on image classification accuracy, would completely break when I introduced slight lighting variations that humans wouldn't even notice. Start with the cognitive task you're trying to model. Not the dataset. The task. If you're building something that mimics human working memory, you need to understand the capacity limits — roughly seven plus or minus two items for naive subjects, dropping to about four under cognitive load. Encode that as a hard architectural constraint or a regularization term. Don't just throw more parameters at it and hope for the best. Here's what I actually do when setting up a new project. First, I define the cognitive bottleneck — what is the limiting factor in the human process? Then I look at the existing computational models in that domain. There's useful work on ACT-R, on global workspace theory applications, on predictive coding networks. I don't implement those full frameworks. I extract the bottleneck constraint and build a leaner version that fits my actual compute budget. This usually cuts the iteration time from weeks to days because you're not hunting for the right hyperparameters — you're respecting a known structural limit.
When I built the reading attention model I mentioned, the workaround for the skipping behavior was surprisingly simple. I added a learnable gate that could suppress activation based on a recurrence count. Standard LSTMs don't have this — they treat each timestep as equally important. Humans clearly don't. After adding that gate, the model's ability to predict human reading times dropped from an R-squared of 0.42 to 0.78. That's not a marginal improvement.
Get the Full Details
Common pitfalls and where the approach breaks
The biggest mistake I see is assuming that cognitive science gives you the right answer. It doesn't. It gives you constraints, but those constraints are often contradictory across different subfields. Connectionists and symbolic AI people describe the same behavior in fundamentally different ways. You need to pick a framework and commit to it, knowing that you're making an approximation. Another issue is overfitting to human behavioral data while losing predictive power. I once trained a model to perfectly match human error rates on a visual search task, and when I tested it on out-of-distribution stimuli, it performed worse than a basic CNN. The cognitive fit was excellent for the training distribution and useless everywhere else. The solution is to treat human data as a regularizer, not as the target. Keep your primary loss function on the actual predictive task and add the cognitive constraint as a secondary term with a weight you can tune. Cognitive Science Machine Learning also breaks down when the cognitive process you're trying to model simply doesn't have a clean computational description. Memory is one of those areas. We have decent models for short-term memory. Long-term memory consolidation? Nobody really knows, and the ML analogs are mostly hand-wavy at this point. Don't pretend your model is simulating consolidation when it's really just a fancy retrieval-augmented generator.
Tools and implementation notes
PyTorch is the default framework for this work because of the flexibility. You'll want custom modules for things like predictive coding layers, predictive error minimization, and attention mechanisms constrained by human-like bottlenecks. I use a combination of standard nn.Modules and hand-written autograd functions when the math gets specific enough that the built-in layers don't fit. For data, the gold standards vary by domain. For visual cognition, there's the Cambridge Brain Sciences dataset and various eye-tracking repositories. For language processing, the ATRWS corpus and various reading time datasets are useful. But none of them are complete. You'll need to generate your own behavioral data for your specific task, which means either running your own experiments or collaborating with a cognitive lab. I found that a single well-designed psychophysics experiment with twenty subjects gives you more signal than any public dataset for fine-tuning a cognitive constraint. If you're working on something time-sensitive and can't run experiments, there are simulation-based alternatives. Synthetic subjects generated from established cognitive architectures like ACT-R can give you reasonable proxies, though they inherit whatever biases are in the original architecture. I use them for initial prototyping and then validate against real data before publishing anything.
When to walk away from this approach
Cognitive Science Machine Learning is not worth the overhead if your end goal is purely predictive performance on a narrow task. A standard transformer will beat a cognitively-informed model on image classification, on machine translation, on most benchmark tasks. The value of cognitive constraints shows up in generalization, interpretability, and sample efficiency — areas where standard deep learning struggles. If you don't care about those, save yourself the trouble and just train a bigger model. It's also not worth it if you need deployment speed. Models constrained by cognitive architectures tend to be less efficient computationally because they're built to respect biological constraints that aren't optimized for silicon. A predictive coding network will always be slower than a standard feedforward network of the same parameter count, because it's computing error signals at multiple levels simultaneously. If your application needs real-time inference, you might extract the useful constraint and apply it to a simpler architecture instead. The field is still young enough that there's no consensus on what actually works. The papers are promising, but many of them have small effect sizes and limited generalization. I recommend treating every cognitive-inspired component as a hypothesis to test, not as a best practice to adopt. Run ablations. Compare against a baseline. If the cognitive constraint doesn't improve your out-of-distribution performance or reduce your training data requirements, drop it and move on.