Working With Col A Linear Algebra in Practice
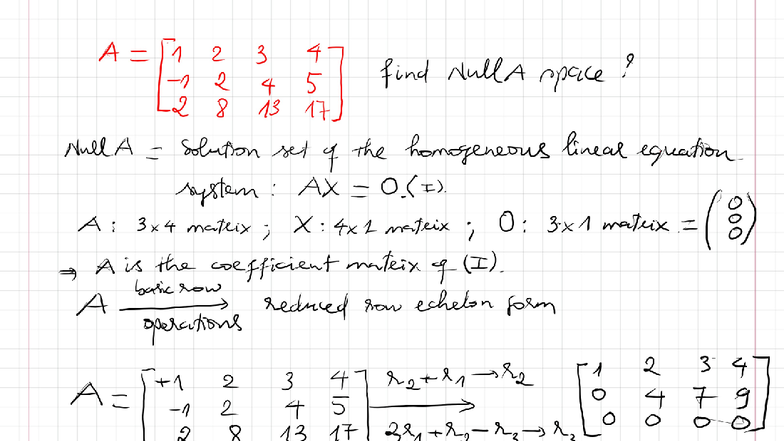
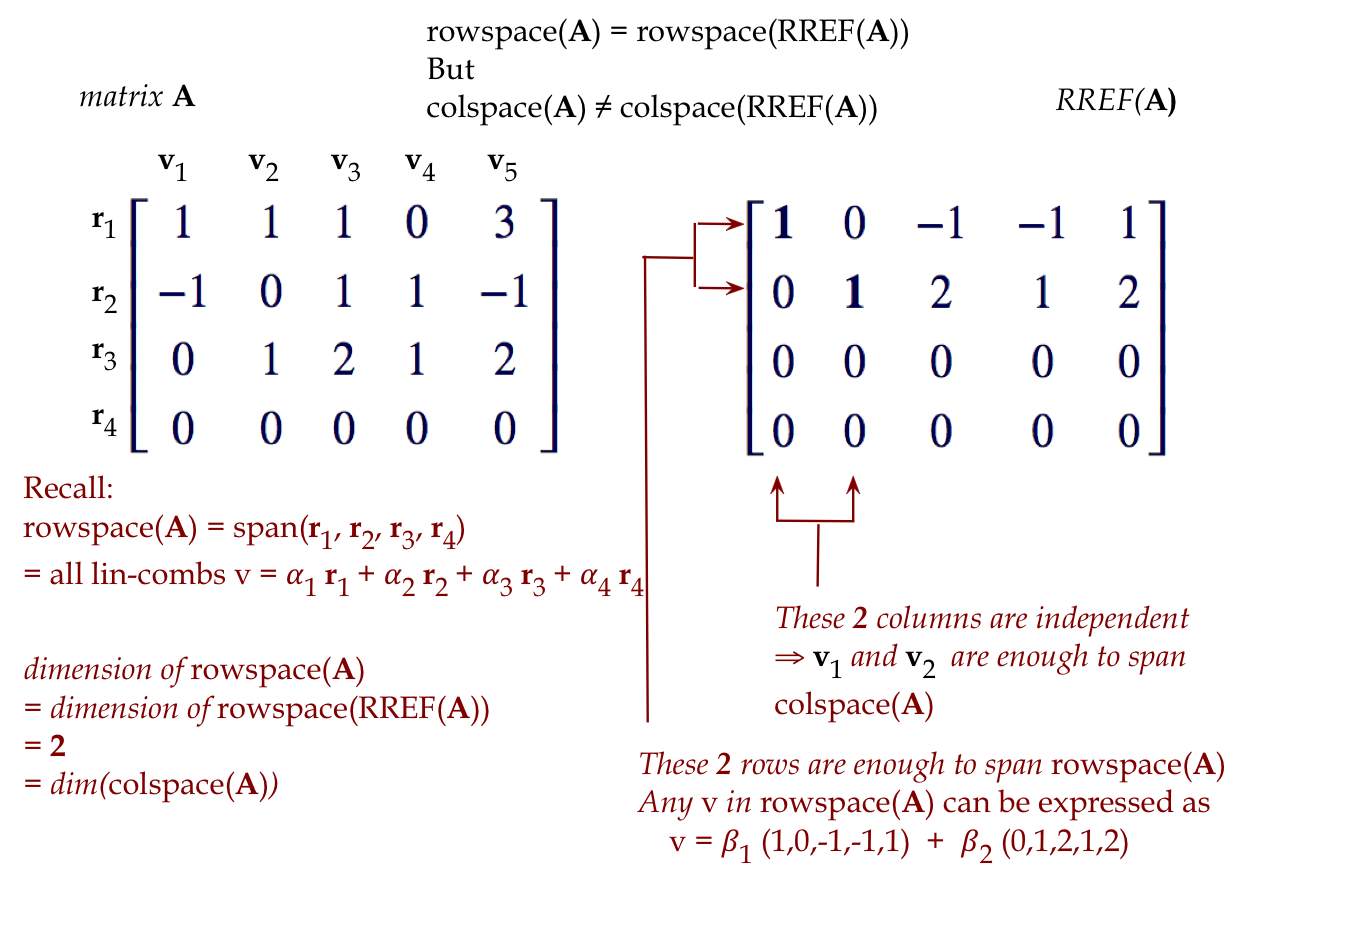
The column space of a matrix, often written as Col A, is the set of all possible linear combinations of the columns of A. If A is an m by n matrix, then Col A lives in R^m. That is the textbook definition. The part nobody tells you until they have already failed a midterm is how to actually compute it when the numbers are messy and you are working by hand or with limited tools. I got handed a 6 by 4 matrix last year with entries like 3.14, negative seven halves, and some repeated rows that looked clean until you checked the third column. The assignment was to find Col A and write it in terms of a basis. The straightforward route is row reduce to reduced row echelon form, pick the pivot columns from the original matrix, and call it a day. That works when the arithmetic cooperates. It did not cooperate in my case because I was doing this on a whiteboard during a meeting and kept losing track of fractions. So here is the method that actually works consistently. Take your matrix A. Perform Gaussian elimination to get to row echelon form, or go all the way to reduced row echelon form if you want extra clarity. Identify which columns contain pivots. Those are your key columns. Go back to the original matrix and extract those same columns. That subset is a basis for Col A. The dimension of Col A is the number of pivots, also called the rank of A. Do not use the pivot columns from the row-reduced matrix as your basis. That is a very common mistake. The row operations change the column space. They preserve the null space and rank, but they do not preserve Col A itself. Only the original columns corresponding to the pivot positions work.
Let me walk through a small example with actual numbers. Say A is a 3 by 3 matrix: Column one is 1, 2, 3.
Column two is 2, 4, 6.
Column three is 1, 0, 1. Row reduce the second row by subtracting twice the first row, and the third row by subtracting three times the first row. You will see that column two becomes zero. The pivot is in column one and column three. So the basis for Col A is the first and third columns of the original matrix: 1, 2, 3 and 1, 0, 1. The dimension is two. Column two was redundant because it is exactly twice column one. That is the whole thing in a clean case.
Where it gets tricky is when you have near-dependence. I worked with a dataset once where two columns were almost linearly dependent but not quite, and floating point rounding made the pivot detection ambiguous. The matrix was roughly 20 by 15 with values scaled differently across columns. Standard Gaussian elimination on that produced a basis that was numerically unstable and meaningless for any downstream application. The workaround was to use a QR decomposition with column pivoting instead of plain Gaussian elimination. That gave me a rank-revealing factorization and a stable basis for the column space. In practice it cut my debugging time from several hours down to maybe twenty minutes because I stopped second guessing whether a tiny pivot was real or just roundoff noise. Another thing that trips people up is the relationship between Col A and the row space. They live in different dimensions when A is not square. If A is m by n, then Col A is a subspace of R^m and the row space is a subspace of R^n. They share the same dimension because rank is rank, but they are completely different objects. Students mix them up constantly and then blame the professor for being unclear. The professor is not unclear. The students just need to keep track of which space they are actually in. If you are doing this computationally, most people reach for NumPy or MATLAB. The routine numpy.linalg.matrix_rank will give you the rank, but it uses a singular value decomposition under the hood and returns a floating point rank. That means you have to set a tolerance yourself. The default tolerance is machine epsilon times the largest singular value, which works fine for well-conditioned problems but fails for anything with moderate conditioning issues. I usually set the tolerance explicitly to something like 1e-10 when I know the data has been through some preprocessing. It is not a perfect fix but it prevents the algorithm from silently truncating a singular value that you actually need.
Get the Full Details

For extracting the actual basis columns, there is no single built-in function that just gives you the pivot columns from the original matrix in every library. In Python you typically compute the rank and pivot indices from an LU or QR factorization and then index into the original array. In MATLAB, [Q,R,P] = qr(A,'vector') gives you the pivot permutation directly, so you can grab the columns from A(:,P(1:r)) where r is the rank. This is more reliable than trying to read pivot positions out of a row-reduced matrix that has been mutated in place. Here is a practical tip that saves time: before you run any reduction, check whether your matrix has any obviously zero columns or obviously identical columns. Remove or consolidate those first. It does not change the column space, but it reduces the size of the problem and makes the arithmetic cleaner. I once spent forty minutes debugging a basis calculation only to realize two columns were literally the same. That should have been obvious from looking at the matrix for five seconds. One more edge case worth mentioning. If you are working with symbolic matrices, like in a proof or a homework problem with variables in the entries, the row reduction path depends on whether certain expressions are zero. You may need to consider multiple cases. This is where Col A Linear Algebra stops being a computation exercise and starts being an algebra exercise. I recommend splitting the problem into cases early rather than pretending a single reduction covers everything. It is messier on paper but it does not lead to false conclusions.
The column space is fundamental to understanding what a matrix can actually do. Every output of the linear transformation x mapped to Ax has to live in Col A. If your target vector is not in Col A, the system is inconsistent and there is no exact solution. That is why projecting onto Col A matters in least squares problems. The whole framework rests on knowing what Col A is and how to compute it reliably. If you want a quick reference sheet or a script to automate the basis extraction, you can find implementations online. Search for something like Col A Linear Algebra basis extraction script and you will find plenty of examples in Python and MATLAB. The logic is always the same: reduce, identify pivots, map back to original columns. Anything more complicated than that is either over-engineered or solving a different problem.