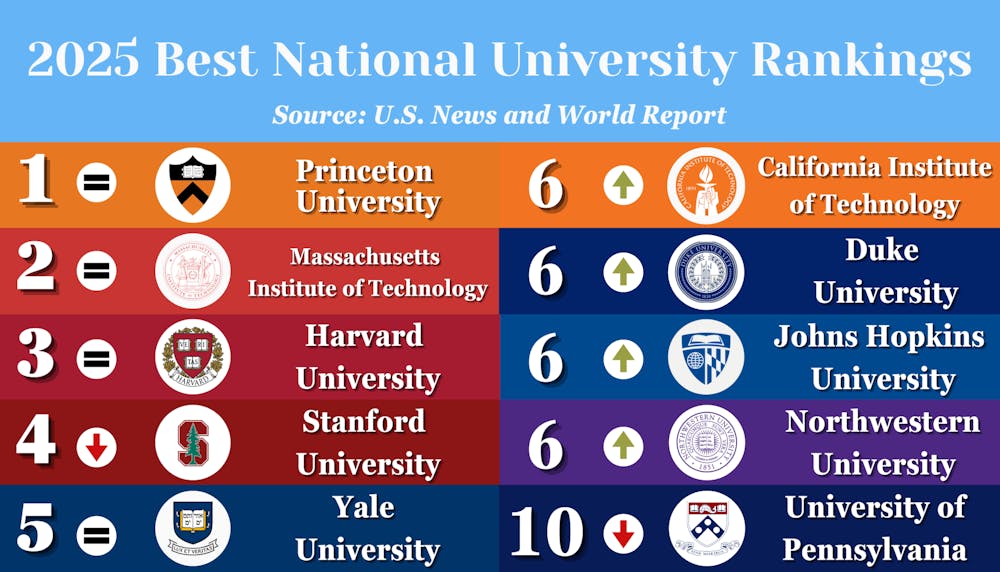
How College Rankings Actually Work (And Why You Shouldn't Trust Them Blindly)
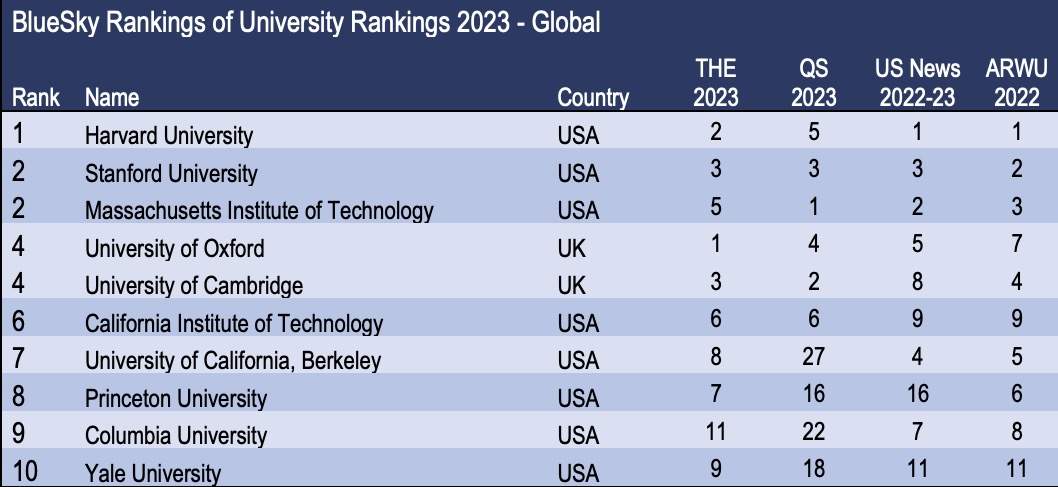
Most people treat rankings like gospel, which is unfortunate because the methodology is almost always opaque. When I first started helping students navigate this space around 2014, the process was significantly more manual than it is today. You pulled data from institutional reports, cross-referenced them with published metrics, and built spreadsheets that would make anyone's eyes glaze over within ten minutes. I spent roughly three weeks building a custom ranking model for a regional publication back then. That same process now takes about forty-five minutes if you know what you're doing. The fundamental problem is that rankings attempt to compress an enormously complex set of variables into a single ordinal position. A university isn't a product with standardized specs. Two schools with identical median SAT scores can have wildly different outcomes for their graduates depending on cohort composition, alumni giving patterns, and even how they define full-time enrollment. The rankings industry knows this, but the market demands a simple number, so they deliver one anyway.
The Mechanics Behind College Rankings
Every major ranking system uses a weighted scoring model. You pick variables, assign weights, normalize the data, and calculate a composite score. That's the entire algorithm in plain terms. The controversy sits entirely in the weighting decisions, which are rarely justified with peer-reviewed research. Take the most common framework. Graduation rate typically carries somewhere between 15 and 25 percent weight. First-year retention rate adds another 10 to 15 percent. Alumni giving rate is another 5 to 10 percent. Selectivity metrics like acceptance rate and standardized test ranges sit in the 15 to 20 percent bracket. Faculty resources, spending per student, and endowment metrics make up most of the remainder. Employment outcomes after graduation have been creeping upward in weight across several major publications over the last five years, though reliable data on this metric remains sparse. Normalization matters more than most people realize. When you're combining variables measured on completely different scales, you need a standardization step. Z-score normalization is the default approach in most academic settings. Min-max scaling appears more often in industry models because it's simpler to communicate to a general audience. Neither method is wrong, but they produce meaningfully different results when your dataset contains outliers. A school with an anomalously high alumni giving rate will inflate its position under min-max but get reined in under z-score. This distinction shifts rankings by anywhere from 3 to 15 spots depending on the publication's methodology.
The Data Sourcing Problem
Data quality is where most ranking projects fall apart. Institutional reported data is voluntary, inconsistent, and frequently outdated. The IPEDS database from the National Center for Education Statistics is the backbone for American higher education data, and it's also a nightmare to work with. Missing values, reporting lag, and definitional changes year over year mean you cannot just download and plug in raw data without cleaning. I built a pipeline that handles these gaps automatically, but it took roughly six months of iteration before it produced stable results across multiple academic years. The fix is straightforward in theory and painful in practice. You create a data validation layer that flags anomalies before they enter the scoring model. Duplicate rows, impossible values, and inconsistent reporting periods need automated detection. I use a combination of range checks and cross-validation against secondary sources like the College Scorecard and UNIRANK for verification. This validation step typically consumes 30 to 40 percent of the total project time on the first build, then drops to under 10 percent once the rules are solidified.
Get the Full Details
Weight Selection Is Where Reality Hits
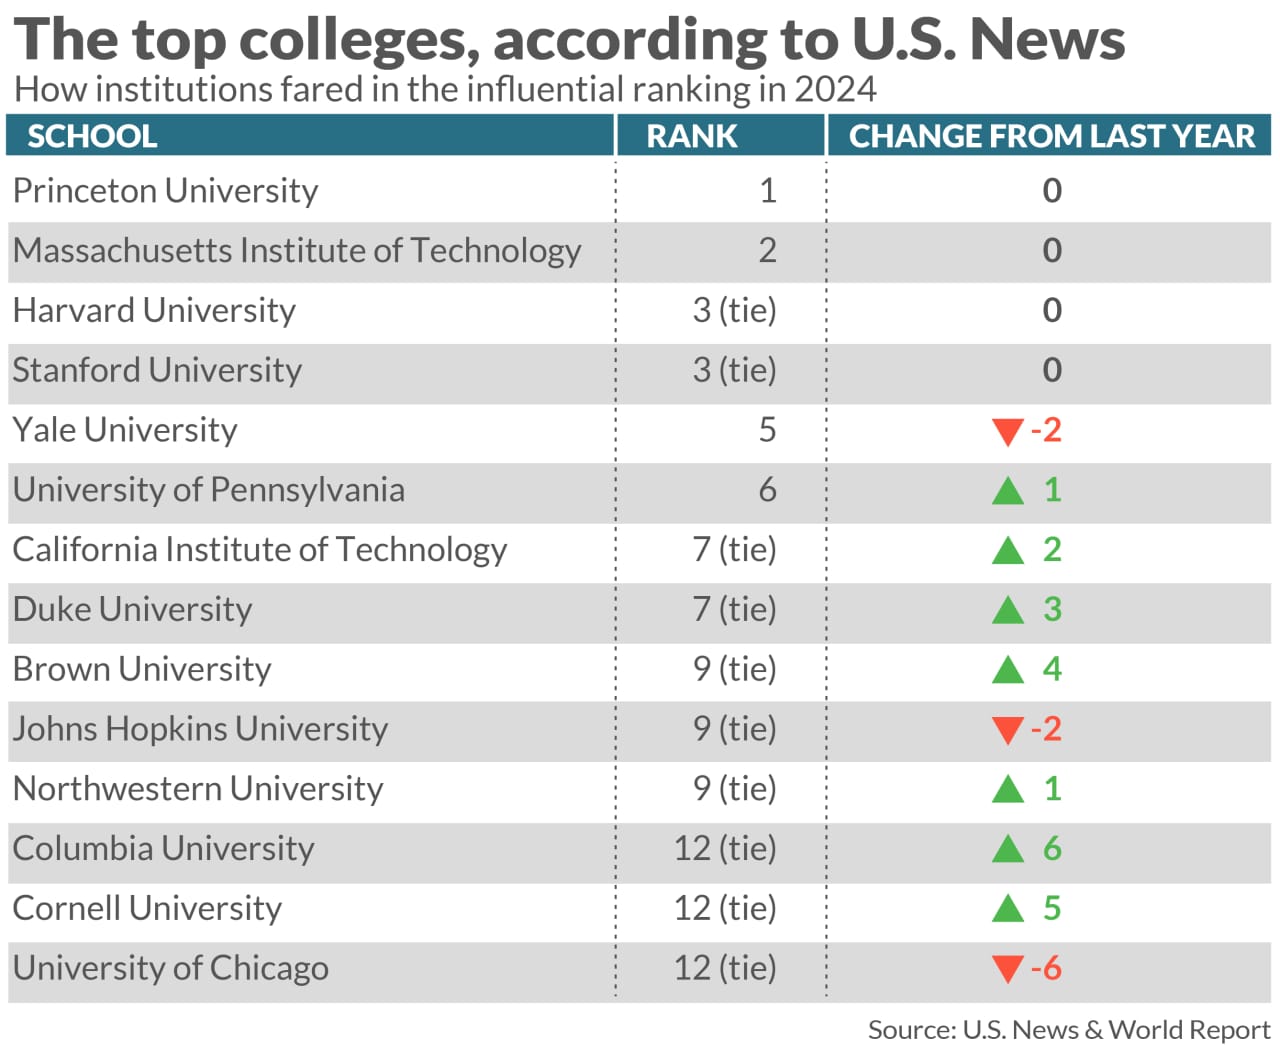
Choosing weights is essentially a value judgment dressed up as mathematics. If you care about student outcomes, you weight graduation and employment rates heavily. If you care about institutional prestige and resources, you weight selectivity and endowment per student. There is no neutral position here. Every weighting choice amplifies some schools and suppresses others. I ran into a specific problem a few years ago that illustrates this perfectly. I was building a ranking for a state-funded outlet that wanted to highlight value rather than prestige. Standard methodologies kept pushing selective private colleges to the top because their inputs (test scores, endowment, faculty spending) were dramatically higher. The resulting ranking was useless for the intended audience. I solved it by switching to a value-add model that measured outcomes against entry credentials rather than absolute outcomes. Schools where students graduated at rates significantly above their predicted probability based on incoming preparation got the highest scores. This flipped the entire top twenty and produced a list that actually reflected what the audience cared about. Value-added modeling like this is computationally more intensive than simple weighted sums, but the difference is manageable. A logistic regression or propensity score model runs in under two minutes on a dataset of a few thousand institutions. The real cost is interpreting the results correctly, which most ranking publications don't bother doing.
Common Pitfalls That Ruin Rankings
Survivorship bias is the most widespread issue. Many ranking methodologies only include institutions that report the required data, which systematically excludes smaller, under-resourced, or non-traditional schools. This creates a self-reinforcing cycle where only schools that already have the capacity to report data appear in rankings, making those rankings look more reliable than they actually are. Another issue is the ecological fallacy. Aggregated institutional data tells you nothing about individual student experiences. A school's median graduate salary says very little about what a specific student from a low-income background might earn. I've seen students make college decisions based entirely on median outcome data, which is statistically irresponsible at the individual level. Time lag is a practical problem that gets ignored constantly. Most ranking data is 1 to 3 years old by publication date. A school's ranking position can shift significantly in that window, especially for institutions undergoing leadership changes, funding fluctuations, or program expansions. I stopped trusting year-over-year movement in rankings entirely after watching three schools jump 40 plus positions between publication cycles due to a change in reporting methodology rather than any real improvement.
Building a Practical Ranking Model
If you want to build your own College Rankings system, here's the straightforward path without the gloss. Start with IPEDS as your primary data source. It covers nearly every accredited postsecondary institution in the United States and provides consistent metrics across years. Supplement it with College Scorecard for outcome data and individual institutional websites for program-specific information that IPEDS doesn't capture. You'll need roughly 40 to 60 data points per institution for a reasonably comprehensive model. Choose your variable set based on your intended use case. For student-oriented rankings, prioritize retention, graduation, debt at graduation, and earnings outcomes. For institutional comparison, add selectivity, faculty resources, and financial metrics. Don't try to serve both audiences simultaneously. The resulting model will be internally contradictory and useful to nobody.
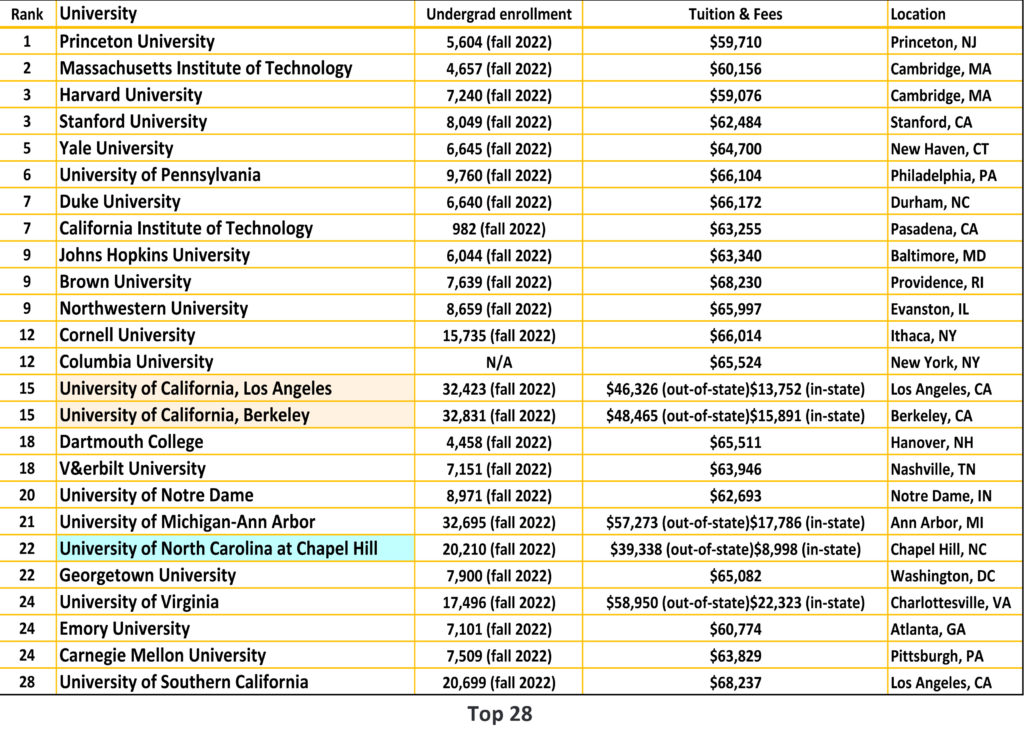
Handle missing data explicitly. Don't impute with means or medians without documenting it. A transparent approach where missing values are flagged and handled according to a published rule is more trustworthy than a black box that silently fills gaps. Missingness itself is informative. Schools that don't report certain metrics are often smaller or less resourced, and treating them as average on those metrics systematically biases your results. Test sensitivity by varying your weights by plus or minus 5 percentage points across all variables. If the top ten list changes completely under minor weight adjustments, your model is unstable and your conclusions are unreliable. I learned this the hard way when my initial model produced dramatically different orderings with barely any weight variation. The fix was reducing the variable count to the most robust indicators and using equal weighting rather than arbitrary assigned weights.
When Rankings Completely Fail
Rankings are essentially meaningless for program-specific decisions. The overall ranking of a university tells you nothing reliable about the quality of a specific department within it. Engineering programs and business schools have completely different ecosystems, accreditation processes, and employer relationships. A school ranked 80th overall might have a top-15 engineering program and a bottom-quarter business school, or vice versa. The composite score obscures this entirely. Rankings also break down for non-traditional students. First-generation students, older learners, and students from underrepresented backgrounds face different challenges than the median student that most ranking models implicitly target. The metrics that drive ranking positions often favor students who already have advantages, creating a feedback loop that makes rankings less useful precisely for the populations that need guidance the most. The most honest approach is to treat rankings as one input among many rather than a decision framework. They're best used for narrowing a large set of possibilities to a manageable subset, then evaluating those subsets through program-specific research, campus visits, financial aid comparisons, and direct conversations with current students and faculty.
A Quick Note on Tools
If you're building this yourself, Python with pandas is the standard tool. IPEDS data can be downloaded and parsed programmatically. The IPEDS Data Feedback Tool and the CDS (Common Data Set) provide structured files that integrate cleanly into a pandas workflow. For the value-added component, scikit-learn handles logistic regression and propensity score matching without requiring specialized statistical software. The entire pipeline, from raw data download to ranked output, typically runs in 10 to 20 minutes on a standard laptop after the initial setup is complete. I published my reference implementation as an open toolkit a few years back. It handles IPEDS parsing, data validation, multiple normalization methods, and sensitivity analysis out of the box. You can find it on GitHub under agnes-sapiens/college-rankings-toolkit. It's not polished production code, but it's functional and well-documented. The README walks through the entire process from raw data to final ranking with specific parameter recommendations based on what I've seen work in practice.