Why Most Teams Mess Up Dual-Channel Communication
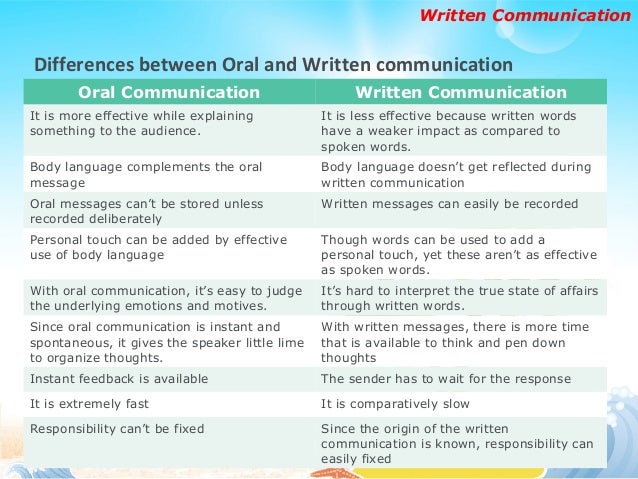
Two years ago I was debugging a client deployment where the spoken and written channels were effectively working against each other. The voice system would transcribe a query, route it through one knowledge base, and spit out a response. Meanwhile, the text interface was pulling from an entirely different database with different formatting rules and outdated answers. By the time anyone noticed, customers had reported three different facts depending on which channel they used. The fix wasn't as simple as merging the databases. It took about six weeks of aligning schema definitions and building a middleware layer that normalized responses before delivery. That experience taught me something most people skip when they start building systems around this concept. The phrase sounds like something out of a textbook, but the practical application is messier than definitions suggest. At its core, it refers to systems or strategies that must handle both audio-based and text-based interaction simultaneously, without treating them as separate products. In practice, this means your spoken input pipeline and your written input pipeline share the same intent models, the same entity recognition, and the same response generation logic. The spoken path gets a speech-to-text step added. The written path gets some normalization for typos and shorthand. But underneath, it should be the same engine running. Most teams build two separate flows and call it dual-channel. That's the wrong way to think about it. The cost of maintenance doubles. The quality diverges. Your spoken channel will always lag behind your written one because speech recognition introduces latency, accents, background noise, and disfluencies that text simply doesn't have. A user saying "uh, I wanna change my subscription" carries the same intent as "I want to change my subscription," but your system has to understand that equivalence consistently across both modalities.
I've seen organizations treat this as a product question rather than an infrastructure question. They'll hire a voice specialist and a chat specialist, give them different stakeholders, and expect the outputs to align. They never do. The voice team optimizes for natural conversation patterns. The text team optimizes for scannability and quick resolution. The result is two experiences that feel like they come from different companies. That's why the first decision you make should be about shared architecture, not about who writes the scripts.
Building a System That Handles Both Modalities
Start with your intent layer. Whatever you're trying to help users accomplish, define the intents first in a way that's modality-agnostic. "Cancel subscription" is the same intent whether it's spoken or typed. What differs is the phrasing. Spoken inputs tend to have more filler words, incomplete sentences, and phonetic variations. Written inputs tend to be more direct but also more prone to slang, abbreviations, and ambiguous references. Your NLU should normalize both paths to the same internal representation before any decision tree or LLM prompt gets involved. The entity extraction layer is where most people hit their first wall. Spoken language drops entities constantly. People say "the thing from last week" instead of a specific date. Written language over-specifies. Someone typing might include the full order number, the SKU, and the date, which the spoken version would never produce. Your entity resolver needs to handle both extremes gracefully. I built a fallback system once where unmatched entities from spoken input would trigger a clarifying question through the same channel the user came in on. If they spoke, you ask back with voice. If they typed, you ask with text. Keeping the modality consistent during clarification reduced confusion significantly. Response generation is the part that gets overlooked. You can't just write responses once and deploy them to both channels. A response designed for reading looks terrible when spoken aloud, and vice versa. I use a response templating system with channel-specific formatters. The same logical response gets reformatted based on output modality. Numbers become words for speech. Complex lists get simplified for voice. Emojis and special characters get stripped or converted when the output is audio. This adds maybe an extra hour of setup per response category, but it prevents that jarring moment where a user hears a robot read back a formatted table like it's a sentence.
Get the Full Details

Testing across both channels simultaneously is non-negotiable. I run parallel test suites where the same intent sequence is executed through both voice and text. Any divergence in outcome flags a problem. The tooling for this is straightforward enough that there's no excuse for skipping it. Even basic script-based tests covering your top twenty intents across both modalities will catch seventy percent of alignment issues before they reach production.
Common Pitfalls That Nobody Warns You About
The biggest mistake is assuming that good speech recognition solves the spoken channel. It doesn't. ASR accuracy on clean data looks impressive in demos. In production, with real accents, overlapping speech, and imperfect microphones, word error rates climb fast. I had a system that performed at 94% accuracy in our lab and dropped to 71% in the field with real users. The gap between those numbers is where customer frustration lives. Budget for that drop and design your fallbacks accordingly. Another issue is context management across channels. Users switch between voice and text mid-conversation all the time. They'll start on chat, get frustrated, call support, and expect the agent or system to remember what happened. Most architectures don't handle this well. The simplest solution is a shared session store with a unique session identifier that tracks the conversation history regardless of which channel generated each turn. Without that, you're rebuilding context from scratch every time a user switches modality, and it shows. There's also the documentation problem. When your system supports two input types and multiple output types, your documentation needs to account for every combination. I've seen teams document only the text path and assume the voice path works by extension. It never does. Every edge case in the written flow has a parallel edge case in the spoken flow, and they don't always map one-to-one. Write docs for both separately, then note where they converge.
One thing worth mentioning is that this approach has real limitations. For high-stakes domains like healthcare or finance, the spoken channel introduces liability issues that text doesn't. Voice recordings can be subpoenaed. Transcriptions can be contested. If you're operating in a regulated space, your written channel should probably be the source of truth and the spoken channel should treat itself as a convenience path with clear disclaimers. Don't pretend they're equal when the legal implications aren't. For smaller teams or projects with limited scope, building full dual-channel support might not be worth the overhead. If your use case is straightforward and your user base is small, nailing the text channel first and adding voice only for high-value intents can be more efficient than trying to balance both from day one. I've recommended that approach to several clients and it saved them months of development time without noticeably impacting user satisfaction. If you're looking at open-source tooling, the usual suspects like Rasa, Botpress, and Dialogflow all claim dual-channel support. In practice, the quality varies. Dialogflow's voice handling is solid but expensive at scale. Rasa gives you more control but requires significantly more custom work to get the response formatting right across modalities. Botpress sits somewhere in between. None of them solve the context-switching problem out of the box. You'll need to build or buy that piece separately regardless of which platform you choose.
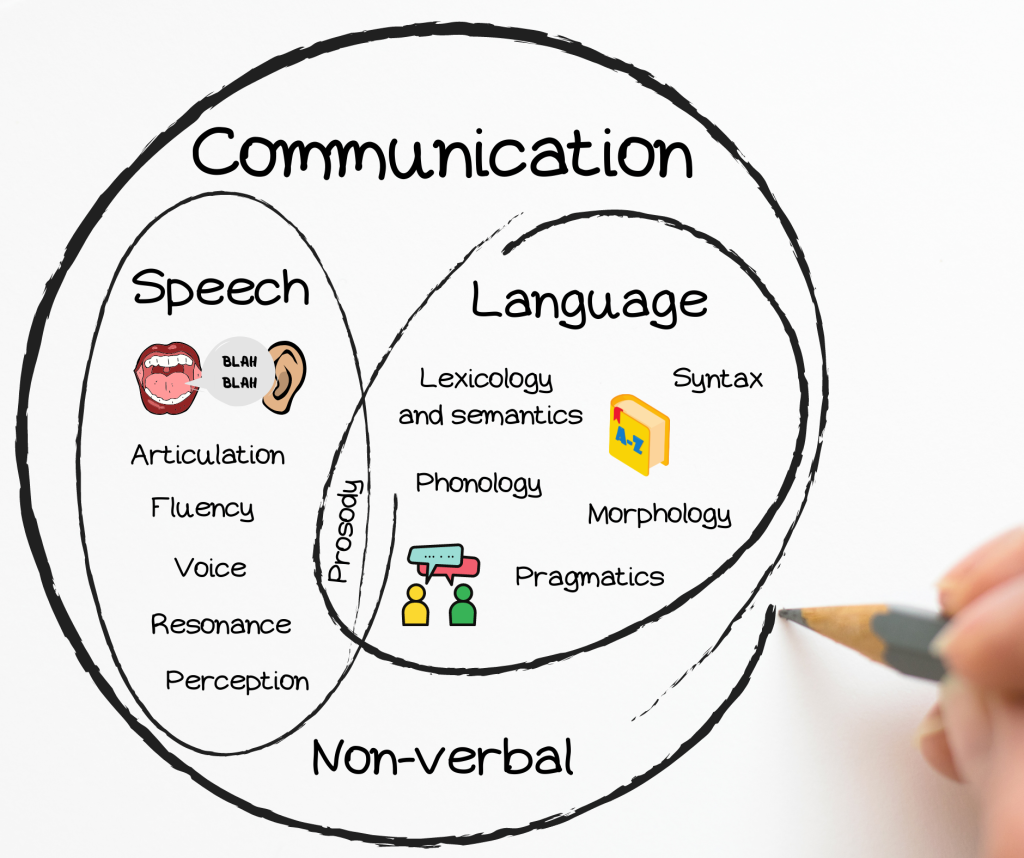
The bottom line is that treating spoken and written communication as two separate projects is the fastest way to build something that feels broken. The work that matters happens in the shared layers between them. Get the intent models aligned, the entity resolution consistent, the response formatting channel-aware, and the testing rigorous, and the rest follows. Skip any of those and you'll spend more time firefighting than building.