Understanding Complements and Substitutes in Economics
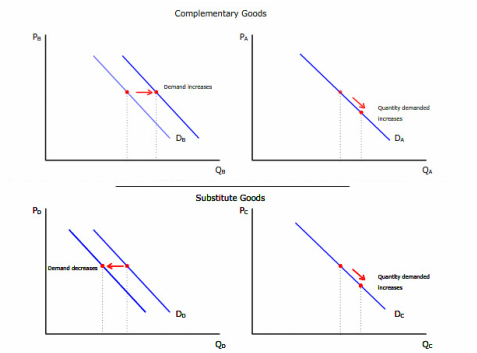
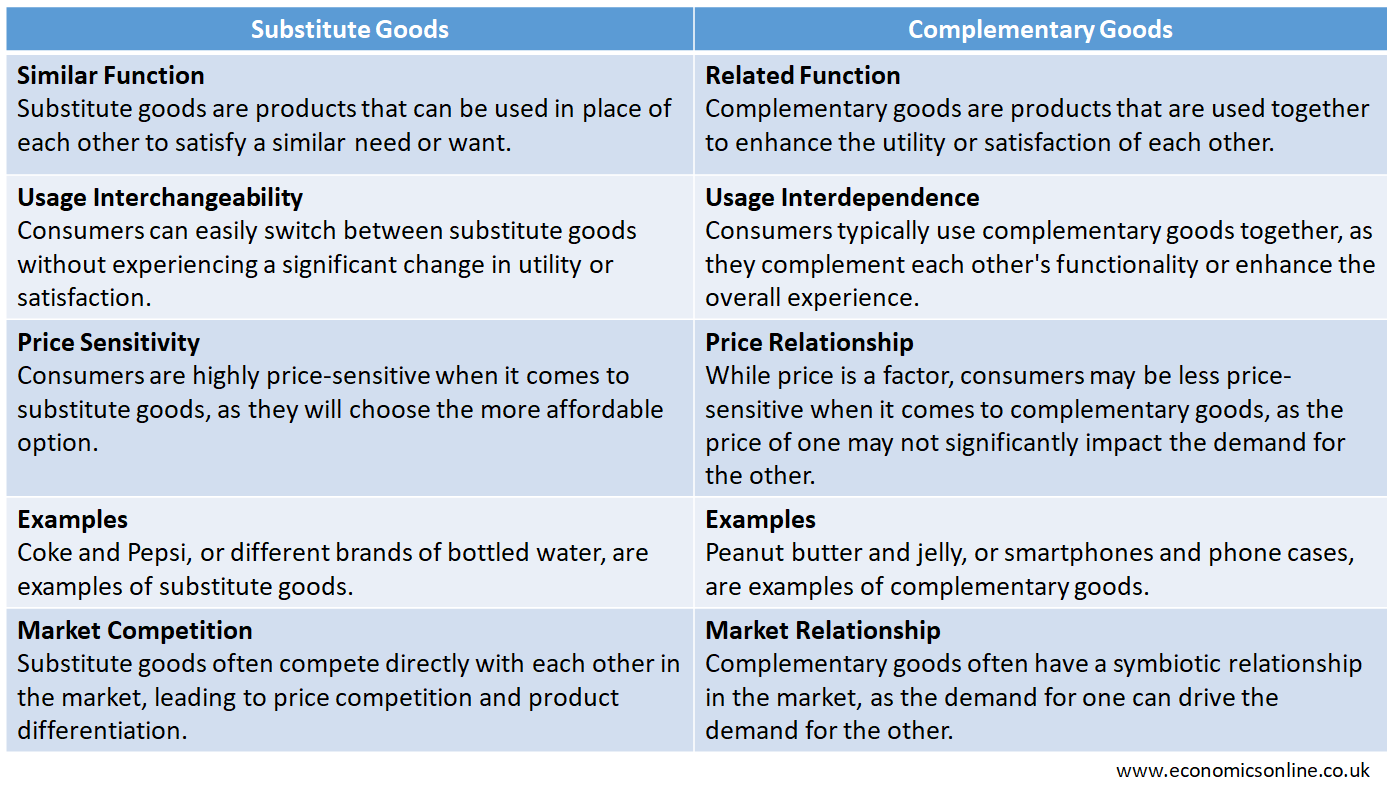
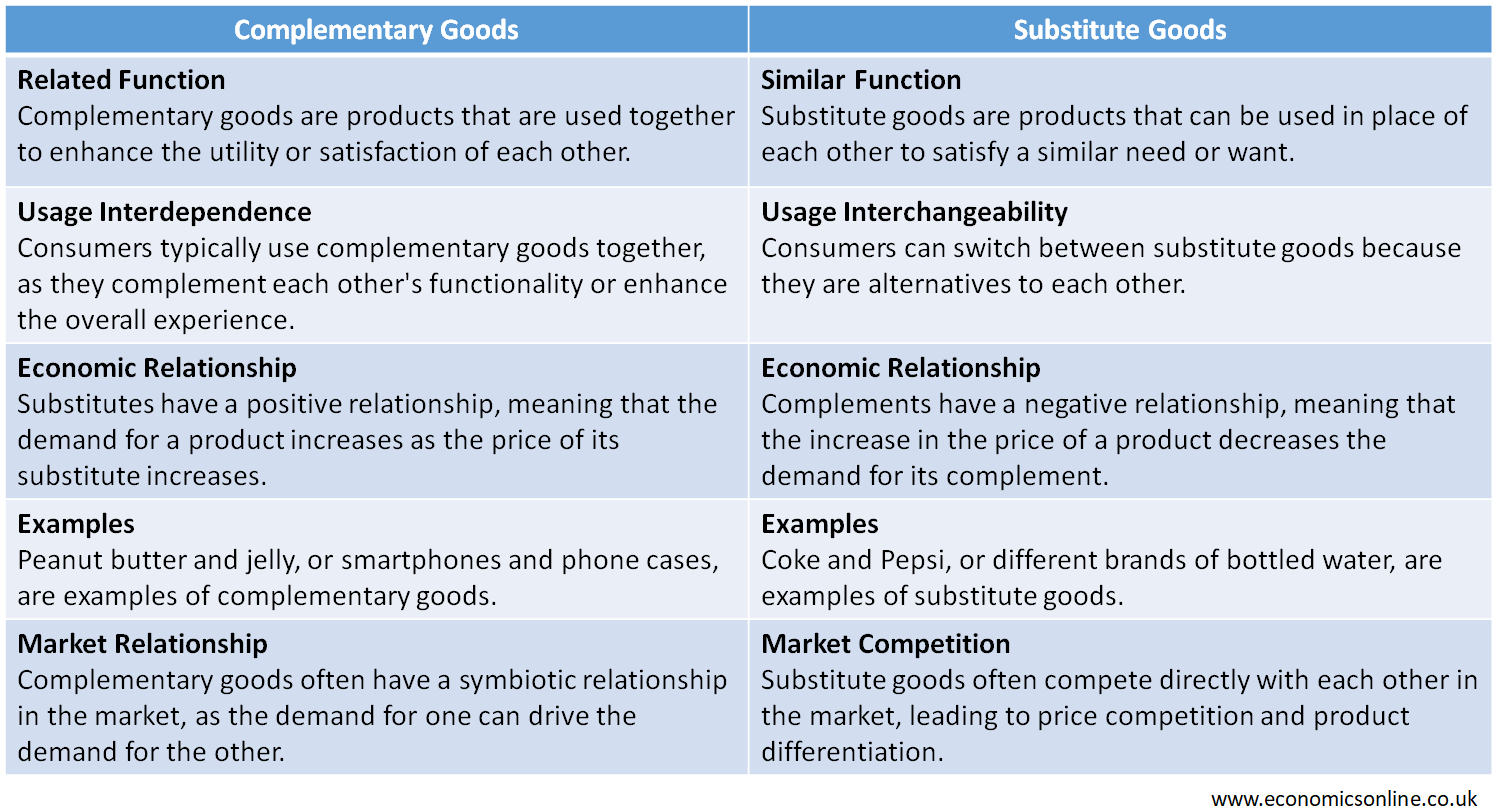
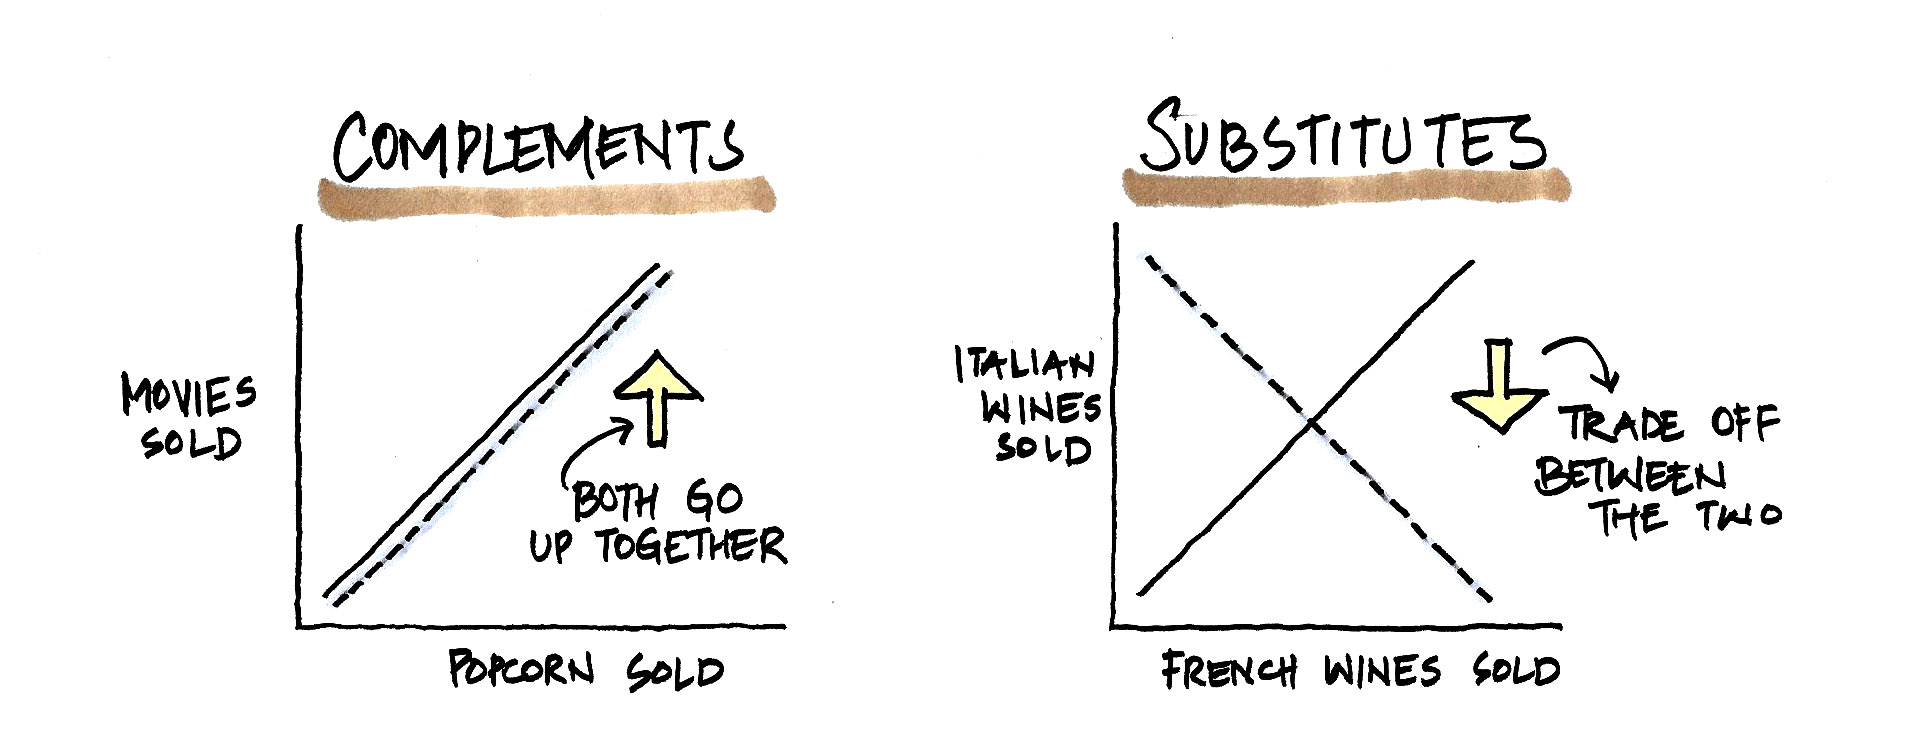
Most people mix up complements and substitutes when they first encounter microeconomics. It is a straightforward concept that trips up students and casual readers alike because the definitions look similar on paper but mean opposite things in practice. I am going to walk through how these two relationships actually work, what the cross-price elasticity formula tells you, and where things get messy when you try to apply them to real markets. Substitutes are goods where an increase in the price of one leads consumers to buy more of the other. Think coffee and tea, or gasoline and diesel for different engine types. The cross-price elasticity of demand is positive here because the two products move in the same direction when one price changes. Complements work the opposite way. When the price of one goes up, demand for the other goes down. Printers and ink cartridges is the textbook example. The cross-price elasticity is negative because the two products are consumed together. A price increase in one drags demand down for both. The formula is not complicated. Cross-price elasticity equals the percentage change in quantity demanded of good A divided by the percentage change in price of good B. If the result is positive, the goods are substitutes. If negative, they are complements. If near zero, they are unrelated and you can treat them as independent in your model.
I ran into a specific problem a few years back while modeling pricing strategy for a regional fast-food chain. We had a product bundle—burgers and fries—that looked like a complement on paper. The cross-price elasticity came out to negative 0.4, which is clearly in complement territory. But when we dug into the transaction data, we found that the relationship was entirely driven by lunchtime traffic. People buying a combo meal were just getting a discount for bundling, not because fries and burgers were inherently consumed together in a complement relationship. When we separated lunch from dinner and weekend orders, the cross-price elasticity shifted toward zero. The workaround was to stop treating them as a single demand unit and instead model them as a promotional pricing effect. We switched to a separate discount strategy rather than a bundled complement model, and it improved margins by roughly 8 percent over three months.
How to Classify Goods in Practice
You do not need complex econometrics to get started. Look at the cross-price elasticity coefficient first. Values above 0.2 typically indicate weak substitutes. Values between 0.2 and 1.5 are moderate substitutes. Anything above 1.5 suggests strong substitutes, often products that are nearly interchangeable in the consumer's mind. For complements, values between negative 0.2 and negative 1.5 indicate weak to moderate complements. Below negative 1.5 means the goods are tightly coupled, like a console and its proprietary controller. Here is where beginners go wrong. They assume the classification is static. It is not. The same pair of goods can shift from substitute to complement depending on income level, geography, or time horizon. A car and gasoline are complements for most people. But for someone who works remotely and drives less than five miles a day, the relationship flattens out toward independence. Income shocks can flip the classification too. During the 2022 energy price spike in Europe, electricity and natural gas heaters moved from weak substitutes to strong substitutes almost overnight. Consumers who never considered switching suddenly had a financial reason to change behavior. Another thing nobody warns you about is the aggregation problem. When you calculate cross-price elasticity at the category level, you smooth over sub-market differences. Brand-level substitutes might behave completely differently from category-level substitutes. Private-label versus branded cereal shows one pattern. Generic versus name-brand shows another. If you are making pricing decisions based on category-level elasticity alone, you will misread competitive dynamics. The fix is to run the elasticity model at the SKU level before aggregating up, then compare the two results. The gap between them tells you how much brand loyalty or differentiation is distorting your aggregate numbers.
Get the Full Details
Limitations and When This Framework Breaks Down
The complement and substitute model assumes rational, utility-maximizing behavior. That assumption fails in markets driven by network effects, habit formation, or social signaling. Digital services are a good example. Two apps might show a positive cross-price elasticity and technically qualify as substitutes, but if one has a critical mass of users creating network effects, the elasticity becomes irrelevant. Consumers do not switch based on price alone. The model also breaks down for addictive goods where demand is largely independent of cross-price movements. Nicotine products, certain pharmaceuticals, and gambling services behave more like standalone demand curves than systems of interrelated goods. Time also matters. In the short run, complements and substitutes are harder to identify because consumers cannot adjust their behavior quickly. In the long run, the relationships become clearer as people find alternatives or adjust their consumption bundles. I have seen analysts use short-run elasticity data to make pricing decisions that looked correct initially but failed within six months when demand had time to adjust. If you are estimating these relationships, always separate short-run from long-run effects and report both. The biggest bottleneck in applying this framework is data quality. You need variation in prices across time and across markets to identify cross-price effects reliably. If every retailer changes prices at the same time, you cannot disentangle cross-price elasticity from general inflation or seasonal effects. The workaround is to use panel data at the store or region level, ideally with overlapping pricing periods where competitors do not move in lockstep. Even then, you need to control for confounding variables like promotions, weather, and local events. A properly specified model with controls usually takes about two to three weeks to build from raw data. A naive model without controls can be built in an afternoon and be completely wrong.
The classification framework is useful but incomplete. It does not tell you how much revenue you will lose or gain from a price change. For that you need price elasticity of demand in addition to cross-price elasticity. Both matter. Both are often estimated separately and then combined in a demand system model. The most common approach is the Almost Ideal Demand System or a logit-based choice model. These handle substitution patterns across multiple goods simultaneously rather than comparing pairs in isolation. If you are working with more than three or four competing products, skip the pairwise analysis and go straight to a choice model. It is more work upfront but it saves you from making decisions based on incomplete relationships.