Working Through Function Tables
Most people treat function tables like worksheets where you plug numbers into a rule. The hard part isn't doing the arithmetic once you know the rule. It's figuring out the rule when you're only given a handful of input-output pairs and told to fill in the rest. I see this come up constantly in both spreadsheet work and introductory discrete math courses, and the failure mode is almost always the same: people assume linearity too quickly and miss a quadratic or exponential pattern hiding in plain sight. Start by looking at what you have. Say your table gives you x values of 0, 1, 2, 3, 4 and corresponding y values of 2, 5, 10, 17, 26. Your instinct will be to say the difference is +3 each time, which would make it linear. But the differences are actually 3, 5, 7, 9. Those aren't constant. The second differences — the differences of the differences — are 2, 2, 2. That constant second difference is the signal. You're dealing with a quadratic, not a line. Once you know the degree, the rest is mechanical. A quadratic takes the form f(x) = ax² + bx + c. With three known points you can solve the system directly. Using (0, 2), (1, 5), and (2, 10): c = 2 from the first point, then a + b = 3 from the second, and 4a + 2b = 8 from the third. Solving gives a = 1, b = 2, so f(x) = x² + 2x + 2. Verify against the remaining points — 3² + 6 + 2 = 17, 4² + 8 + 2 = 26. It holds.
For exponential patterns, check the ratios instead of differences. If each output is roughly 2.7 times the previous one, you're looking at f(x) = a · b^x. Take logs if the base isn't obvious. Logarithmic relationships show constant differences in the outputs for geometrically spaced inputs, which trips people up because the inputs don't look uniform. Here's where I made a mistake early in my career that cost me a day of rework. I was handed a dataset with x values 1 through 6 and y values that I assumed followed a simple linear trend because the first four points looked close enough. I extrapolated using that line for the last two. The actual function was f(x) = 2^x, and the "linear" points were just the flat left tail of an exponential curve. The divergence only became visible at x = 5 and x = 6. My workaround was straightforward but something I wish I'd done immediately: always compute second differences or ratio tests before committing to a model, even when the first few points look deceptively clean. That single check would have caught it in minutes instead of requiring a full rebuild.
When This Method Breaks Down
Function tables are only as reliable as the pattern you've identified, and there are scenarios where the pattern is genuinely ambiguous. A set of five points can be perfectly fitted by infinitely many curves of sufficiently high degree. If you're given inputs 0, 1, 2 with outputs 1, 2, 4, that could be f(x) = 2^x or f(x) = x² - x + 2 or any number of other functions. The table alone doesn't tell you which one is intended. In practice, the context usually resolves this — a physics problem implies polynomial behavior, a compounding interest problem implies exponential — but if you're working in a vacuum, you should note the ambiguity rather than picking the simplest-looking answer and presenting it as fact. Another hard limitation is domain restriction. If x represents something like a count of items or a time variable that can't be negative, filling in entries for x = -1 or x = -2 is technically "completing" the table but producing values that are meaningless in the original context. I've seen this error repeatedly in introductory settings where students compute outputs without checking whether the input falls within a valid domain. Logarithmic and rational functions are especially prone to this — plugging in x = 0 for f(x) = ln(x) gives you nothing useful, and dividing by zero at a pole turns your neat table into a list of undefined entries. There's also the spreadsheet edge case where intermediate calculations involve floating-point arithmetic and you end up with values like 2.9999999997 instead of exactly 3. This doesn't affect manual function tables since you're working with exact numbers, but if you're automating table completion in a script or sheet, rounding decisions matter. Set a tolerance or explicit rounding step rather than letting raw float values pollute your output column.
Get the Full Details
Practical Filling Strategy
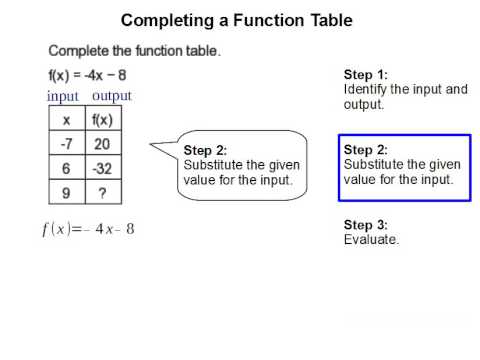
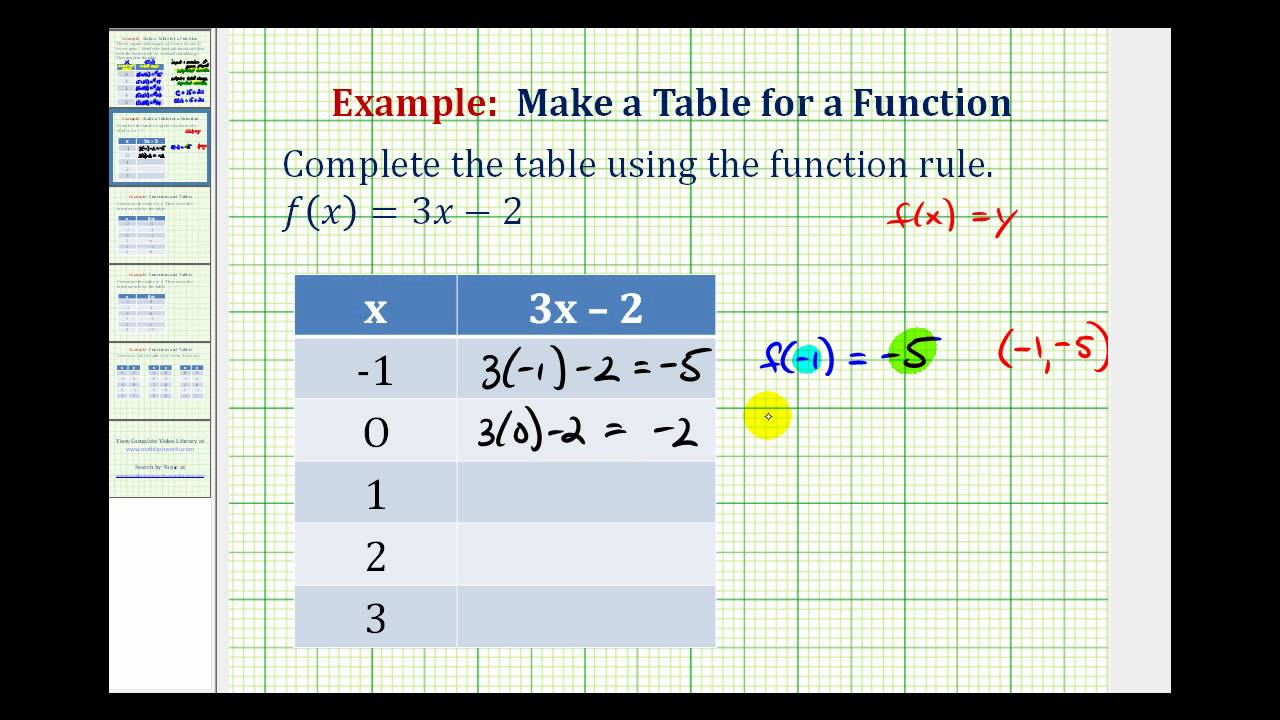
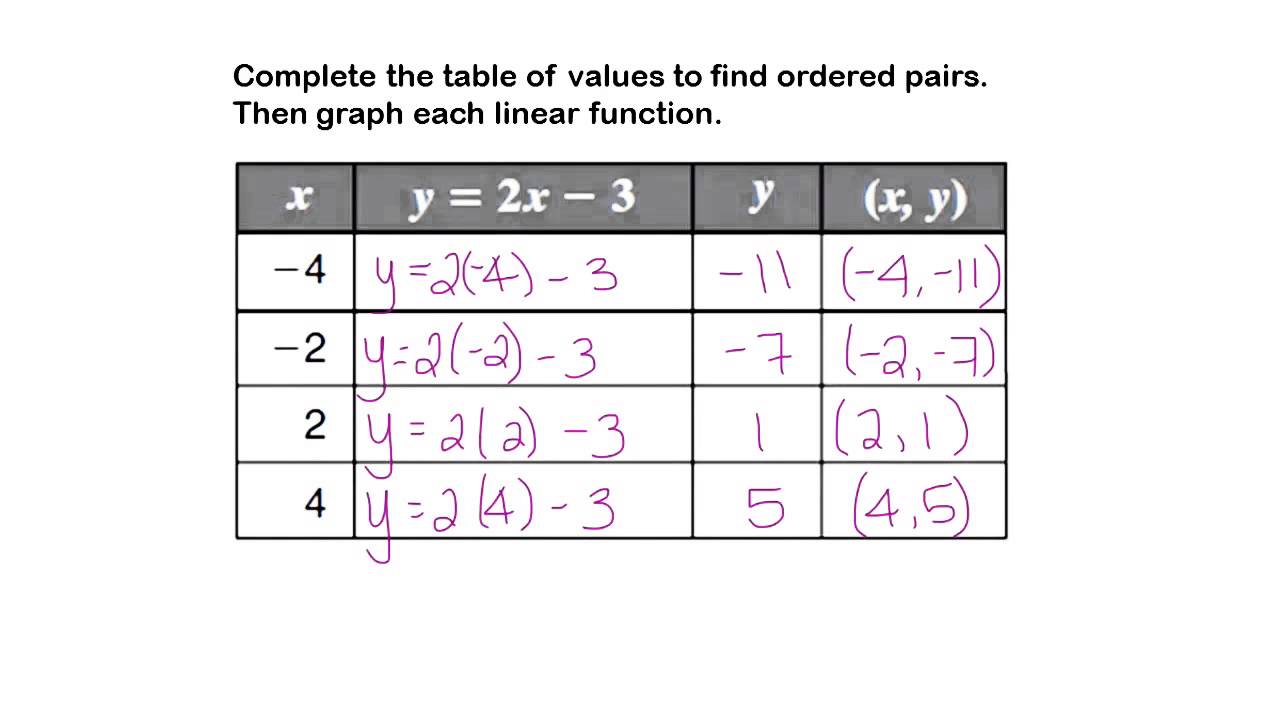
When you have a complete function definition and just need to generate the output column, the process is less interesting but still worth doing carefully. For f(x) = 3x² + 2 with x values 0 through 4, you compute 2, 5, 14, 29, 50. Not 2, 5, 10, 17, 26 — that was the earlier example with a different function. Mixing up your own examples is a real risk when you're working through tables quickly, so label your function clearly before you start filling. If you're working piecewise functions, treat each interval as its own sub-problem. A function that uses one rule for x 0 and another for x > 0 will produce a discontinuity at the boundary. The table should reflect that — don't smooth it over by applying a single formula across the break. I've corrected more than a few student submissions where the person applied the positive-side formula to x = 0 out of habit, getting the wrong value on the boundary point. The main takeaway is that completing a function table is really two separate skills stitched together: pattern identification and mechanical evaluation. Most mistakes happen at the boundary between those two. Get the pattern wrong and everything downstream is wrong. Get the pattern right and the rest is arithmetic. Spend your energy on the first part.