What People Actually Mean When They Say Comprehensive Coding Tracker
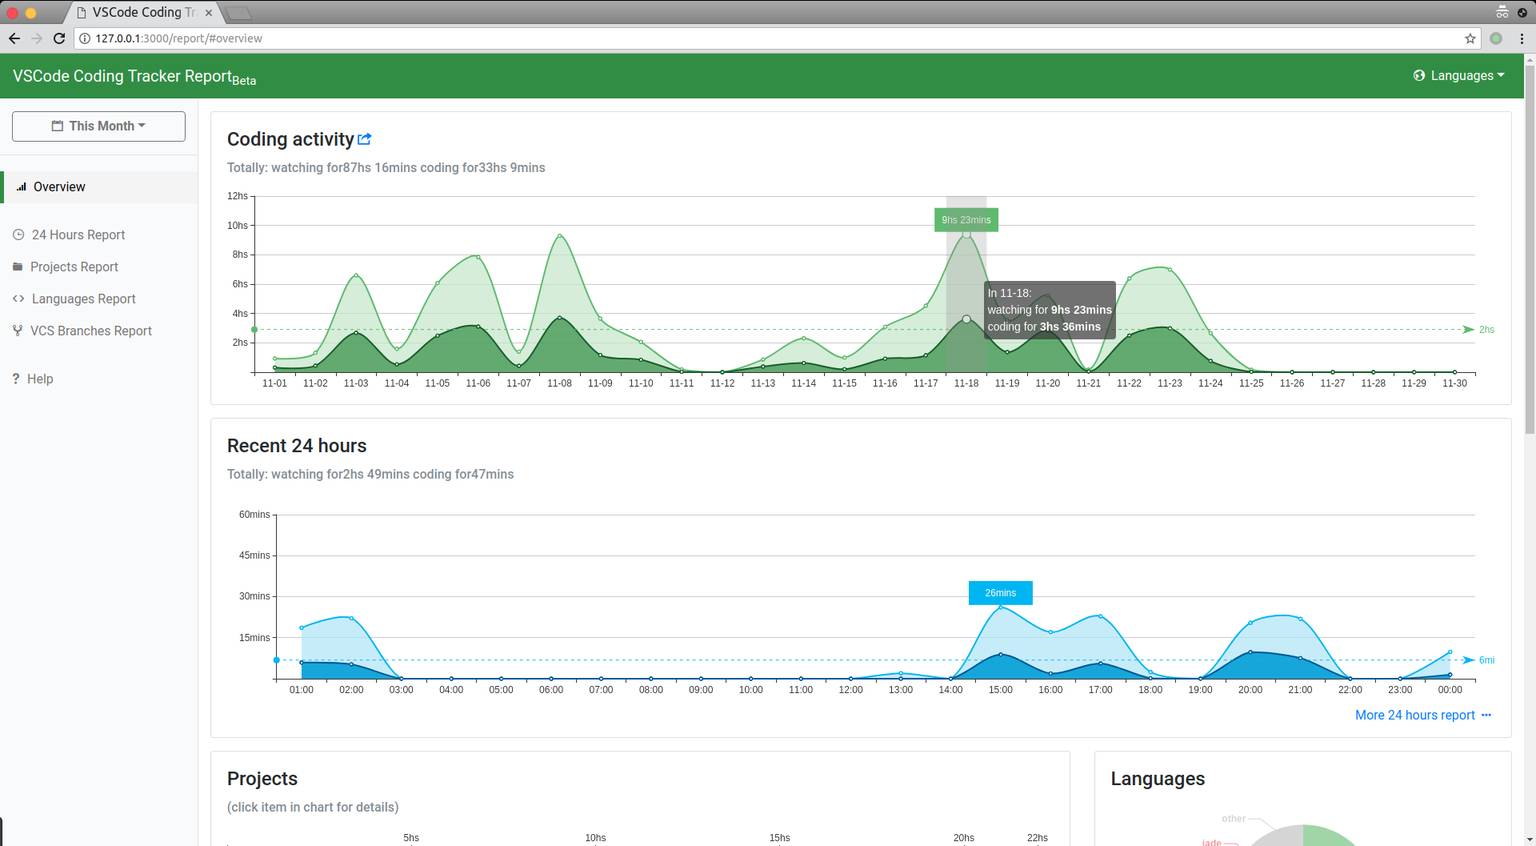
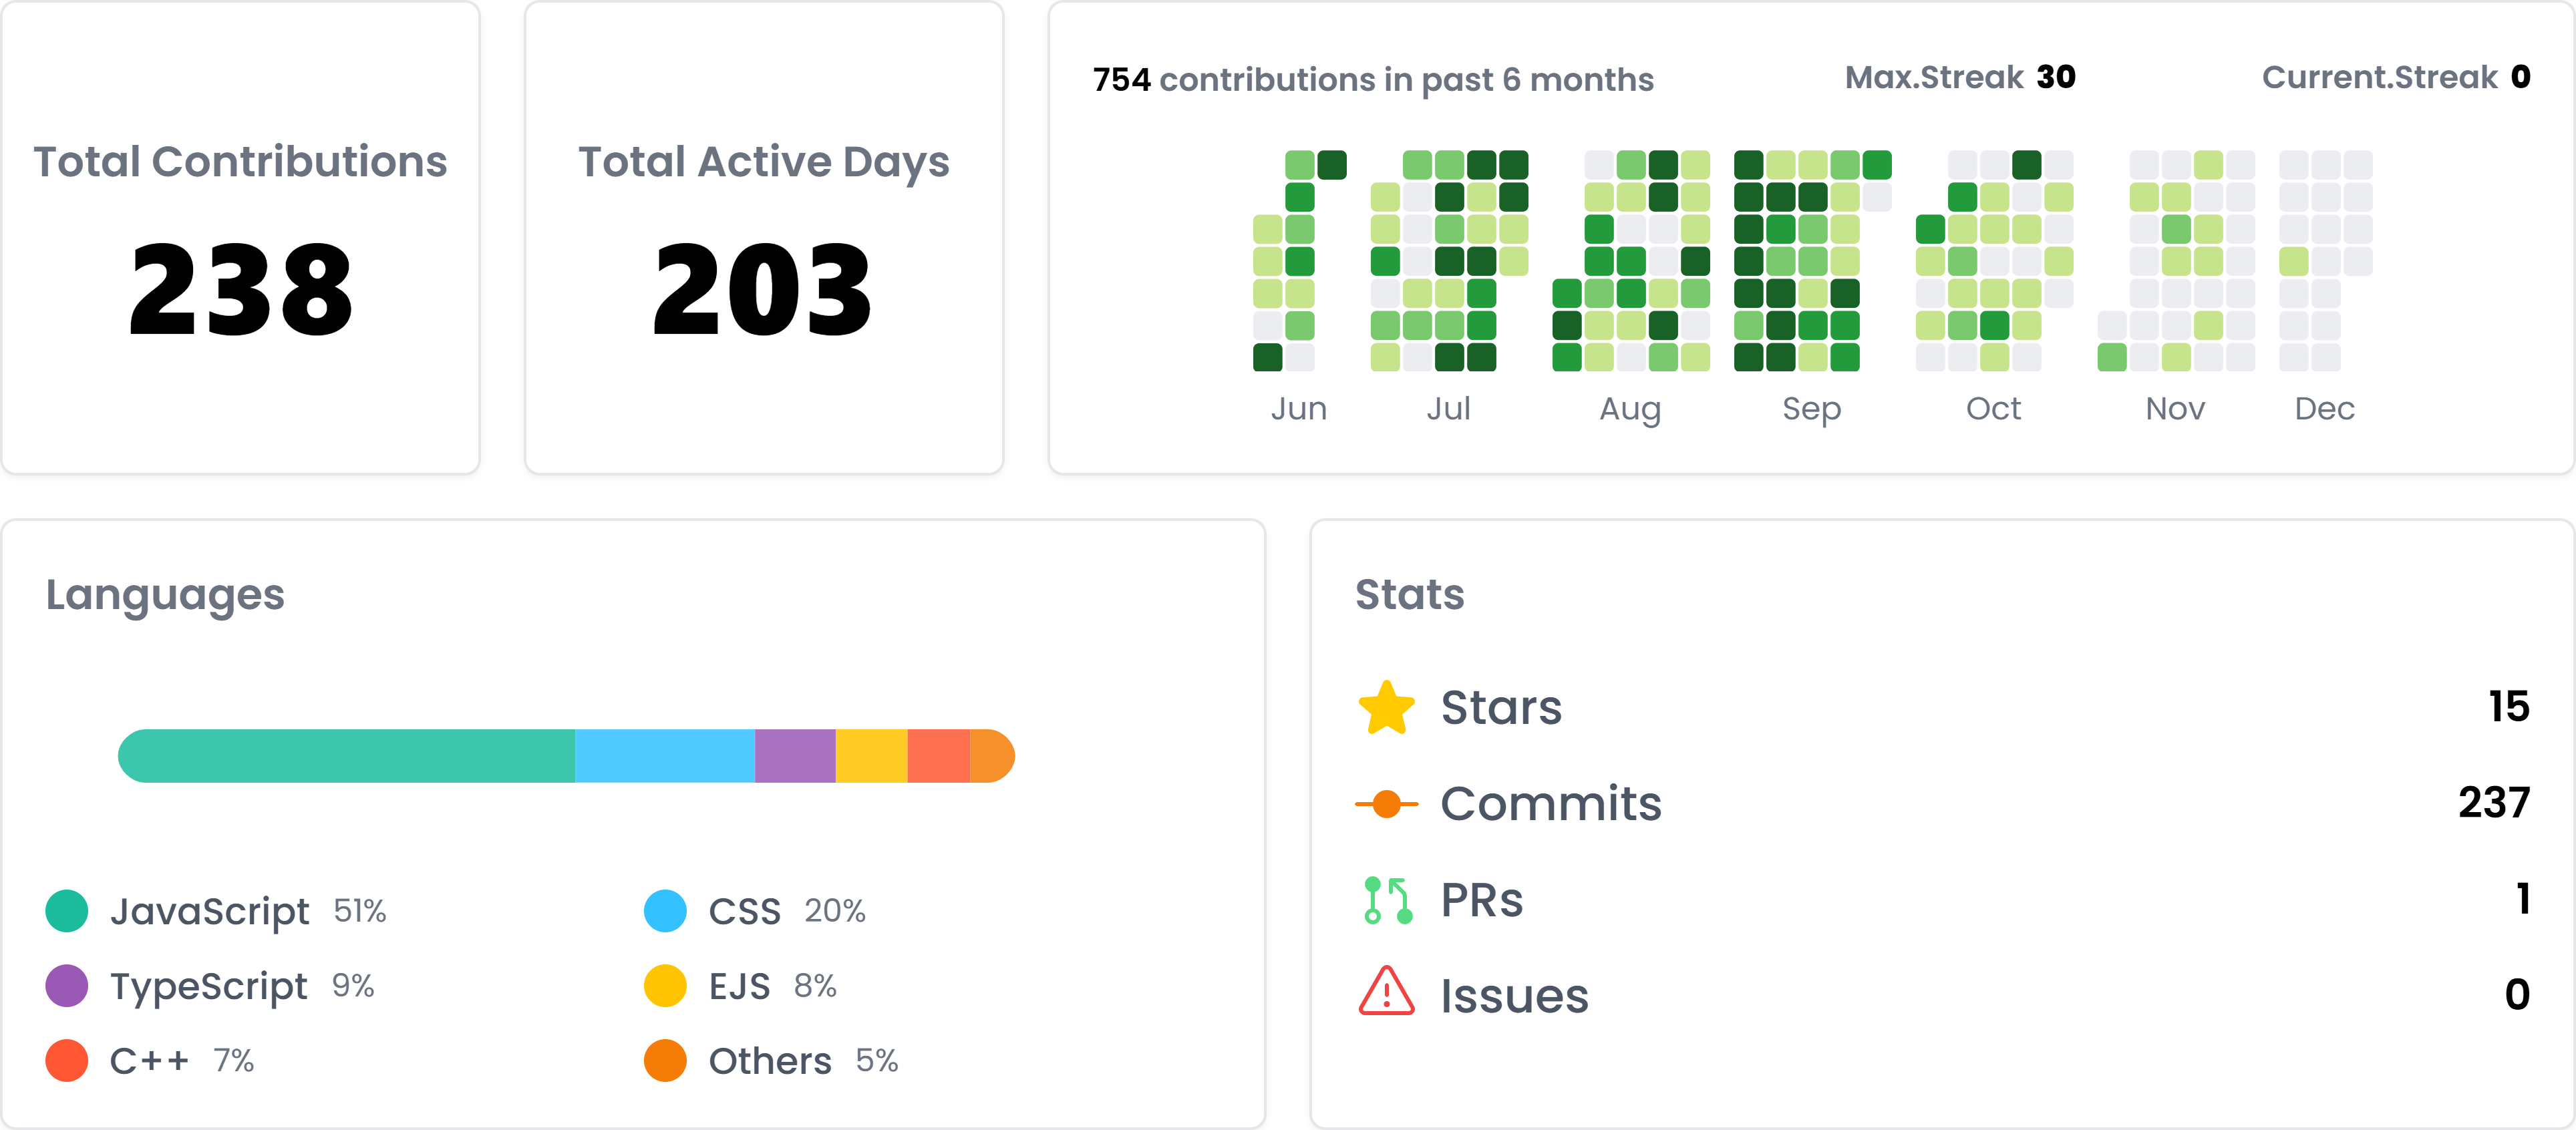
A comprehensive coding tracker is basically a system that logs every meaningful action you take while writing software. Commit hashes, branch merges, bug tickets, time spent per file, test coverage changes, deployment timestamps, pull request reviews. The good ones pull all of that together into one view instead of making you context-switch between Jira, GitHub, your terminal, and some spreadsheet where you manually logged hours last Thursday because you forgot to use a timesheet tool. I stopped trying to build my own from scratch about three years ago. The problem is not tracking itself. The problem is integration. Every tool you connect introduces a failure point. A webhook misses a commit, your script crashes on a timezone mismatch, you lose a week of data and never realize it until someone asks why the velocity chart looks like a cliff edge. I learned that the hard way after a failed migration attempt cost me four days of reconstructing historical data from .git log exports and Slack threads.
Comprehensive Coding Tracker Setup
If you want to set something up that actually works, start with the data sources, not the dashboard. Most people build the visualization first and then spend weeks wondering why their numbers are wrong. Pick your platforms. GitHub or GitLab for version control. Your project management tool for tickets. A CI/CD pipeline for deployments. Optionally a code coverage tool. Then figure out the aggregation layer before you touch any frontend work. The aggregation layer is where everything either holds together or falls apart. I use a simple Python script that pulls from each API on a cron schedule, normalizes the timestamps to UTC, deduplicates entries by source ID, and writes everything into a SQLite database. Yes, SQLite. For a single developer or small team, it is more than enough and it does not require a running PostgreSQL instance that someone forgets to back up. If you are past roughly fifty concurrent users, move to PostgreSQL with proper indexing. But most people are not at that scale and do not need to be. Here is the specific edge case that burned me for two weeks. GitLab and GitHub use different timestamp formats in their API responses. GitLab returns ISO 8601 with timezone offset. GitHub returns RFC 3339, which is technically the same format but some of their older endpoints occasionally omit the trailing Z or timezone designator on certain event types. My parser assumed a consistent format and silently produced garbage dates for about 12 percent of GitHub events. The tracker showed deployments happening in 1970 and 2099. I caught it when I was trying to correlate a spike in bug reports with a release and the timeline looked like abstract art. The workaround was to add a strict ISO 8601 parser with fallback logic that tries multiple format strings and logs a warning whenever it has to use the fallback path. Now I know exactly which events were ambiguous and can review them manually.
What the Metrics Actually Tell You
The useful metrics from a coding tracker are lead time for changes, deployment frequency, change failure rate, and mean time to recovery. These are the same four metrics from the State of DevOps reports and they remain useful because they measure flow, not activity. Number of commits is not a useful metric. It measures motion. Flow measures whether code actually reaches production and whether it works when it gets there. One counter-intuitive thing I found after running this setup for over a year. Teams that have high commit frequency but low deployment frequency are usually the ones with the most process debt. They are committing work in progress frequently because nobody has the bandwidth to merge it, or the CI pipeline is failing intermittently and they are stuck in a queue. The tracker makes this visible immediately when you overlay commit count against deployment count on a weekly timeline. You will see the divergence. That divergence is your bottleneck. It is usually a review process, a flaky test suite, or a deployment gate that someone added six months ago and nobody remembers why. Another thing beginners miss. Test coverage percentage is almost never the right metric to optimize for. I watched a team push their coverage from 62 percent to 89 percent over three months and their bug rate in production actually increased. They were writing trivial coverage for setter methods and generated code, not testing actual business logic. The tracker showed the coverage number going up while the change failure rate also went up. Those two trends moving in the same direction should always make you suspicious. A comprehensive coding tracker becomes useful when you stop treating any single metric as truth and start looking at correlations between metrics over time.
Get the Full Details
Common Pitfalls and Where This Approach Fails
The biggest failure mode is tracking everything and learning nothing. I once connected twelve different data sources into one dashboard and spent so much time maintaining the pipeline that I stopped looking at the dashboard. The system was technically comprehensive and practically useless. Cut your data sources down to the minimum that answers the questions you actually have. If you do not know what questions you have, that is fine. Start with three. Deployment frequency, lead time, and incident count. Add more only when those three stop answering your problems. Another limitation. A coding tracker cannot capture context. It will tell you that a developer made 47 commits in a week and deployed three times. It will not tell you that two of those deployments were hotfixes for a production outage caused by a misconfigured environment variable, or that the developer was simultaneously covering for a teammate who was out sick. Raw tracking data without team context produces misleading conclusions. Managers who look at tracker numbers without talking to engineers will draw the wrong inference about performance every time. Use the tracker to ask better questions, not to answer them alone. If you are looking for a ready-made solution instead of building your own, there are tools like Plandex, CodeScene, and Sirene that attempt this. They are better than nothing for small teams but they struggle with the same integration fragility. Any tool that claims to be truly comprehensive will eventually hit a platform edge case where the vendor has not implemented the mapping yet. That is why understanding the underlying pipeline matters even if you are using commercial software. When something breaks, you need to know whether it is a data problem or a display problem.
The SQLite approach I described runs on a single Raspberry Pi 4 in my office. It uses about 300MB of disk space for six months of data across five repositories and updates every fifteen minutes. The dashboard is a basic Flask app with Chart.js. Total development time for the initial version was roughly two days. Maintenance is maybe thirty minutes a week for log review and occasional API schema changes from GitHub or GitLab. It is not elegant. It does not have a mobile app. It does exactly what it needs to do.