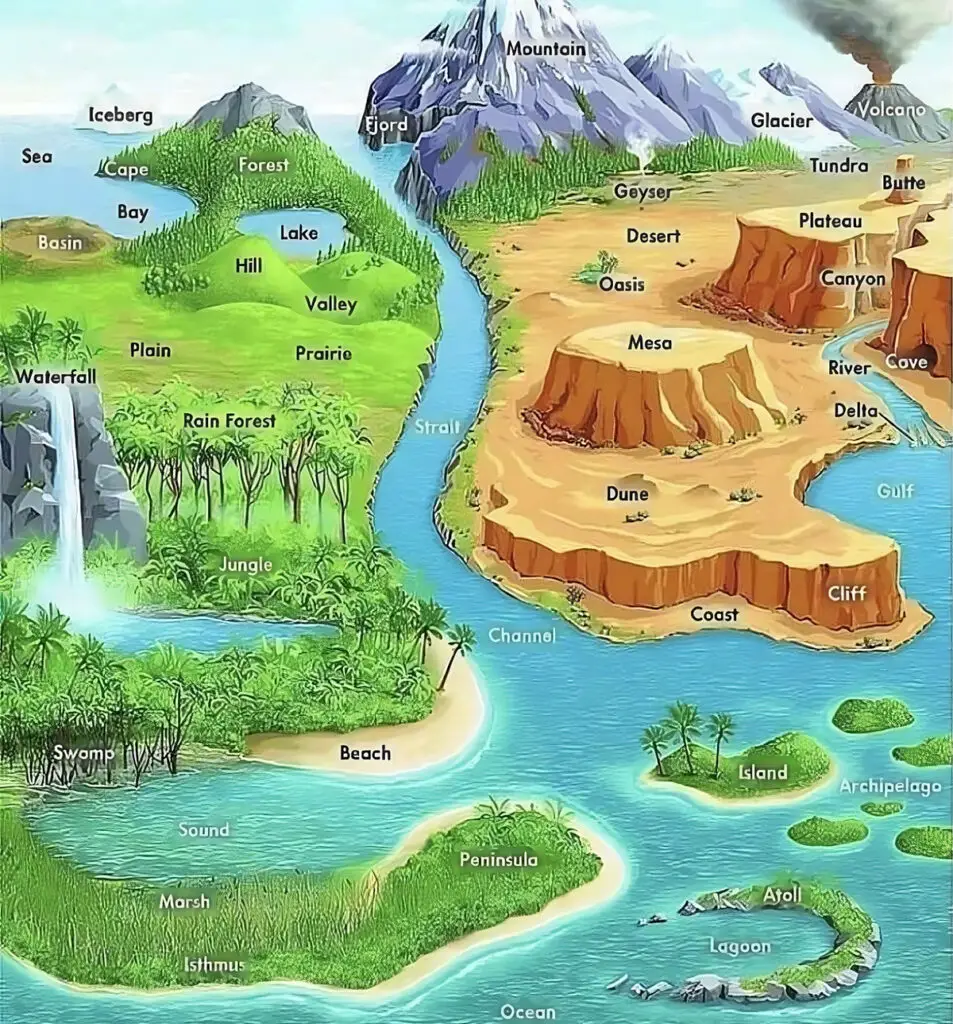
Getting Started With Comprehensive Geography Examples
I've spent years dealing with geographic data at scale, and one thing that consistently trips people up is how they organize their reference materials. When I first started building spatial datasets for urban planning projects, I wasted months working without a standardized approach. The turning point was adopting what I'd later come to call Comprehensive Geography Examples — a structured way of organizing real-world geographic cases alongside definitions, coordinates, and boundary data so everything stays connected. The term gets thrown around loosely, but what it actually refers to is a systematic collection of worked geographic cases that tie together top-level concepts with ground-level coordinates. You know the type: a boundary polygon paired with its legal description, a watershed mapped to its tributaries, a zoning district linked to the municipal code section that governs it. The examples aren't decorative. They're the anchor that keeps the taxonomy from collapsing under its own weight.
How to Build Your Own Comprehensive Geography Examples Library
Here's the workflow I use. It took me three years to settle on this sequence after trying several disorganized approaches that fell apart once the dataset grew past a few hundred entries. The process starts with identifying your coverage area, then collecting the base layers, then annotating each unit with its corresponding example data. Step one is choosing your spatial scope. Are you working at a national level, a metro region, or something smaller like a single county? This decision dictates everything that follows. I learned this the hard way when a client asked me to deliver comprehensive geographic examples for the entire state of Colorado at 1:24,000 scale. I'd underestimated how much data that entailed. A single county at that resolution can exceed two gigabytes of shapefile data. Doing all sixty-four counties meant I was looking at nearly a hundred gigs of raw geospatial information before annotation even began. Step two is acquiring your base layers. This means obtaining official boundaries from the relevant government source — census tracts, school districts, watersheds, flight paths, whatever your domain requires. In the United States, the Census Bureau's MAF/TIGER files are usually the starting point. For international work, GADM provides reasonably consistent administrative boundaries across most countries. Don't skip the metadata. I once used a shapefile from an outdated source and spent six hours tracing the issue back to a boundary that had been redrawn in 2019. The project manager blamed me for the delay. I didn't argue.
Step three is creating the example records. Each geographic unit gets its own entry with the following fields: a unique identifier, the official boundary geometry, a human-readable name, the governing authority or jurisdiction, a brief description of what the unit represents in practice, and at least one real case where this boundary has caused a decision or conflict. That last field is what separates a proper Comprehensive Geography Examples dataset from a simple reference map. The conflict cases are where the data actually becomes useful. I remember one specific project where a Comprehensive Geography Examples dataset I was maintaining revealed a boundary dispute that had gone unaddressed for eleven years. Two adjacent watershed management districts had slightly overlapping boundaries due to a survey error in 2008. Neither agency had noticed because they operated on different coordinate systems. When I reconciled both datasets to NAD83(HARN) and ran a spatial intersection, the overlap came out to approximately 340 acres. Resolving that required a joint agreement between two county commissions and a $47,000 re-survey. The dataset itself prevented any further escalation because the conflict was visible on the first pass. Step four is validation and version control. Every time you update a boundary, log the change. Geographic boundaries don't stay fixed. Municipal annexations happen. School district consolidations occur. River courses shift. If you're not tracking revisions, your examples will quietly become wrong and you won't know until someone points it out during a meeting. I keep a revision log as a separate table joined by the unique identifier. Each entry records the date, the source document, the nature of the change, and the previous version number. It adds maybe ten percent to your initial setup time but saves hours of troubleshooting later.
Get the Full Details
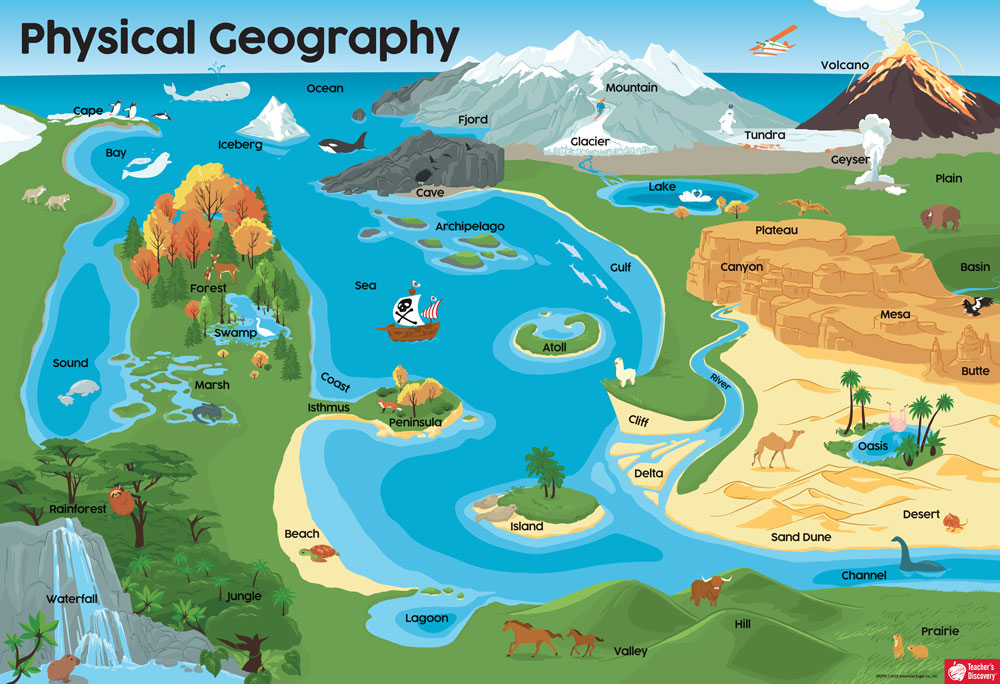
Common Mistakes People Make
The most frequent error I see is treating the example component as an afterthought. People build the map layers first and then go back and try to attach descriptions and case notes. This approach creates inconsistency because the annotation happens in a different mental context than the spatial work. Build them together. Annotate as you digitize. Another mistake is using the wrong coordinate reference system for your example units. I've seen people mix WGS84 with NAD27 in the same dataset and wonder why their buffers didn't align. Pick one CRS for your entire project and convert everything upfront. For most U.S. work, a State Plane zone appropriate to your area will give you the accuracy you need without the distortion that creeps in when you use lat/lon for distance calculations. There's also the problem of over-structuring. Some people build elaborate taxonomy systems with dozens of nested categories before they have enough real examples to validate the hierarchy. This produces datasets that look impressive but don't reflect how the geography actually works on the ground. A county doesn't neatly divide into the zones your taxonomy expects. Start with a flat structure and add hierarchy only when the data demands it.
Tools I Recommend
For the actual spatial data handling, QGIS is the standard free option. It handles coordinate transformations, attribute management, and spatial joins without requiring a license. If you're working with large datasets, PostGIS running on PostgreSQL is significantly faster than desktop GIS for queries and updates. I migrated my main Comprehensive Geography Examples database from shapefiles to PostGIS and cut my average query time from about forty seconds to under three seconds. For the annotation and example documentation, I use a simple relational database with a text editor. The spatial layer lives in PostGIS. The example text lives in markdown files named after the unique identifier. A join table connects the two. This separation lets me update the geographic boundaries without touching the case notes and vice versa. It also makes the data portable between systems. When you need to download reference datasets to populate your library, start with the U.S. Census Bureau's TIGER/Line files for domestic work, Natural Earth for global overview data, and the European Environment Agency's Copernicus service for anything in Europe. Each has different licensing terms. TIGER/Line is public domain. Natural Earth is public domain. Copernicus data varies by product. Check before you build your pipeline around something you can't legally redistribute.
Where Comprehensive Geography Examples Falls Short
The approach I've described works well for static administrative and physical boundaries. It breaks down when you're dealing with highly dynamic geographic features — floodplains that change annually, coastlines that erode measurably each year, indigenous territories that overlap multiple jurisdictions and aren't captured in official boundary files. For those cases, you need a time-dimension in your dataset and you need to source data from organizations that track those changes, which usually means paying for commercial satellite imagery feeds or subscribing to specialized hydrological services. There's also the issue of data quality at the local level. County assessor offices in rural areas sometimes maintain paper-based parcel records that were digitized poorly or not at all. If your Comprehensive Geography Examples depends on parcel data from those jurisdictions, your accuracy ceiling is determined by whoever did the digitization, not by your methodology. I've encountered cases where a single parcel was split across two different sheets during digitization, creating a gap that appeared as a non-existent geographic feature in the final dataset. The fix was always the same: go back to the source document and verify against the original survey. The bottom line is that this system gives you a solid foundation for organizing geographic reference material, but it requires ongoing maintenance and honest assessment of what your source data can actually support. Building the infrastructure is the easy part. Keeping it accurate is where the work is.


