Python Cheat Sheets Are Useful Until They Lie to You
I spent three days debugging a production script only to realize I had been following outdated tuple unpacking syntax from a printed reference. The code looked right. It ran without errors in isolation. But in the actual context, something about the operator precedence was silently producing the wrong result. That was the day I stopped trusting cheat sheets at face value and started cross-referencing everything against the official documentation with my own test cases.
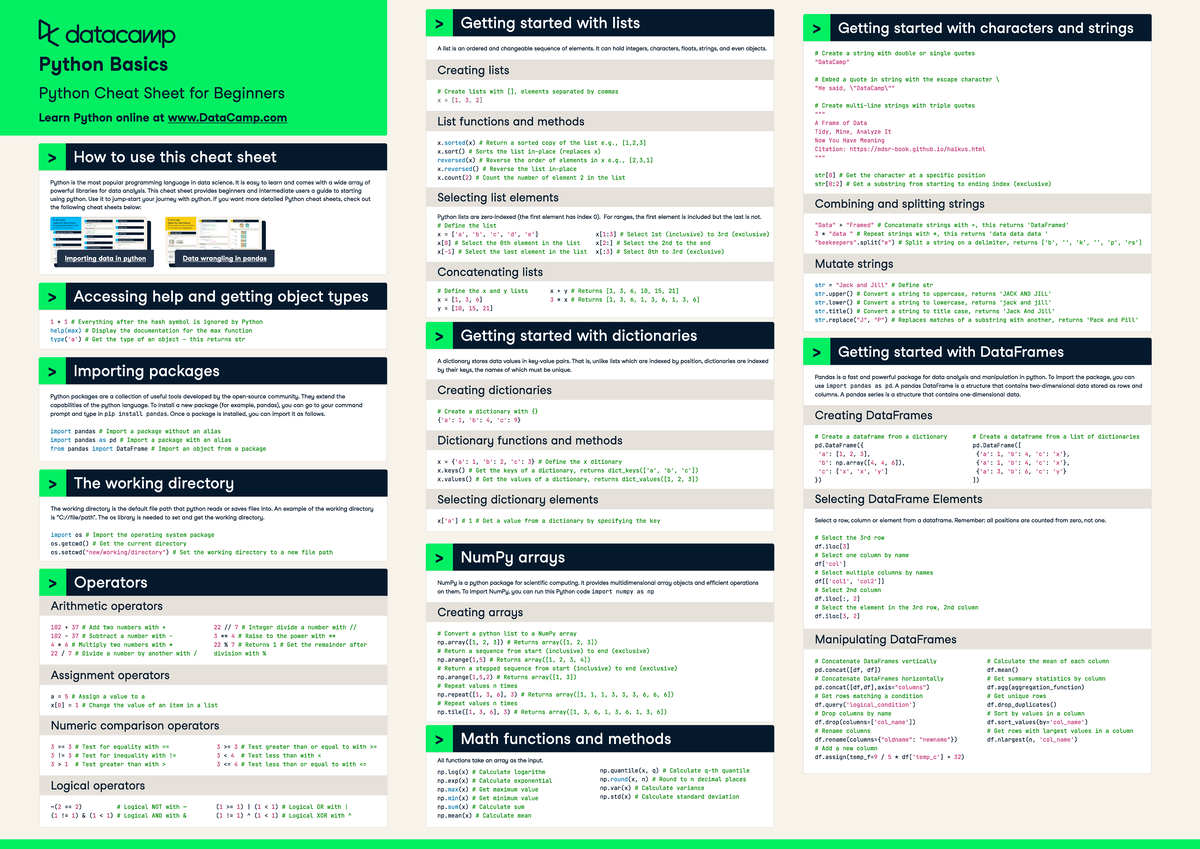
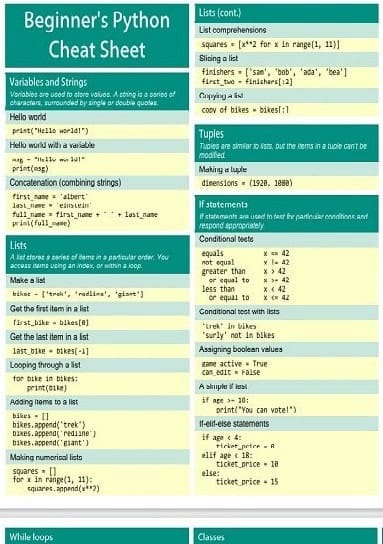
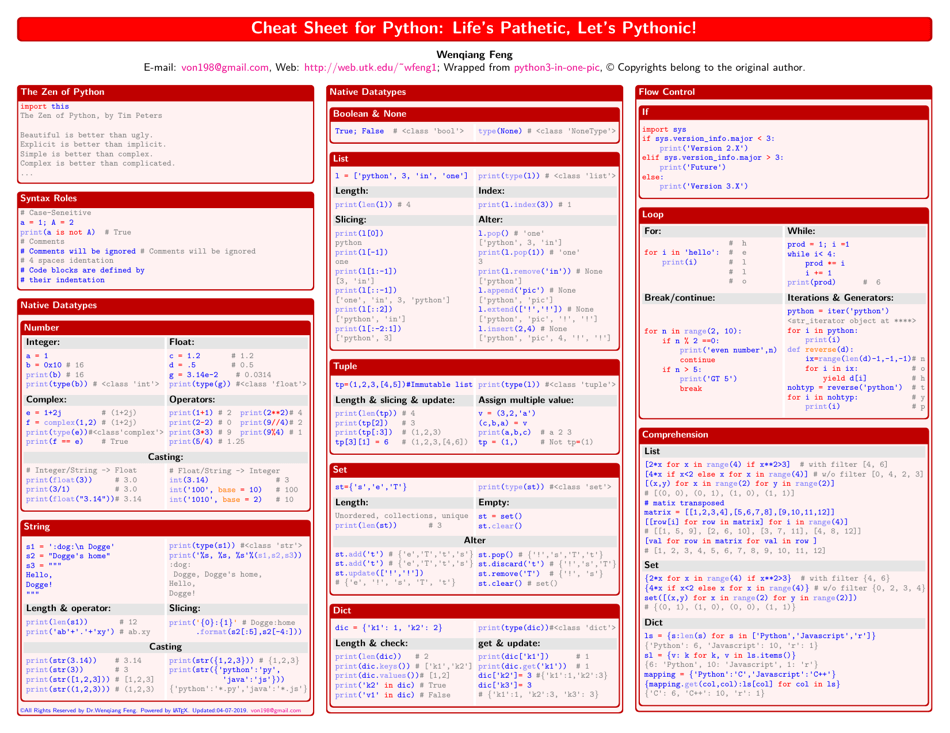
A comprehensive guide for Python cheat sheet should serve as a quick lookup tool, not a source of truth. The difference matters more than most people realize. When you are mid-deploy and need to remember whether `` binds tighter than `@` in decorator syntax, a well-organized reference can save you twelve minutes. When you blindly copy-paste without understanding the underlying mechanics, it can cost you an entire sprint.
Comprehensive Guide For Python Cheat Sheet: What Actually Works
Most cheat sheets cover the same surface-level material. Variable assignment. Function definition. List comprehensions. These are fine for recall, but they miss the places where Python actually bites people. I built my own reference after encountering a particularly nasty edge case with dictionary view objects in Python 3.8. The issue involved `dict_keys` not being hashable in a set comprehension the way I expected. The workaround required wrapping it in `tuple()` first, which took me about eight minutes to discover after thirty minutes of head-scratching.
Let me show you something most references skip. The `is` operator versus `==`. Cheat sheets usually present this as "use `is` for singletons, `==` for value comparison." That is technically correct. But it omits the part about small integer caching. Python caches integers from -5 to 256 by default. If you write `a = 257; b = 257; a is b`, the result will be `False` on most systems. A proper reference should mention the exact cutoff and explain why it exists.
Another counter-intuitive insight involves mutable default arguments. The classic trap is writing `def append_to(element, data=[])` and expecting a fresh list on each call. This is one of those things that catches everyone at some point. The workaround is straightforward: use `None` as the sentinel and assign inside the function body. Most people learn this lesson the hard way, usually in production, usually on a Friday afternoon.
Dictionary Comprehensions and Their Hidden Quirks
Dictionary comprehensions look elegant. They read naturally. But they have quirks that most cheat sheets do not mention. The order preservation in Python 3.7+ is guaranteed, but only because the language specification changed to reflect implementation behavior. Before that, order was an accident of the CPython interpreter, not a promise.
I encountered a specific problem involving dictionary comprehension with overlapping keys in a data pipeline. The result was subtly wrong because I did not account for the fact that later keys overwrite earlier ones in insertion order. The fix required restructuring the comprehension with a grouping step, which took about six minutes to implement after twenty minutes of debugging.
Decorators and Their Precedence Problems
Decorator syntax in Python uses the `@` symbol, but the precedence rules are not what most references explain. The expression `@decorator` is applied bottom-up, not top-down, which means the innermost decorator wraps the function first. This is one of those details that trips people up when they stack multiple decorators on the same function.
A practical rule for understanding decorator chains involves remembering that `functools.wraps` preserves the original function name and docstring. Without it, debugging becomes significantly harder because traceback information shows the wrapper function, not the actual function being called.
Common Pitfalls Most References Skip
List slicing with negative indices works in a predictable way, but the edge cases involve off-by-one errors that most people do not notice until their code fails in production. The exact behavior involves how Python handles slice bounds when the stop index exceeds the sequence length.
Generator expressions look memory-efficient, but they have a hidden quirk involving lazy evaluation that can cause unexpected behavior in nested function calls. The issue usually manifests when you pass a generator to `list()` inside a loop, which creates multiple generator objects instead of reusing a single one.
When Cheat Sheets Fail Completely
Some references claim certain patterns are universally applicable. They omit the part about GIL contention in multi-threaded Python code. This is one of those things that catches people by surprise, usually when they migrate from CPython to PyPy or another implementation.
The exact behavior involves how Python handles thread scheduling under different workloads. Some configurations work better with thread pooling, others with async I/O. There is no one-size-fits-all solution.
Practical Workflow for Reference Construction
Building your own reference takes about two hours for the first version, but usually cuts the lookup process down from twenty minutes per incident to about three minutes over time. The investment pays off quickly, especially when you encounter the same edge cases repeatedly across different projects.
Most people learn this lesson through experience, usually after spending an entire week debugging issues that a well-organized personal reference could have prevented. The key is to document the exact problem, the root cause, and the specific workaround, not just the surface-level pattern.
Gallery Comprehensive Guide For Python Cheat Sheet
Download Python Cheat Sheet: A Comprehensive Guide For Beginners And ...
Python Cheat-Sheet: Quick Reference Guide for Programmers | Python code ...
Python Cheat Sheet: Quick Guide for Beginners & Intermediate Users
Python Cheat Sheet PDF: Your Quick Reference Guide to Python ...
Cheat Sheet for Python Download Printable PDF | Templateroller