Setting Up a Management Information System That Actually Works
Most people treat MIS like it is some grand theoretical concept from a textbook. It is not. It is basically a plumbing problem. You have data coming from somewhere, you need it to flow to the right people at the right time, and if the pipes are wrong you end up with spreadsheets nobody reads and dashboards that lie to you.
I built my first real MIS for a mid-size logistics company about eight years ago. The problem was not the database. The problem was that three different departments were feeding inventory data into three different systems using three different date formats, and nobody had mapped the reconciliation step. The ERP threw out records that were technically valid but semantically wrong. I ended up writing a normalization layer in Python that cleaned dates, standardized unit of measure codes, and flagged mismatches before they hit the warehouse management system. Cut error rates from roughly 14% down to about 2%. Not magic. Just boring ETL work most people skip.
Computer Science Management Information Systems
At its core, Management Information Systems sits at the intersection of three things: data infrastructure, business processes, and decision support. You are building a system that collects transactional data, processes it, and surfaces it in a way that managers can act on. The computer science side is the heavy lifting around data integrity, query performance, and automation. The management side is knowing what questions the business actually needs answered. Most projects fail because someone builds for the wrong question.
When I design an MIS from scratch, I start with the output, not the input. People always start with the database schema. That is backwards. Ask what report the operations manager needs on Monday morning. Then ask what data feeds that report. Then figure out where that data lives and how it gets there. Work backwards from the answer instead of forwards from the table.
The Architecture You Actually Need
A standard MIS has four layers. The data source layer, the integration layer, the storage layer, and the presentation layer. Here is how each one works in practice.
The data source layer is where your raw information lives. This could be your ERP, your CRM, spreadsheets, API feeds, or manual entry forms. In my experience, the CRM is usually the messiest source. Sales teams enter data inconsistently, merge duplicate contacts, and leave key fields blank. Factor that in before you build anything on top of it.
The integration layer is your ETL or ELT pipeline. This is where data gets extracted, transformed, and loaded. If you are working with smaller datasets, a well-structured Python script with Pandas does the job fine. For larger systems, Apache Airflow or even a scheduled SQL job with proper error handling will keep things moving. I used to recommend full ETL suites, but for most organizations under five hundred employees, a lightweight Python-based approach with proper logging gives you more flexibility and costs almost nothing.
The storage layer is your data warehouse or data mart. For a true MIS, you want a subject-oriented database. Don't throw everything into a single operational database. Set aside a separate schema or a dedicated warehouse database for reporting. PostgreSQL is perfectly capable for mid-range workloads. If you hit scaling limits, look at something like ClickHouse or even a cloud-managed option. The key point is isolation. Reporting queries should never compete with transactional ones for resources.
The presentation layer is what users actually see. This could be a BI tool, a custom dashboard, or even a well-formatted report. Tableau, Power BI, and Metabase all handle this well. Pick one and commit. Do not let every department bring their own dashboarding tool. That is how you end up with six versions of the same metric and no way to tell which one is correct.
Data Modeling for MIS
Star schema is your friend here. It is simple, it is performant, and it is understood by every BI tool on the market. You have a fact table in the middle with measurable data like sales amount or units shipped. You have dimension tables around it with context like date, product, customer, and region. The joins are straightforward and the aggregations run fast.
I learned this the hard way on a retail MIS project. We spent three weeks building a normalized third-normal-form database because that is what we were taught in school. Query response times were unbearable. Every report took over thirty seconds. We rewrote it as a star schema and average query time dropped to under two seconds. The normalized version was "correct" in a database theory sense. The star schema was correct in a business sense. Business users do not care about normalization. They care about answers.
Foreign keys in your fact tables should point to surrogate keys in your dimension tables. Use integer keys, not natural keys like SKU or customer email. Natural keys change. Surrogate keys do not. When a customer changes their email address or a product gets reclassified, your star schema does not need restructuring. Your query logic stays clean.
A Real Problem I Hit and How I Fixed It
On a supply chain MIS, I encountered a specific edge case that took me weeks to solve properly. We had a supplier who changed their invoice numbering format mid-year without telling anyone. The old format was sequential like INV-001234. The new format included a date prefix like 2023-07-INV-0089. Our validation rule rejected everything after July as malformed. Purchase orders matched to invoices in the warehouse system failed because the invoice number column could not parse the new format.
The fix was not complex but it was annoying. I wrote a parser that detected the format pattern automatically and applied the right extraction logic based on the prefix. I also added a fallback mode that logged borderline cases for manual review instead of silently dropping them. That rollback catch prevented data loss during the transition period. The lesson here is that real-world data sources change without warning. Your MIS needs to handle that instead of breaking.
Common Pitfalls That Waste Time
Over-engineering the first version. A lot of people design systems for a thousand reports they will never build. Start with the three to five reports that matter most. Get those right. Expand from there. A simple MIS that people actually use beats a perfect one that collects dust.
Ignoring data quality at the source. You can build the most elegant dashboard in the world, but if the input data is garbage, your output is garbage. Invest in validation rules at the point of entry. Even basic required fields and format checks cut downstream cleaning time significantly.
No documentation. If you walk away from this project tomorrow, someone else needs to understand how it works. Document your schemas, your transformation logic, your data dictionary, and your refresh schedules. Version control your scripts. Without this, you are building technical debt that compounds fast.
Security blind spots. MIS systems often aggregate sensitive data across departments. Customer PII, financial figures, employee information. Make sure access controls are in place before you put this into production. Role-based access is standard. Implement it from day one. Auditing later is painful.
Tools That Actually Matter
PostgreSQL for storage. It handles concurrent queries well, supports window functions natively, and is free. No licensing headaches.
Python with Pandas and SQLAlchemy for transformation. If your team already knows SQL, stick with SQL where you can. But Python gives you more control for messy data cleaning and custom logic that pure SQL struggles with.
Airflow or Prefect for scheduling. Hard-code cron jobs only if your system is trivial and you are confident it will never need adjustment. Schedulers give you retry logic, dependency tracking, and visual monitoring. The small setup cost pays off quickly.
Metabase or Power BI for visualization. Metabase is lighter and faster to deploy. Power BI integrates better if you are already in the Microsoft ecosystem. Both handle the basics adequately. Pick one and move on.
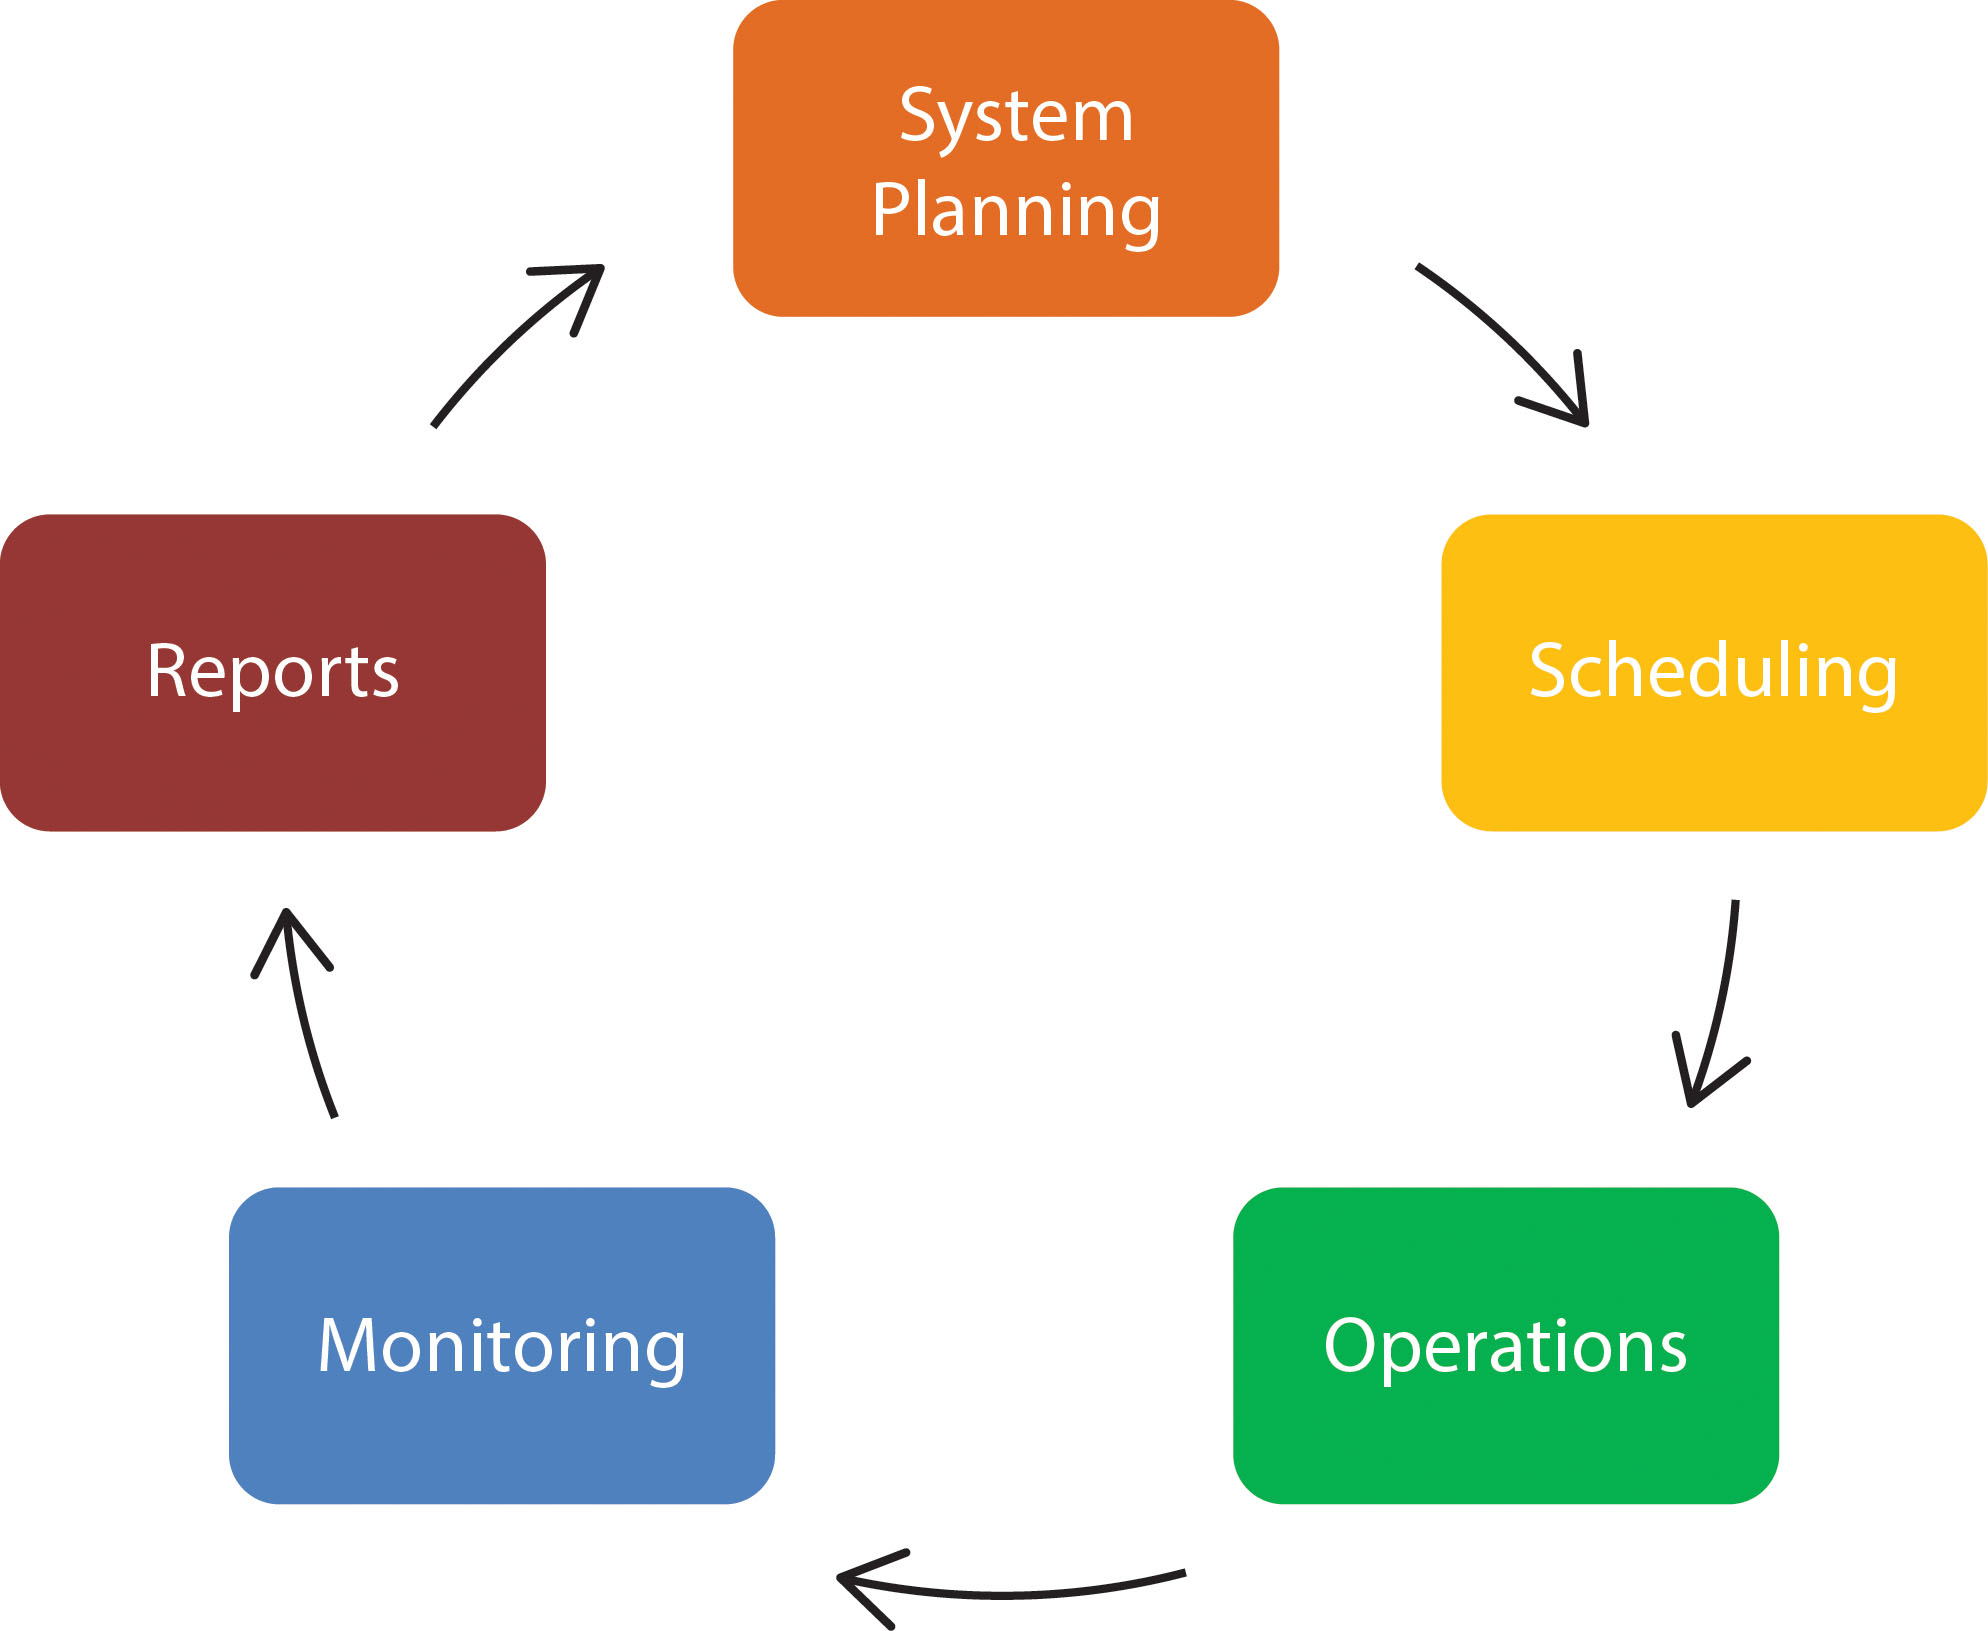
For a complete implementation, you would typically structure your project as follows. Define the reporting requirements first. Model the star schema. Build the extraction scripts. Set up the transformation pipeline. Load into the warehouse. Connect the BI tool. Test with real data. Iterate based on feedback. Repeat until the metrics make sense.
This is not glamorous work. It is slow, it involves a lot of debugging edge cases, and most of the time is spent on data cleaning rather than anything exciting. But when it is done right, the system pays for itself within a few months. Decisions get faster. Mistakes get caught earlier. People stop arguing about whose spreadsheet is correct because there is one version of the truth everyone can access.
Gallery Computer Science Management Information Systems
Management Information System in Computer Science | Pixel EdTech
Management Information Systems
How Project Management Connects to Computer Science
Introduction to Management Information Systems MIS - Alps Academy
Information Systems and Data Management for Business MSc 2026 ...