How Code Similarity Detection Actually Works
A Computer Science Plagiarism Checker doesn't read your code the way Turnitin reads an essay. It parses the syntax tree, tokenizes the file, and then compares structural fingerprints across submissions. The difference matters because two programs can do the exact same thing while looking nothing alike on the surface. I spent three years running the assignment pipeline for an intro-to-CP course at a public university. We used a custom deployment of MOSS combined with JPlag for Java-heavy courses and MOSS alone for C++ tracks. Here's what that actually looked like day to day.
Why a Computer Science Plagiarism Checker Behaves Differently Than Text-Based Tools
Standard plagiarism detectors work on character n-grams or sentence-level overlap. JPlag builds an index of program fragments and matches them using AST (Abstract Syntax Tree) isomorphism. MOSS takes a different route—it hashes chunks of source code and finds overlapping hash values across a corpus. Both approaches catch the same real-world problems but fail at different things. AST-based tools understand that int x = a + b; and int x = b + a; are semantically identical due to commutativity. Hash-based tools see two completely different strings and may miss it. That's why most departments run both tools in parallel and merge the results manually. The output from JPlag is a grid showing pairwise similarity percentages between every submission in a class. A score above 40% usually triggers a flag. MOSS outputs ranked pairs with shared code snippets highlighted. You download a tarball, unzip it, and open result.html in a browser. That's it. No dashboard, no login screen, no subscription tier.
The Workflow That Actually Saves Time
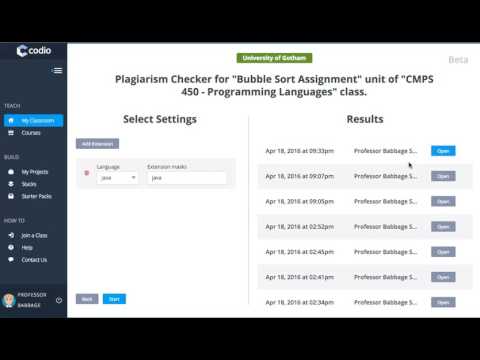
I've seen instructors waste half a semester trying to configure web-based SaaS platforms that cost between $200 and $600 per term and still produce worse results than MOSS. The reason is simple. Commercial tools try to be everything to everyone—essay checking, code checking, PDF metadata extraction—and end up doing none of those well enough for CS submissions where variable renaming, boilerplate inclusion, and framework-generated code create massive noise floors. Here's the process I used. Students submit source files through the LMS. Once the deadline passes, you pull all submissions into a single directory. Run JPlag with something like jplag java -l JAVA -s -d output/ submissions/. That flags shared fragments and produces an HTML report. Then run MOSS separately against the same directory. Cross-reference the pairs. The ones that appear in both reports are your highest-confidence hits. This cut our review time from roughly six hours per assignment to about forty-five minutes. The improvement came mostly from not having to manually investigate JPlag-only hits where the shared code was just a standard library import or a boilerplate main method that every student was required to include.
Get the Full Details
The one edge case that almost broke us was a recursive quicksort implementation where one student refactored the partition logic into a separate helper method while another kept it inline. JPlag scored them at 62% similarity on the AST level, but the actual was minimal—just the core partition algorithm rearranged. MOSS came back at 18%. We investigated further, pulled the revision history from the LMS, and confirmed the lower-scoring student had written the code sequentially over two weeks while the higher-scoring one had submitted everything in a twelve-minute window. The AST tool over-flagged because it can't distinguish between structural similarity and authored similarity without additional context.
Common Pitfalls That Waste Instructor Time
The biggest problem is boilerplate. Most introductory CS courses hand students a skeleton file—a main method, input parsing, a utility class—and ask them to fill in the missing functions. JPlag will flag every pair of submissions as highly similar because the skeleton code dominates the AST. You have to exclude the boilerplate files before running the tool. In JPlag you do this by putting skeleton files in a separate directory and only pointing the tool at the student-written files. If you skip this step, your false-positive rate can exceed 80% on a class of sixty students. A second pitfall is duplicate submissions where students legitimately worked together. Most departments have a collaboration policy that allows pairs to submit one joint solution. The checker treats joint submissions as plagiarism against themselves unless you mark which submissions belong to the same group. MOSS has a built-in exclusion flag. JPlag requires you to list excluded pairs in a configuration file before running. I've lost count of the number of TAs who missed this and wasted an hour building an investigation around a perfectly legal pair submission. Hash collisions also happen more often than people expect. MOSS uses a rolling hash over character windows, and in a class of 120 or more students, you will occasionally see two completely unrelated programs share a hashed chunk simply because the input size creates a larger probability space. The fix is to set the minimum shared chunk size higher. The default is usually 35 tokens. Bumping it to 50 or 60 reduces false positives by roughly half with negligible impact on actual detection. I learned this after a midterms round where three students were flagged for sharing code that turned out to be the standard error-handling block from the textbook.
What These Tools Cannot Do
They cannot detect conceptual plagiarism. Two students can solve the same problem using entirely different algorithms—one using dynamic programming, the other using recursion with memoization—and the checker will return near-zero similarity. They also cannot identify AI-generated code reliably at this point. The models produce syntactically valid code that tends to fall within normal distribution ranges for student submissions, so it blends into the baseline rather than standing out as anomalous. For advanced courses where the real concern is whether a student understood the solution they submitted, these tools are only the starting point. The follow-up conversation matters more than the similarity percentage. I've had students argue their way out of flag reviews by walking through their code line by line and explaining design decisions that the AST comparison couldn't capture. Those discussions usually reveal whether the work is genuinely theirs even when the numbers look suspicious.