Understanding Confidence Intervals on a Proportion: The Practical Side
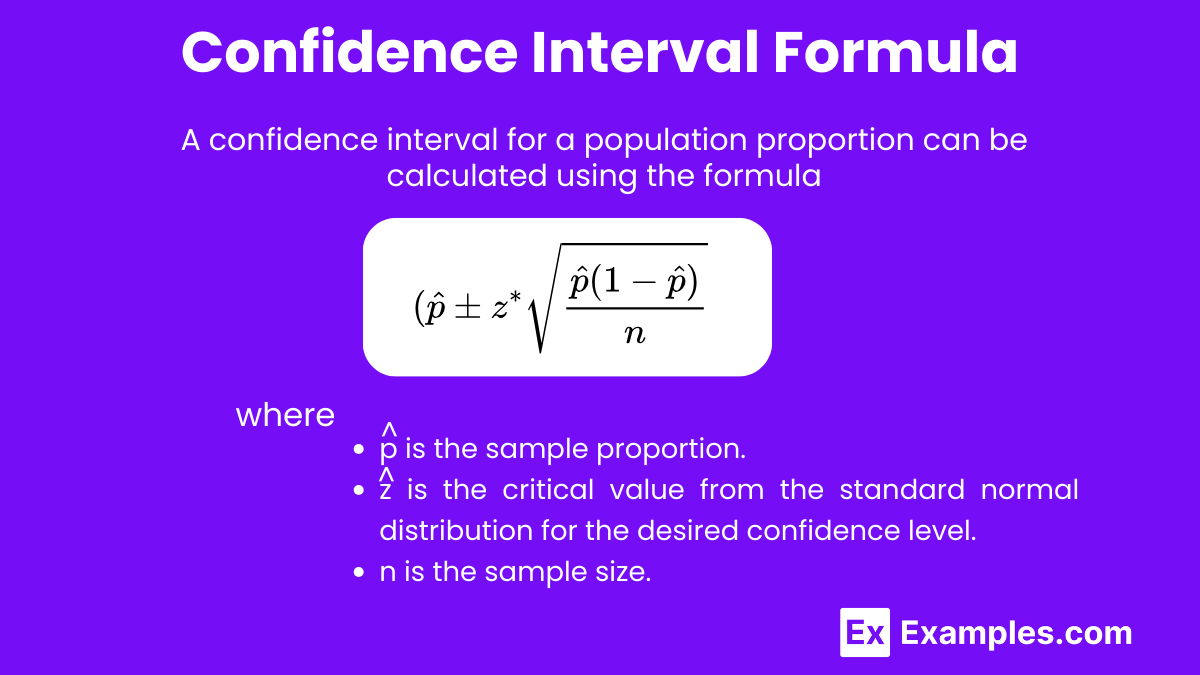
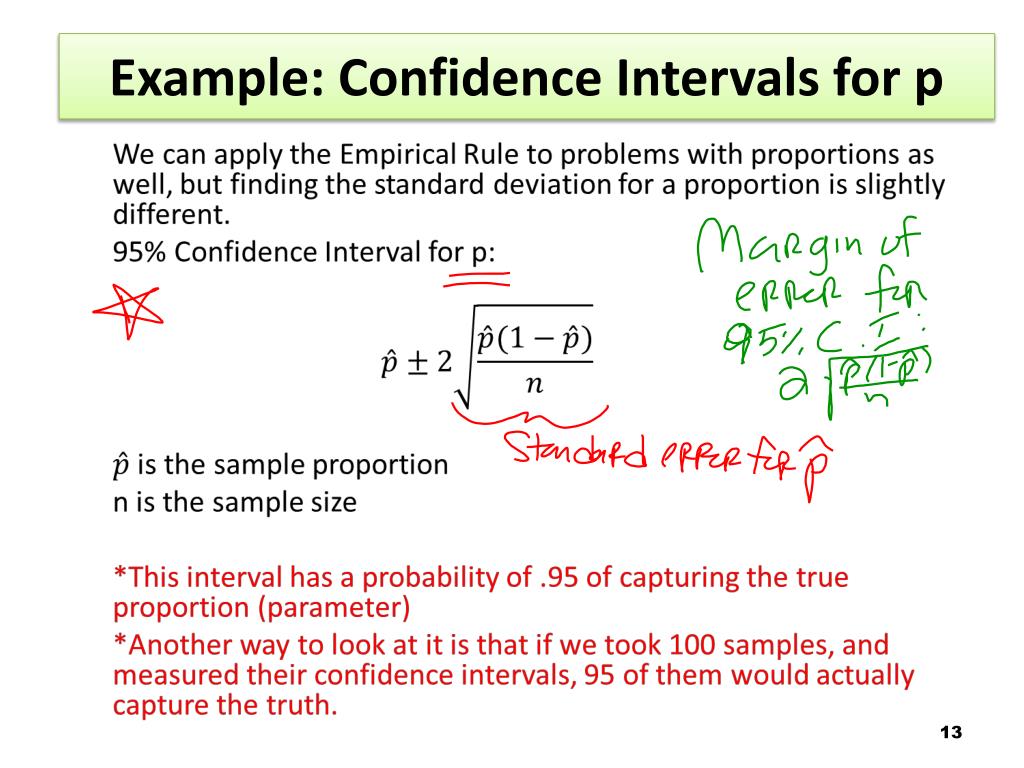
I deal with this stuff constantly, and honestly, the textbook approach works most of the time but falls apart in ways people don't expect. Let me walk through how to actually calculate one properly, what goes wrong, and why your default tool might be giving you garbage numbers without warning you. It's a range of values that likely contains the true population proportion, based on a sample. You take your sample proportion (p-hat = number of successes divided by sample size), apply a formula, and get an interval like 0.42 to 0.58. That's it fundamentally. The math behind it assumes your sample is large enough and random enough for the normal approximation to hold. When those conditions break, everything downstream breaks too. The standard Wald interval looks like this: p-hat plus or minus z times the square root of p-hat times (1 minus p-hat) divided by n. The z-value depends on your confidence level. For 95%, that's 1.96. Simple enough, but here's the thing nobody emphasizes: this formula is notoriously bad when p-hat is near 0 or 1, or when your sample size is small. I ran into this specifically last year working on a conversion rate analysis where the success rate was around 3%. I plugged it into the Wald formula and got a lower bound that was negative. A negative proportion. Obviously impossible, and the interval was wildly asymmetric around p-hat. The Wald method just doesn't respect the [0,1] boundary.
The workaround I ended up using was the Wilson score interval. It's not a huge jump in complexity but it handles edge cases far better. The formula is a bit messier but modern tools compute it without much effort. For my conversion rate example, the Wilson interval stayed cleanly within [0, 1] and gave a much more realistic range. If you're doing this by hand, there are online calculators that support Wilson, Agresti-Coull, and Jeffreys methods. Don't waste time trying to remember all the formulas—just make sure your tool supports the right one for your data.
Common Pitfalls That Wreck Your Results
Assuming normality without checking. The rule of thumb is that np-hat and n(1-p-hat) should both be at least 10. Some people use 5 as a cutoff, which is too loose for anything requiring precision. I've seen analysts apply the Wald interval to samples where the expected count was 7 successes out of 500. The resulting interval was asymmetric in a way the formula couldn't capture, and it was subtly wrong in a direction that made a business decision look more confident than it should have been. Ignoring the population size. If your sample is more than about 5% of the total population, you need a finite population correction factor. Otherwise your interval is too wide. I see this come up when companies analyze their own user base—say 20,000 users out of a total of 50,000—and they treat it as an infinite population. The correction shrinks the interval noticeably. Misinterpreting the confidence level. A 95% confidence interval does not mean there's a 95% probability that the true proportion falls in your calculated interval. The true proportion is fixed. What the confidence level means is that if you repeated the sampling process many times, 95% of the intervals you construct would contain the true value. This distinction matters when you're presenting results to stakeholders who will inevitably ask "so what's the probability it's in this range?" The answer is not what they think it is.
Get the Full Details

What to Use Instead When Conditions Break
Beyond the Wilson score interval I mentioned, there are other options worth knowing about. The Agresti-Coull interval adjusts p-hat upward by adding pseudo-successes and pseudo-failures before applying the Wald formula. It's a clever hack that performs well across a broader range of conditions than pure Wald. For Bayesian folks, the Jeffreys interval based on a Beta(0.5, 0.5) prior is another solid option that gives nice properties even with very small samples. Here's a counter-intuitive point that trips people up: wider intervals aren't always worse. If you're working with rare events and a tiny sample, a wider interval honestly reflects the uncertainty better than a deceptively narrow one from a method that's misfiring. I learned this the hard way when a client pushed back on my Wilson-based interval because it spanned 2 percentage points while their Wald calculator had produced a 0.5-point interval. The narrower one was wrong. The wider one was honest. One more thing that isn't obvious: if you're comparing two proportions, the interaction between their individual confidence intervals is not the same as the confidence interval for the difference. People sometimes check overlap between two separate intervals to assess significance, and that approach is unreliable. You need to compute the interval for the difference directly.
Tools That Actually Handle This Correctly
R's prop.test and binom package give you multiple methods out of the box. Python's statsmodels has proportion_confint which includes 'wilson', 'agresti_coull', 'beta', and 'normal'. In Excel, you're mostly on your own unless you build custom functions. I built a quick Google Sheets template that implements Wilson, Agresti-Coull, and Jeffreys with a clean input area, and I use it when someone needs a one-off calculation without opening R. If you need something similar, it takes about 20 minutes to set up once you have the formulas down, and it saves you from going back to flawed defaults every time. The takeaway isn't that the Wald interval is useless—it works fine when your sample is large and p-hat is somewhere in the middle of the range. But in practice, data rarely sits there neatly, and defaulting to Wald without checking assumptions is how you get intervals that look precise but aren't. Pick a method that respects your data's shape, verify your conditions, and move on.