Why Your Proportion Confidence Intervals Keep Looking Wrong
I spent about three years of my career dealing with survey data where the response rate was somewhere between 12 and 18 percent, and the confidence intervals for proportions came out either absurdly wide or completely nonsensical. The problem wasn't the math. It was the assumptions baked into the standard formulas most people reach for. Let's just get into how this actually works in practice. When you're estimating a proportion — say, the percentage of customers who churned, or the pass rate on a quality check — you're not dealing with a mean. You're dealing with a binomial distribution, and that changes what kind of interval makes sense.
Understanding Confidence Level For Proportion
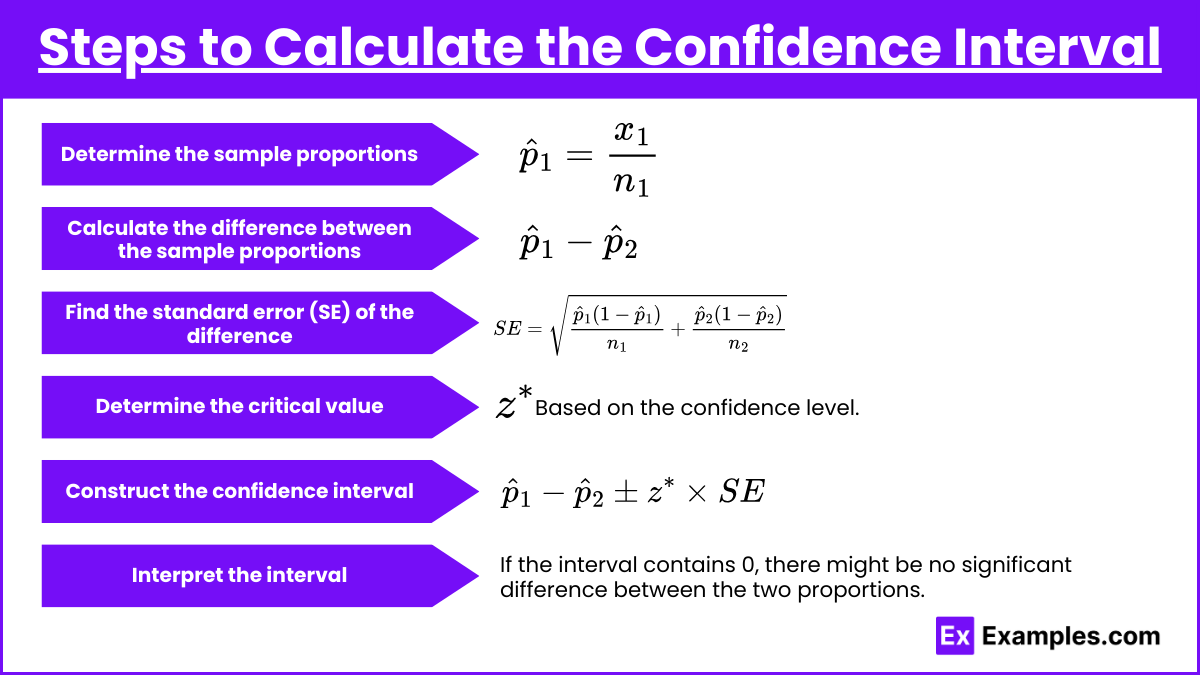
A confidence interval for a proportion gives you a range around your observed sample proportion where the true population proportion is expected to fall, with a stated level of confidence. The confidence level — usually 90, 95, or 99 percent — is your long-run coverage guarantee. If you constructed 100 such intervals from 100 different samples, roughly 95 of them would contain the true parameter, assuming everything behaves as the model says. The basic formula most people learn first is the Wald interval: p-hat plus or minus z-star times the square root of p-hat times one minus p-hat, all divided by n. It's clean on paper. It falls apart in practice whenever your sample proportion is close to zero or one, or when your sample size is small. I learned that the hard way on a project where p-hat was 0.02 and n was 150, and the resulting interval stretched from negative 0.01 to positive 0.06. Negative proportion. It doesn't exist. Here's the practical thing most guides don't tell you: the Wald interval's actual coverage probability can be dramatically lower than the nominal confidence level, especially in the tails. With n=150 and p=0.02, a 95 percent Wald interval might actually cover the true parameter only 80 or 85 percent of the time. That's not a rounding error. That's a systematic underestimate of uncertainty.
What Actually Works
For anything with moderate to small sample sizes or proportions outside the 0.2 to 0.8 range, the Agresti-Coull interval is your best default. It's sometimes called the "plus-four" method because you add two successes and two failures to your data before computing the interval. You adjust p-hat by adding four to the denominator and two to the numerator, then apply the standard formula with that adjusted proportion. The effect is modest but it stabilizes the variance estimate considerably. With n=150 and 3 successes out of 150, the Wald interval gives you roughly 0.02 ± 0.03, which includes negative values. The Agresti-Coull approach adjusts to 5 out of 154, giving p-tilde of about 0.032, and the interval comes out to roughly 0.032 ± 0.025, or [0.007, 0.057]. No negative garbage. Much more reasonable coverage. For very small samples — say fewer than 30 observations or when you have fewer than 5 successes or failures — the Clopper-Pearson exact interval is the conservative choice. It's based directly on the binomial cumulative distribution function rather than a normal approximation. The downside is that it's genuinely conservative: a 95 percent Clopper-Pearson interval often has actual coverage well above 95 percent, sometimes 97 or 98, which means it's wider than it needs to be. You pay for that safety with precision.
Get the Full Details

The Jeffreys interval, derived from a Bayesian analysis with a Beta(0.5, 0.5) prior, sits somewhere between Agresti-Coull and Clopper-Pearson in terms of width and coverage accuracy. It's not as commonly implemented in standard statistical software packages, but it performs very well across a wide range of scenarios. I tend to use it when I'm writing custom analysis scripts because it handles edge cases gracefully without requiring exact distribution calculations.
How to Choose
The decision tree I actually use is simpler than what the textbooks present. If n is at least 30 and both the expected number of successes and failures are at least 5, the Wald interval is acceptable for rough work. It's what every quick analysis produces by default, and when the conditions hold, its coverage is close enough to the nominal level that the difference rarely matters in practice. If either condition fails, switch to Agresti-Coull. This covers the vast majority of real-world situations — survey research, A/B test conversion rates, defect detection in manufacturing batches. It's a one-line adjustment and it fixes the main problem. If n is below 30 or you're working with extremely rare events, go Clopper-Pearson for regulatory or compliance work where overcoverage is acceptable, or Jeffreys for general analysis where you want tighter intervals without sacrificing much coverage accuracy.
There's one more thing I wish more people understood about confidence level for proportion calculations: the confidence level and the interval width are not independent. Moving from 95 percent to 99 percent confidence doesn't just add a small buffer. The z-star multiplier jumps from 1.96 to 2.576, which increases the half-width by about 32 percent. For a proportion of 0.5 with n=200, the 95 percent Wald half-width is approximately 0.069, while the 99 percent version is about 0.091. That's a substantial difference in interpretability, especially when your stakeholders are making decisions based on whether an interval crosses a decision threshold.

Common Mistakes
The most frequent mistake I see is mixing up the confidence level with the p-value. They're related through the same z-distribution but answer fundamentally different questions. A 95 percent confidence level means the procedure covers the true parameter 95 percent of the time in repeated sampling. A p-value of 0.05 means the observed data would be unusual under the null hypothesis. People conflate them because the numbers look the same, and then they misinterpret what their interval is actually telling them. Another issue is treating the interval as if it describes where individual data points fall. A confidence interval for a proportion describes uncertainty about the population parameter, not variability in the sample. Saying "we're 95 percent confident the true proportion lies between these values" is technically closer to the truth than saying "95 percent of the data falls in this range," but even the standard phrasing is often misunderstood by anyone who isn't familiar with frequentist inference. Weighted survey data also deserves a mention. If you're working with complex survey designs — stratified sampling, clustered sampling, unequal probability weighting — the standard proportion formulas are wrong. You need to account for the design effects, which inflate the variance. A design effect of 2, which is common in clustered samples, means your interval should be roughly sqrt(2) times wider than the simple random sample formula suggests. I've seen people report precision that was off by a factor of 1.4 to 2.0 because they ignored this entirely.
A Quick Reference
For the Agresti-Coull adjustment, compute p-tilde as (X + 2) / (n + 4), where X is the number of successes. Then the interval is p-tilde plus or minus z-star times the square root of p-tilde times one minus p-tilde, all over n + 4. The z-star values are 1.645 for 90 percent, 1.96 for 95 percent, and 2.576 for 99 percent confidence. For Clopper-Pearson, you compute the lower bound using the inverse beta distribution: Beta_inv(alpha / 2, X, n - X + 1) and the upper bound using Beta_inv(1 - alpha / 2, X + 1, n - X). Most statistical software has built-in functions for this. In R it's binom.test, in Python you'd use scipy.stats.beta or the statsmodels proportion confidence interval routines. The bottom line is that the standard Wald interval is adequate for large samples with moderate proportions, but it's the wrong tool for most real data. Agresti-Coull is a trivial modification that gives you far better behavior across the board. Clopper-Pearson is your safety net for small samples, and weighted data requires its own treatment entirely. Pick the method that matches your data structure rather than defaulting to whatever your software spits out.