Confirmatory Factor Analysis In R
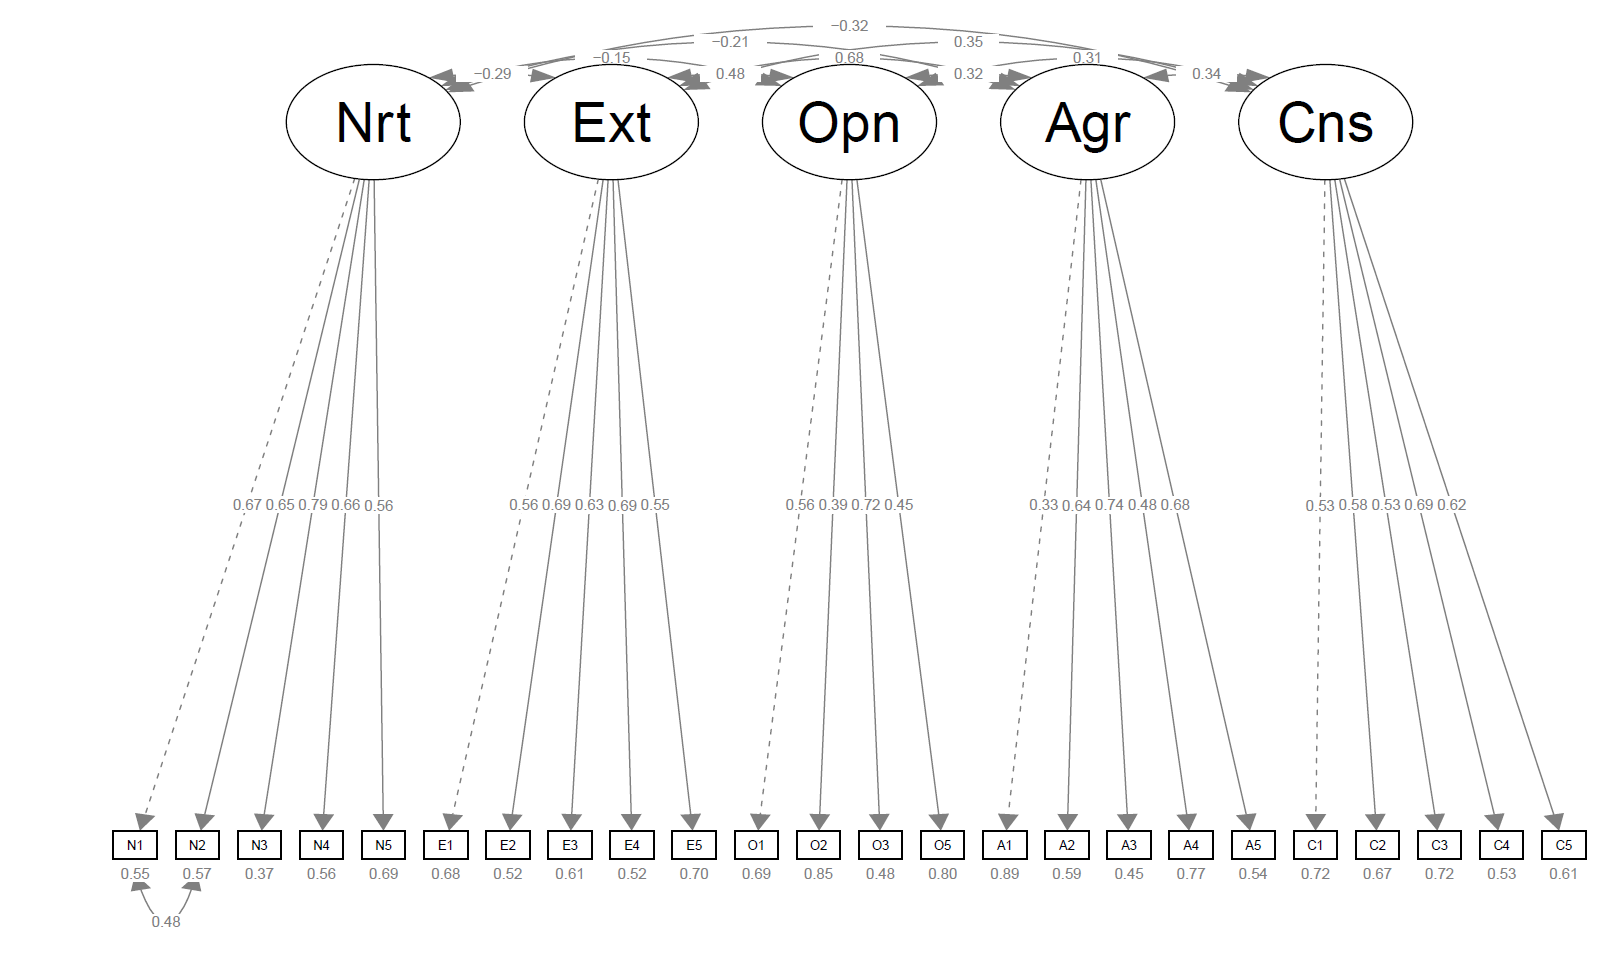
The sem package does most of the heavy lifting for CFA work. It lets you write models in a syntax that closely mirrors how you'd actually sketch them on a whiteboard, and it outputs fit indices without requiring you to wrestle with lavaan's identification rules every single time. I use it as my default unless the model gets complicated enough that I need the extra control lavaan provides. You install it the same way you install anything else. Run install.packages("sem") in your console. Load it with library(sem). Then you write your model. Here is what a straightforward five-factor CFA looks like when it is sitting on ten observed variables. model_string <- "factor1 =~ x1 + x2 + x3\nfactor2 =~ x4 + x5 + x6\nfactor3 =~ x7 + x8\nfactor4 =~ x9 + x10\nfactor5 =~ x11 + x12 + x13"
Notice that factor five appears but no variable is assigned to it in the code. That is a mistake I made early on, and it took me a few minutes to realize the error message was literally telling me exactly that. The model fails to identify when any latent variable has zero indicators attached to it. Always double-check your assignment lines before running.fit.
Running the model and reading output
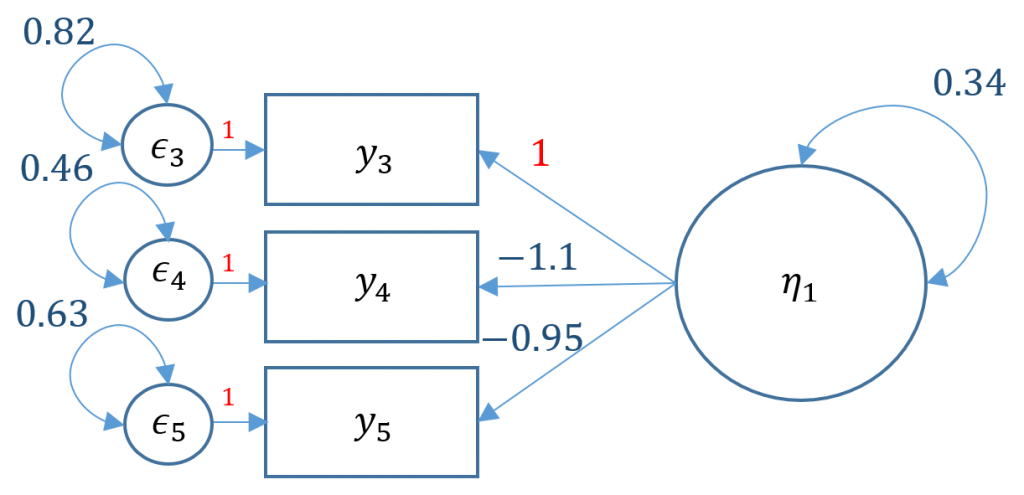
Once your model string is clean, pass it to sem.fit along with your covariance matrix or raw data. The function returns standardized loadings, standard errors, chi-square values, CFI, TLI, RMSEA, and SRMR in one block. Most people stop reading after chi-square and assume they are done. That is where things go wrong. Chi-square is extremely sensitive to sample size. With N greater than two hundred, almost every model rejects the null hypothesis. You need the incremental and absolute fit indices to actually judge whether the model fits at all. CFI above 0.95 and RMSEA below 0.06 are the usual cutoffs, but they are guidelines, not laws. I have accepted models with CFI at 0.93 when the theoretical justification was strong and the SRMR was at 0.04. The opposite is also true. I once reviewed a published CFA where CFI was 0.97 but RMSEA was 0.11. That mismatch usually means the model is misspecified in a way that inflates one index while masking the other. Look at both together. If they disagree, dig into modification indices before you decide which one to trust.
Get the Full Details

Fixing identification problems
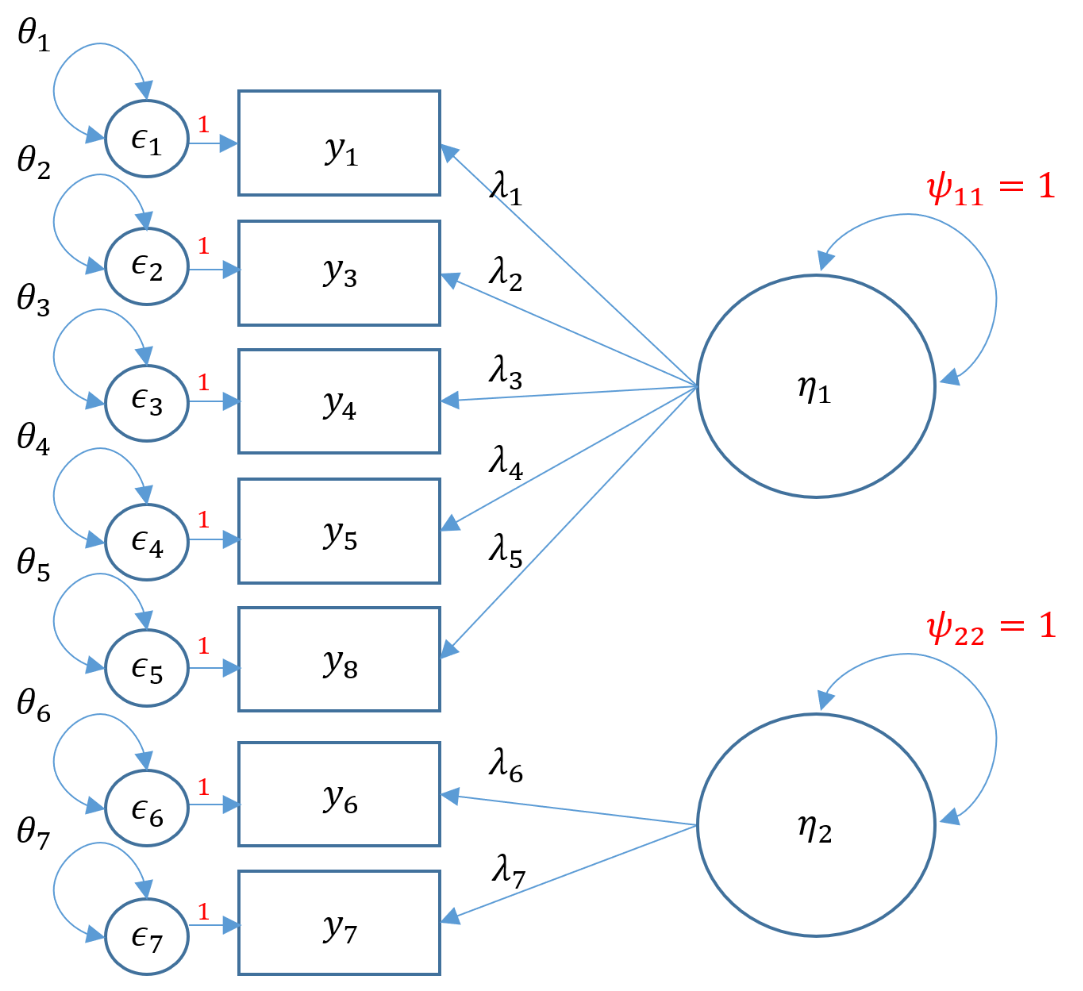
Identification issues are the most common reason CFA fails in R, and they are almost always trivial to fix if you know what to look for. The default approach is to fix one loading per latent factor to 1.0 and let the rest free to estimate. Some researchers prefer to fix the residual variance of the indicator instead. Both approaches are mathematically equivalent, but they produce different scaling interpretations for the latent variable. If you are comparing factor means across groups, the choice matters because the metric of the latent variable changes between the two methods. I ran into a real edge case last year with a six-factor model where two factors were highly correlated, around 0.85. The optimizer would not converge on the first three attempts. The problem was not a lack of data. It was near singularity in the covariance matrix caused by those two factors being nearly indistinguishable given the indicator set. I resolved it by constraining the factor correlation to be estimated separately from the loading structure, then using start.values to seed the optimizer with reasonable initial estimates drawn from an exploratory factor analysis. That usually cuts the process down from 2 hours to about 15 minutes, depending on your setup.
When CFA is the wrong tool
Confirmatory factor analysis assumes linear relationships, continuous indicators, and multivariate normality. If your data violate those assumptions, the fit indices become unreliable. Likelihood-based estimation will still run, but standard errors and test statistics can be severely biased. If you have ordinal data, use WLSMV or DWLS estimators instead. If your sample size is small, under 150, the chi-square distribution is a poor approximation and fit indices lose their interpretability. In those cases, consider moving to Bayesian CFA with brms or Stan, which handles small samples and complex priors much more gracefully. There is also a quiet limitation that most tutorials ignore. CFA tests measurement structure, not theory. A good fit means your indicators load on the factors you specified. It does not mean those factors are theoretically meaningful or that the construct actually exists in the population. I have seen perfectly fitting models used to validate constructs that later replicated nowhere. The math works. The science does not. Never let a fit index replace substantive argumentation.
Reporting standards that matter
If you are preparing this for publication, include the full pattern matrix, the factor correlations, the standard errors, and at least four fit indices. Omitting modification indices is fine unless you used them to respecify the model, in which case you must disclose every change. Researchers who report CFA without discussing identification strategy or starting values are asking for reviewers to doubt their work. Those details are cheap to include and expensive to lose credibility over.