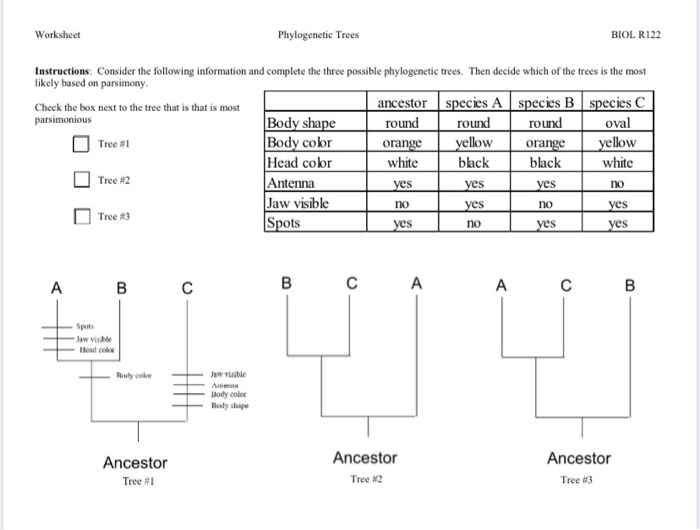
Phylogenetic trees are not as straightforward as people assume, and building one requires more than just running a tool and calling it done
I have spent years watching students and early researchers treat tree construction like a black-box exercise. You paste sequences into a program, click build, and suddenly you have a diagram. The problem is interpreting what that diagram actually means and catching the errors that happen before the visualization appears. A Constructing A Phylogenetic Tree Worksheet helps you document each step so you are not making assumptions you cannot defend later. The most common starting point is a multiple sequence alignment. I usually recommend Clustal Omega or MAFFT for this, depending on your sequence count. MAFFT handles larger datasets faster, but Clustal Omega gives you a cleaner interface if you are working with fifty sequences or fewer. Once your alignment is ready, you need to trim poorly aligned regions. This is where most mistakes creep in. A poorly trimmed alignment will produce a tree that looks reasonable but is built on noise rather than signal. For trimming, Gblocks or trimAl are standard choices. Gblocks is stricter and removes more ambiguous sites, which can be too aggressive for conserved gene families. trimAl has several modes. The automata1 mode is a good middle ground for most vertebrate datasets. I learned this the hard way when I was working on a mitochondrial genome alignment and Gblocks removed nearly forty percent of my sites. The resulting tree had terrible resolution and collapsed nodes everywhere. Switching to trimAl with the gappyout setting recovered most of the signal and gave me a much cleaner topology.
After alignment and trimming, the next decision is the substitution model. Model selection is not optional. Using the wrong model can push your tree in the wrong direction without you ever noticing. jModelTest for nucleotide data or ModelFinder built into IQ-TREE are the go-to tools here. IQ-TREE's ModelFinder is faster and does it on the fly, which saves time during iterative runs. The output will tell you something like TIM2+I+G4 or WAG+I+G. You use that string in your downstream tree-building step. There are three main methods to actually build the tree: maximum parsimony, maximum likelihood, and Bayesian inference. Each has a specific use case. Maximum parsimony works for small datasets where computational speed matters and homoplasy is low. It breaks down quickly with longer branches or divergent sequences because it does not account for multiple substitutions at the same site. Maximum likelihood is the workhorse for most modern studies. IQ-TREE, RAxML, and PhyML are the main programs. Bayesian inference using MrBayes or BEAST is the most computationally expensive option but gives you posterior probabilities instead of bootstrap values. If you need a quick tree for a class assignment, maximum likelihood with 1000 ultrafast bootstraps in IQ-TREE is usually sufficient and takes about ten to twenty minutes on a standard laptop for a dataset under two hundred sequences. One thing beginners consistently miss is that bootstrap values below seventy percent are essentially uninformative. A node with a sixty-five percent bootstrap support is not "weakly supported." It is saying the data cannot resolve that particular split. I have seen papers where authors treat fifty percent nodes as meaningful relationships. They are not. If your bootstrap values are that low across most nodes, the real problem is usually the alignment, not the tree-building method. Go back and check your alignment coverage and taxon sampling.
When you actually run the tree construction, keep track of every command and parameter. I use a simple markdown or plain text log file. Write down the alignment program, the trimming tool and its settings, the model selected, the tree-building program, the number of bootstrap replicates, and the version numbers. Someone reading your worksheet later needs to reproduce your result, and they cannot do that if you wrote "used ModelFinder" without noting which version or dataset it was run on. Visualization comes after. FigTree is free and adequate for basic editing. For publication-quality figures, iTOL is easier to use and handles larger trees better. Both accept Newick format, which is what IQ-TREE, RAxML, and most other programs output. Make sure you label your outgroup correctly. An incorrectly placed outgroup reverses the direction of your entire tree and makes every relationship look backwards. This is an easy mistake to make when you are tired and rushing to finish a worksheet.
Get the Full Details

Edge cases and what to do when the tree makes no sense
Long branch attraction is the classic problem. Two sequences that are highly divergent from everything else will cluster together artificially, even if they are not closely related. This happens because the model interprets multiple independent substitutions as shared derived characters. The fix is either adding more taxa to break up the long branches or switching to a model that accounts for rate heterogeneity across sites. The +G component in your model addresses this partially, but adding representative sequences is the more reliable solution. Another issue that comes up frequently is incomplete lineage sorting. This is especially common in recent radiations where species diverged quickly. Your gene tree will not match the species tree, and no amount of bootstrap support will fix this. The workaround is using multiple unlinked loci and coalescent-based methods like ASTRAL. If you are only working with a single gene, acknowledge this limitation explicitly in your worksheet notes rather than presenting the tree as species-level truth. Sometimes your sequences have contamination or mislabeled entries. I ran into this once when a colleague submitted what they thought was a nuclear gene sequence and it turned out to be a mitochondrial pseudogene. The tree placed the sample deep inside a completely different clade, and the bootstrap support was ninety-eight percent. The tree was internally consistent but based on wrong data. Always verify your sequences against the source database before alignment. A quick BLAST search takes five minutes and can save you hours of confused analysis.
Common mistakes that waste time
Using default settings without checking what they are. RAxML defaults to GTRGAMMA, which is fine for many datasets but not all. If your data has strong base composition bias, this model will mislead you. Check your composition with Chi-square tests before committing to a model. iqtree has the -m MFP option which runs modelFinder automatically, but you still need to verify the model makes biological sense for your markers. Neglecting to root your tree properly. An unrooted tree shows relationships but not evolutionary direction. If your worksheet requires a rooted tree, select an appropriate outgroup that is closely related enough to align but distant enough to sit outside your ingroup. Too close and it becomes part of your clade. Too distant and you invite long branch attraction. Overinterpreting topology. A single tree from a single gene is a hypothesis, not a fact. Different genes from the same organisms can produce different topologies due to horizontal transfer, hybridization, or other biological processes. Your worksheet should reflect this uncertainty. Note when results are congruent across genes and when they are not. Honest documentation matters more than a pretty picture.
Practical workflow summary
Start with raw sequences in FASTA format. Align with MAFFT or Clustal Omega. Trim with trimAl. Run ModelFinder in IQ-TREE. Build the tree with maximum likelihood and 1000 ultrafast bootstraps. Inspect bootstrap values critically. Visualize in iTOL. Document every step with program names, versions, and parameters. Verify your outgroup. Repeat if bootstrap values are consistently low or topology contradicts known biology. This workflow typically takes between forty-five minutes and two hours depending on dataset size and your familiarity with the tools. The first time through, expect closer to two hours. After a few repetitions, you can cut that down significantly. The Constructing A Phylogenetic Tree Worksheet is not about filling in blanks to get a grade. It is about building a record of decisions that someone else can evaluate and reproduce. Phylogenetics is error-prone by nature. The data is always incomplete, the models are always approximations, and the trees are always hypotheses. Your worksheet should make that clear rather than hiding it behind a well-supported-looking diagram.


