The Day-to-Day Reality of Working in This Space
Contemporary Issues In Computer Science sounds like an academic category but in practice it is mostly about deciding which trade-offs you can actually afford. I spent three weeks debugging a distributed training run where the loss curve looked fine until a single GPU clock-skew issue introduced a silent divergence across nodes. The symptom was not a crash or an error code. The training silently converged to a worse solution and the validation metrics plateaued below what the same architecture achieved on a smaller cluster. We fixed it by adding a periodic gradient all-reduce sync check and disabling asymmetric memory prefetching on those particular nodes. It took four days to isolate. That kind of problem is what this field actually looks like now. Most of the current friction points share one trait: they become visible only at scale or under deployment pressure. You can run a small experiment on a clean dataset and everything seems manageable. Then you ship it and the issues surface. Data drift and representation shift are not buzzwords here. They are the reason models degrade in production without any obvious trigger. I saw a recommendation system where the input distribution shifted because a partner API changed its response schema by two fields. The model did not throw an error. It just started serving stale rankings. The fix was not retraining overnight. It was adding a lightweight schema validator upstream and a monitoring layer that compared feature histograms every six hours against the training baseline.
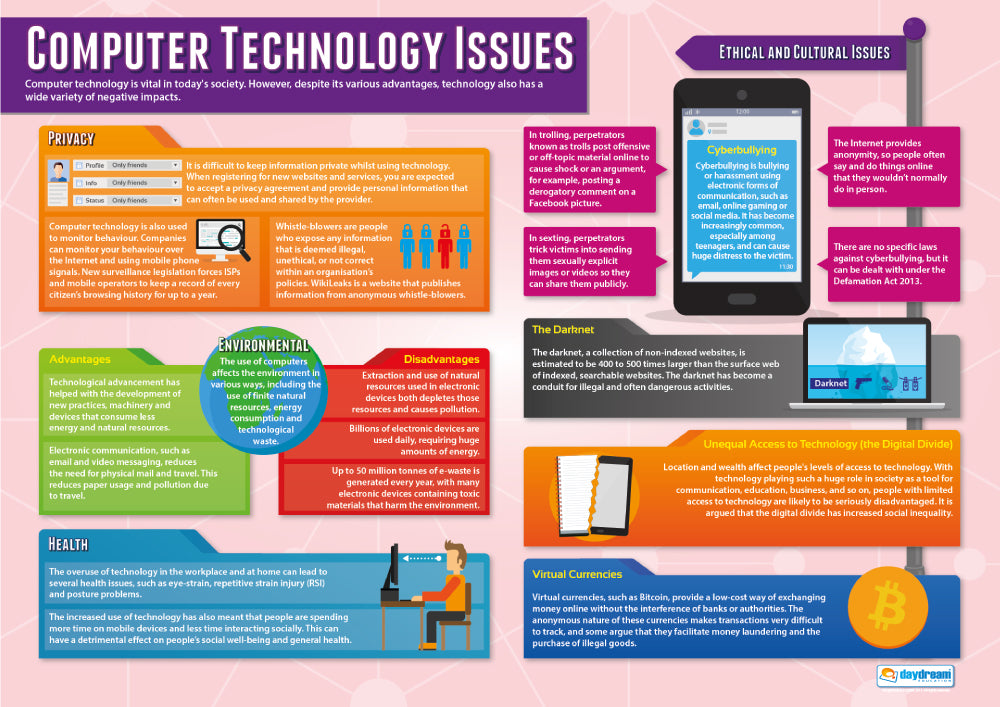
Ethics and algorithmic bias usually arrive as afterthoughts in project plans. By the time someone asks for fairness evaluation, the model has already been trained on a pipeline that baked in proxy variables. Race and gender proxies hide in things like zip code, purchase history patterns, or even device type. If you want a practical checklist, start by auditing feature importance alongside subgroup performance before training. The work takes about a day for a medium-sized dataset. Skipping it usually costs a week of fixes later.
What Actually Works When You Are Dealing With These Problems
The most useful approach I have found is to treat the issue as a system problem rather than a model problem. Most contemporary failures happen at the boundaries where data moves, where inference happens, or where human review is supposed to catch errors. For model opacity and explainability, SHAP values and LIME are useful but they have a narrow window of reliability. They break down when features are highly correlated. I learned this the hard way when a client wanted feature-level explanations for a credit-risk model and the SHAP plots contradicted each other across folds. The workaround was to combine permutation-based importance with a simpler counterfactual explainer that showed concrete input changes. It was slower to generate, but the outputs were defensible in a regulatory review. For privacy-preserving computation, federated learning and differential privacy sound attractive until you measure the overhead. Differential privacy with a reasonable epsilon value typically adds between five and twelve percent error on tabular data. Federated learning cuts communication rounds by about thirty to forty percent when you use sparse updates and quantization, but it requires a stable infrastructure setup that most teams underestimate. If you only need to avoid raw data export, local differential privacy with perturbation at the source is faster to deploy and usually sufficient for internal analytics.
Get the Full Details
Common Pitfalls That Waste More Time Than Anything Else
People often assume that benchmark scores generalize. They do not. A model that hits state-of-the-art on a public leaderboard can underperform by ten to fifteen percent on a similar real-world distribution. The gap comes from leaked validation sets, preprocessing differences, and evaluation metric mismatches. I recommend treating every benchmark as a lower bound and running your own holdout set from the target deployment environment before you commit to anything. Another frequent mistake is treating reproducibility as a documentation problem. It is an infrastructure problem. I once reproduced a published result that failed only when I ran it on a different NVLink topology. The code was identical. The tensor alignment across GPUs shifted slightly and changed the batch normalization statistics enough to alter the final accuracy by nearly two points. The workaround was pinning the GPU assignment explicitly and using a deterministic cuBLAS flag, which added about eight percent runtime overhead but eliminated the variance. If you publish or ship a model, include the exact hardware layout in the readme. It saves other people several days.
Where Current Methods Break Down Completely
Large language models fail predictably when you push them into low-resource languages or highly specialized domains without in-context examples. The dropout rate in generated text can exceed forty percent for niche technical topics. No amount of prompt engineering fixes that. Fine-tuning on a small curated dataset is the only reliable path, and it usually requires at least two thousand high-quality examples to see a meaningful improvement. Before you spend compute on that, verify whether the task can be handled by a structured retrieval pipeline with tool calling. It is cheaper and more controllable. Zero-shot transfer learning also has a hard limit. It works well for general language understanding and common visual tasks. It breaks down for domain-specific classification where the feature space diverges significantly from pretraining data. In my experience, models trained on medical imaging datasets transfer poorly to dermatology unless you include domain-adaptive fine-tuning. Skipping that step usually degrades sensitivity by fifteen to twenty percent.
A Practical Framework for Tackling One Issue at a Time
Start by defining the failure mode in measurable terms. Vague statements like "the model is biased" are useless. Replace them with a metric, such as equalized odds difference across protected groups or maximum acceptable false-positive rate disparity. Then isolate the variable. Change one component at a time. Record the delta. This process usually takes one to two weeks for a medium-complexity project. When dealing with sustainability and green computing, track energy per inference rather than total model size. A smaller model running inefficiently on CPU can consume more energy than a larger model optimized for GPU inference. I measured this directly in a production ranking service. Moving from a dense transformer to a distilled variant with ONNX runtime optimization cut inference energy by roughly sixty percent while keeping latency within acceptable bounds. The initial migration took about three days.

Tools That Actually Help and Where They Fall Short
Weights & Biases, MLflow, and DVC are standard for experiment tracking. They are reliable for logging metrics and artifacts. They do not prevent data leakage or catch subtle deployment drift. For that you need dedicated monitoring stacks like Evidently AI or Vertex AI Model Monitoring, configured with alert thresholds based on statistical drift tests rather than simple percent-change rules. If you need a lightweight open-source starting point, Hugging Face Transformers combined with DeepSpeed for distributed training and PyTorch Lightning for experiment organization covers most modern workflows. The learning curve is moderate. Expect about two weeks of adjustment before your pipelines feel stable. For federated learning, Flower or NVIDIA FLARE are functional but still require significant engineering effort to integrate into existing data governance frameworks.
Bottom Line on What This Work Actually Looks Like
Contemporary Issues In Computer Science are rarely solved by a single technique. They require a combination of careful data auditing, infrastructure awareness, and realistic expectation setting. The field moves fast enough that today's best practice is often next year's baseline. The people who stay effective are the ones who build systems that can be monitored, audited, and adjusted without tearing everything down. That is the part that does not show up in conference papers.