The Reality of Running PDCA Cycles Without Losing Your Mind
I used to run quality management systems for a mid-size manufacturing operation. We had 47 active corrective action reports at any given time and a turnover rate that made retention feel like a losing bet. The problem wasn't the framework. It was the gap between how PDCA was supposed to work on paper and how it actually played out when someone's job depended on shipping 2,000 units before 5 PM. Continuous Improvement In Quality Management is often presented as a straightforward loop: Plan, Do, Check, Act. That's technically correct and entirely useless if you've never watched a team burn through three improvement cycles only to realize they were optimizing for a metric nobody actually cares about anymore. The framework doesn't break. People do.
Continuous Improvement In Quality Management: Where It Actually Breaks
Most guides will tell you to start with A3 thinking or Six Sigma methodology. I've done both. What they won't tell you is that DMAIC, by itself, has a structural weakness that most organizations walk right into. Define, Measure, Analyze, Improve, Control assumes your process is stable enough to measure. When your process isn't stable — and most real production environments aren't — your baseline data is garbage and every subsequent step compounds that error. I learned this the hard way in 2019. We had a persistent defect rate on a sub-assembly line that sat at 4.2% for eight months. The quality team ran a full DMAIC cycle. We mapped the process. We collected 3,000 data points. We identified three root causes using fishbone analysis. We implemented countermeasures. The defect rate dropped to 2.8%. We celebrated. Two weeks later it bounced to 5.1%. The problem was that the original 4.2% wasn't a consistent process failure. It was a symptom of a tool wear pattern we hadn't accounted for. The process was inherently variable in a way our measurement plan missed because we never ran a preliminary control chart analysis before committing to the full cycle. We optimized against noise instead of signal.
The workaround was brutal but simple: go back to the data and plot it on an I-MR chart first. Identify whether the process is even in statistical control before you do anything else. If it isn't, you don't do improvement. You do stabilization. Those are two different operations with different skill sets and different timelines. Mixing them up is the single most common mistake I see in quality teams.
Get the Full Details
Practical Execution: What Actually Works Day to Day
Here's how I'd structure a sustainable improvement program without the corporate polish: Step one is not what you think. Most organizations jump into training people on Lean tools before establishing what problems actually exist. Start by doing a proper problem selection process. Not every variation deserves improvement resources. Use a Pareto analysis on your defect data, but don't stop at the classic 80/20 rule. Look at the cost of poor quality for each defect category, not just the frequency. A defect that occurs once a month but causes a $40,000 recall risk is more valuable to address than one that happens daily but costs $12 per occurrence. The second step is feedback loop that doesn't require a meeting. This sounds trivial until you've sat through three hours of a quality review where nothing changed. Digital kanban boards, Andon alerts that route to Slack channels, automated dashboards — whatever fits your environment. The goal is to reduce the time between problem detection and problem acknowledgment from weeks to hours. Every day of delay in that acknowledgment window is where momentum dies.
Step three is standardizing the countermeasure implementation. This is where most programs founder. You identify the root cause. You propose a fix. Then six different supervisors implement six different versions of that fix because nobody documented the expected outcome, the acceptance criteria, or the rollback plan. Use a standardized change control form. One page. Force people to write down: what exactly changes, what metric proves it worked, what happens if it doesn't. If you can't fill out that page in ten minutes, the improvement isn't ready to launch. Step four is the Check phase, and it's where everyone cheats. You don't check by looking at the monthly report. You check within 48 hours of implementation. Short feedback loops matter more than long-term trends at this stage. If a countermeasure isn't showing directional movement within two days, you either had the wrong root cause or the implementation failed. Both are common. Don't wait three months to find out. Step five is the Act phase, which is actually the hardest part. Standardize the improvement, or it dies. I've seen improvement projects that delivered real results get abandoned because nobody updated the work instruction. The operator who knew the fix quit. The new hire went back to the old method. The improvement existed for forty-two days and then vanished. Document it, train to it, audit it. Not in that order. All three simultaneously.
Tools Worth Using and Tools You Should Skip
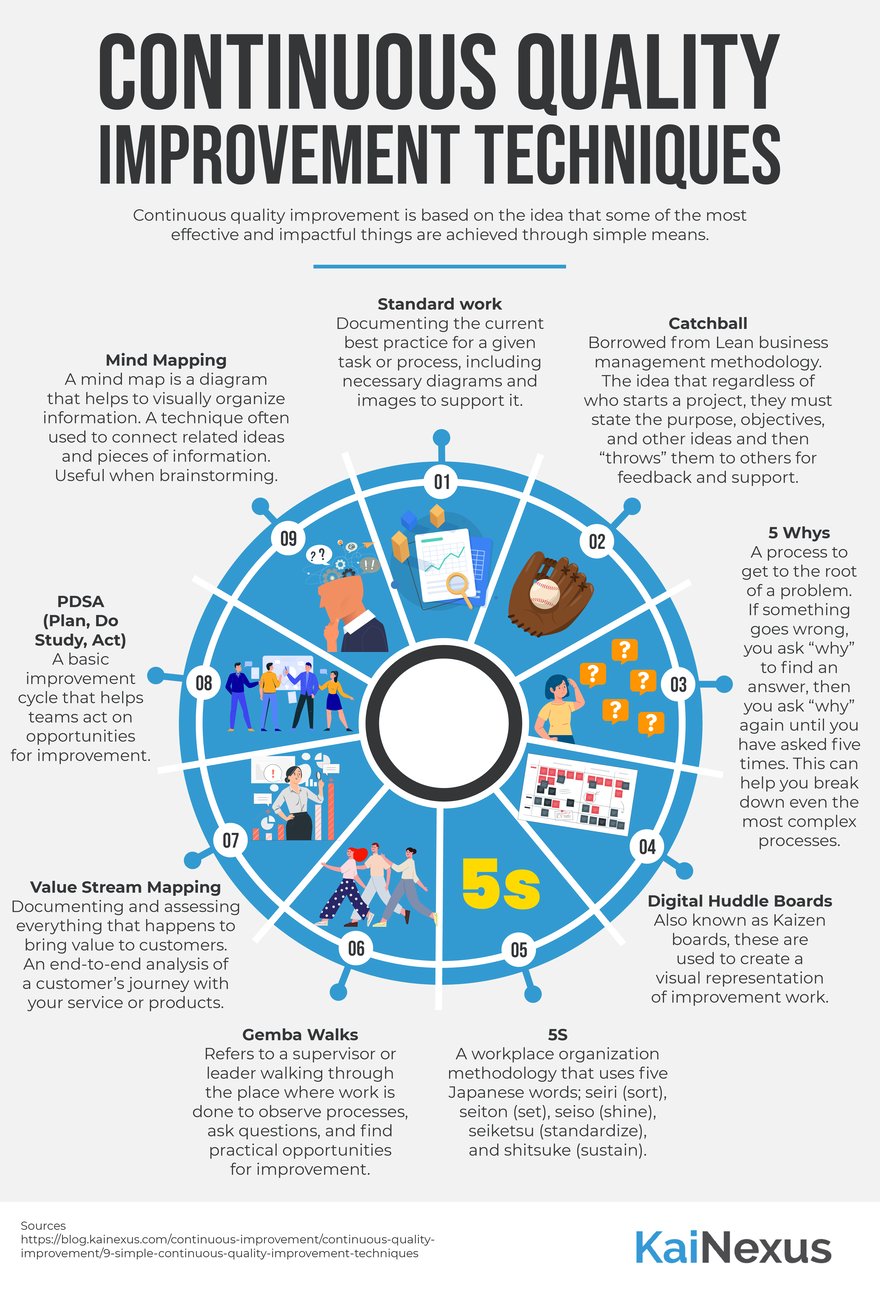
Minitab is the industry standard for statistical analysis and it's worth the license cost if you're doing real measurement system analysis or process capability studies. But for day-to-day continuous improvement, most of your team doesn't need Minitab. They need a well-configured control chart in Excel or a cloud-based SPC tool that auto-plots as data comes in. The barrier to entry for statistical tools should be as close to zero as possible. If getting a control chart requires a statistical degree, you've already lost. For root cause analysis, the 5 Whys gets a bad reputation because people use it poorly. It's not a substitute for proper experimental design or hypothesis testing. But for straightforward problems where the causal chain is linear and documented — and most shop-floor problems are — it's faster and more accurate than people give it credit for. The key is stopping at a root cause that's actionable, not philosophical. "The machine broke because it wasn't maintained" is actionable. "The machine broke because humans are flawed" is not. PFMEA is another tool that's widely misunderstood. Most organizations treat it as a compliance document. They fill it out once during product launch and never update it. A living PFMEA should be updated whenever a new failure mode is observed, not just at launch. If you've had three field returns on the same component and your PFMEA still shows low severity ratings, your FMEA is lying to you. Treat it as a dynamic knowledge base, not a paperwork exercise.

When Continuous Improvement Fails Completely
There are scenarios where structured continuous improvement methodologies simply don't apply and knowing this will save you from wasting months on the wrong approach. High-mix, low-volume production is one. If you're making custom parts where no two batches are identical, traditional SPC and DMAIC become nearly impossible to apply meaningfully. The statistical assumptions break down because you don't have enough data points per variant. In these environments, mistake-proofing (poka-yoke) and cellular manufacturing principles tend to deliver better results than cycle-based improvement frameworks. The focus shifts from reducing variation to preventing errors outright. Regulatory-constrained environments present another limitation. In pharmaceutical manufacturing or medical device production, every process change requires validation and regulatory documentation. The cost of implementing and documenting an improvement can exceed the cost of the defect itself. In these cases, continuous improvement exists but operates on a much longer timescale. A single PDCA cycle might span eighteen months instead of eighteen days. Understanding this constraint upfront prevents frustration and unrealistic expectations.
Culture is the silent bottleneck. This isn't inspirational language. It's a technical constraint. If your organization punishes people for reporting problems — directly or indirectly — no framework will fix that. I've seen companies implement Six Sigma Black Belt programs, invest in statistical training, buy enterprise quality software, and still have defect rates climb because operators hid problems to protect their shift metrics. The improvement system was sound. The incentive structure was broken. Fix the incentives before you touch the methodology.
A Counter-Intuitive Point About Metrics
Most quality teams track too many metrics. The average organization I've worked with tracked between 40 and 80 KPIs across their quality dashboard. Fewer than ten of those actually influenced decisions. The rest were vanity metrics that created the illusion of oversight without providing insight. The principle is simple but hard to enforce: if a metric doesn't change an action within 30 days of being reported, it should be discontinued. Not archived. Discontinued. I've seen senior leaders resist this because they felt blind without certain data points. But blind is better than distracted. You can always add a metric back. You can't easily remove the attention it drains from more important signals. There's also a nuance around leading versus lagging indicators that most people miss. Defect rate is a lagging indicator. It tells you what already happened. Process cycle time variation, first-pass yield, and equipment OEE are leading indicators. They predict future defect rates before defects occur. If your improvement program is tracking only lagging indicators, you're constantly reactive. You're always behind the problem. Shift your primary dashboard to leading indicators and you'll start improving before issues surface instead of after.
The Document You Actually Need
If you're starting a continuous improvement program from scratch, don't begin with a textbook. Begin with a one-page template that captures the essential elements of each improvement cycle. Problem statement, current state data, root cause analysis, proposed countermeasure, success criteria, implementation date, owner, verification result, and standardization action. That's it. Anything more elaborate becomes a reporting burden that slows the cycle down. I used to maintain a shared spreadsheet with all active improvement cycles. Each row was one PDCA. Color-coded by status. Updated weekly. It took me twelve minutes per week to maintain and gave me visibility into which improvements were stalled, which were completed, and which teams were carrying too many concurrent cycles. Three concurrent improvements per team was the maximum that produced results. Beyond that, context switching killed the momentum on all of them. The spreadsheet itself wasn't sophisticated. It was Google Sheets with conditional formatting and a pivot table. But it made the entire improvement portfolio visible in a single screen. That visibility alone prevented roughly half the failures I saw in other organizations, where improvement projects died quietly because nobody was tracking them past the planning phase.
Bottom Line
Continuous improvement in quality management works when the organization treats it as a operational discipline rather than a certification program. The tools are well established. The failure points are almost always human and structural, not methodological. If you want a starting point that won't waste your time, begin by mapping your current problem-to-resolution cycle time. Measure how many days pass between a quality issue being reported and a verified countermeasure being implemented. If that number is above thirty, you don't need a new framework. You need to remove bottlenecks from your existing process. Everything else is optimization on top of a foundation that may not be set yet.