What Control Charts Are and Why Most People Plot Them Wrong
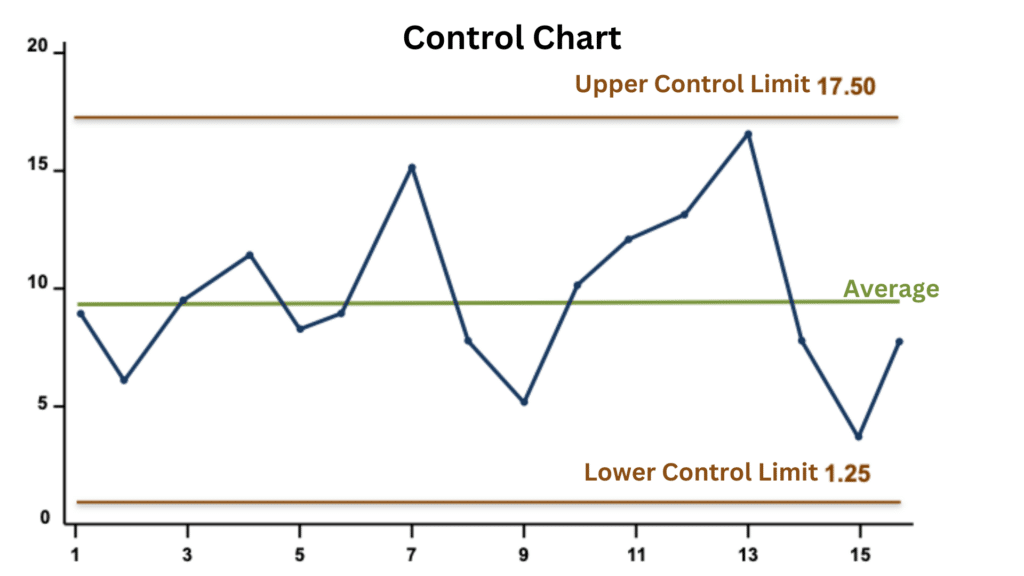
A control chart is a time-ordered plot of a process statistic with a centerline and two control limits. That is it. Nothing more. The U.S. Geological Survey, the FDA, and every Six Sigma handbook will tell you the same thing, but the part they do not emphasize enough is that control limits are derived from the data, not target values or specification limits. I see people confuse these constantly. When you place specification limits on a control chart, you get a mess of false signals that leads nowhere productive. Khan Academy has a section covering this topic as part of their statistics and probability curriculum.
Control Charts Khan Academy
walks through the basic construction using standard deviations from the mean. Their examples are deliberately simple, which is fine for learning the mechanics but leaves a lot of practical gaps unaddressed. That is normal. No single resource covers everything.How to Build One Without Losing Your Mind
Start by collecting your data in subgroups. The subgroup size matters. If you are doing X-bar and R charts, a subgroup size of 4 or 5 is the traditional sweet spot because the control chart constants table d2 values become more stable there. Smaller than 2 and the math gets fragile. Larger than 10 and you are usually better off switching to an individuals chart with moving ranges. Calculate the mean of each subgroup. Then calculate the overall grand mean across all subgroups. Next, calculate the range within each subgroup and average those ranges. The control limits use this average range multiplied by constants like D3 and D4 for the R-chart, or d2 for the X-bar chart limits. Khan Academy shows you the formulas directly. You can follow along and replicate their examples in a spreadsheet. It takes about ten minutes once you know where to click. The hard part is not the arithmetic. It is deciding what constitutes a rational subgroup in the first place. I once worked on a bonding process where the engineering team had been collecting one sample per hour for six months. The control chart showed excellent stability, which sounded great until I asked who was pulling the samples and why. They were pulling them from the same machine, same shift, same raw material lot. There was zero between-subgroup variation because the subgroups were not actually independent. The chart was stable but completely useless for detecting real process shifts.
The fix was to restructure the sampling plan so that each subgroup contained consecutive units produced within a short time window, while variations between subgroups captured shift changes, material lot changes, and operator differences. The resulting control chart immediately flagged a tool wear issue that had been hiding in plain sight for three weeks. The old chart had looked perfectly in control because it was measuring the wrong thing.
Get the Full Details
What the Video Lessons Do Not Tell You
The Khan Academy material covers the mechanical steps well enough for an introductory course. What it does not cover is what happens when your data violate the underlying assumptions. Control charts assume your data are approximately normally distributed and that the subgroups are independent. Neither assumption is always true, and both violations produce misleading signals. For count data like defect rates, using a standard X-bar chart is incorrect. You need a p-chart or u-chart instead. Khan Academy mentions these chart types briefly but does not spend enough time on the difference between np-charts and p-charts, which confuses a lot of beginners. An np-chart tracks the actual number of defectives and requires a constant sample size. A p-chart tracks the proportion and allows variable sample sizes. Pick the wrong one and your control limits will be wrong too. Another thing most people miss: control limits and specification limits serve completely different purposes. Specification limits come from the customer or the design engineer. They define what is acceptable for the product. Control limits come from the process itself. They define what the process is actually doing. You can have a process that is perfectly in control and still produce out-of-specification parts if the process is not capable. Running a control chart on an incapable process just tells you that you are consistently producing bad output, which is not particularly helpful without a capability analysis to back it up.
Practical Pitfalls That Waste Time
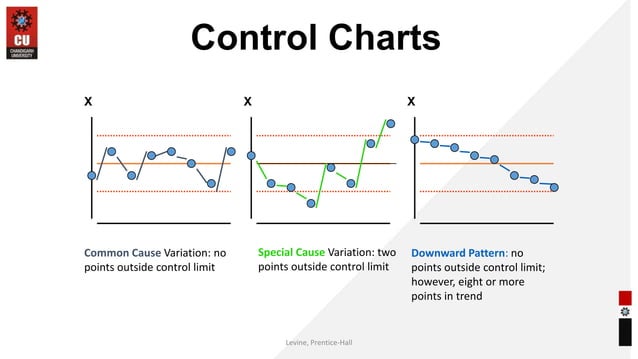
The most common mistake I see is recalculating control limits every time a new data point arrives. Control limits should be established during a baseline period when the process is known to be stable, and then held fixed. If you recalculate them with every new observation, you are just chasing noise. The chart will always look in control because the limits keep expanding and contracting to accommodate the latest data point. This is sometimes called adaptive control charting and it is generally a bad idea unless you have a very specific statistical reason for doing it. A second issue is treating any point outside the control limits as the only signal worth investigating. That is incomplete. There are established Western Electric rules and Nelson rules for detecting non-random patterns within the control limits. A run of seven points on one side of the centerline, a trend of six points continuously rising or falling, or a cycle pattern repeating at regular intervals are all valid signals that the process has shifted even when no single point has crossed a control limit. Khan Academy touches on these patterns but does not go deep enough for practical implementation. You will need to supplement their material with a reference like Montgomery's Introduction to Statistical Quality Control if you want to apply this properly in a manufacturing environment.
When Control Charts Fail Completely
Here is the blunt truth: control charts are not useful for every process. They require a process that produces relatively homogeneous output over time. If your process is inherently nonstationary, like a chemical batch reactor where every batch is fundamentally different from the last, a control chart will either show constant out-of-control signals or no signals at all, depending on how you construct it. Neither outcome is informative. They also require sufficient data. I have seen people try to build a control chart from twelve data points and then declare the process in control. You need at least twenty to twenty-five subgroups before you can reliably estimate process variation. Fewer than that and your control limits are essentially guesses wrapped in mathematical formalism. Khan Academy's exercises use small sample sizes for pedagogical reasons, which is fine for a classroom setting but dangerous if someone takes that as a realistic minimum for production use. If your process is low-volume or custom work, consider batch control methods or individual-moving range charts instead. These handle sparse data better and are less sensitive to the assumption of large subgroup counts. For processes where measurements are destructive or extremely expensive to obtain, the moving range approach lets you work with individual observations rather than subgroups. The trade-off is reduced sensitivity to process shifts, but that is often an acceptable compromise.

The Khan Academy videos are a reasonable starting point for anyone who needs to understand the basics. They are free, clearly presented, and adequate for passing an introductory statistics exam. But they are not a substitute for working through real data and seeing where the assumptions break down. The gap between a classroom example and an actual production line is wider than most people expect. Once you have the foundation from Khan Academy, you will need to fill in the practical details yourself.