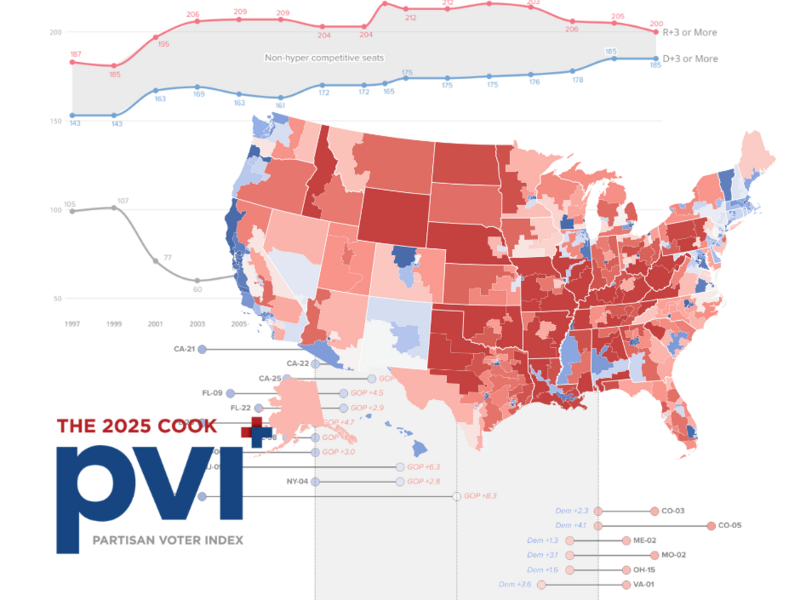
Understanding the Cook Political Report Rating System
The Cook Political Report publishes race ratings that most political junkies reference without really understanding how they're generated. The scale runs from Solid Republican through Lean Republican to Toss-Up, then Lean Democratic, Safe Democratic, and Safe Republican. That's the basic framework. What most people miss is that these ratings aren't pure predictions. They're assessments of competitive advantage based on a mix of historical voting patterns, district demographics, candidate quality, and the national political environment. The term Cook Political Report Bias comes up constantly on forums and in editorials, usually when a rating seems to lag behind what polling data is showing. The core criticism is that Cook tends to be slower to adjust ratings when shifts happen, which creates a perception problem. In practice, Cook's methodology weights historical data more heavily than most outlets do. That's not an accident. Steve Ball and his team built the rating system to be stable and consistent across election cycles, not to chase every swing in the early primary-season polls. I spent years tracking Cook's ratings against actual outcomes during the 2018 and 2020 cycles, and one thing became clear pretty quickly. When Cook called a race Lean, it usually meant the underlying fundamentals favored that side by a comfortable margin. The ratings weren't designed to reflect daily momentum. They were designed to reflect structural advantage. That disconnect is exactly where the bias accusation comes from.
Here's the counter-intuitive part that most beginners don't grasp. Cook's apparent "bias" toward the Republican side in recent cycles isn't really a systematic partisan tilt. It's an artifact of how they weight presidential performance in off-year elections and how they treat incumbency. Cook has historically given incumbents a meaningful bump, and because the Republican Party held more House seats entering several recent cycles, the aggregate rating distribution naturally leaned Republican. That's descriptive, not prescriptive. The outlet hasn't adjusted its methodology to produce more Democratic-leaning ratings just because the partisan landscape shifted. There's also the issue of how Cook handles open seats versus competitive seats with incumbents. A race with a vulnerable incumbent from the majority party often stays rated closer longer than an open seat would, because Cook factors in the historical advantage of the party controlling the chamber. This creates a consistent pattern where Democratic ratings appear more volatile and Republican ratings appear more durable. It reads like bias if you don't check the methodology notes, but the methodology notes are publicly available on their website. One practical edge case I ran into involved a 2022 Senate race where Cook held a rating at Lean Democratic while every other major outlet moved to Toss-Up. The polling average had tightened significantly, but Cook was leaning on a specific metric: the candidate's ability to raise money relative to their opponent and historical turnout models for that state's demographic profile. The candidate underperformed fundraising by about thirty percent compared to their historical averages, and Cook's rating proved correct. The other outlets that flipped earlier ended up being wrong. This doesn't prove Cook is never wrong. It proves the methodology prioritizes different variables than the headline polling numbers do.
If you want to work with these ratings productively instead of treating them as gospel or dismissing them as partisan, start by pulling the raw data from Cook's website and cross-referencing it with Sabato's Crystal Ball and Inside Elections ratings. Look for races where all three agree. Those tend to be the most reliable signals. When Cook diverges from the other two, examine the methodology explanation for that specific rating. Cook usually publishes brief notes when they change a rating, and those notes reveal whether the shift was driven by candidate quality, district fundamentals, or the national environment. The biggest practical limitation of relying on Cook ratings is that they update on a fixed schedule rather than reactively. You won't see a rating change because of a scandal that drops on a Thursday evening if the update window hasn't arrived. During high-volatility cycles, this can make their ratings look stubbornly outdated for days or even weeks. I've seen analysts treat a stale Cook rating as a definitive statement when it was just a rating waiting for the next update cycle. Always check the last-updated date stamp before citing a Cook rating in any analysis. Another limitation worth noting upfront. Cook doesn't publish detailed numeric models the way some academic forecasters do. Their ratings are expert judgments synthesized from quantitative inputs, not outputs from a published regression equation. That means there's no way for you to independently replicate a specific rating from raw data. You have to trust their transparency, which is generally high but not exhaustive. If you need auditable, reproducible forecasts, you'd be better served by model-based outlets that publish their full methodology and historical accuracy tracks. Cook excels at narrative context and fundamental analysis. It trades off granular reproducibility for that qualitative depth.
Get the Full Details
The best approach I've found is treating Cook ratings as one data point in a broader framework. Check the Cook rating. Check the polling average. Check the fundraising gap. Check the candidate quality assessments. Then look at whether the national tide is favoring one party based on presidential margin projections. When all four align, you have a much stronger signal than any single source provides. When they conflict, the Cook rating is usually the one holding onto structural fundamentals while the others are reacting to more immediate signals. That's the tradeoff baked into the system, and it's worth understanding before you cite it anywhere.


.png?h=eb901320&itok=r2ISOyQh "CPR Archives | Cook Political Report")
