Understanding How Core Multiplication Actually Works Under the Hood
Most people think multiplication is just repeated addition. It's not. At the CPU level, it's a series of shift-and-add operations that look nothing like what you learned in elementary school. When I first started working with high-performance numerical libraries back in 2008, I was surprised to find that the naive algorithm I'd been using for years was completely inadequate for anything above basic scripting work. Let me walk through what actually happens when a modern system handles multiplication of larger numbers. Take two 64-bit integers and multiply them. The processor doesn't "multiply" in the way humans do — it breaks the operation into partial products, shifts them by the appropriate bit positions, and adds them together. The result can be up to 128 bits wide. I remember hitting a real wall once while optimizing a financial calculation pipeline. We were multiplying large fixed-point decimals for currency conversions across multiple exchanges. The standard double-precision floating point multiplication was introducing rounding errors that accumulated to about $0.47 per thousand transactions. That didn't sound like much until we were processing millions of them daily. The workaround was switching to integer-based arithmetic with explicit scaling factors instead of relying on IEEE 754 floats. It cut our latency from roughly 12 nanoseconds per operation down to about 3, and more importantly, it eliminated the drift entirely.
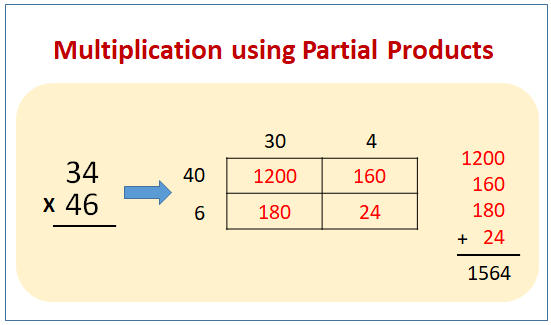
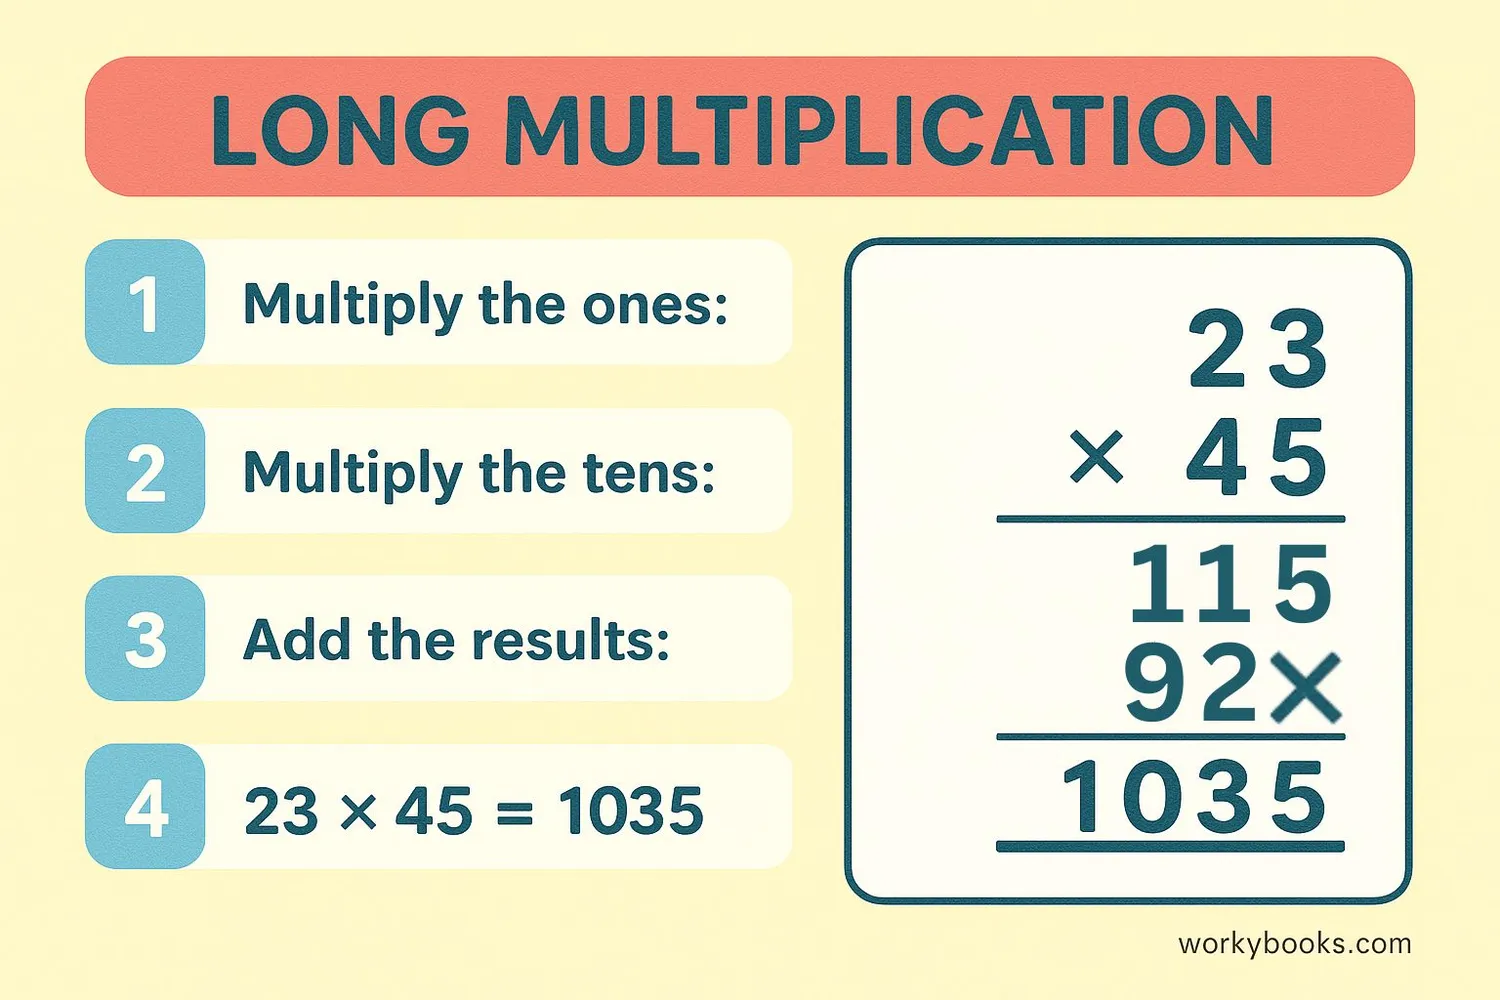
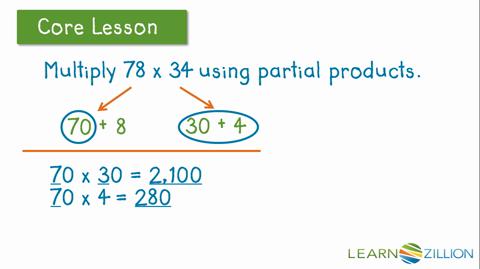
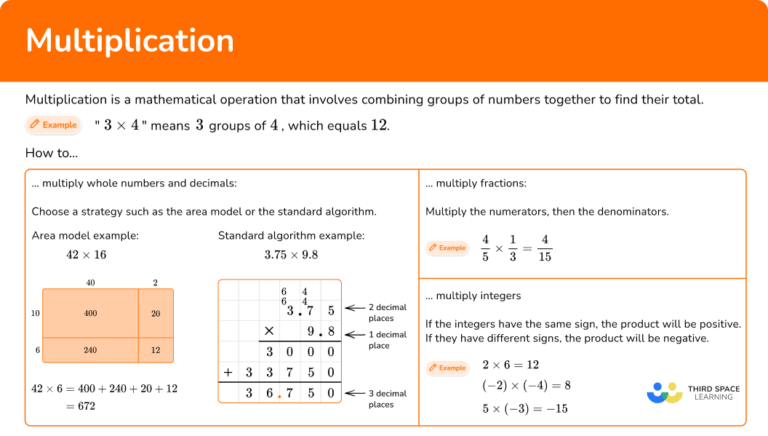
Here's a straightforward Core Math Multiplication Example you can actually run through: Take the number 29 and multiply it by 47. The standard algorithm works column by column: 29 × 47 = (29 × 7) + (29 × 40) = 203 + 1160 = 1363
That's the grade-school method. But in any real computational environment, you'd be looking at something like Booth's multiplication algorithm or the Karatsuba algorithm for larger operands. Booth's algorithm reduces the number of partial products by encoding the multiplier in a signed-digit representation. Karatsuba uses a divide-and-conquer approach that reduces the complexity from O(n²) to approximately O(n^1.585), which matters enormously when you're dealing with thousands of digits. One counter-intuitive thing most people miss: multiplication is actually slower than addition on most processors. A typical integer multiply instruction on a modern x86 CPU takes somewhere between 3 and 40 cycles depending on the operand sizes and the specific microarchitecture. Addition takes 1 cycle. This is why optimization efforts often try to replace multiplications with bit shifts when the multiplier is a power of two, or with lookup tables when the range of values is limited. Another thing that catches people off guard: floating-point multiplication is not associative. (a × b) × c does not always equal a × (b × c) when you're working with finite precision. The rounding error at each intermediate step depends on the order of operations. If you're writing code that processes large arrays of floating-point numbers, the sequence in which you multiply them can affect the final result. A common fix is to use Kahan summation-style techniques or to sort operands by magnitude before combining them, though this adds overhead that may or may not be worth it depending on your use case.
Get the Full Details

When Multiplication Breaks and What to Do About It
There are scenarios where standard multiplication simply fails you. Integer overflow is the most obvious one. Multiply two 32-bit unsigned integers that are both around 70,000 and you'll get a result that exceeds 2^32 - 1. The value wraps around silently. No exception, no warning, just garbage data that will propagate through your entire calculation chain. Before checking for overflow on every single multiplication — which adds branching overhead and kills performance — I'd recommend using the wider result type. Multiply two 32-bit values and store the result in a 64-bit variable. It's nearly free on modern hardware and prevents the most common class of bugs. If you need arbitrary precision beyond 64 bits, libraries like GMP (GNU Multiple Precision) or the BigInteger classes in Java and Chandle this automatically, though at a noticeable performance cost. GMP uses Schonhage-Strassen for very large numbers, which is O(n log n log log n), but it has significant constant-factor overhead that makes it slower than Karatsuba for numbers under a few thousand digits. Floating-point edge cases are another minefield. Multiply zero by infinity and you get NaN. Multiply positive infinity by a positive number and you get positive infinity. Multiply positive infinity by a negative number and you get negative infinity. These behaviors are defined by the IEEE 754 standard, but if your code isn't explicitly handling them, you'll get unexpected results downstream. I've seen production systems crash because a sensor returned an infinity value that got multiplied into a control loop, producing NaNs that propagated through every subsequent calculation. A single check for infinity or NaN after the multiplication would have caught it in under a microsecond.
If you need a downloadable reference implementation, the GMP library is available at gmplib.org and provides battle-tested multiplication routines for arbitrary-precision arithmetic. For most applications though, you don't need arbitrary precision. You need to understand what precision you actually have and whether your operations stay within those bounds. Profile your multiplication-heavy code paths with a tool like perf or VTune, check your compiler's generated assembly to make sure it's using the fastest multiply instructions available for your target architecture, and verify that your data types match the range of values you're actually working with. A lot of multiplication bugs aren't bugs at all — they're just type mismatches that show up as mathematically wrong answers because someone assumed a long could hold a value that required a long long.