Getting Your Network Segments Working Without Losing Your Mind
I spent three days last month troubleshooting why a VLAN tagged for guest Wi-Fi could still reach the production database server. The firewall rules looked correct on paper. The switch configuration matched the documentation we had from 2019. The actual problem was a misconfigured static route on an edge router that nobody had noticed because it was buried under forty other entries. I found it by pinging the database server from the guest network at 2 AM instead of reading the config files line by line, which is probably the single most useful troubleshooting habit I have picked up over twelve years in this field. Corporate Computer And Network Security isn't really a product you buy. It is a set of practices that keep your organization from getting held hostage by a ransomware operator or losing customer data to a misconfigured cloud bucket. The industry sells it as a dashboard with colored lights, but the reality is much less glamorous and a lot more repetitive.
The Actual Work of Corporate Computer And Network Security
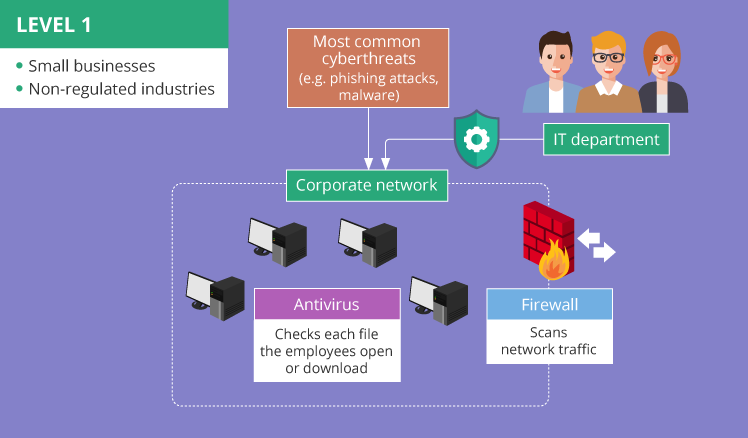
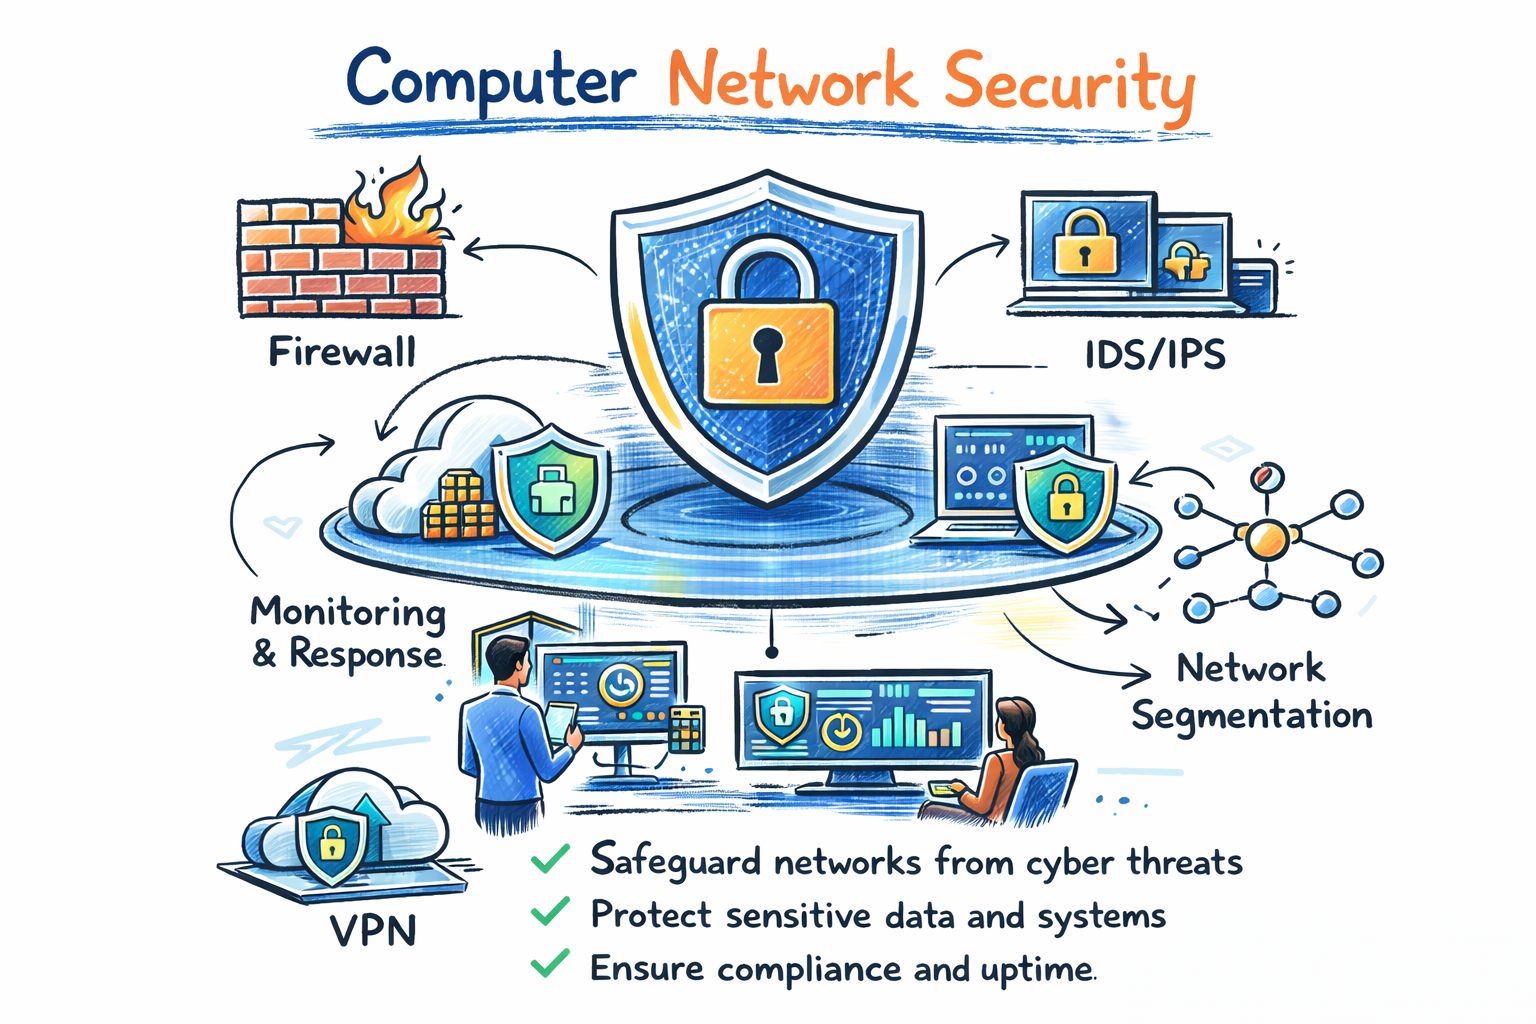
It starts with asset inventory, which sounds boring because it is boring, but it is also the foundation everything else rests on. You cannot protect what you do not know exists. I ran into this exact problem at a mid-size logistics company where we discovered forty-two server instances running in a forgotten AWS account under an employee who had left the company two years earlier. Those instances were still receiving production traffic through a DNS record nobody had deleted. We shut them down and patched the access policy in about twenty minutes, but they had been sitting there unmonitored for over fourteen months. The second layer is network segmentation. This means dividing your internal network into separate zones so that a compromise in one area does not give an attacker free movement across the entire infrastructure. The typical zone structure looks like this: corporate workstations in one segment, servers in another, VoIP and IoT devices in a third, and guest wireless isolated from everything. Each zone talks to the others only through controlled choke points, usually firewalls or managed switches with ACLs. A common mistake I see is treating VLANs as equivalent to security boundaries. They are not. A switch can assign ports to different VLANs, but without enforced routing policies and firewall rules between those VLANs, a compromised workstation can still reach any other device on the same switch. I configured a rule once that allowed all VLANs to communicate freely while the access control list was technically applied. It was a copy-paste error from a lab environment. The rule sat there for eleven days before a port scan from a compromised PC revealed it. That is the kind of thing that keeps you awake at night.
Endpoint Protection Without Overloading the Helpdesk
Endpoint detection and response tools are standard now, but the deployment phase is where most organizations break something. I helped roll out a new EDR solution at a manufacturing plant with three hundred Windows endpoints. The initial policy pushed agent updates and a full system scan simultaneously across the entire fleet during business hours. This took the network down for about forty minutes because the legacy factory floor network runs on aging switches with barely enough bandwidth for the actual production systems. The fix was straightforward: stage the updates with a priority queue so that critical manufacturing machines get their patches first, and use a maintenance window script that staggers the reboot phase across fifteen-minute blocks instead of hitting all three hundred devices at once. That approach cut the incident duration from four hours of downtime to about twenty-five minutes of scattered brief interruptions. Hardening your endpoints is the next step, and it mostly involves disabling unnecessary services, enforcing application allow-listing where possible, and making sure that local admin rights do not sit in the hands of every employee. I have seen companies run on a model where every user is a local administrator because it makes IT support easier in the short term. It also means that when someone clicks a phishing link, the malware runs with full privileges and can modify system registries, install persistence mechanisms, and disable security software without prompting. Group Policy can restrict local admin rights, but you need to think carefully about which applications actually need elevated privileges. Most modern software runs fine without them, but some legacy accounting tools and industrial control system interfaces do require admin rights to function. Build a allow-list for those, test them in a sandbox environment, and only grant elevation to verified applications.
Get the Full Details
Firewall Rules That Actually Do Something
Firewalls are not a set-it-and-forget-it tool. I inherited a Palo Alto firewall at a previous employer with roughly two thousand rules, none of which had a documented owner or review date. About sixty percent of those rules were redundant or had never triggered a match in the logging database. I wrote a Python script that pulled the hit counts from the firewall every six hours for two weeks, then flagged any rule with zero hits and no recent modifications. After confirming with the network team that those services were indeed decommissioned, we removed eight hundred and forty-seven rules in a single maintenance window. The management interface responded noticeably faster afterward, and more importantly, the chance of an accidental open rule slipping through the gaps dropped significantly. A useful principle here is deny-by-default on internal firewalls and explicit allow-listing for everything that needs to communicate. This sounds obvious until you realize how many organizations run on the opposite model: open by default and blocking only what causes problems. When a new service request comes in, the easiest path is often to just add another allow rule rather than investigating whether the traffic actually needs to flow that way. Document every allow rule with its business justification, the owner, and a review date. I found this practice painful at first because it required chasing down people to get answers, but after six months of maintaining the documentation, it became a reference that saved us during an incident response when we needed to trace how an attacker moved laterally through the network.
Identity and Access Management as the Real Perimeter
The concept of a network perimeter is largely dead. Employees work from coffee shops, contractors connect through VPNs, and cloud services mean your critical data lives outside your physical buildings. Identity has become the new perimeter, which is why multi-factor authentication deserves more attention than it usually gets. I have seen MFA implemented as an afterthought, bolted on top of existing credentials without considering the user experience. The result is either people finding workarounds or managers disabling the requirement because helpdesk tickets spike. The right approach is to mandate MFA for all privileged accounts immediately and phase it in for standard users over a six-week period with clear communication about why it is happening. Provide multiple MFA methods so that users who cannot use a mobile app can use a hardware token or a backup code printed on paper, and make sure helpdesk staff are trained to handle MFA reset requests quickly. Privileged access management is another area where I have seen too much go wrong. The classic pattern is a shared admin account used by five different engineers, with the password written on a whiteboard in the server room. I replaced that with a just-in-time access model using Azure PIM, where engineers request elevation to a specific role for a maximum duration, receive an approval notification, and automatically lose access after their time expires. The first week was chaotic because everyone had to adjust to the request workflow, but within two months the number of unauthorized privilege escalations dropped to zero and the audit trail gave us visibility into who was doing what and when. This system also caught a former contractor who still had active login credentials because the offboarding process had not included disabling that particular account.
Vulnerability Management That Does Not Crush the Team
Running vulnerability scans is routine, but triaging the results is where most teams fail. A typical enterprise scanner will produce thousands of findings overnight, and if you try to address all of them at once, you will miss the ones that actually matter while spending weeks on low-risk issues. I use a risk-based prioritization model that weights findings by exploitability, asset criticality, and current exposure. A critical CVE on a web-facing server with known public exploit code takes priority over a medium-severity finding on an isolated database server with no internet access. The CVSS score alone is misleading because it does not account for your specific environment. A server running an outdated version of OpenSSL might score high in isolation, but if that server sits behind three firewalls and only accepts connections from internal monitoring tools, the real risk is much lower. Patching cadence matters more than most organizations admit. I recommend a tiered approach: critical patches within forty-eight hours, high-risk patches within seven days, and medium-risk patches within thirty days. This gives the patching team time to test before deployment while ensuring that the most dangerous vulnerabilities are addressed quickly. The forty-eight-hour window for critical patches assumes you have an automated patch management system in place. If you are still pushing updates manually through remote desktop sessions, you will not meet that target consistently. Invest in SCCM, Intune, or a comparable solution early, even if it means spending two weeks configuring compliance policies and deployment rings. The time saved after the initial setup pays for itself within the first month of operation.
Incident Response That Actually Works
Most incident response plans are document decks that nobody has practiced. I wrote an IR plan for a company that read like a textbook, full of and decision trees, but when a real phishing campaign hit six months later, the team panicked because the plan assumed a different attack vector. The playbook called for isolating infected endpoints, but it did not account for the fact that our email gateway was integrated with Active Directory and blocking one account would cascade into locking out the entire marketing department. We ended up responding manually, which took three days longer than necessary and resulted in additional compromised accounts because the containment phase was disorganized. The fix was to run tabletop exercises quarterly with different scenarios and to write separate playbooks for common attack types rather than one massive document. Each playbook covers the specific indicators, containment steps, communication templates, and escalation paths for that scenario. A ransomware playbook is very different from a data exfiltration playbook, which is different from a credential theft playbook. Keep each one to about three pages so that responders can reference it under stress without flipping through twenty minutes of documentation. I also added a runbook section with exact commands and screenshots for the most common containment actions, because typing the wrong PowerShell command while a situation is escalating is a real risk.
Log Management and Visibility
You cannot detect what you cannot see, and visibility depends on centralized logging. I deployed a SIEM at a regional hospital where the previous setup involved individual administrators SSHing into servers to check logs in text files. When a ransomware variant encrypted the SQL database server, the team did not notice for three business days because nobody was actively monitoring the logs. The new SIEM ingests authentication events, firewall logs, endpoint telemetry, and cloud audit trails into a single dashboard with automated correlation rules. A brute force login attempt followed by a successful login from a different geographic location triggers an alert within ninety seconds. This caught a compromised service account that had been used to exfiltrate patient data over a two-week period before anyone realized something was wrong. Log retention is a separate concern that usually comes up during compliance audits. Most regulations require somewhere between ninety days and seven years of log retention depending on the data type. I have seen teams delete logs older than thirty days to save storage costs, then fail an audit because they could not demonstrate monitoring coverage for the previous fiscal year. Set up tiered storage with hot, warm, and cold tiers. Keep the most recent sixty days on fast storage for active investigation, move the next two years to cheaper object storage, and archive anything older according to your retention policy. Automated lifecycle policies in cloud storage make this manageable without consuming engineering hours.
Common Failures I Keep Seeing
The most frequent failure mode is treating security as an IT problem instead of an organizational problem. I worked with a team that spent most of their budget on technical controls while neglecting user training, expecting the firewall and endpoint agents to catch everything. A single distracted employee clicking a link in a spoofed vendor email defeated all of that investment. Security awareness training is not optional, but it also needs to be practical. I replaced generic compliance videos with targeted scenarios relevant to each department. Finance staff received training about invoice fraud and business email compromise. Engineering staff received training about supply chain attacks and dependency poisoning. The engagement rate improved dramatically because the content was actually useful to the people receiving it. Another recurring issue is over-reliance on a single security tool. I have watched organizations invest heavily in one platform and then treat it as the entirety of their security posture. A next-generation firewall does not protect against insider threats, a SIEM does not prevent credential phishing, and an EDR agent does not secure your cloud configuration. Security is a stack of overlapping controls where each layer catches what the others miss. If one layer fails, the others should still provide coverage. Design your architecture with this defense-in-depth principle in mind, and test each layer independently to confirm it actually works when the primary defense falls through.

Cloud Security Adds a Whole New Layer
Moving to the cloud does not remove your security responsibilities. It changes them. AWS, Azure, and GCP all share a responsibility model where the provider secures the infrastructure and you secure what you put on top of it. I encountered a case where a company migrated their production environment to Azure without reviewing the default network security groups. Those groups had overly permissive inbound rules that allowed RDP from any IP address on the internet. We found them because a legitimate penetration test revealed the exposure, but the gap existed for four months before the test was scheduled. Configure Azure Policy rules that enforce minimum security standards for all new resources, and use Azure Defender to continuously monitor for misconfigurations. Set up alerts that fire immediately when a security group with wide-open inbound rules is created, and require peer review before such a rule can be deployed in production. Cloud storage buckets are another common failure point. S3 buckets and Blob containers with accidental public access have led to massive data breaches across multiple industries. I configure bucket policies with explicit deny-all-public-access at the account level and then grant access through role-based mechanisms with specific conditions. This prevents anyone from accidentally publishing sensitive data through the console or a misconfigured deployment script. The first time this saved us, a junior developer pushed a Terraform script that would have made a customer database publicly readable. The account-level deny policy blocked it, and the CI/CD pipeline failed with a clear error message instead of creating a live security incident.
Physical Security Still Matters
People tend to forget physical security in the age of cloud computing, but it remains relevant. A locked server room does not protect your data, but it does raise the bar for an attacker who wants to perform a direct hardware compromise. I have seen too many offices where anyone can walk in, plug a USB device into an available port, and potentially gain access to the internal network. Implement USB port blocking through Group Policy, use machine-level authentication for building access, and maintain visitor logs that are reviewed weekly. These measures are inexpensive and easy to enforce, and they prevent the kind of casual insider threat that automated scanning tools will never catch. The overall message is that corporate security is a continuous process of assessment, implementation, testing, and adjustment. There is no final state where everything is secure. New vulnerabilities emerge monthly, attack techniques evolve, and your own infrastructure changes as the business grows. Build processes that adapt, document what you do so that knowledge does not leave with individual employees, and test your defenses regularly because assumptions are the enemy of security. The company that wakes up one morning and discovers they have no incident response plan is the same company that finds out its backups are corrupt while a ransomware timer counts down. Both situations are entirely preventable with basic planning and discipline.