Getting Started With Correlation Coefficient Practice
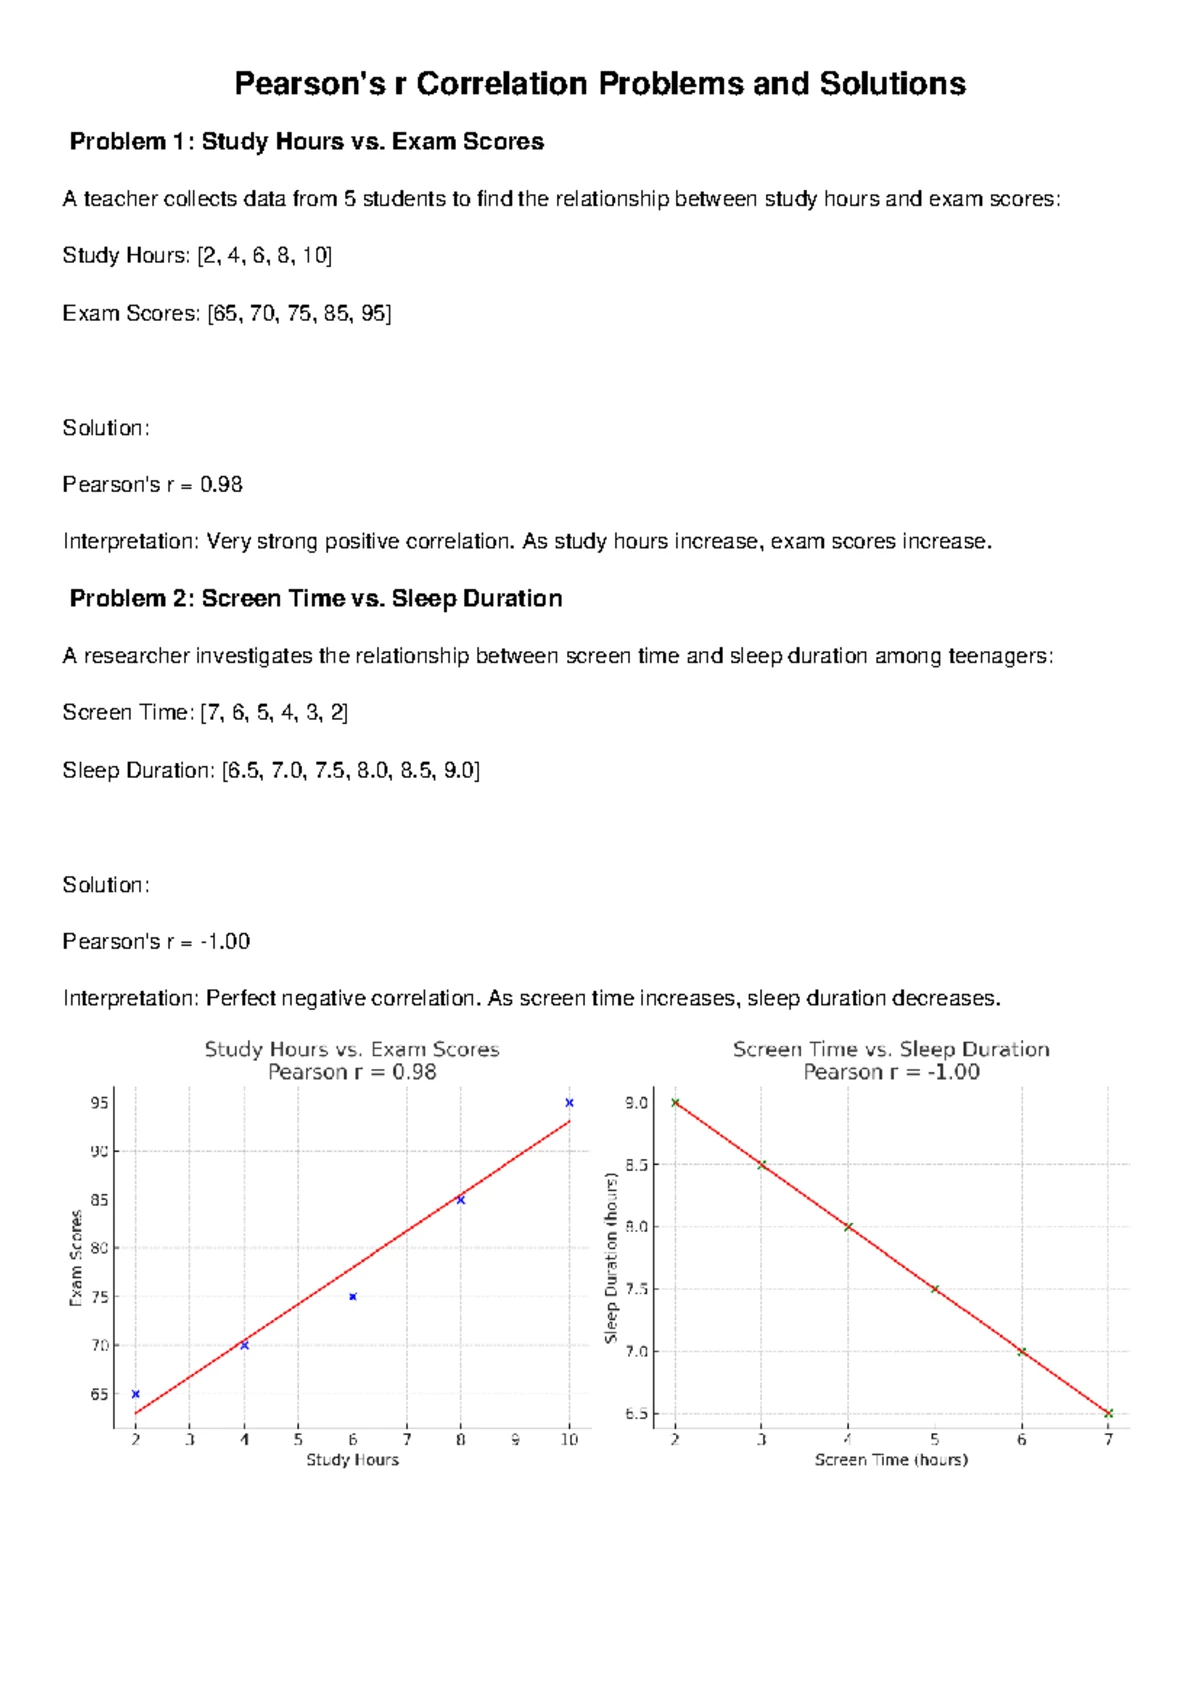
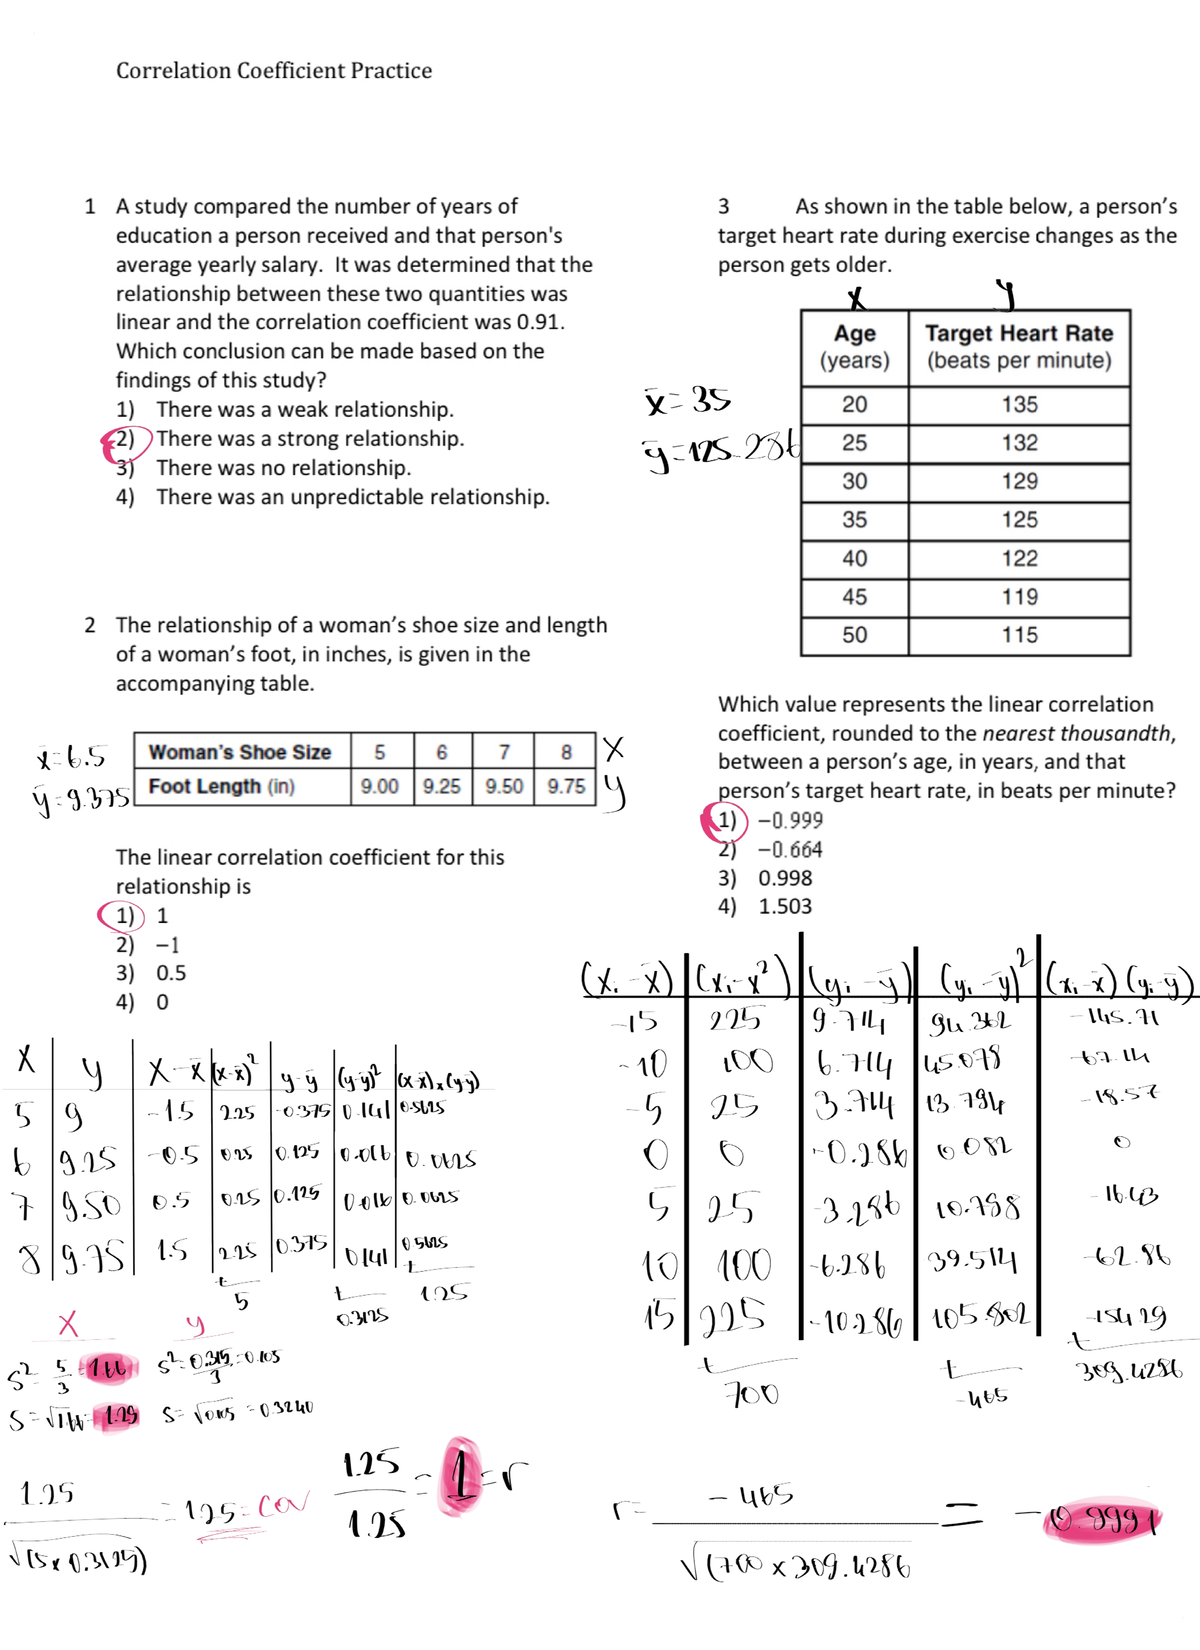
Most people learning statistics hit the correlation coefficient topic and immediately get confused about what the number actually means in real data. I spent years grading student work on this exact topic, and the same mistakes repeat every semester. The Pearson correlation coefficient, usually denoted as r, measures the strength and direction of a linear relationship between two continuous variables. The value ranges from -1 to +1. That part everyone memorizes. The part nobody actually understands is what happens when your data doesn't cooperate. The formula looks intimidating on paper but breaks down into steps you can do with a basic calculator. You need paired observations for variables X and Y. For each pair, you calculate the mean of X and the mean of Y. Then you find the deviation of each observation from its respective mean. Multiply the deviations for each pair together, sum those products, and divide by the product of the standard deviations times the sample size minus one. The standard computational formula that most textbooks use is: r = [n(xy) - (x)(y)] / [{n(x²) - (x)²} × {n(y²) - (y)²}]
Here is where people mess up. They plug numbers in without checking that both variables are approximately normally distributed and that the relationship is actually linear. I had a student last year who computed an r of 0.92 between hours spent studying and exam scores, then tried to use it to predict outcomes for a completely different dataset. The correlation was strong within her sample but completely meaningless elsewhere. Always check the scatterplot first before doing any calculation.
Common Practice Problem Types and What to Watch For
The practice problems you will encounter generally fall into a few categories. Some ask you to compute r from raw data. These are the tedious ones where a single arithmetic error ruins everything. Others give you a scatterplot and ask you to estimate the correlation. A third type presents a computed r value and asks whether the relationship is statistically significant, which requires a hypothesis test. The significance test uses a t-statistic: t = r(n-2) / (1-r²). You compare this against a t-distribution with n-2 degrees of freedom. Here is the counter-intuitive part that trips people up regularly. A correlation of 0.30 with a sample size of 500 can be highly significant, while a correlation of 0.70 with a sample size of 10 might not reach significance at all. Statistical significance does not equal practical importance. With large enough samples, almost any correlation becomes significant. I ran into a particularly annoying edge case recently working with survey data. The variables looked correlated at first glance, but when I split the data by demographic group, the correlation flipped direction in one subgroup. This is Simpson's paradox, and it shows up more often than most people expect. The overall correlation was masking opposing relationships within subgroups. If your practice problem involves grouped data, always check whether a lurking variable might be driving the association.
Get the Full Details
Interpreting Correlation Coefficient Practice Problems Correctly
When you see a practice problem stating that r = 0.65, the correct interpretation is that approximately 42% of the variance in one variable is explained by the other variable. That comes from squaring the correlation to get r², also called the coefficient of determination. People routinely misstate this as "65% of the variance is explained," which is wrong. The squaring step matters. Another thing to remember is that correlation says nothing about causation. This gets repeated so often it becomes background noise, but students still write causal language on exams. "Variable A causes Variable B" is never a valid conclusion from a correlation alone. It might be reverse causation, a third variable, or pure coincidence. The practical bottleneck I see repeatedly is the assumption of linearity. Pearson's r only captures linear relationships. If your data follows a clear U-shaped or inverted-U pattern, Pearson's r might come out near zero even though there is a very strong nonlinear relationship. In those cases, Spearman's rank correlation or a scatterplot transformation does more good. I once had a dataset where the Pearson r was 0.12, but when I logged the Y variable, the correlation jumped to 0.78. The relationship was exponential, not linear, and the raw Pearson coefficient completely missed it.
Outliers and Their Disproportionate Impact
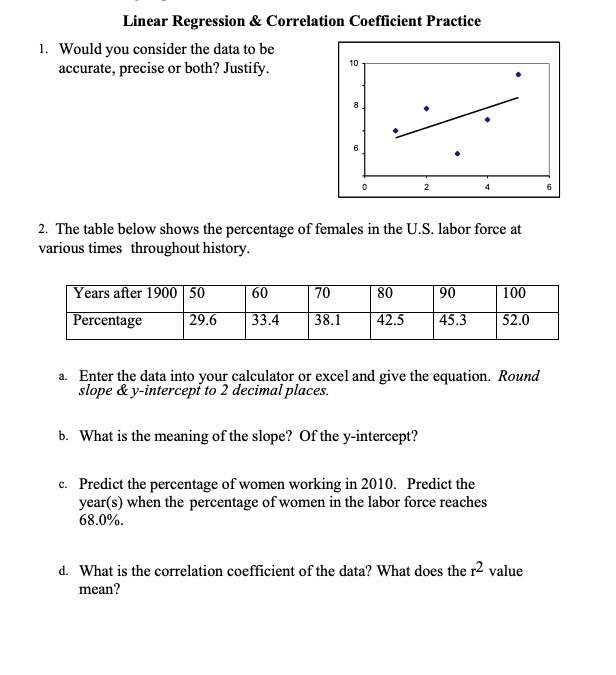
Outliers are the single biggest threat to a reliable correlation estimate. A single extreme point can inflate or deflate r by 0.20 or more in modest samples. There is no magic formula for handling them. The standard approach is to compute r with and without the outlier, report both values, and let the context decide whether the point is a data entry error or a genuine observation. I tend to remove only clear data entry errors. One time I spent two weeks investigating an outlier in a clinical dataset, only to discover it was a real patient response that turned out to be the most informative data point in the entire study. Removing it would have hidden the effect I was looking for. Use spreadsheet software for anything beyond five or six data points. Manual calculation works for tiny datasets in exam settings, but for real work it is a waste of time. Excel's CORREL function or theLINEST function in array form handles the computation instantly. Just make sure you understand what the function is doing under the hood so you can spot errors when they arise. Always draw the scatterplot. It takes thirty seconds and catches more mistakes than any formula ever will. Check for nonlinearity, outliers, and clusters. A single visual inspection saves you from drawing wrong conclusions from a misleading number.
When reporting results, include the r value, the r² value, the sample size, and the p-value. Leave out any one of those and someone reviewing your work will have to ask for it. A correlation without a sample size is basically useless because you cannot judge its reliability.
Where Correlation Analysis Breaks Down
Pearson's correlation assumes interval or ratio data, linearity, homoscedasticity, and approximate bivariate normality. Violate those assumptions and your r value becomes unreliable. Binary variables should use the point-biserial correlation instead. Ordinal data should use Spearman's rho. Highly skewed continuous data should be transformed or analyzed with a nonparametric method. None of these rules are suggestions. They are requirements for the statistic to mean anything at all. There is also the matter of restricted range. If your sample only covers a narrow slice of the possible values for one variable, the correlation will be attenuated toward zero. A study measuring income only among engineers will show a much weaker correlation between income and education than a study measuring income across the entire population. This is a well-known attenuation artifact and it is worth checking before you conclude that two variables are unrelated. If you are looking for structured Correlation Coefficient Practice Problems to work through, most introductory statistics textbooks include exercise sets at the end of the correlation chapter. OpenStax offers free downloadable problem sets online. University course pages sometimes post practice problem PDFs as well. The key is to find problems that include scatterplots alongside the numerical exercises, since being able to visually assess correlation is just as important as computing it.