Getting Your Data Right for North America
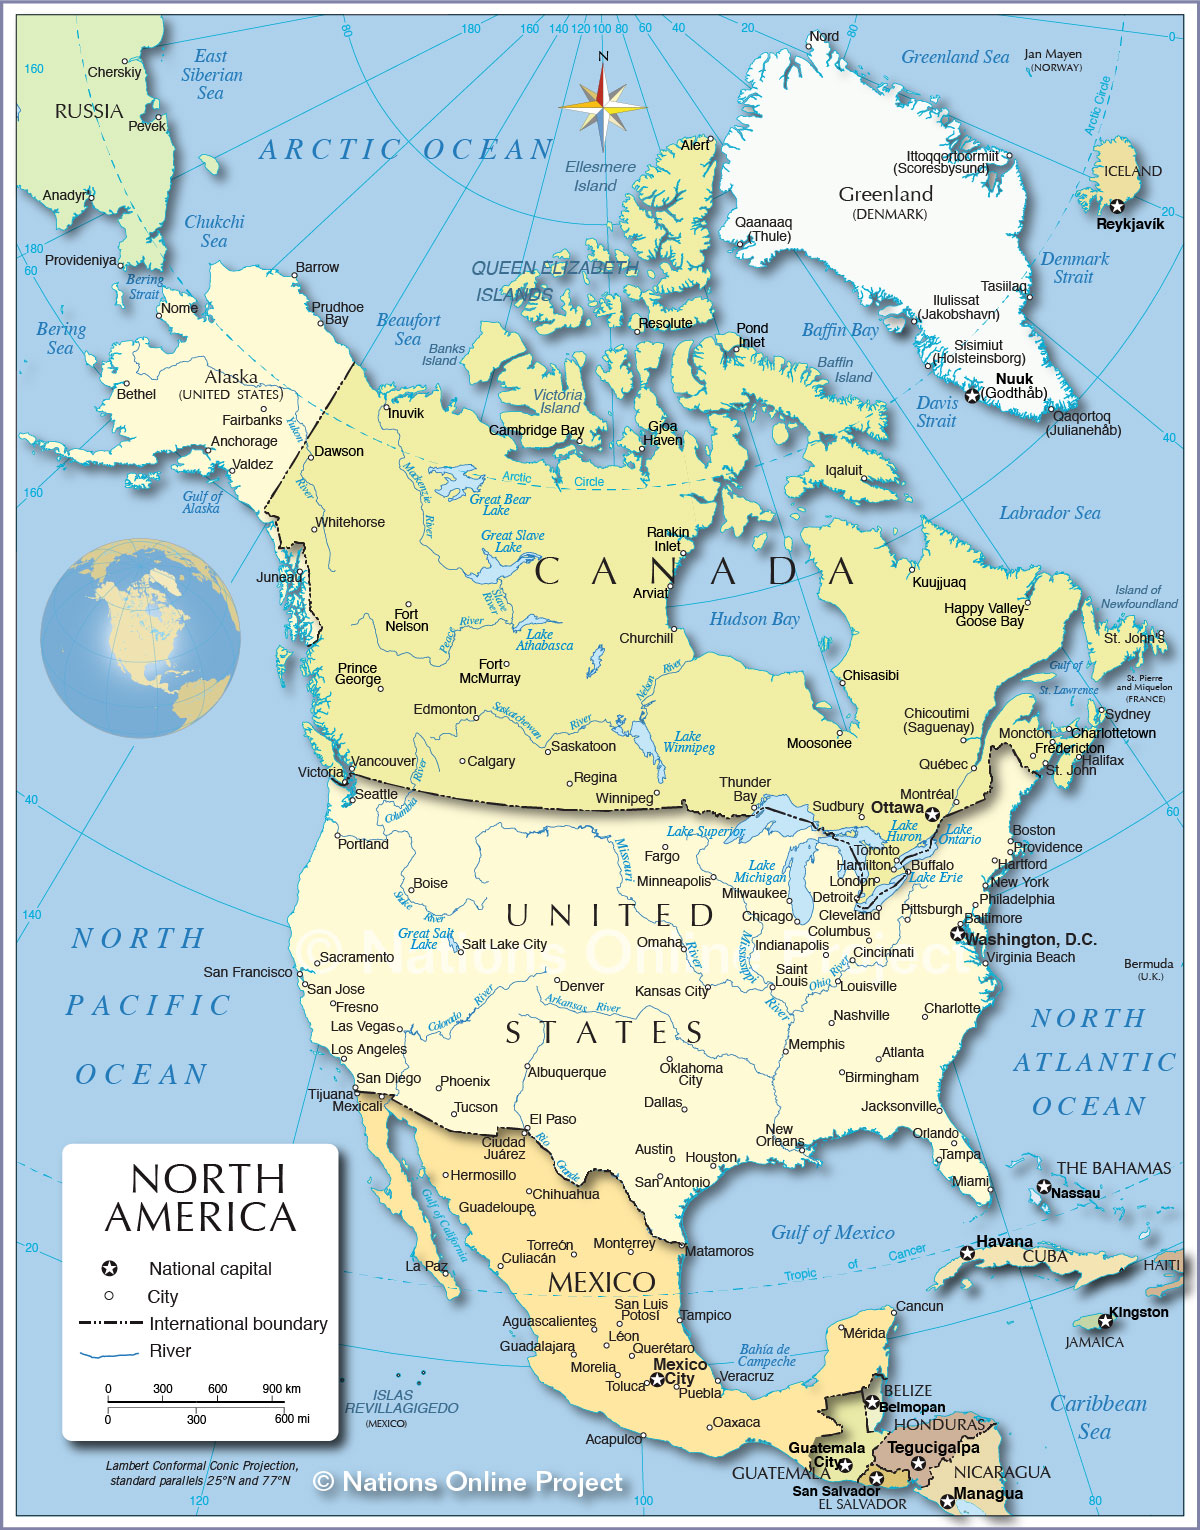
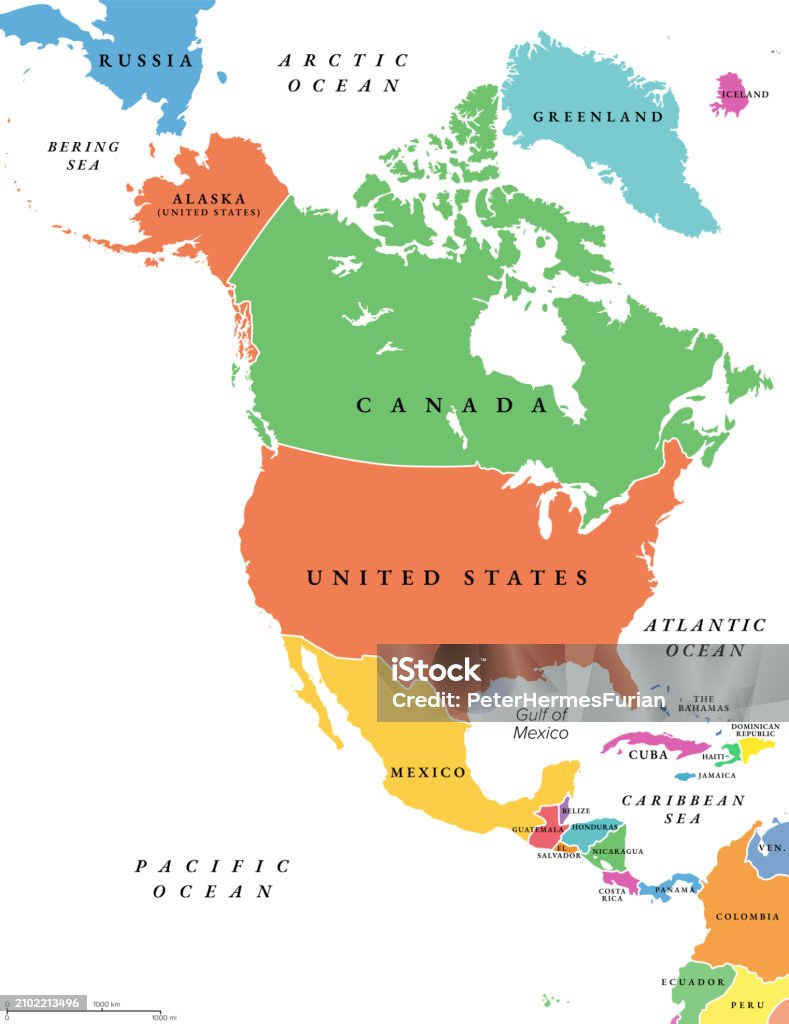
I spend more time than I care to admit sorting out geographic datasets for the North American continent. People usually come to me because they have a CSV file with addresses that don't validate, or their geocoding service keeps returning nulls for half their records. The problem is almost never the tool—it's the underlying data model. North America, geographically, isn't just the United States, Canada, and Mexico. It includes the Central American corridor down to Panama, the Caribbean islands, and Greenland. That distinction matters because most APIs and databases lump these regions differently. I had a project once where a client insisted on using "North America" as a continent filter, but their CRM treated Canada and the Caribbean as separate entities. We spent three weeks reconciling the mismatch before just writing a mapping table that translated between the two systems.
Countries North American Continent
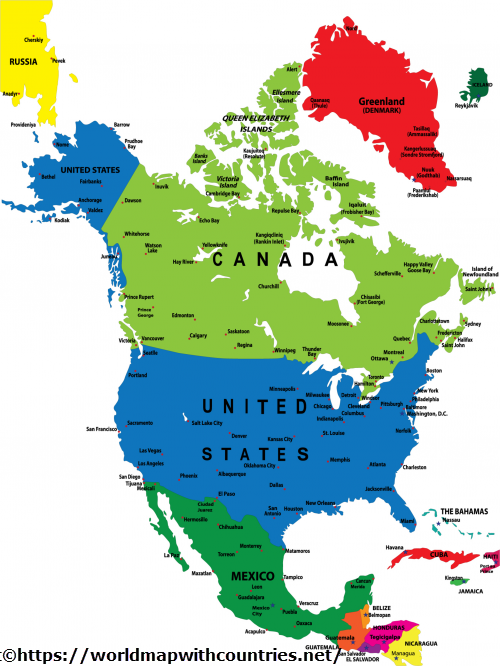
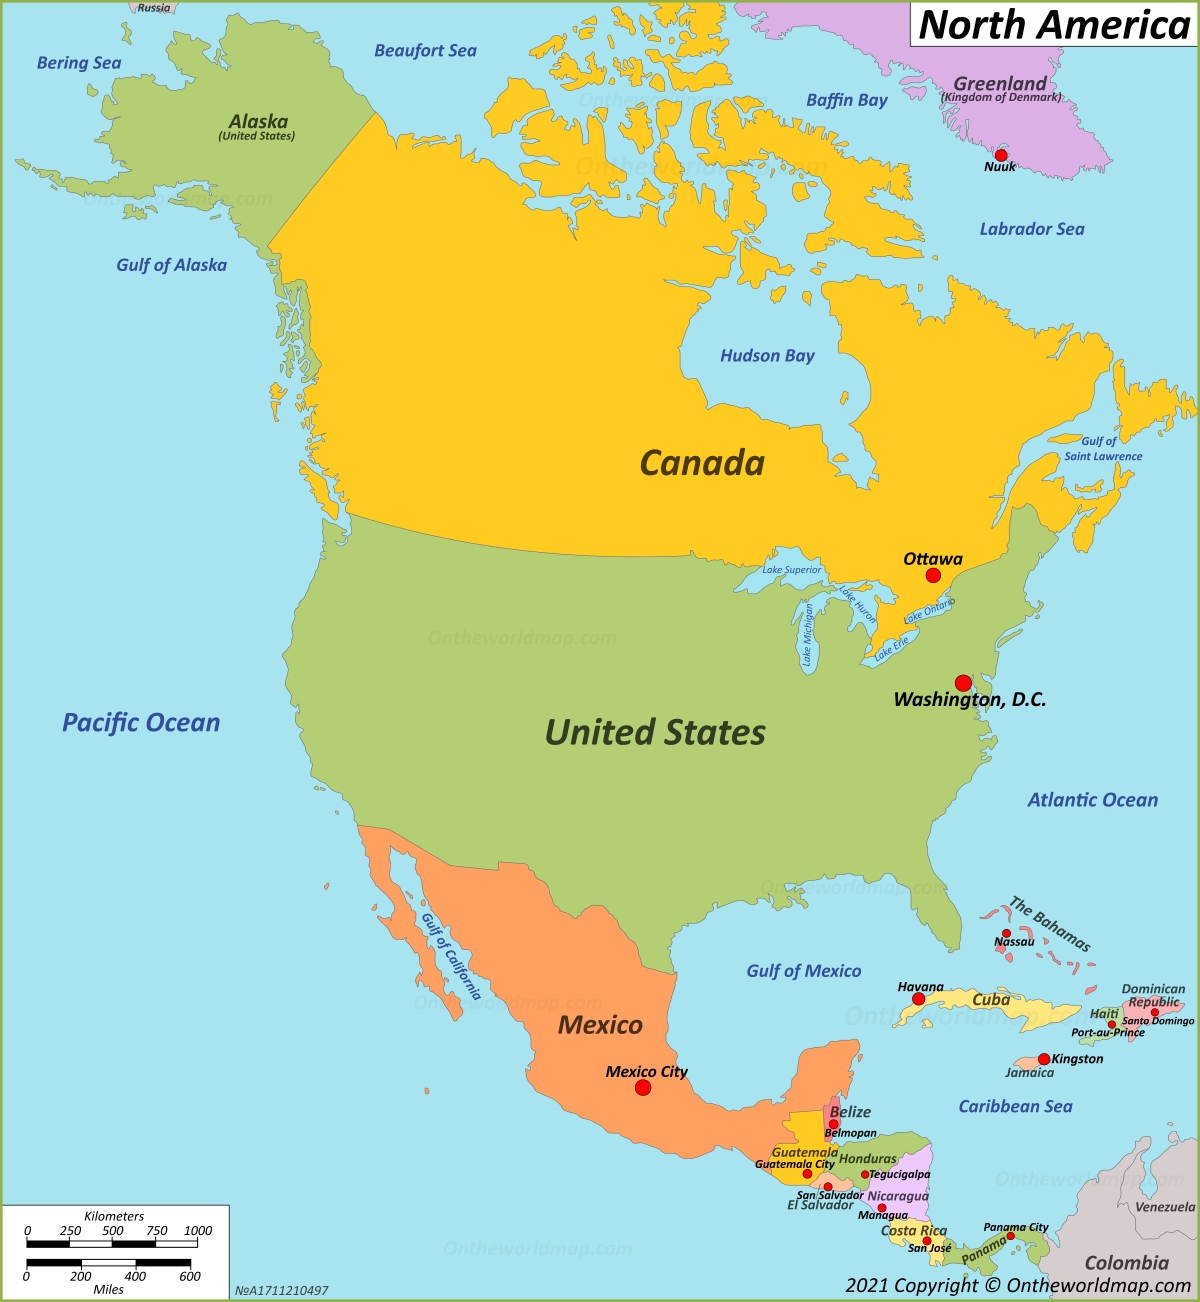
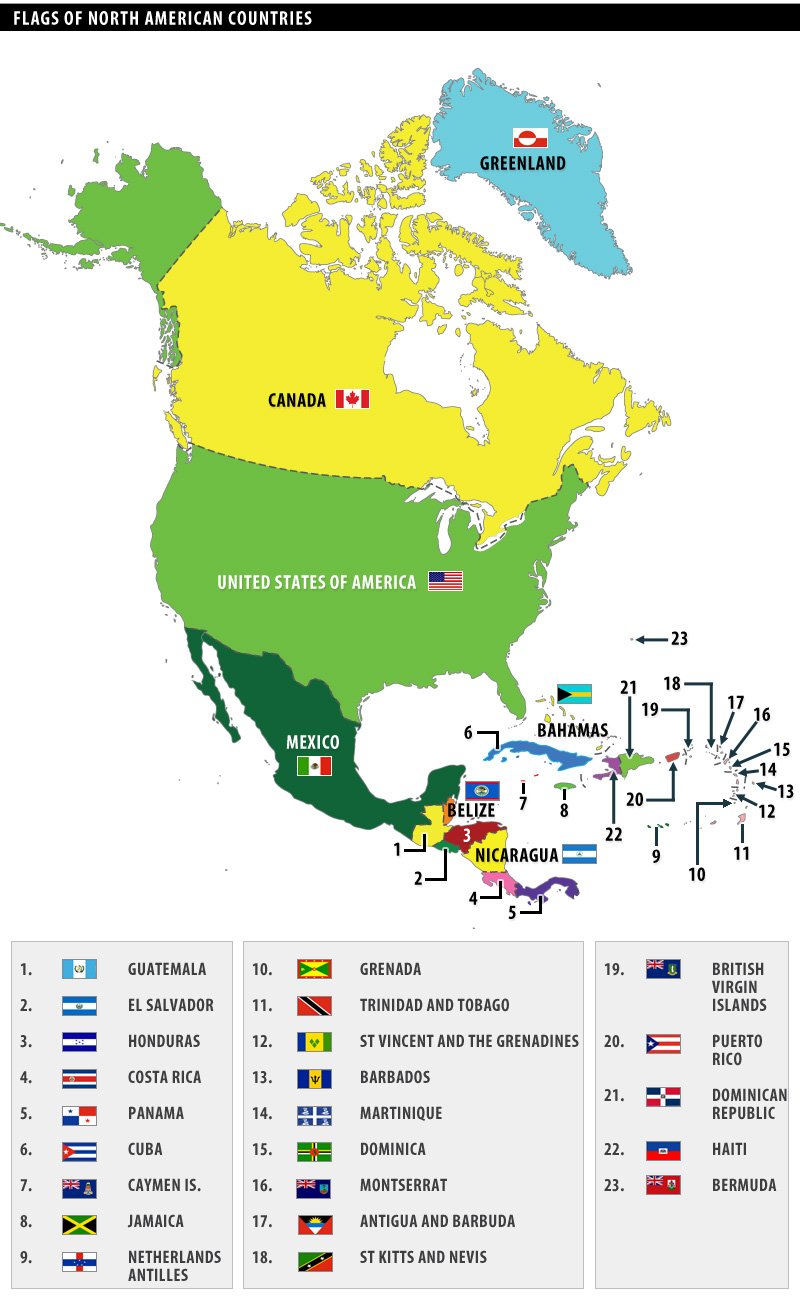
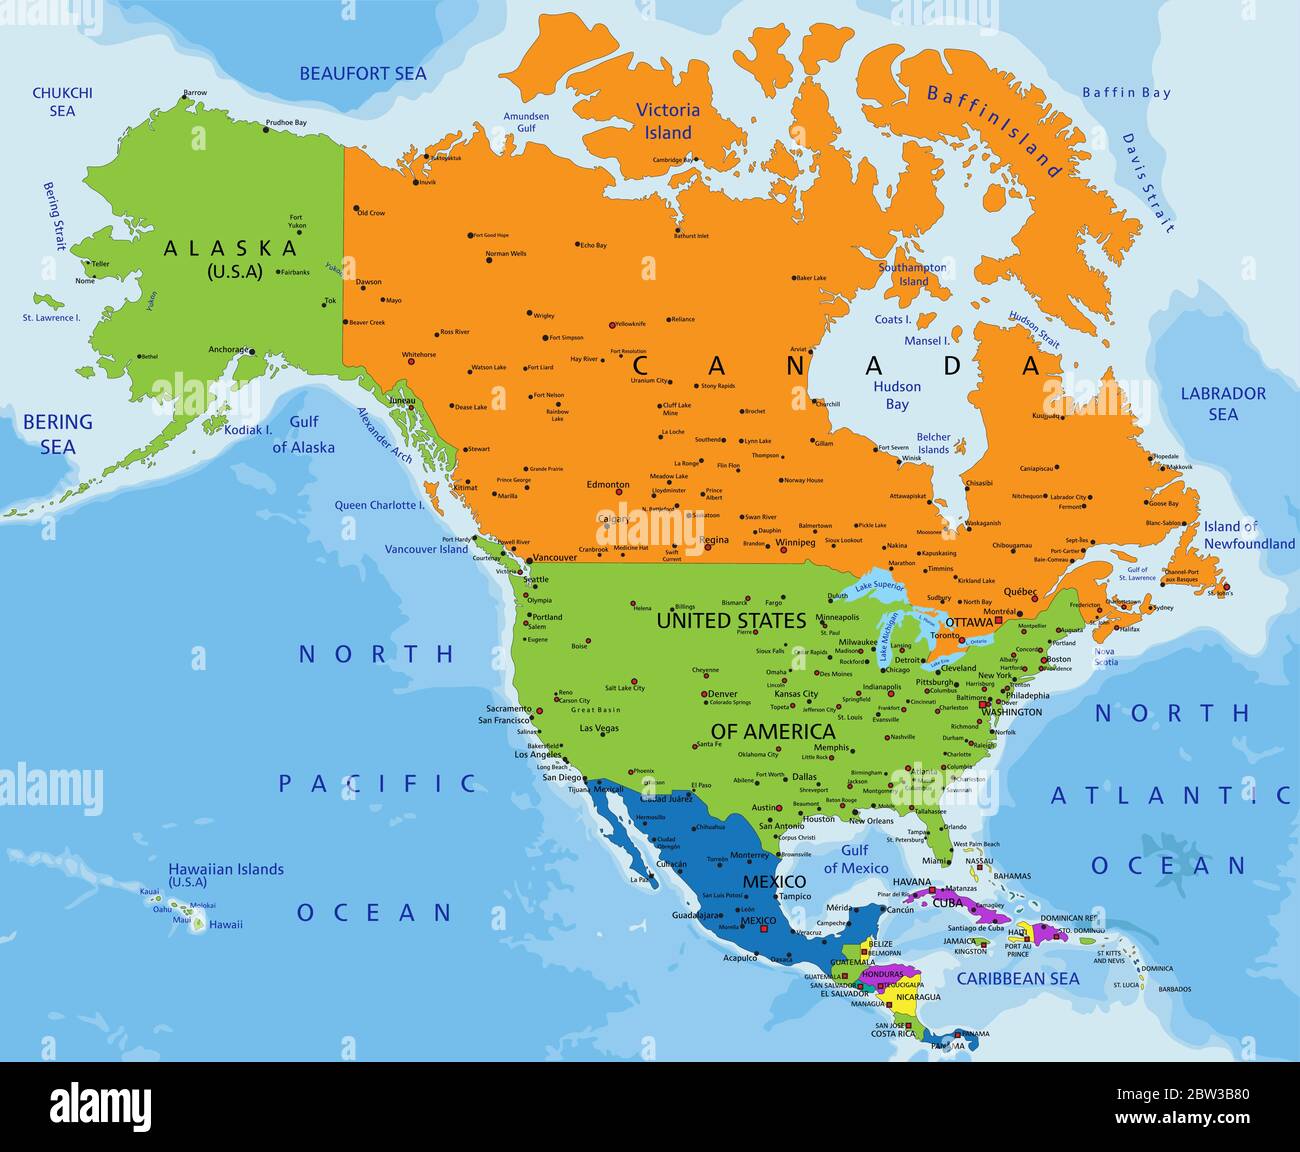
The standard list breaks down into three subregions. Central America covers seven countries: Belize, Costa Rica, El Salvador, Guatemala, Honduras, Nicaragua, and Panama. The Caribbean brings another twenty-plus sovereign nations and dependencies, including Cuba, Haiti, the Dominican Republic, Jamaica, and Trinidad and Tobago. Then there's the northern tier: Canada, Mexico, and the United States. Mexico is the part that trips people up most. It's geographically in North America, but a lot of legacy systems classify it under Latin America or South America region codes. If you're building something that needs to be unambiguous, don't rely on the word "American" alone. Use the specific country codes and define your region boundaries explicitly in your schema. Here's a practical note about data entry. When I'm importing address data, I always validate against the ISO 3166-1 alpha-2 and alpha-3 standards rather than free-text country names. Names change, abbreviations vary, and people spell them differently. A two-letter code like MX for Mexico or CA for Canada eliminates about eighty percent of the ambiguity you'll run into. The remaining twenty percent comes from territories and dependent regions, which are a separate headache entirely.
Greenland is another edge case. It's part of the Kingdom of Denmark geographically and politically, but it's absolutely on the North American landmass. If your dataset is based on political affiliation, it gets filed under Europe. If it's based on continental placement, it's North America. I've seen both approaches used in production systems, and both cause problems downstream. The workaround I use is a dual-tagging system: one field for the geographic continent and a separate field for the sovereign state. It adds a column to your database but saves you from rewriting migration scripts later. When it comes to actual tools, GeoNames and Natural Earth are the two most reliable free sources for boundary and country data. GeoNames gives you clean administrative boundaries and coordinate data. Natural Earth provides simplified polygon files that work well for visualization. Neither is perfect for high-volume transactional systems because the data refreshes slowly, but for anything that doesn't need real-time updates, they're sufficient. I also recommend against rolling your own geocoding from scratch unless you have a serious budget. Open-source options like Nominatim exist, but they require significant infrastructure and careful rate-limiting. For a small team or a one-off project, paying for a managed service like Mapbox or Google Geocoding API usually costs less than the engineering time it takes to build and maintain your own pipeline.
Get the Full Details
The biggest mistake I see is assuming the data is static. Countries change. Border disputes shift. New territories get recognized or renamed. I inherited a project once where the client hadn't updated their region definitions since 2011, and the system was still classifying Palestine as a non-country in their demographic reports. Set up a quarterly review cycle for your geographic reference data. It takes about an hour a quarter if you have it automated, and it prevents a lot of embarrassment. If you're putting together a dataset from scratch, start with Natural Earth at 1:110m resolution for country boundaries, layer in GeoNames for place names and coordinates, and cross-reference with the CIA World Factbook for any political status discrepancies. Export everything to GeoJSON, validate it with a tool like geojsonlint, and then normalize the country codes to ISO standards before loading anything into a production database.