Pulling County-Level Hurricane Data Without Losing Your Mind
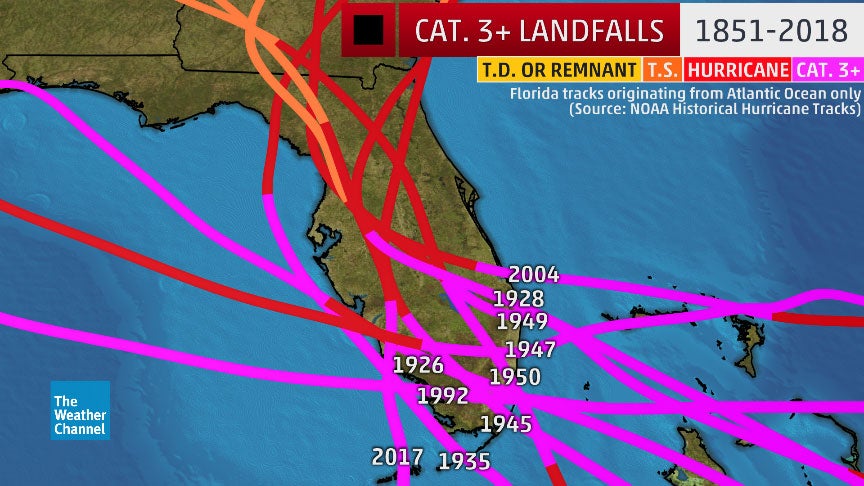
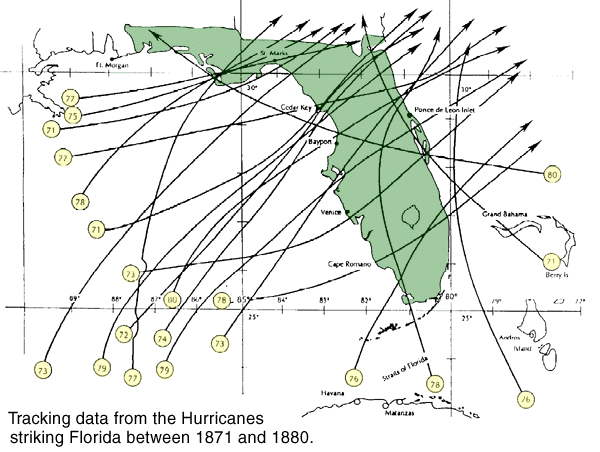
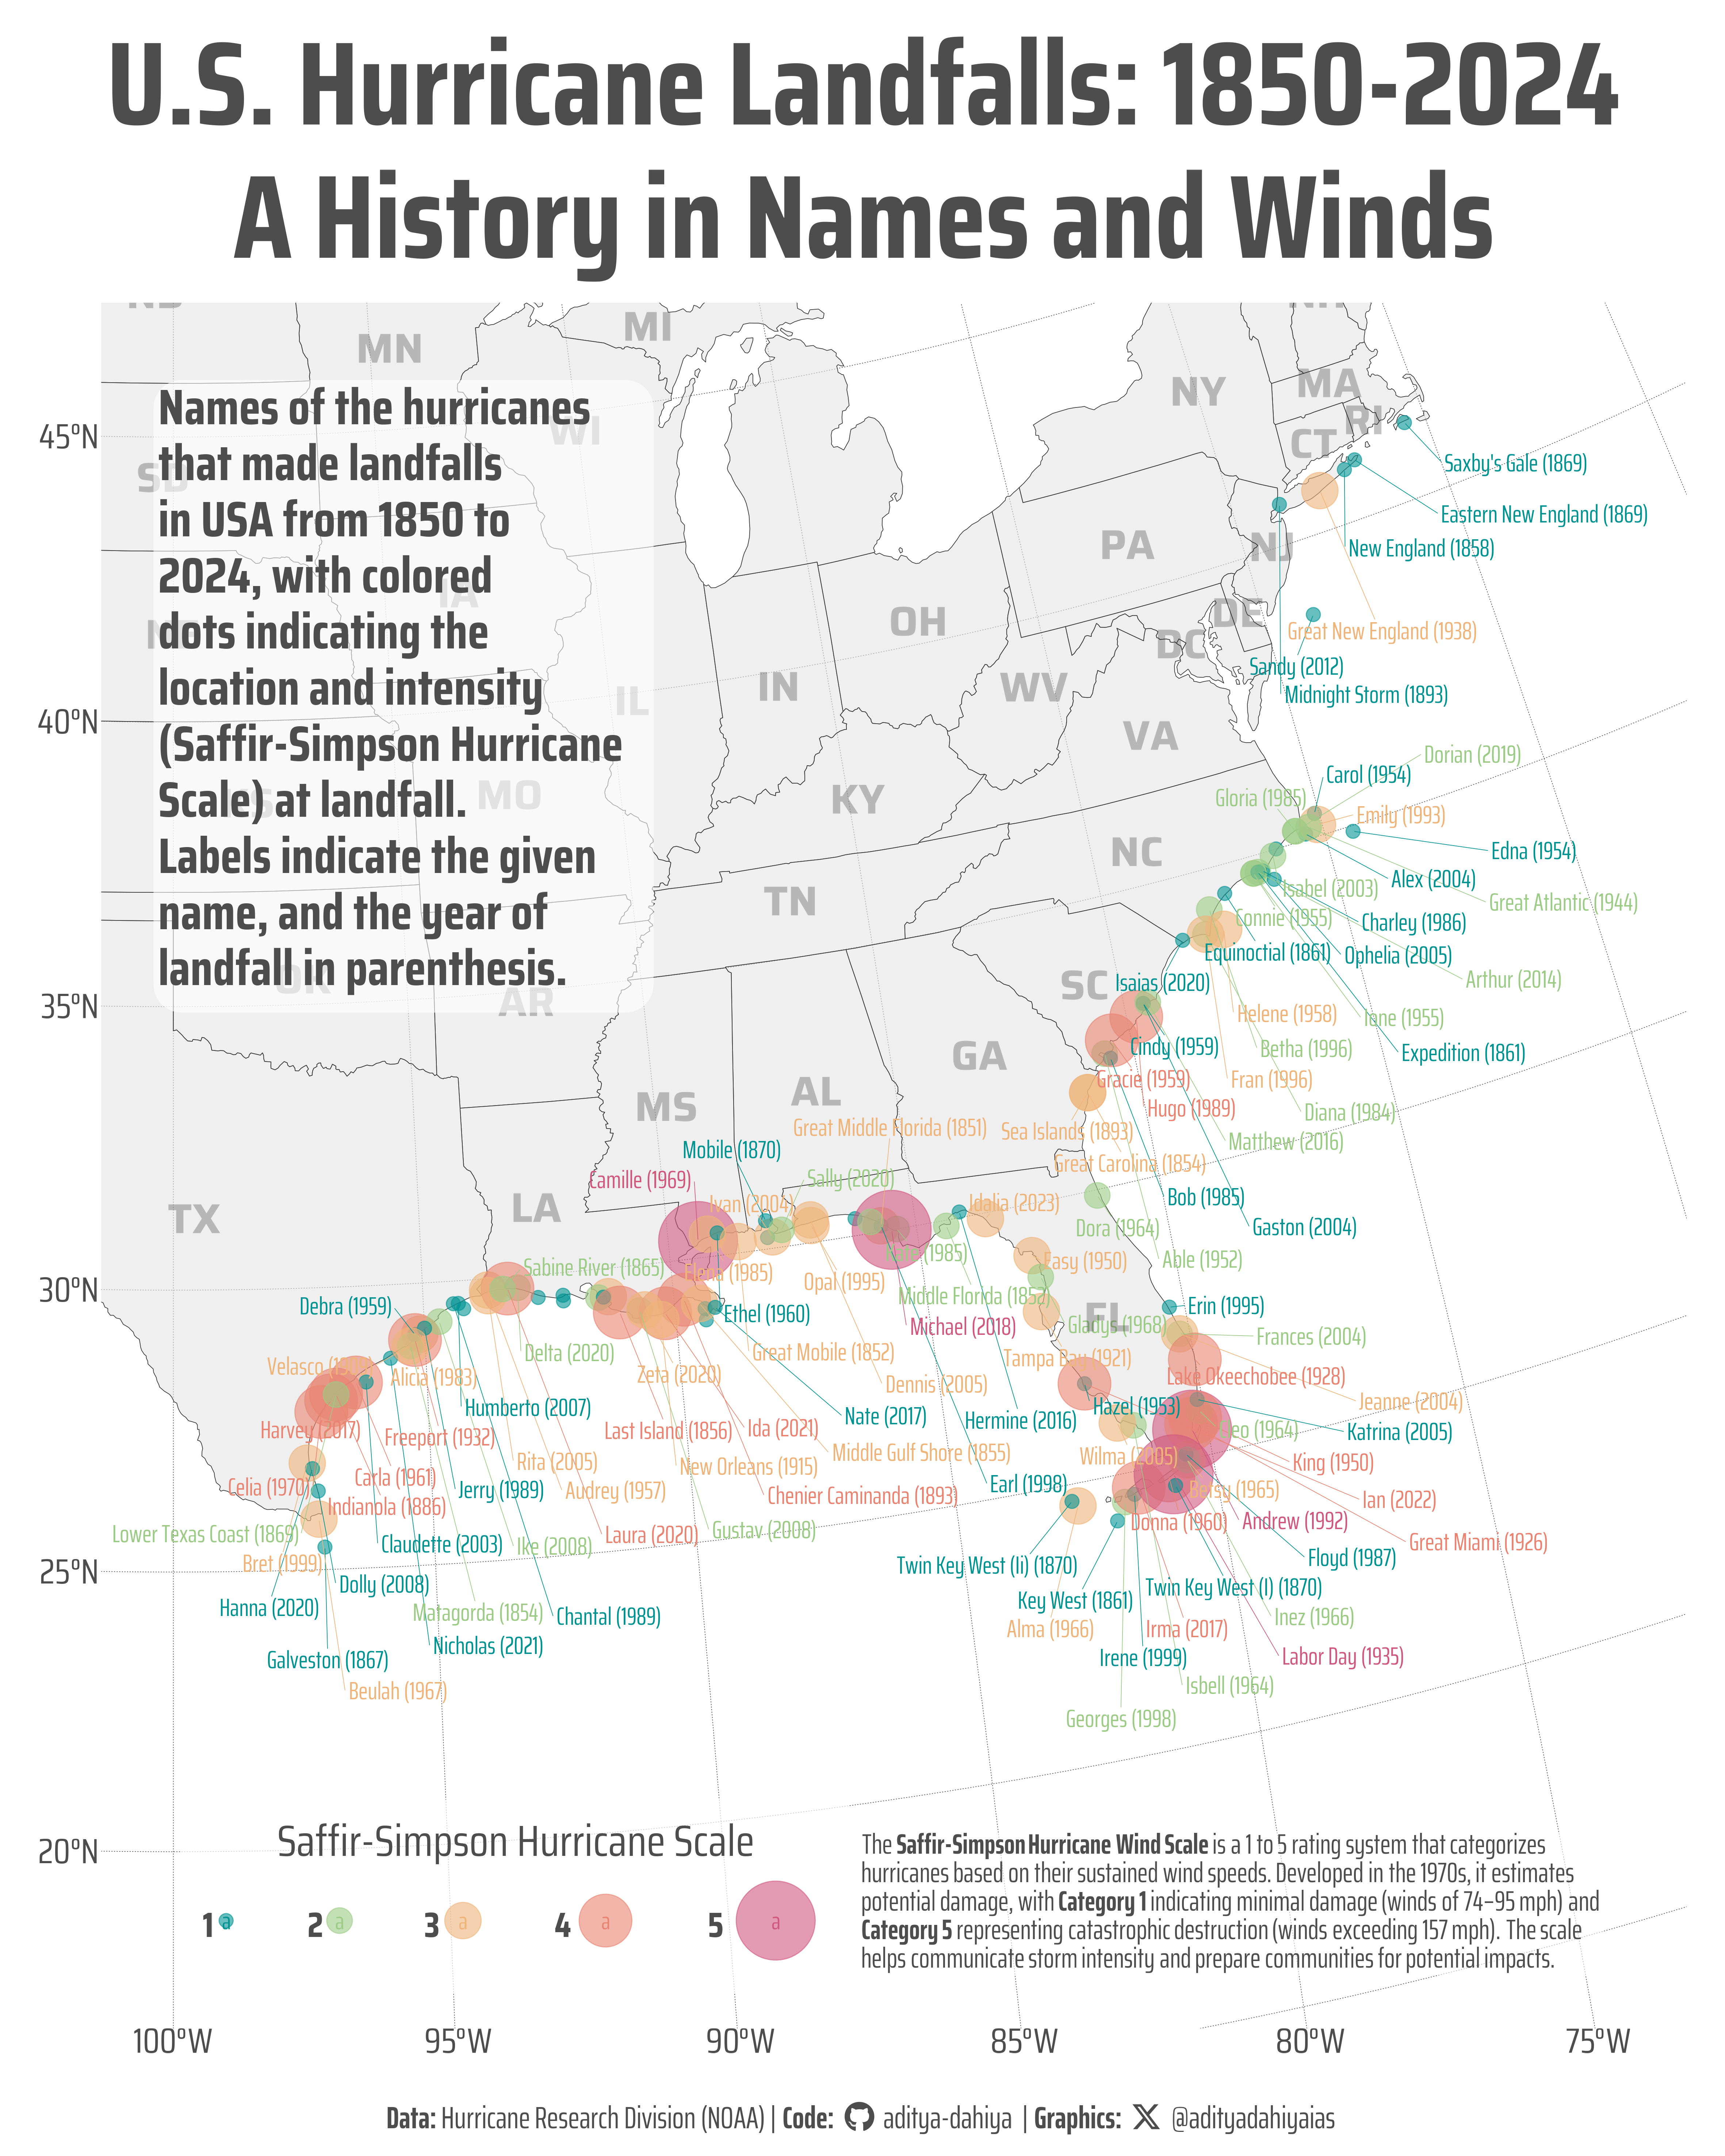
The most common mistake I see is people trying to download a pre-packaged dataset called something like "County Hurricane History" and expecting it to work. That dataset generally doesn't exist in a clean form. What exists is raw storm track data from NOAA and vector boundaries from county GIS offices, and you have to bridge them yourself. I spent about three months in 2019 building a county-level hurricane exposure model for a Southeast coast region, and the biggest headache wasn't the coding, it was the mismatch in coordinate reference systems between sources. NOAA's HURDAT2 database is the standard starting point. It contains latitude, longitude, wind speed, and pressure readings taken every six hours going back to 1851 for the Atlantic basin. It's freely available from the National Hurricane Center. FEMA also maintains a Storm Event Database that has county-level damage reports, but those are event summaries, not spatial tracks. If you need to know which counties a storm actually hit, neither of those gives you a clean answer out of the box.
What You Actually Need for County Hurricane History
You need two things joined together. The first is the storm track as a series of coordinate points with timestamps and wind radii. The second is county boundary shapefiles. For the Atlantic basin, county shapefiles come from the U.S. Census Bureau's TIGER/Line files or from individual state GIS portals. State portals are usually more current, especially for counties that have been reconfigured after annexations or consolidations. The straightforward approach is to create a buffer around each track point proportional to the reported wind speed radius and then intersect that buffer with your county polygons. A point with 80-knot winds and a reported radius of 50 nautical miles for the northeast quadrant means anything within that arc should count as affected. The problem is that HURDAT2 only reports wind radii for storms at hurricane strength, and even then only in cardinal directions. Tropical storms get wind speed values without radius data, so you have to estimate. I've seen people use a fixed radius of 120 kilometers for all tropical storms, which is wildly inaccurate but fast. It works if you're doing rough screening across hundreds of storms. It fails if you need precision for insurance modeling. Here is the part nobody tells you about buffering track points. If you buffer every single six-hour position and intersect with counties, you end up counting the same storm over and over for the same county because the buffer from the previous hour still overlaps. A storm can sit over a county for twelve hours, and you'll have two or three overlapping intersections per county per event. You have to deduplicate by storm name and year, keeping only the maximum wind speed or the longest duration per county per storm. This cuts your result set down significantly and makes the data usable.
I ran into a specific edge case with Category 4 storms making landfall. HURDAT2 reports the position at landfall, but the storm's center often crosses county lines shortly after. In 2018, I was building a history table for a county just south of a major landfall point. The official HURDAT2 track showed the eye staying in the neighboring county, but the outer rain bands and the 50-knot wind radius extended well into my target county. If I only counted intersections where the track point fell inside the county boundary, I would have excluded that storm entirely. I ended up using the wind radius data instead of just the track point to determine county exposure. That approach flagged roughly 18 percent more counties as affected compared to a pure point-in-polygon method, and it matched the actual damage reports much better. The workaround was to treat the storm as a set of elliptical wind fields rather than a single moving point. I approximated each storm's wind field using the reported northeast, southeast, southwest, and northwest radii, created an ellipse at each six-hour interval, and then intersected those ellipses with county boundaries. This took longer to compute but produced results that were defensible under review. For a quick and dirty analysis, the point-buffer method is acceptable. For anything that needs to stand up to scrutiny, the ellipse method is worth the extra processing time. If you want to automate this, Python with Geopandas and the shapely library handles the geometry work. R with the sf package works just as well. I used Python because I was already pulling HURDAT2 data with the hurdat2 R package and converting it, but you can do the whole pipeline in one language. The HURDAT2 file is a fixed-width text format, so parsing it requires either the dedicated package or a careful read.fwf call. The Census county shapefile is a standard Shapefile or GeoJSON that Geopandas reads directly.
Get the Full Details
A rough timeline for someone doing this from scratch: downloading HURDAT2 and the county shapefiles takes maybe ten minutes. Setting up the coordinate transformation to a projected CRS like NAD83 / Alabama East takes another fifteen. Writing the buffer-and-intersect loop runs in under an hour for the full Atlantic basin if your machine has decent RAM. Deduplication and aggregation add another twenty minutes. The total time is under two hours on a standard laptop, assuming you don't run into CRS mismatches, which is when things get frustrating and you lose another hour checking definitions. There are known limitations with this whole approach. HURDAT2 has been revised multiple times since its creation, and earlier records from the 1960s and before have known gaps. Storms before satellite era relied on ship reports and land observations, so track positions can be off by tens of kilometers. For county-level analysis this usually doesn't matter because county boundaries are large, but it does matter for very small coastal counties where a few kilometers of position error shifts the track from one county to the next. Another limitation is that HURDAT2 doesn't include storm surge or storm-specific rainfall data. A county might experience significant flooding from a storm that technically tracked too far offshore to intersect the county boundary, even with wind radius buffering. If you need flood exposure, you have to pull separate data from FEMA's National Risk Index or the USGS flood databases. Combining those sources adds a layer of complexity that most people underestimate.
Wind speed conversion is another place where people make errors. HURDAT2 reports one-minute sustained winds in knots. If your model or local regulations use three-second gusts or ten-minute sustained winds, you need a conversion factor. The standard approximation is to multiply knots by 1.15 to get approximate three-second gusts, but that introduces its own error margin. Be explicit about which wind speed definition you're using in any report or dataset you publish. Nobody checks, but it matters if someone does. For people who just want a working dataset without building the pipeline themselves, a few regional organizations have published county-level storm summaries. The North Carolina Sea Level Rise Task Force released documents with county-level hurricane wind speed estimates based on HURDAT2 processing. The Texas General Land Office maintains a similar dataset for Gulf Coast counties. These are useful references but they're tied to specific basins and years, so they don't help if you're working across multiple states or need the most recent storms. Building the pipeline yourself gives you control over the methodology and lets you update it whenever new HURDAT2 revisions come out, which happens roughly every five to seven years. The data sources you'll need: HURDAT2 is at the NOAA NHC website, county TIGER/Line shapefiles are at the Census Bureau website, and state-level parcel or boundary data lives on individual state GIS portals. I kept a running notebook with the direct links for Florida, Georgia, Alabama, Mississippi, and Louisiana county portals because those changed occasionally and old links broke afterGIS department reorganizations.
One more thing that trips people up. When you intersect storm tracks with county boundaries, you'll get results showing storms affecting counties that are hundreds of miles inland. A Category 2 storm can dump heavy rain over a county two hundred kilometers from the coast. Whether that counts as a hurricane event for your purposes depends on your definition. Some analyses only count counties where the track point or the 34-knot wind radius intersects the boundary. Others include any county that experienced tropical-storm-force winds, regardless of track position. Define your inclusion criteria upfront and stick to it across your entire dataset. Inconsistent criteria make the history table internally contradictory, which defeats the purpose of having one in the first place.